
A city library is designing an accessibility kiosk for visitors with low vision. The kiosk must be able to (1) read the printed text on a posted event schedule aloud and (2) describe the general content of a photo on a nearby exhibit wall in a natural-language sentence. Which two Azure AI Vision capabilities does the team need to combine to meet both requirements? (Select TWO.)
Select all correct answers, then click Submit.
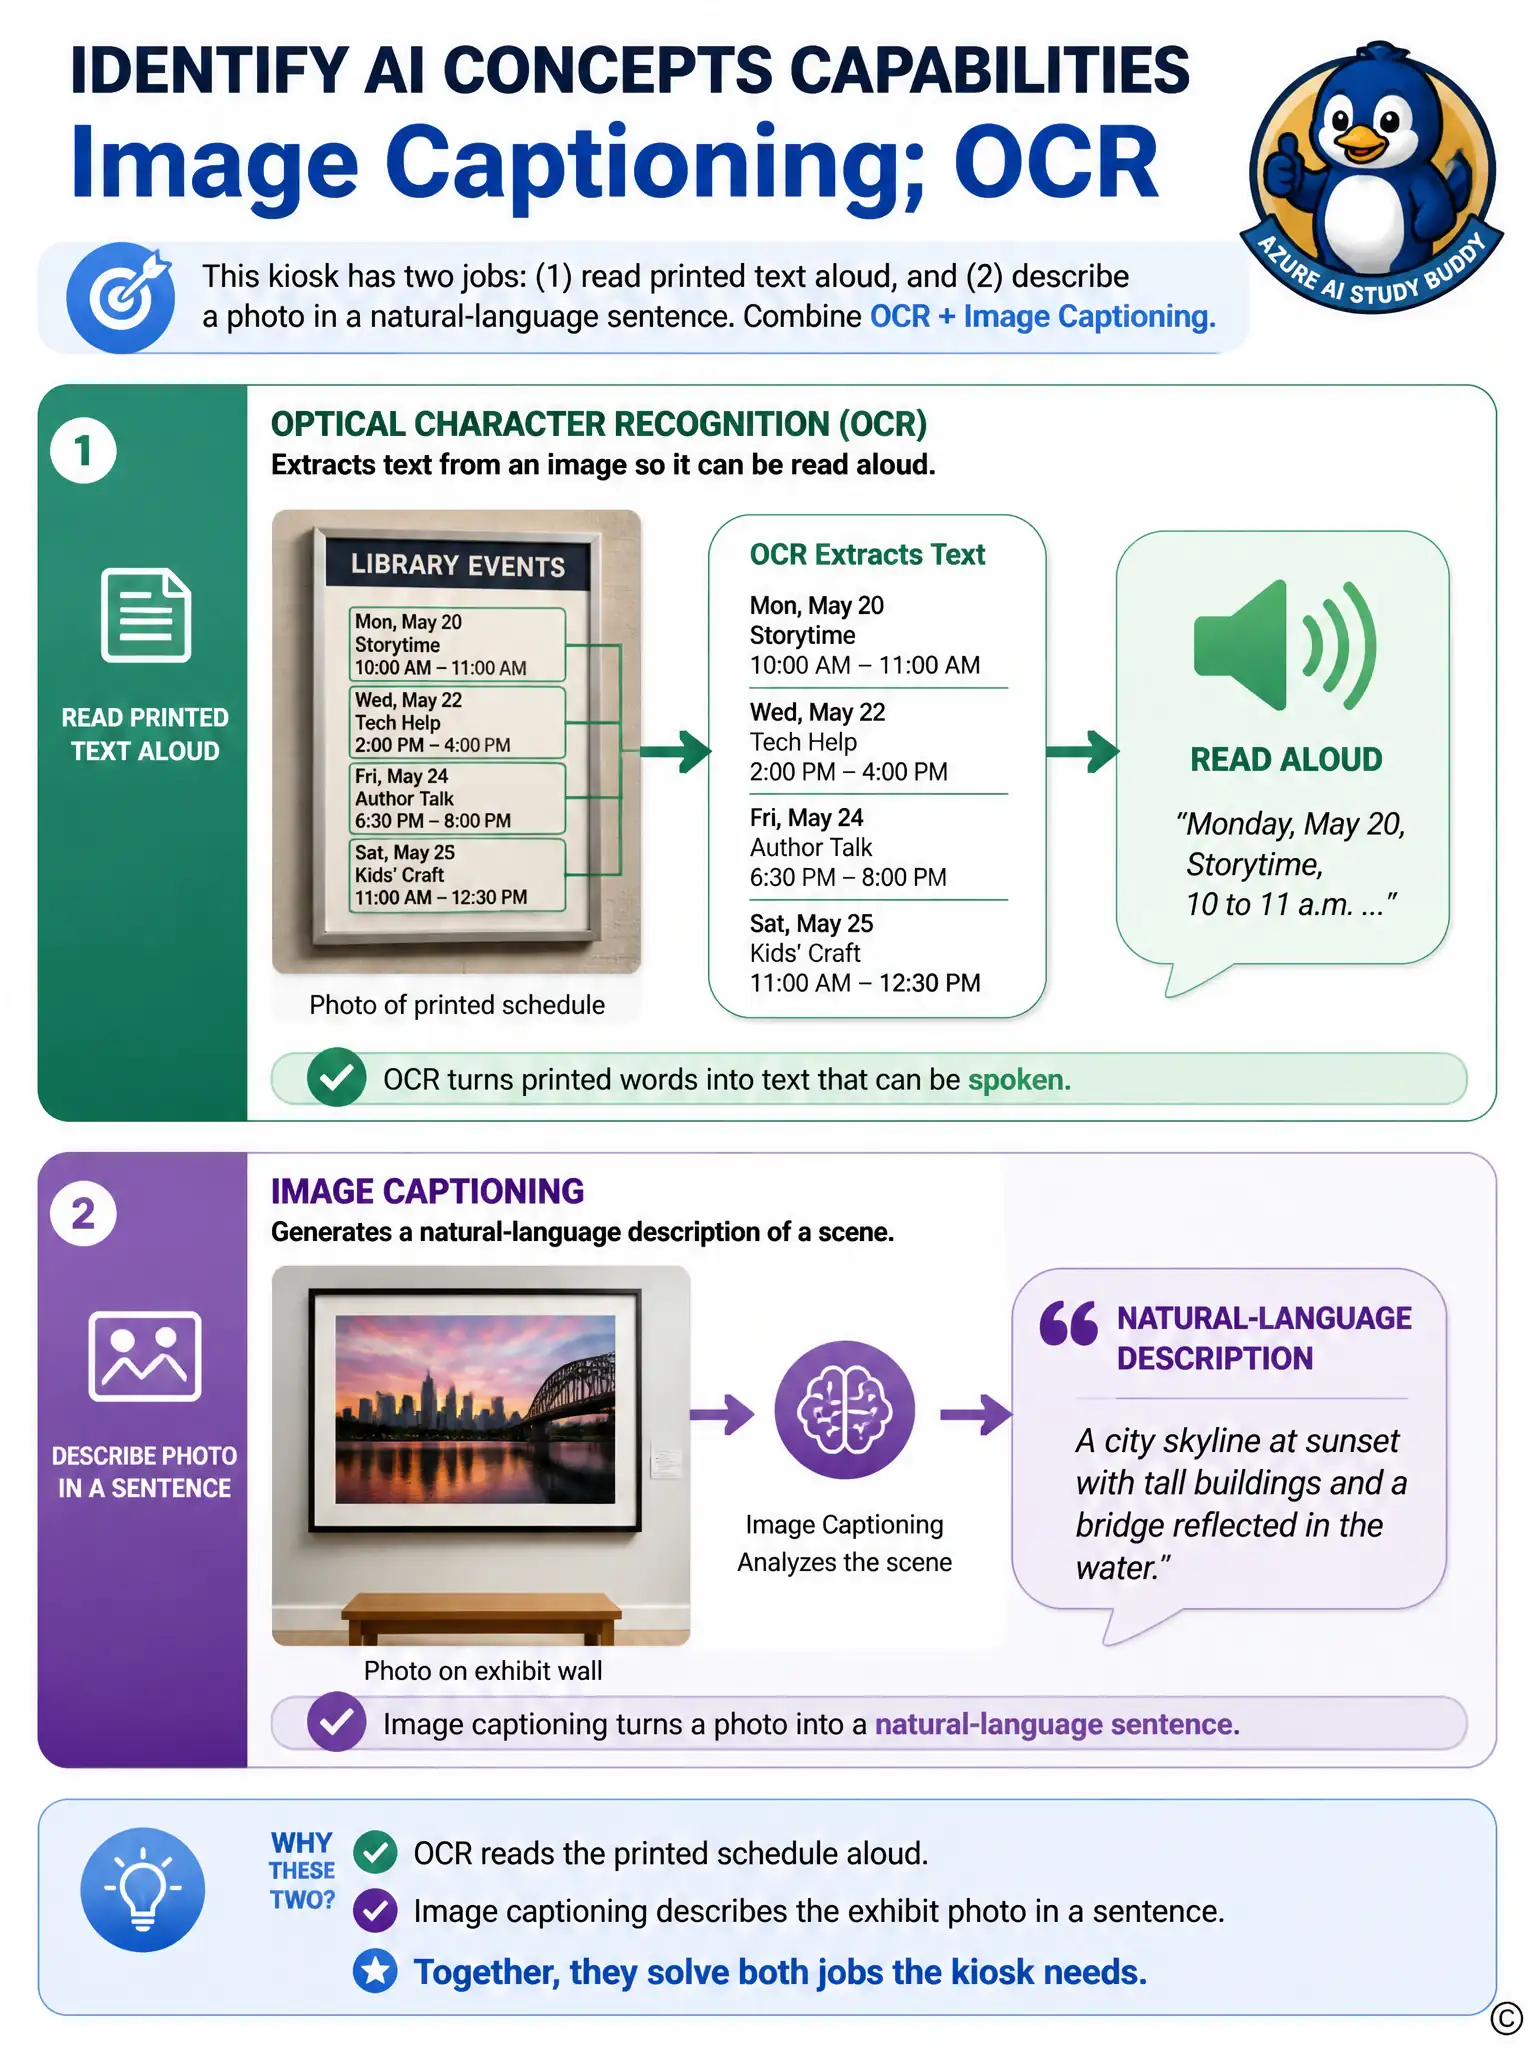
Short Explanation
This kiosk has two jobs, so pair the tool that pulls printed text out of an image with the tool that writes a natural-language sentence about a photo. OCR reads the event schedule for speech, and image captioning describes the exhibit photo. Object detection only labels boxes, and face detection only finds faces, so neither covers both needs.
Full Explanation
The correct capabilities are optical character recognition (OCR) and image captioning. OCR extracts the printed characters from the event schedule so the kiosk can convert them to speech, and image captioning generates a natural-language sentence summarizing what a photo depicts, which covers the second requirement of describing the exhibit image. Object detection is incorrect because it returns bounding boxes and labels for individual objects rather than a flowing descriptive sentence, so it does not produce the kind of narrated summary the exhibit-description requirement calls for. Face detection is incorrect because it only locates and analyzes human faces within an image; it neither reads printed text nor generates a general description of a photo's overall content, so it addresses neither of the kiosk's two stated needs. Because the scenario explicitly requires both extracting printed text and generating a natural-language description, the team must combine the two capabilities that each solve one of those distinct problems rather than choosing a single all-purpose tool.