
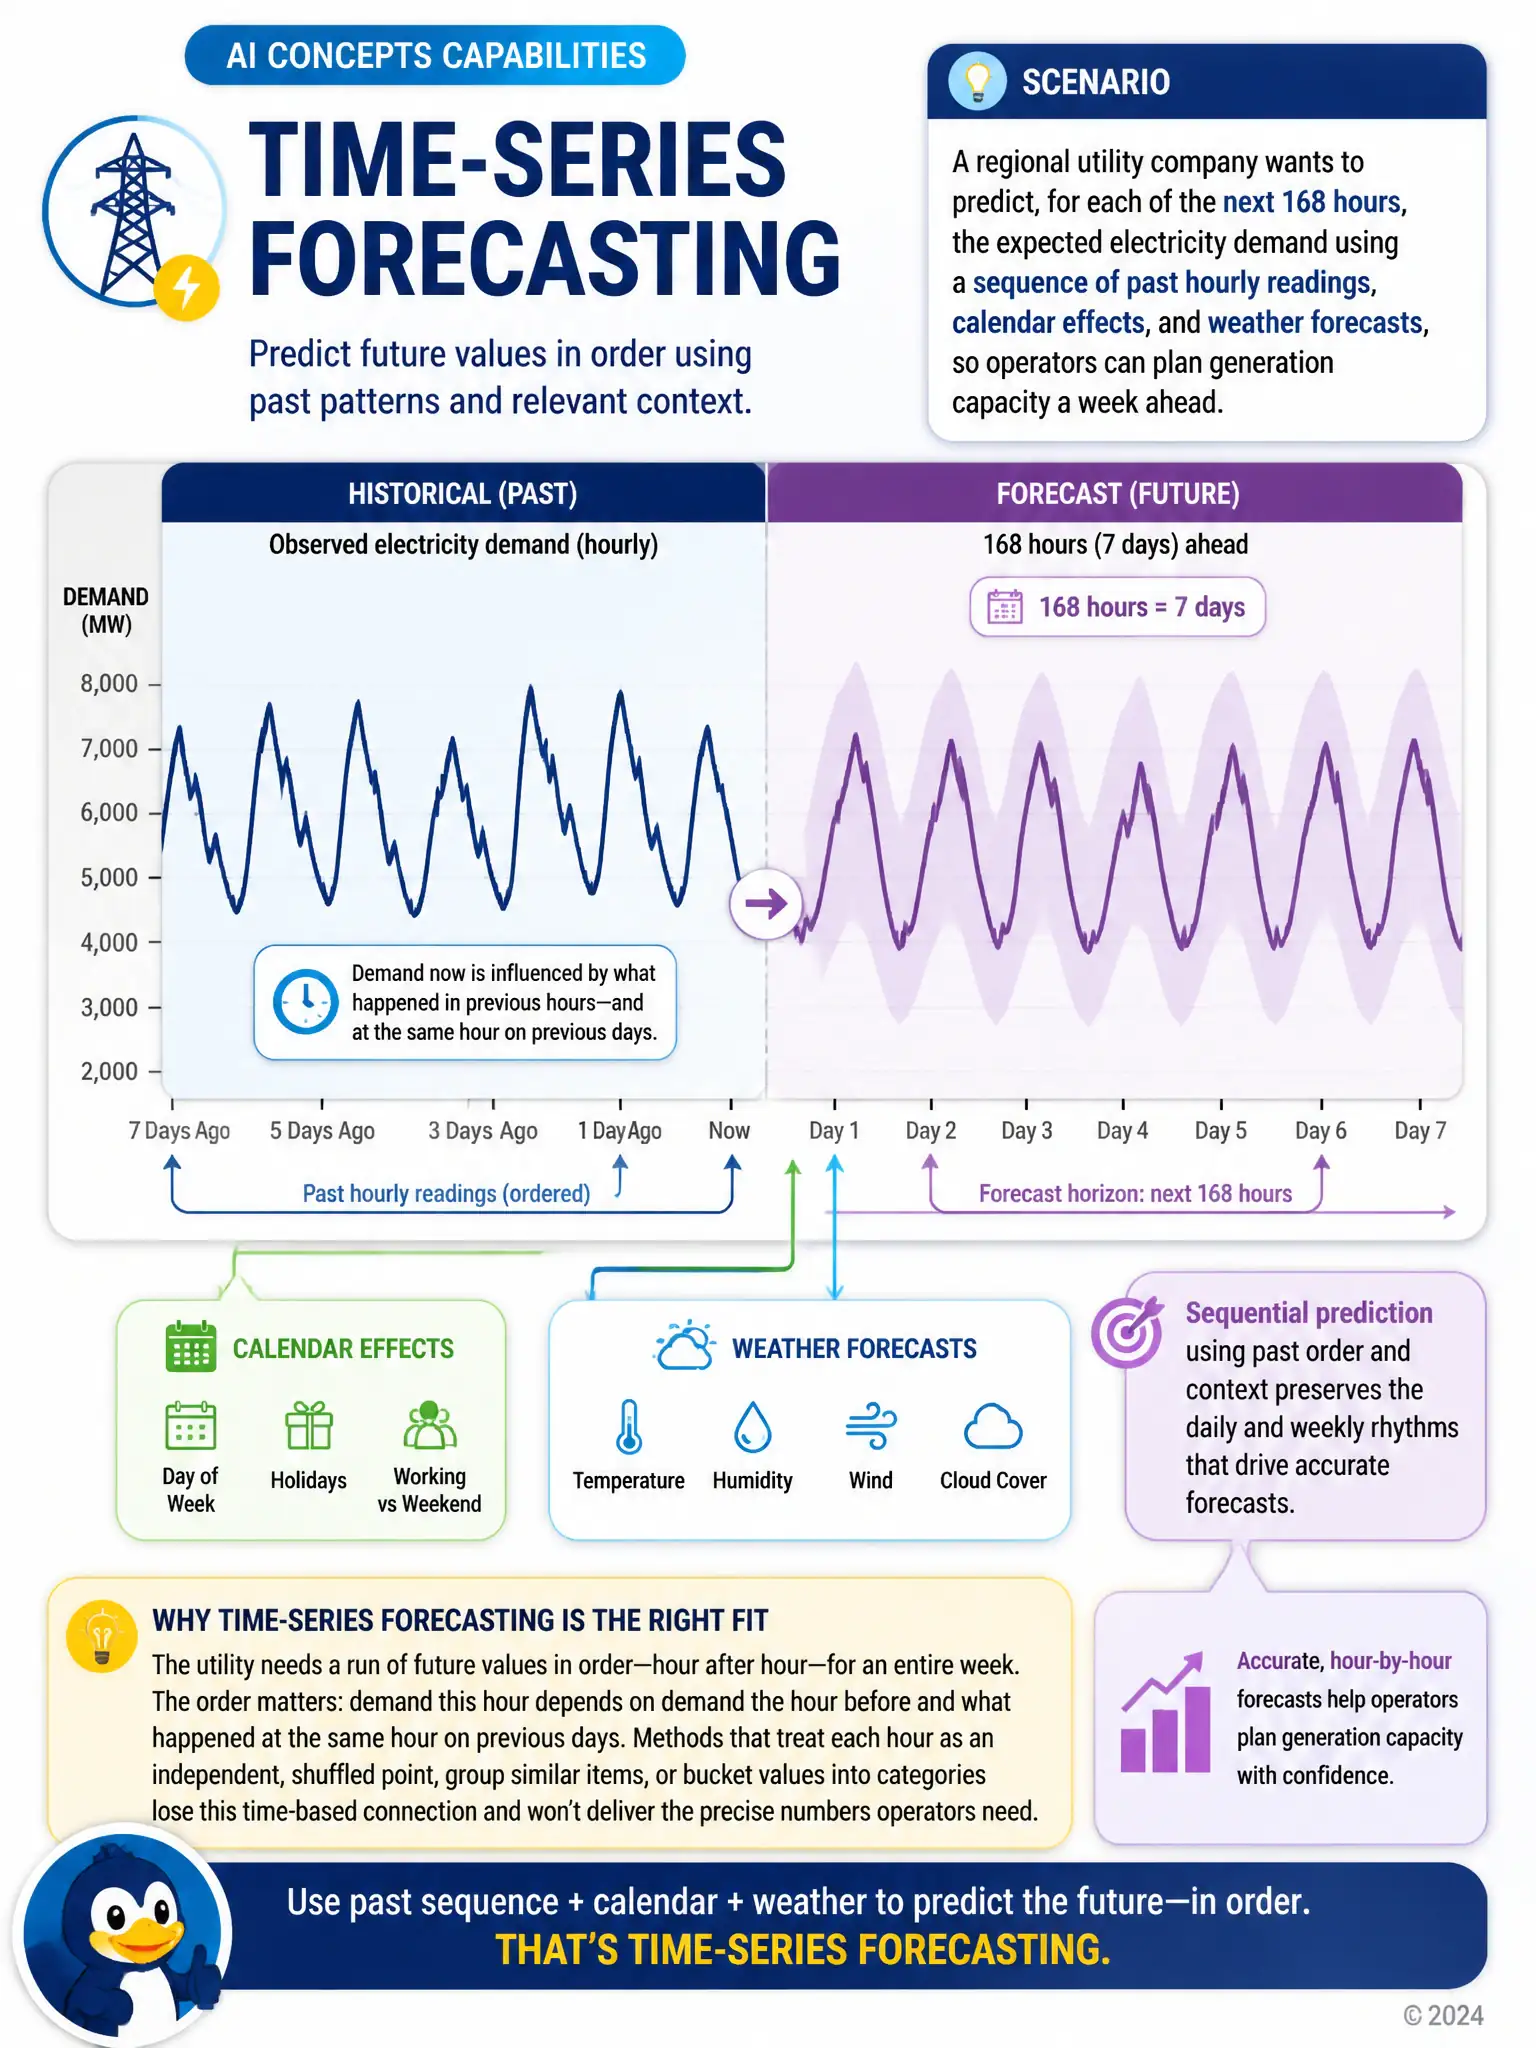
A regional utility company wants to predict, for each of the next 168 hours, the expected electricity demand using a sequence of past hourly readings, calendar effects, and weather forecasts, so operators can plan generation capacity a week ahead. Which machine learning approach best fits this need?
Select an answer to reveal the explanation.
Short Explanation
You're predicting a week of hourly demand in order, not just a single value or category. Time-series forecasting is the fit because it uses past sequence, daily and weekly rhythms, and weather/calendar effects to project multiple future steps. Treating hours as shuffled points or grouping them loses the timing you need.
Full Explanation
Time-series forecasting is the best fit because it is designed to model sequential dependence between observations and produce a sequence of future predictions, which matches the utility's need to project demand hour by hour across an entire week using patterns like daily and seasonal cycles. Classification is incorrect because it assigns inputs to discrete categories, such as 'high demand' or 'low demand,' rather than producing the specific continuous demand values the operators need for capacity planning. Clustering is incorrect because it groups similar data points together without predicting any future numeric outcome, so it cannot generate the 168 hourly demand figures the scenario requires. A regression model that treats each hour as an independent, unordered data point is incorrect because it discards the temporal relationships, such as how demand at one hour strongly influences demand in the next, that give forecasting its accuracy; ignoring that order loses the seasonality and momentum patterns that are central to predicting a full week of sequential demand. Because the task depends on ordered, sequential prediction across many future steps, time-series forecasting is the approach that matches the requirement.