
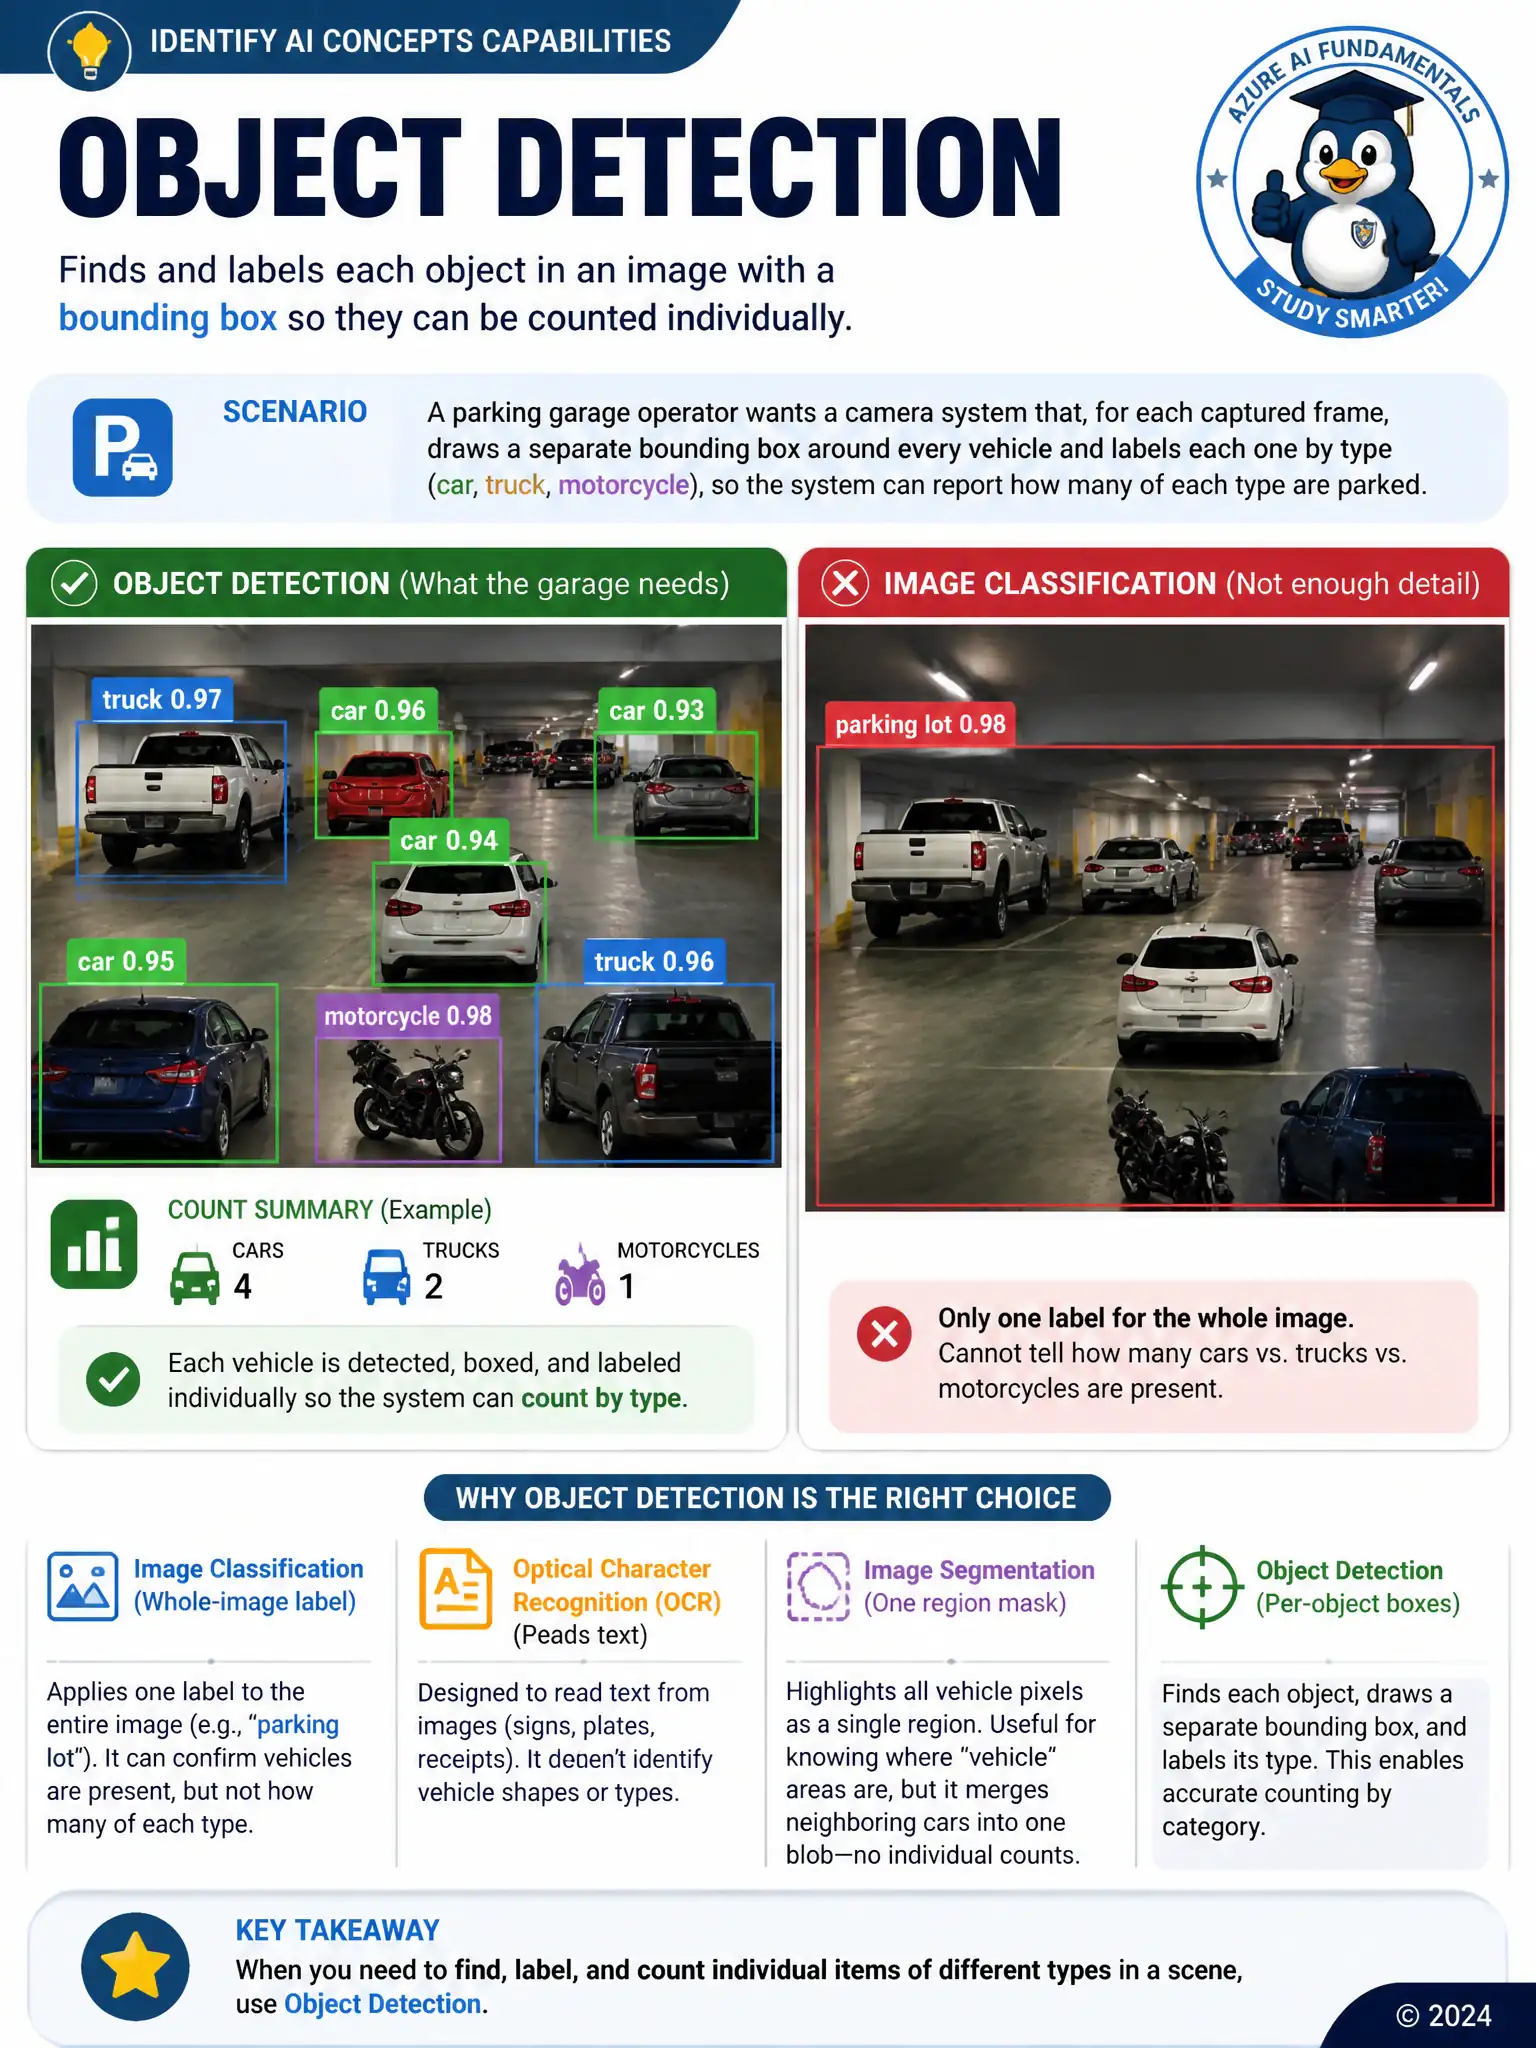
A parking garage operator wants a camera system that, for each captured frame, draws a separate bounding box around every vehicle in view and labels each one by type (car, truck, motorcycle), so the system can report how many of each type are currently parked. Which Azure AI Vision capability should the team use?
Select an answer to reveal the explanation.
Short Explanation
You need object detection because it draws a separate bounding box around each vehicle and labels each one, so you can count cars, trucks, and motorcycles in the same frame. Image classification only labels the whole image, OCR reads text, and semantic segmentation marks pixel regions without separating each vehicle as its own countable instance.
Full Explanation
Object detection is correct because it returns a bounding box and a label for each individual item in an image, which is exactly what the garage needs to isolate and count multiple vehicles of different types within a single frame. Image classification is incorrect because it assigns one label to the entire image, such as 'parking lot,' and cannot localize or distinguish multiple vehicles within that same frame. Optical character recognition (OCR) is incorrect because it extracts printed or handwritten text, such as license plate numbers or signage, and has no mechanism for identifying or counting vehicle types. Semantic segmentation is incorrect because it classifies every pixel into a category, such as marking all 'vehicle' pixels as one class, but it does not separate touching or overlapping vehicles into distinct, countable instances the way object detection's individual bounding boxes do. Because the garage's requirement is discrete counts per labeled vehicle, only object detection satisfies both the localization and the per-instance labeling the scenario demands.