
A manufacturer wants a vision model that recognizes forty different proprietary bracket models unique to its own product line, none of which appear in any public image dataset. The pre-built image classification API the team evaluated was trained on common household and industrial objects and cannot tell the forty brackets apart, returning only a generic 'metal part' label for all of them. What should the team do to get accurate, part-specific results?
Select an answer to reveal the explanation.
Short Explanation
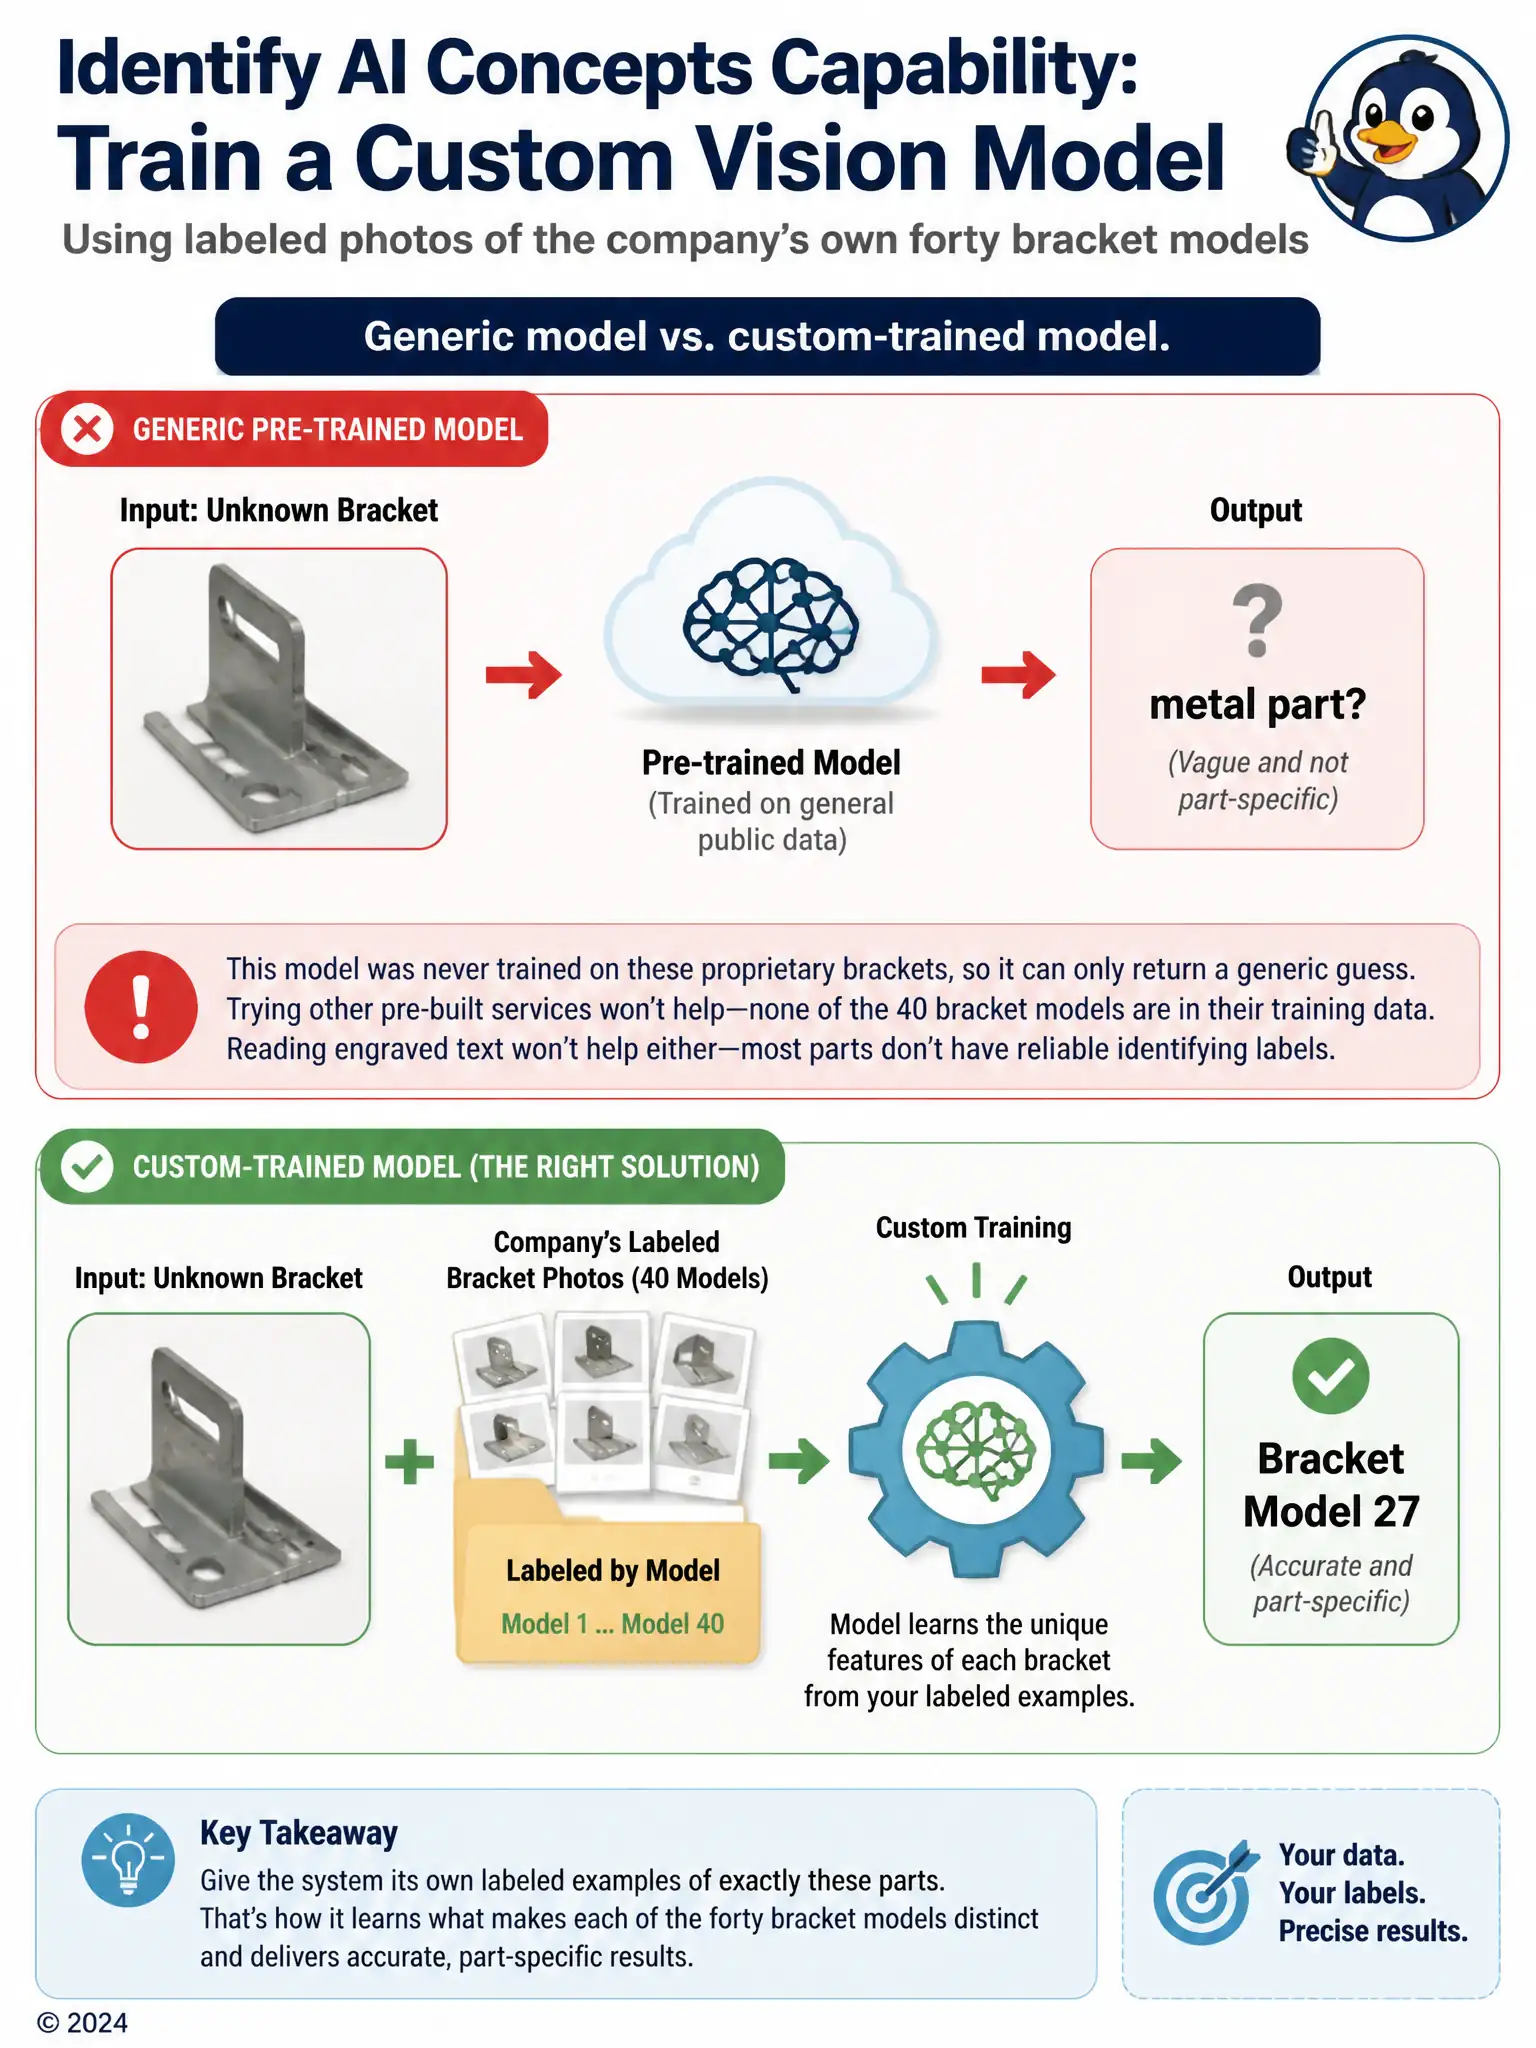
You need to train a custom vision model using labeled photos of the company's own forty bracket models. The pre-built API has never seen these proprietary parts, so it can only give a generic label. Giving the model your own labeled examples lets it learn the visual differences that make each bracket unique.
Full Explanation
The correct choice is training a custom vision model using labeled photos of the company's own forty bracket models. Because the forty bracket models are proprietary and absent from any public training data, the only way to get part-specific labels is to train a custom vision model on photos of those exact brackets, which is precisely what custom vision services are designed for: taking a small, labeled dataset unique to one organization and producing a model that recognizes those specific categories. Continuing to use the pre-built classification API as is is incorrect because that API already demonstrated it cannot distinguish the brackets, returning only a generic label, so continuing to use it unchanged would not solve the problem. Switching to an object detection API instead is incorrect because switching from classification to a different pre-built API does not address the root issue; a pre-built object detection model trained on common objects would be just as unable to recognize proprietary brackets it has never seen, since detection is not inherently more accurate than classification, only structured to locate items rather than label a whole image. Applying optical character recognition to the brackets is incorrect because optical character recognition extracts printed or engraved text characters, not visual part shapes, and most brackets carry no readable identifying text at all. Custom training on labeled examples is the only path to part-specific accuracy here.