
A company records its weekly three-person planning meetings and wants a transcript that not only converts the speech to text but also labels each line with which of the three participants said it, so readers can follow who proposed each action item. Beyond basic speech-to-text transcription, which additional capability does the team need?
Select an answer to reveal the explanation.
Short Explanation
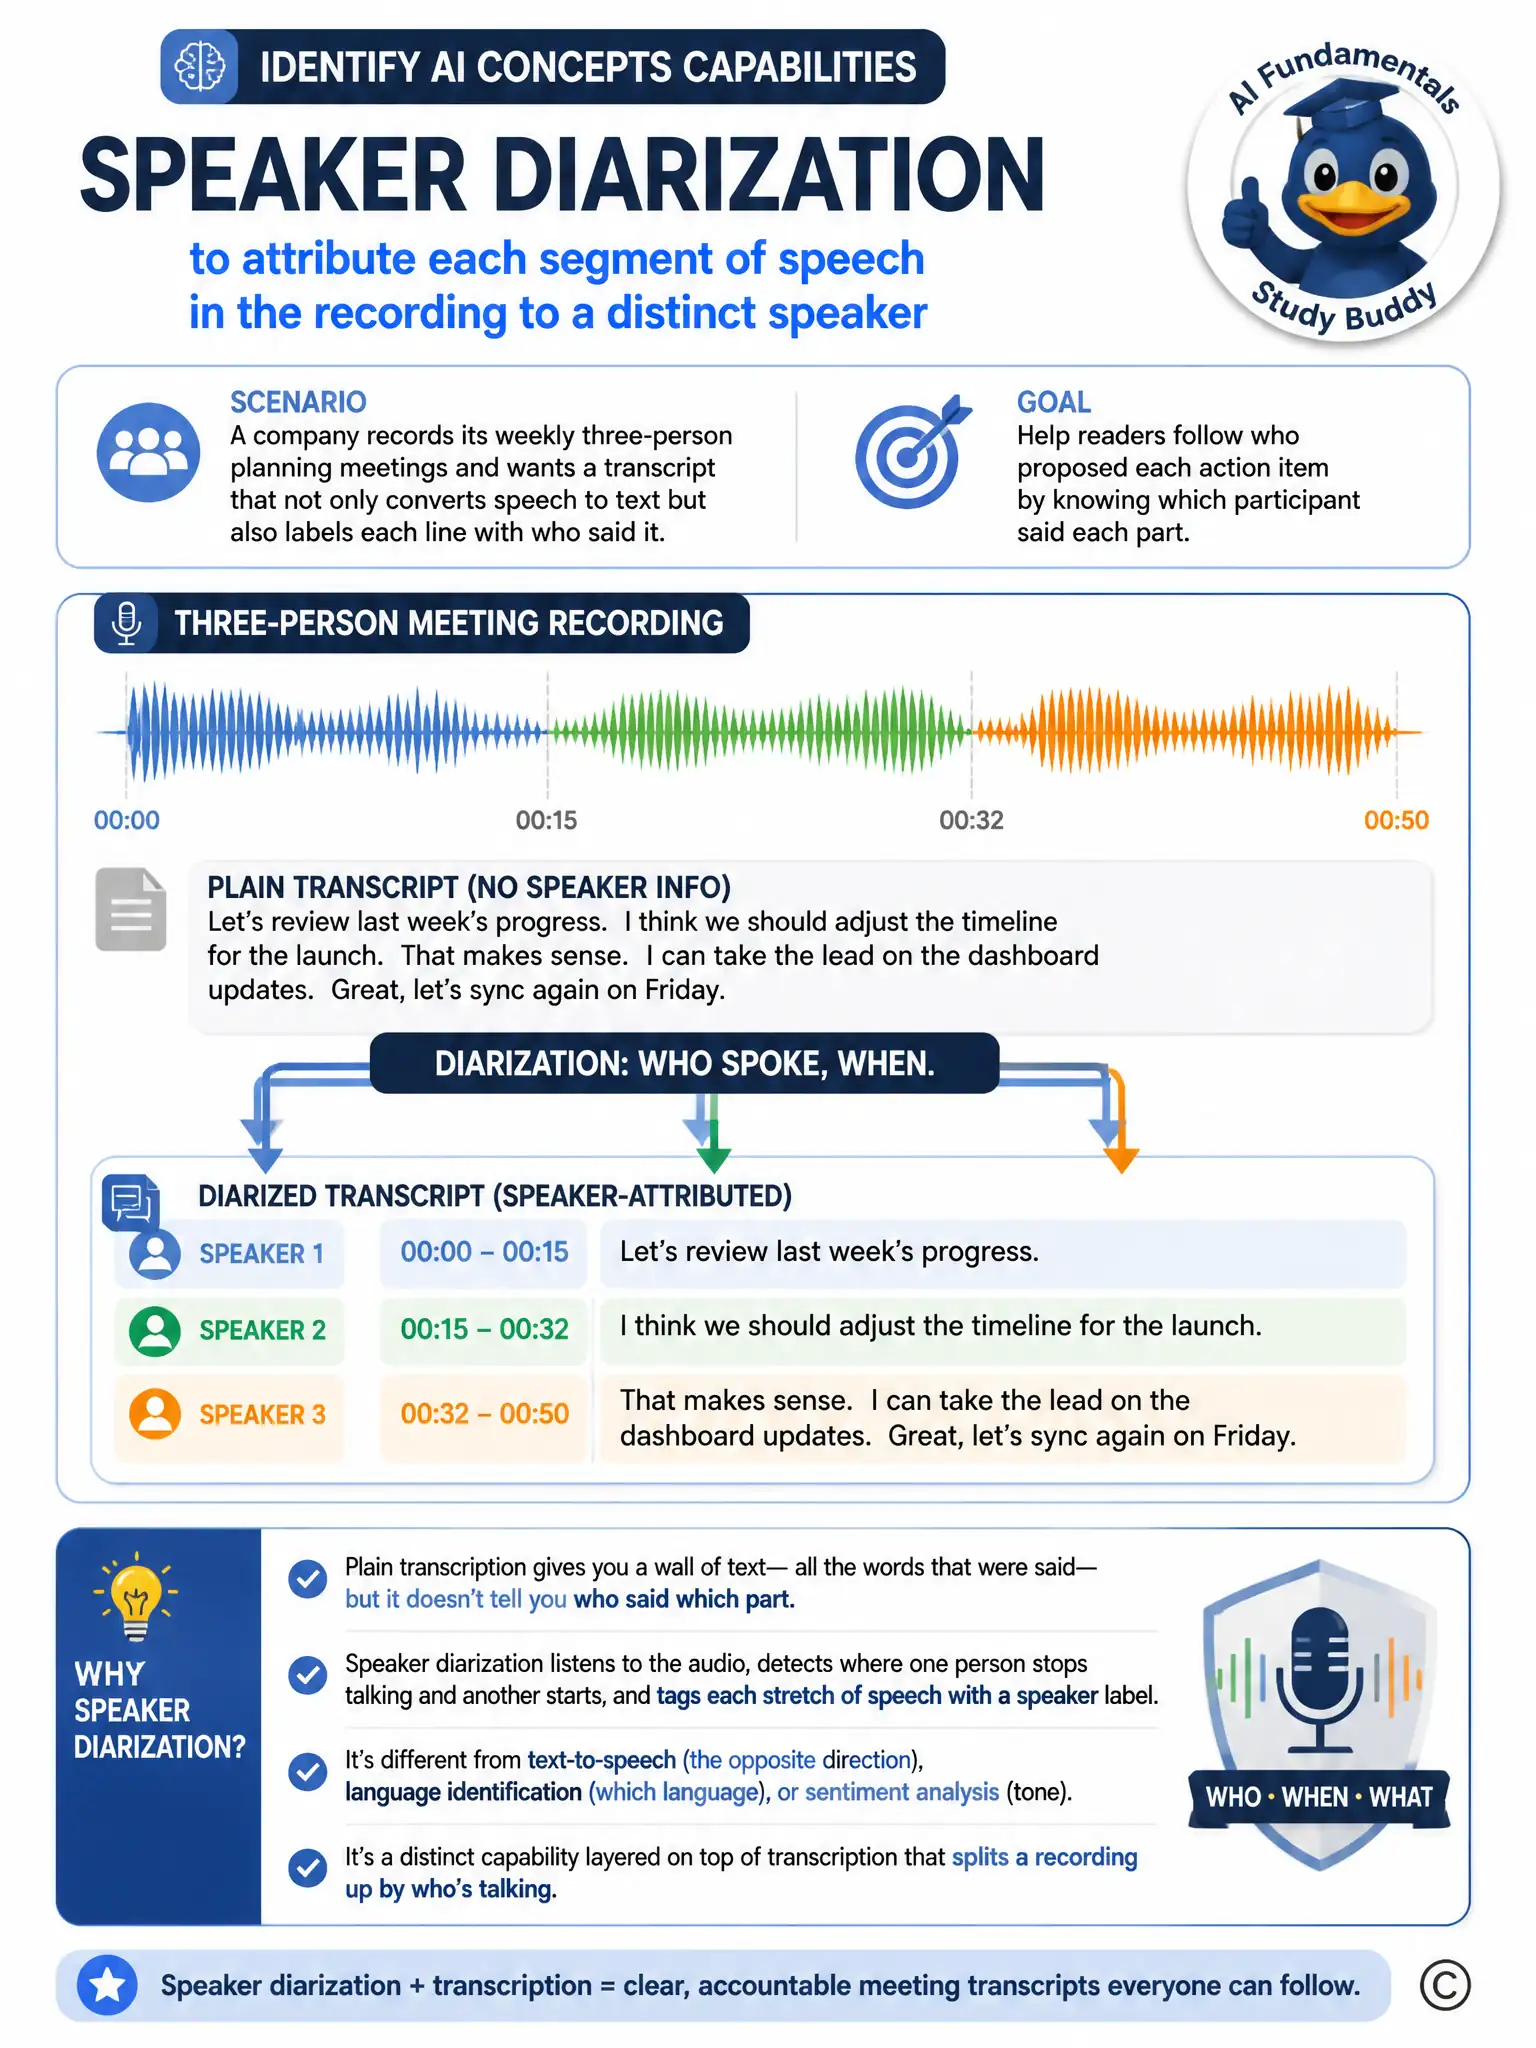
Plain transcription gives you a wall of text, but it doesn't tell you who said which part. You need speaker diarization to split the recording and tag each stretch of speech with a speaker label. It's a separate layer on top of transcription.
Full Explanation
Basic transcription alone converts audio to a stream of text but does not know who said what, so the team additionally needs speaker diarization, which segments a recording and attributes each stretch of speech to a distinct speaker so the transcript can label lines by participant. The capability that generates a separate audio track for each speaker is incorrect because speech synthesis generates spoken audio from text, the reverse of what the team needs, and does nothing to attribute existing speech to individual speakers. The capability that identifies which language is being spoken in the meeting is incorrect because language detection identifies which language is being spoken, which is not the team's problem here since all three participants presumably speak the same language; the missing piece is who spoke, not what language was used. The capability that judges the emotional tone of each participant's remarks is incorrect because sentiment analysis scores emotional tone, which would tell readers how a remark sounded but not which of the three participants made it, leaving the core requirement of speaker attribution unsolved. Speaker diarization is the specific capability layered on top of transcription to separate a multi-person recording into per-speaker segments.