
A health-system team is preparing to launch a Foundry-hosted symptom-checker chatbot for patients. Because incorrect guidance could lead to real harm, the team wants both an automated check for unsafe content and a safeguard that catches subtler clinical errors an automated filter would miss. (Select TWO.) Which two practices should they put in place before general release?
Select all correct answers, then click Submit.
Short Explanation
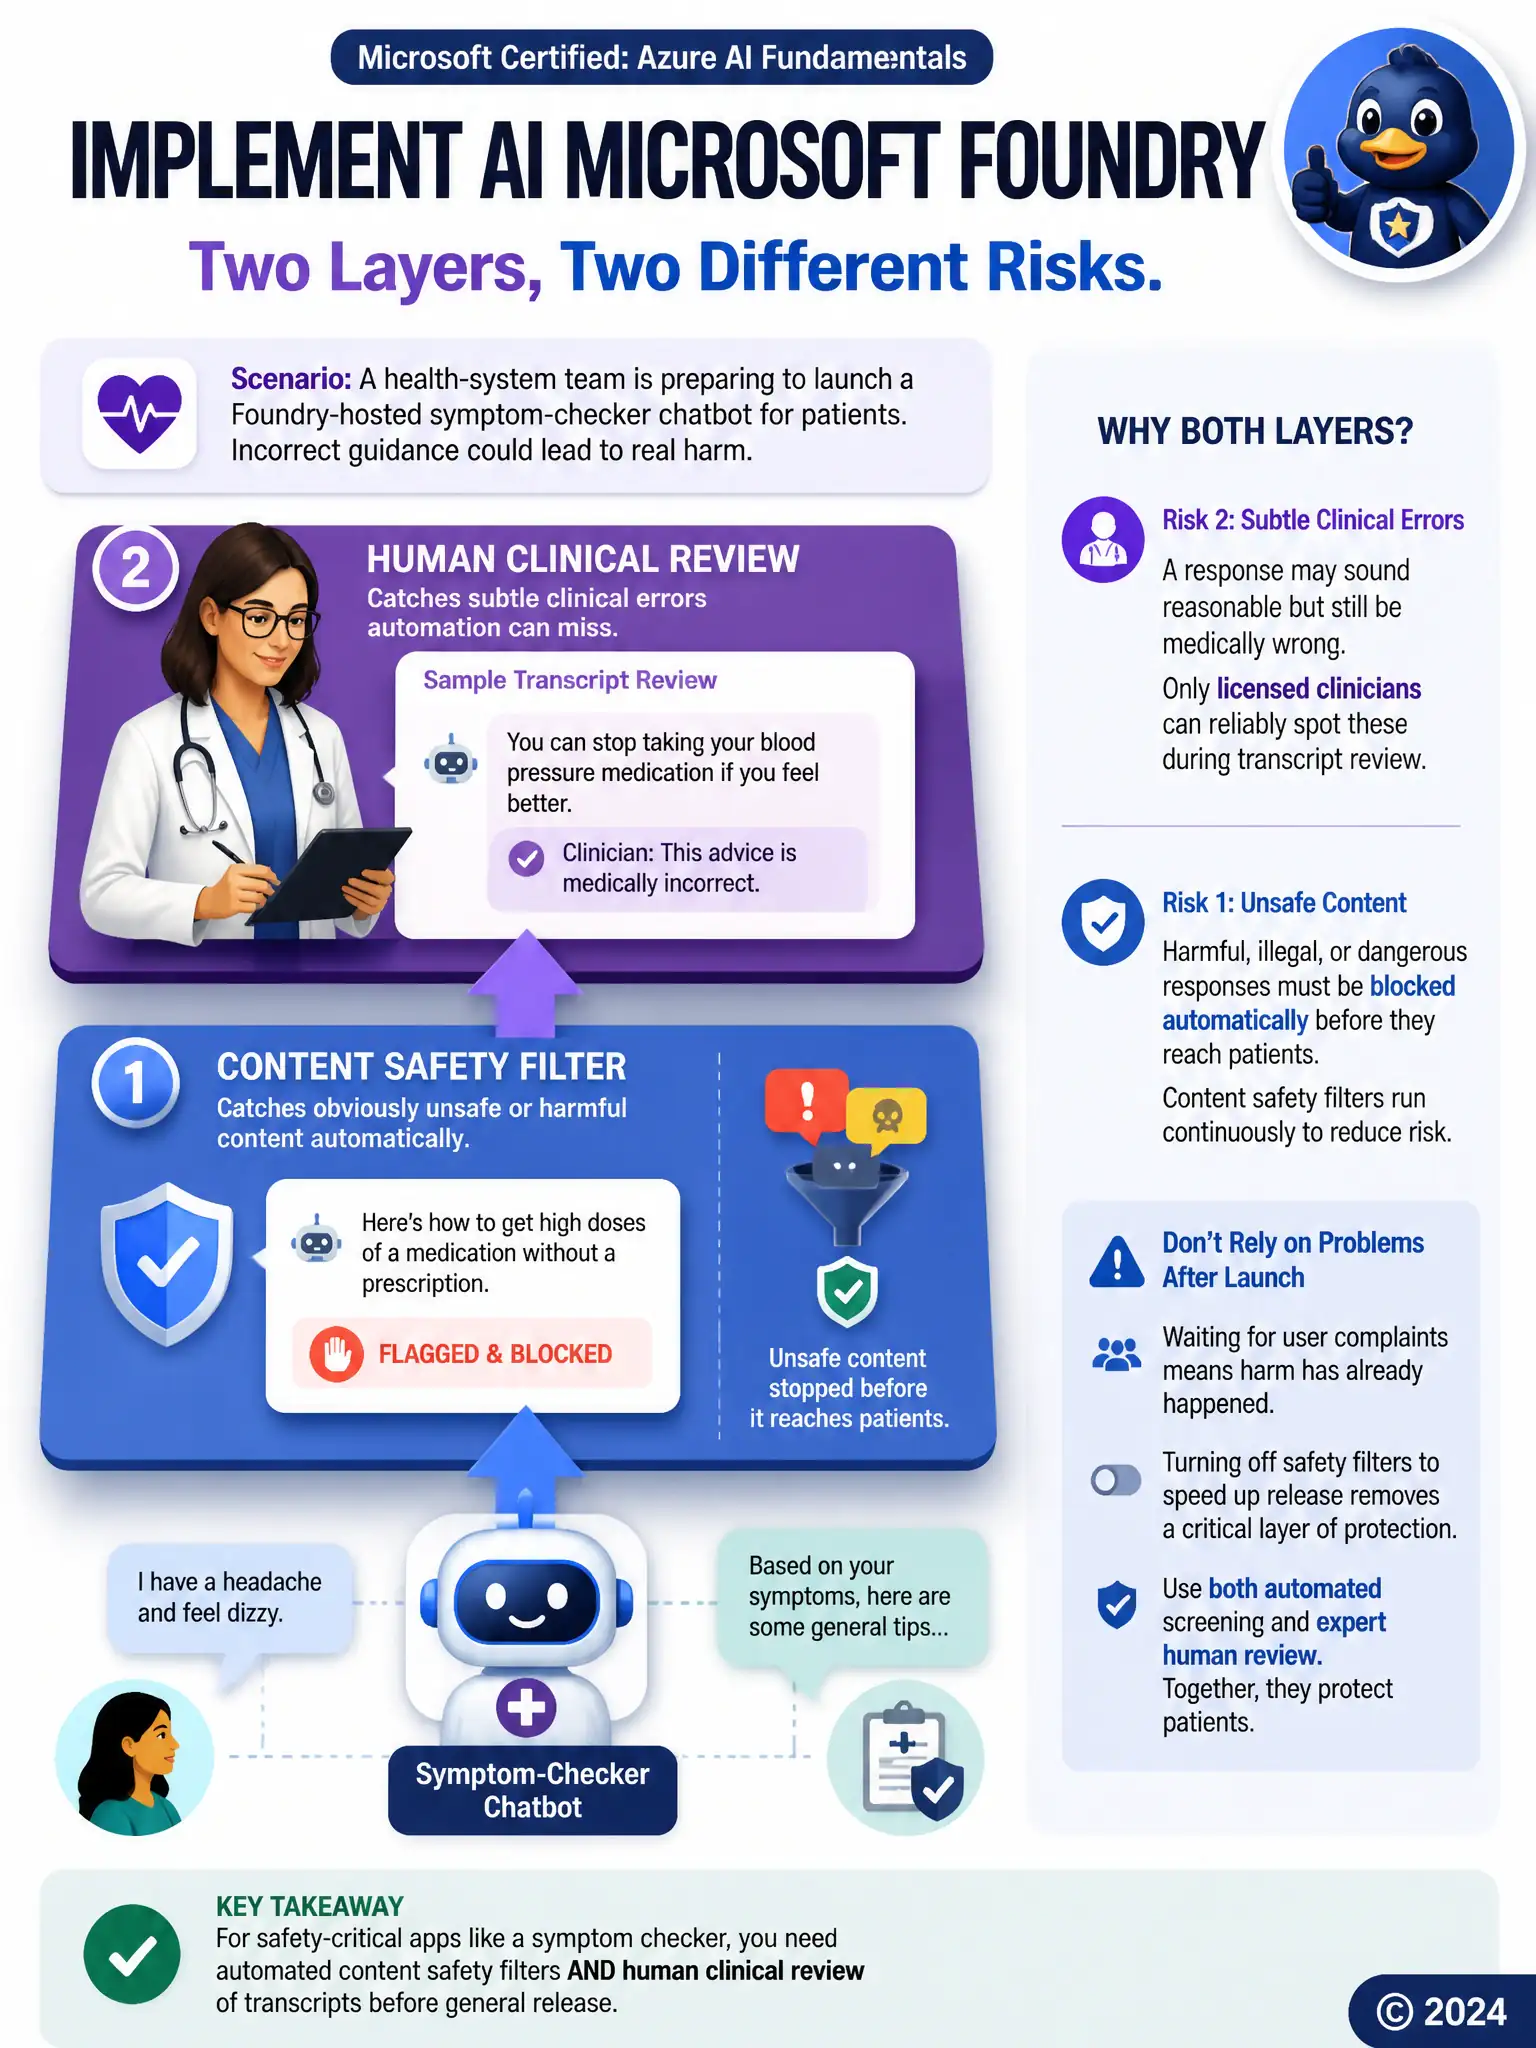
For a symptom-checker chatbot, you need both automated content safety filters and licensed clinician review before wider release. The filters catch obviously unsafe outputs, while clinicians spot subtle medical inaccuracies that automation can miss. Waiting for complaints or disabling filters leaves patients exposed to harm.
Full Explanation
The correct practices are running the deployment's content safety filters and having licensed clinicians review a sample of chatbot transcripts for medical accuracy before the wider release. Running the deployment's content safety filters gives an automated, consistent first line of defense that flags or blocks clearly harmful or unsafe output before it reaches a patient, while having licensed clinicians review a sample of transcripts catches the subtler kind of mistake an automated filter is not equipped to judge, whether a piece of medical guidance is actually accurate and appropriate, not just whether it contains obviously unsafe language. Relying solely on user complaints after launch is incorrect because it is a purely reactive approach; by the time a complaint arrives, a patient may already have acted on incorrect guidance, so it does nothing to prevent harm before it happens. Disabling content filtering is incorrect because it removes an automated safeguard specifically to gain speed, trading away a meaningful layer of protection in a domain where an unsafe response carries real consequences, which is the opposite of what a symptom-checker launch should prioritize. Combining automated content safety checks with human clinical review addresses two different kinds of risk, one catching broadly unsafe content at scale and the other catching domain-specific accuracy problems, which together give this team a stronger safety net than either measure alone before they open the chatbot to the wider patient population.