
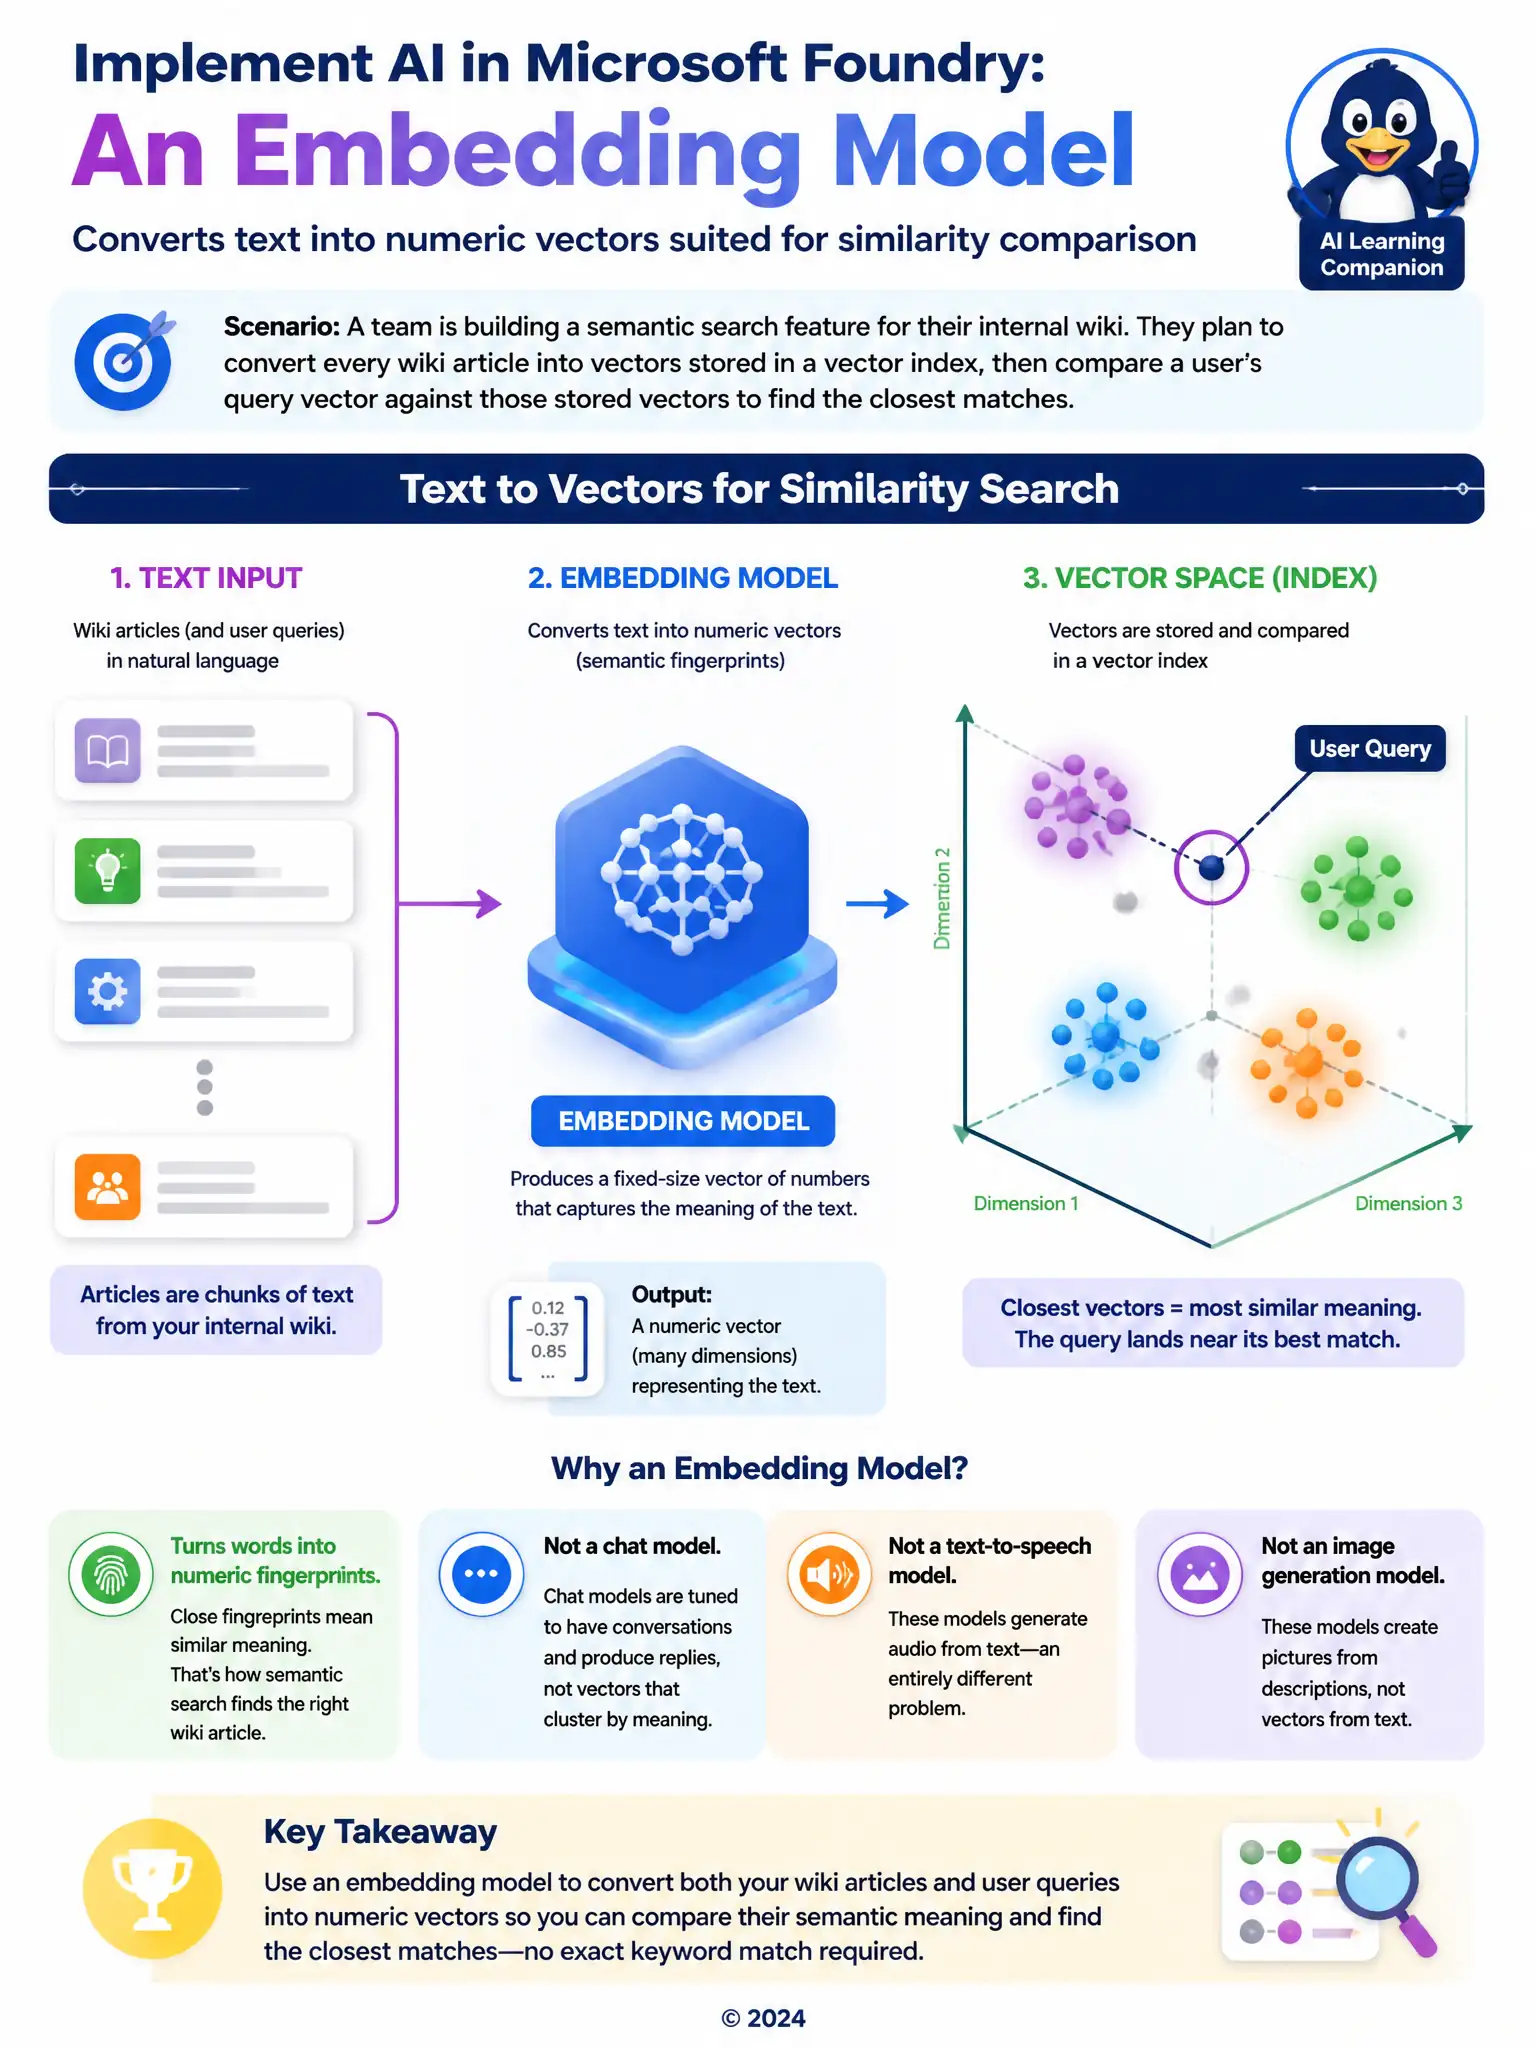
A team is building a semantic search feature for their internal wiki. They plan to convert every wiki article into vectors stored in a vector index, then compare a user's query vector against those stored vectors to find the closest matches. When browsing the Foundry model catalog, which type of model should they select to generate these vectors?
Select an answer to reveal the explanation.
Short Explanation
You need an embedding model because it turns text into numeric fingerprints, and similar meanings end up close together in vector space. Chat completion models, text-to-speech models, and image generation models do different jobs, so they won't give you the vectors your search index needs.
Full Explanation
The correct choice is the embedding model, which is purpose-built to convert text into numeric vectors positioned so that semantically similar content ends up close together in vector space. That is exactly what a search feature needs when comparing a user's query against every stored wiki article. Chat completion models are incorrect because they are optimized to generate natural-language replies to a conversation, not to produce vectors tuned for similarity comparison, so using such models for this step would be working against their intended purpose. The text-to-speech model is incorrect because it converts written text into audio and has no role in producing searchable vector representations. The image generation model is incorrect because it produces pictures from text prompts, which addresses a completely different modality and has nothing to do with indexing written wiki content for search. Selecting the right model type from the catalog matters because each category is trained and optimized for a distinct job; picking an embedding model here ensures the vectors stored in the index and the vector generated from a user's query were produced the same way, which is what makes accurate similarity matching possible.