
A company deploys a Foundry-hosted assistant to screen incoming job applications and generate a shortlist recommendation for recruiters. During a fairness review, the team finds the assistant recommends candidates from certain universities and backgrounds at a noticeably higher rate than others, even when qualifications are similar. Which two actions should the team take to responsibly address this before continuing to use the assistant in hiring decisions? (Select TWO.)
Select all correct answers, then click Submit.
Short Explanation
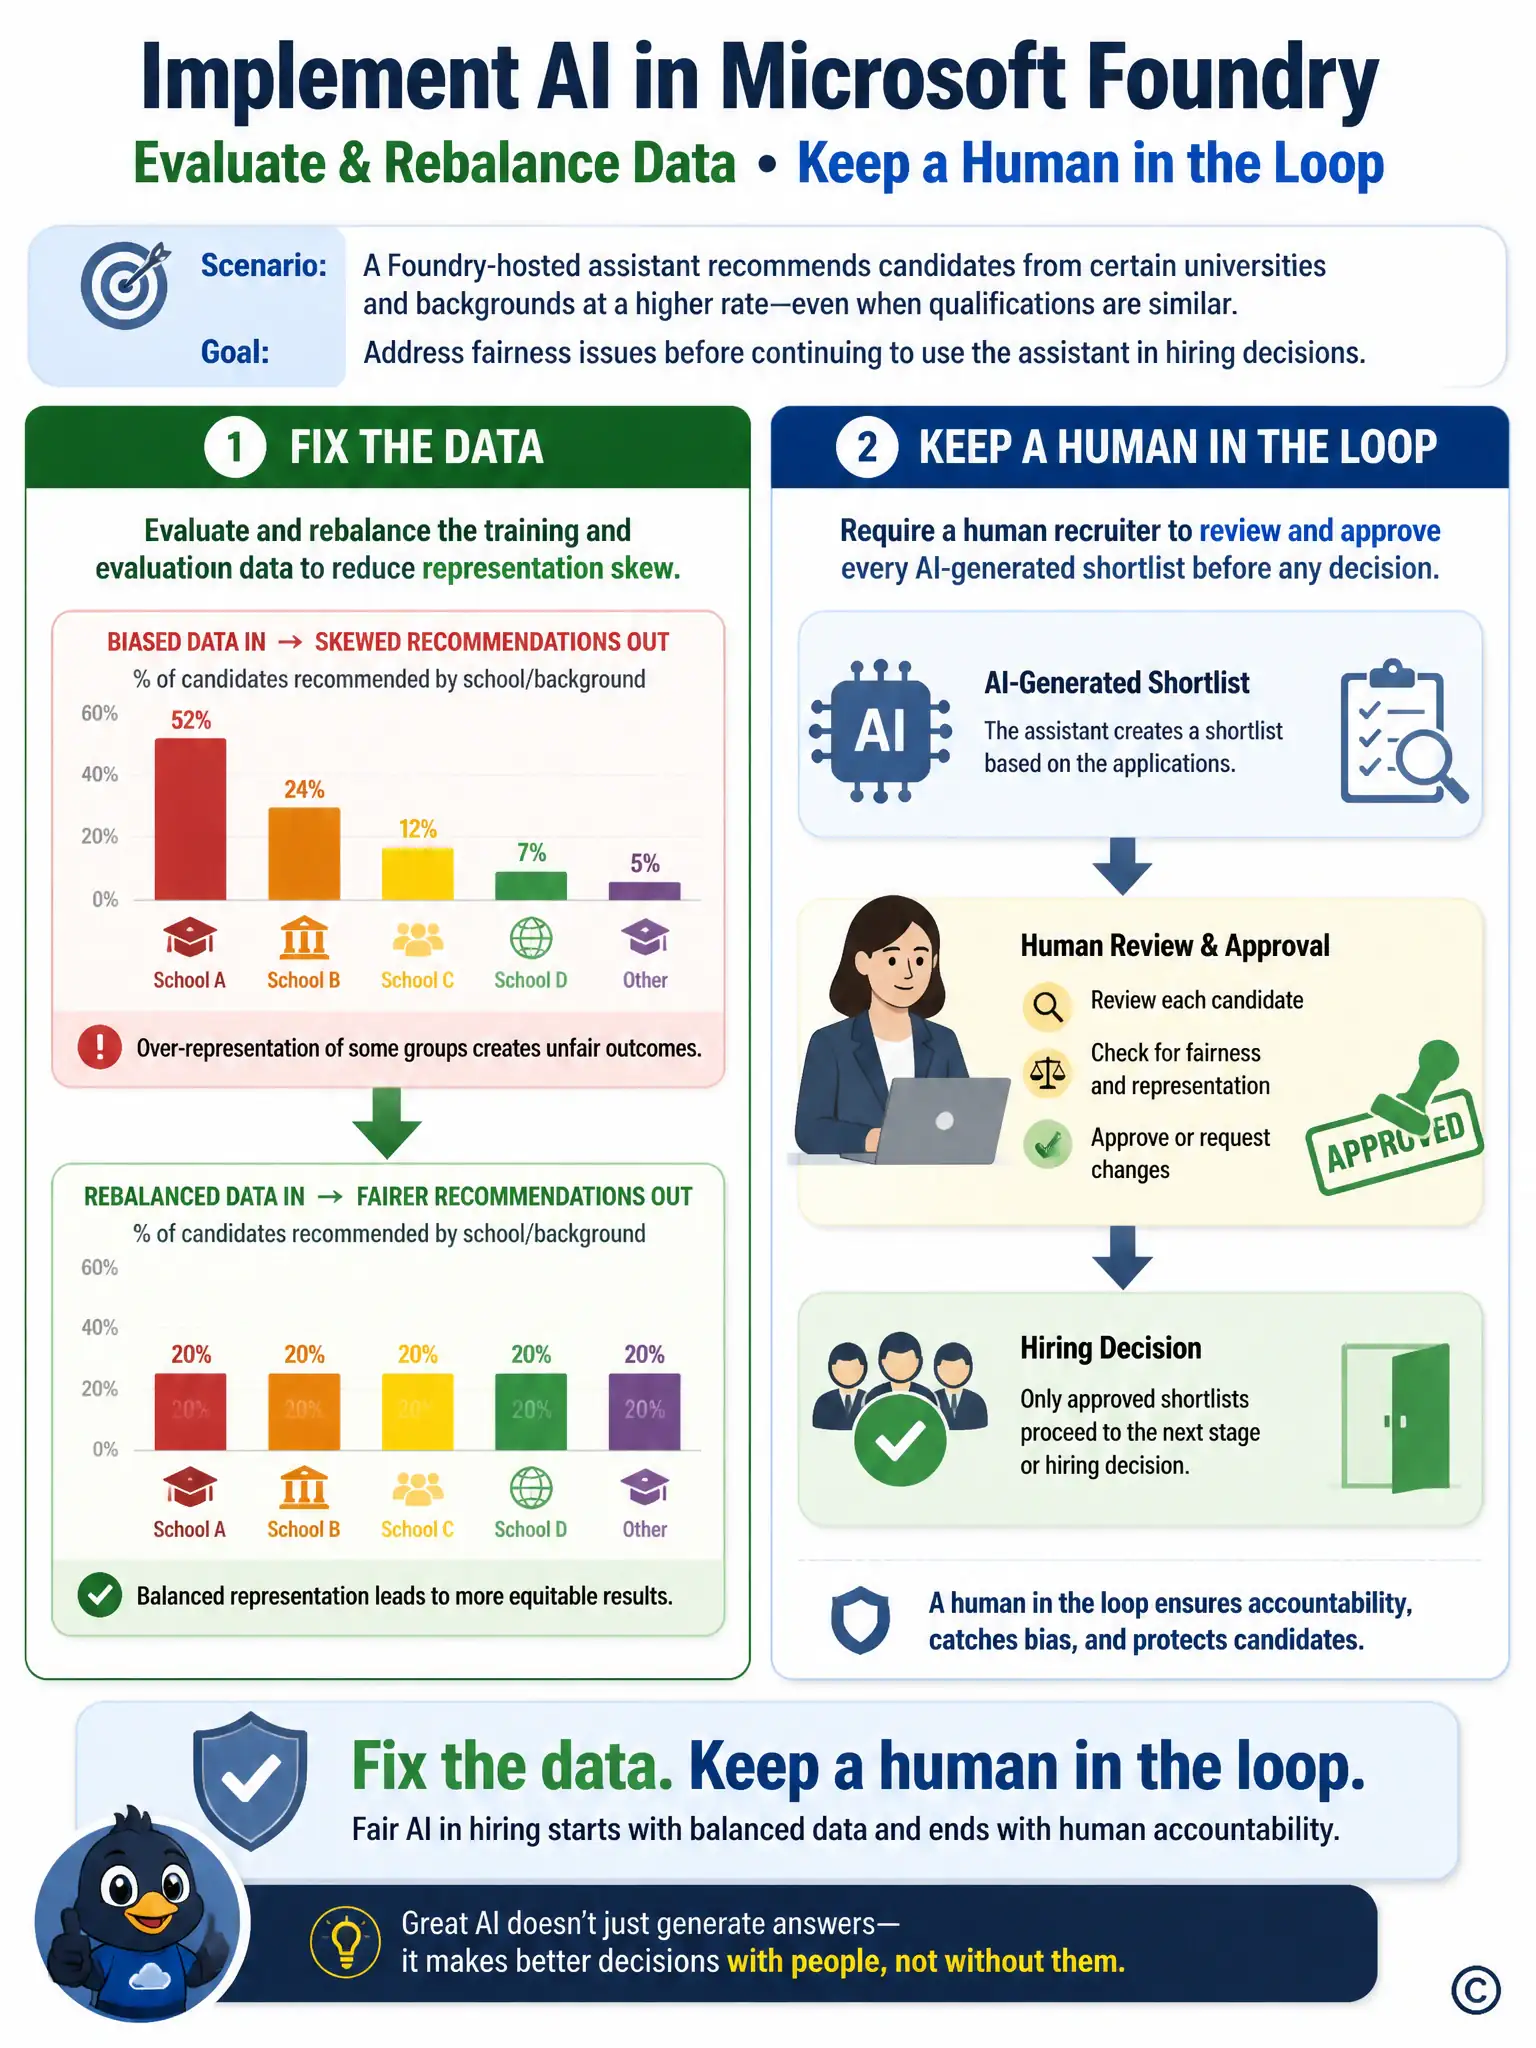
When a screening tool starts favoring certain schools or backgrounds among equally qualified candidates, you've got to fix what's feeding the recommendations and keep a recruiter in the loop. Rebalance the training and evaluation data to reduce representation skew, and require a human recruiter to review and approve every shortlist before it affects hiring. Turning up randomness or trimming explanations won't fix bias.
Full Explanation
The correct actions are evaluating and rebalancing the training and evaluation data behind the recommendations, and requiring a human recruiter to review and approve every assistant-generated shortlist before any hiring decision. Evaluating and rebalancing the data directly targets the root cause the fairness review uncovered, which is skewed representation driving unequal outcomes for similarly qualified candidates, and it aligns with the responsible artificial-intelligence principle of fairness that Foundry deployments in high-stakes areas like hiring are expected to follow. Requiring a human recruiter to review and approve every shortlist adds the human oversight that responsible guidance calls for in consequential decisions, catching biased recommendations before they affect a real candidate's outcome. Increasing the temperature setting is incorrect because it only makes the model's wording and specific picks more varied or random; it does not address why certain universities or backgrounds are systematically favored, and it could even make outcomes less predictable without fixing the underlying skew. Reducing the assistant's maximum response length is incorrect because it changes how much explanation text is generated, not which candidates get recommended or why, so it has no effect on the fairness problem the review identified. Bias in a hiring tool has to be addressed at the data and oversight level, not through generation-length or randomness settings, which is why the two data-and-review actions are the ones that responsibly address the finding.