
A customer support team's Foundry-hosted chatbot keeps the entire conversation history in every request so it can remember earlier turns. On long support sessions that run for dozens of messages, the assistant begins returning errors indicating the request exceeds the model's context limit, and some replies start ignoring details mentioned early in the conversation. What should the team do to keep long conversations working reliably?
Select an answer to reveal the explanation.
Short Explanation
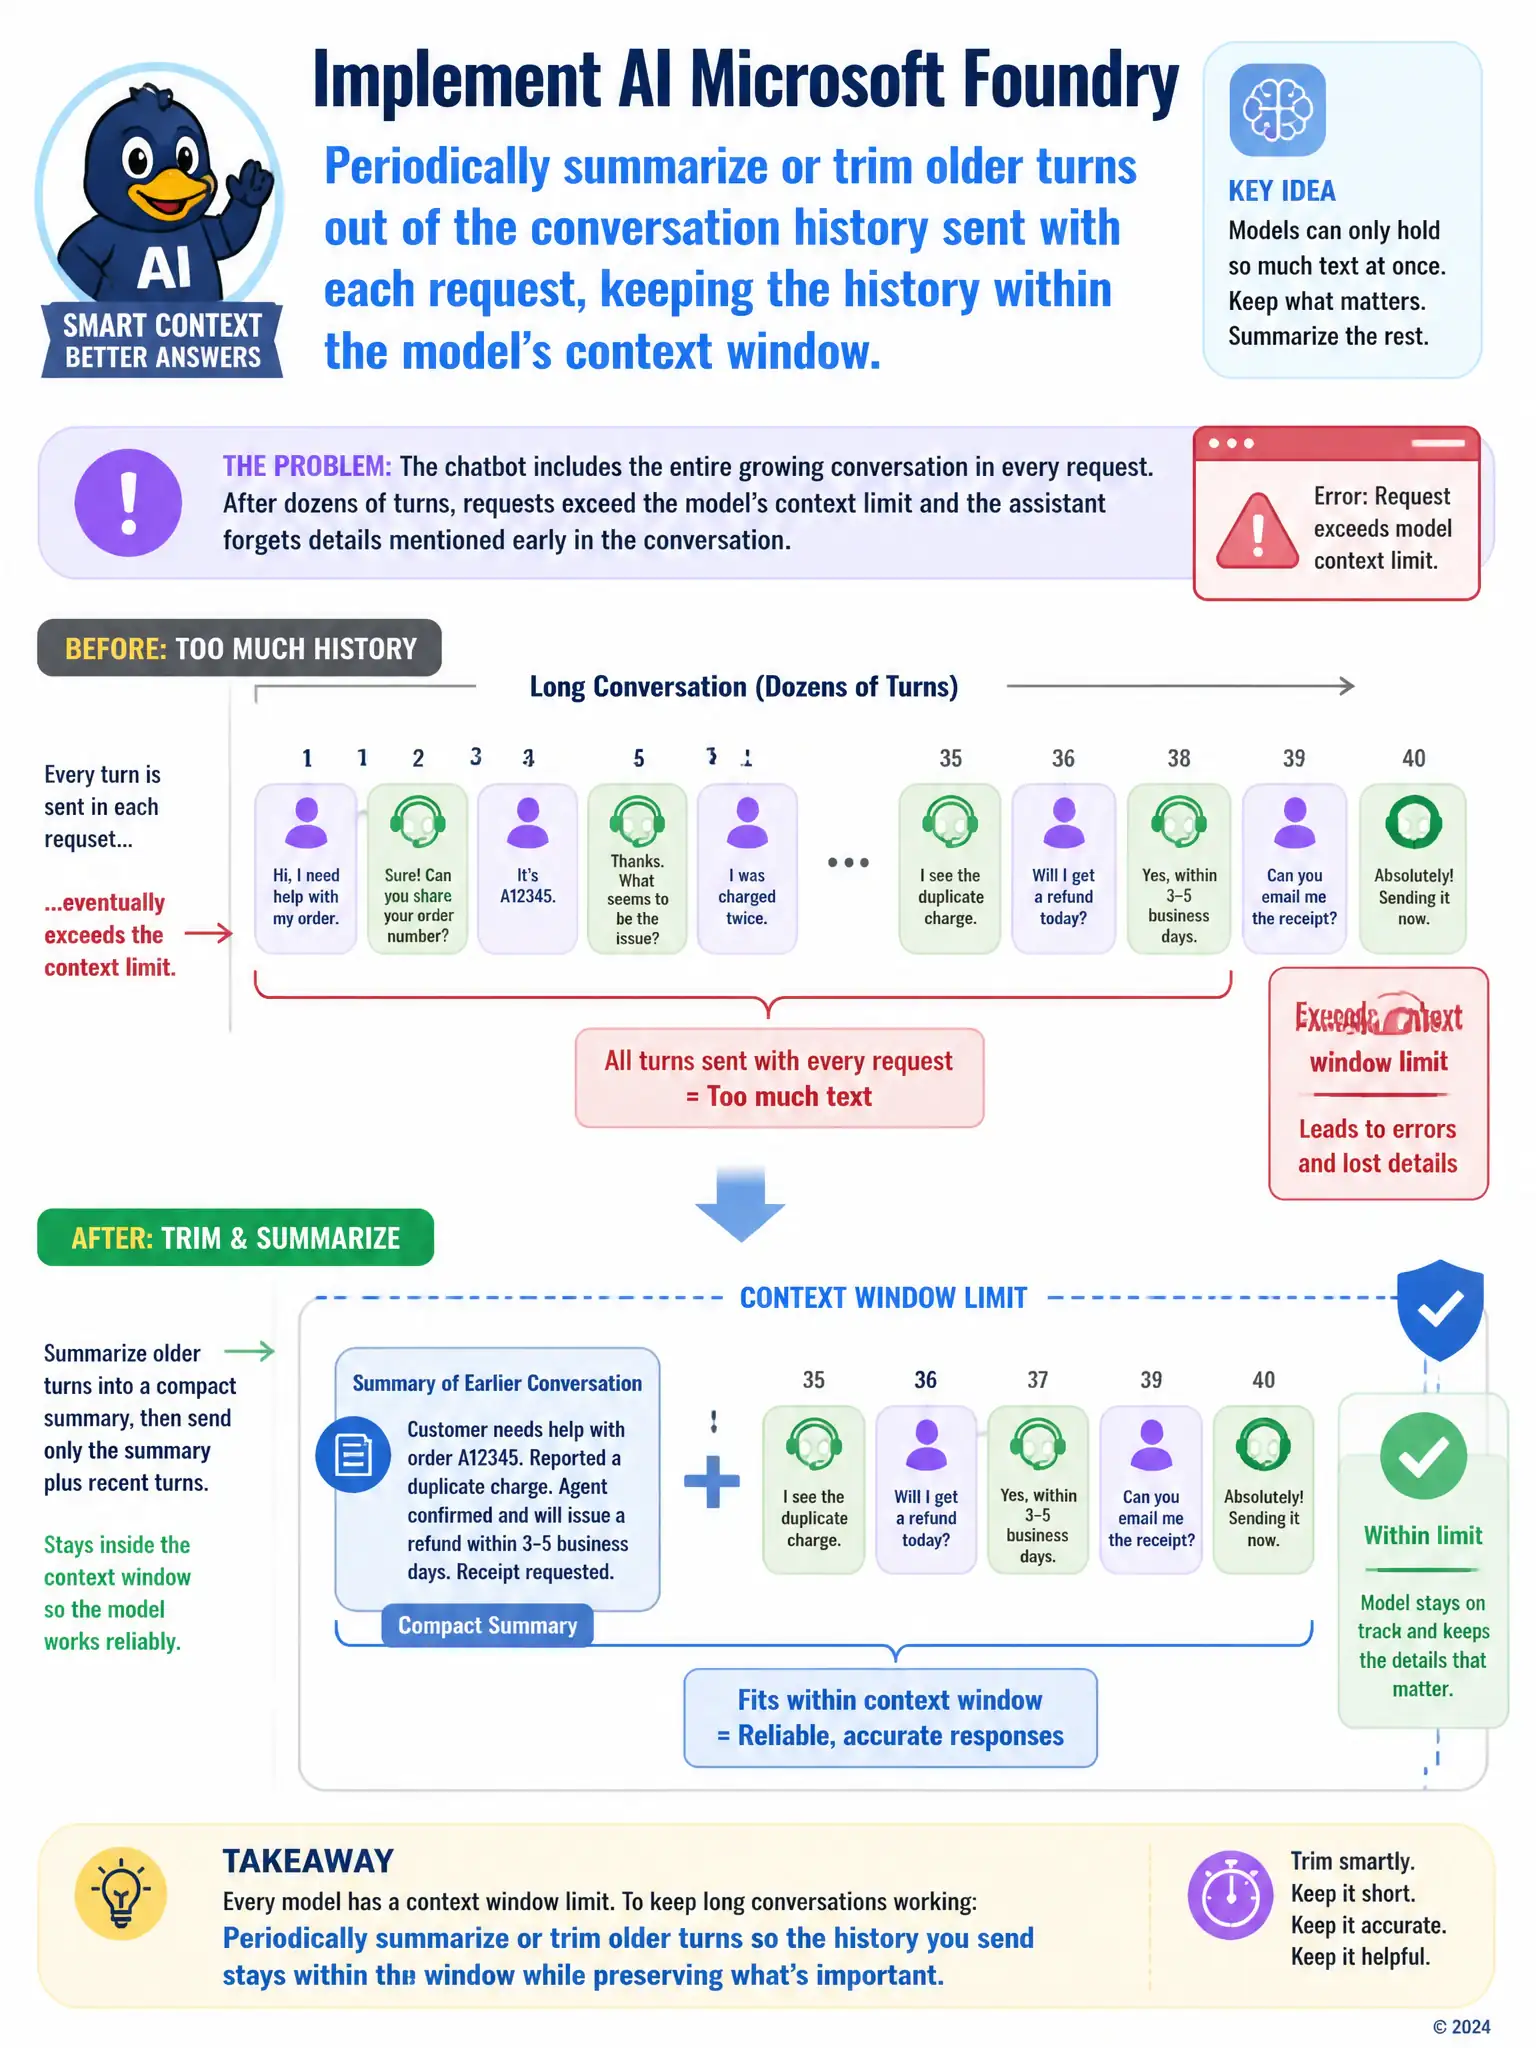
Every model can only hold so much text in its head at once, and stuffing the whole growing chat into every request eventually overflows that limit. You need to summarize or trim older turns so the history sent with each request stays inside the model's context window while keeping the details that still matter. Safety tweaks, randomness tweaks, or archiving the transcript elsewhere won't shrink the live request.
Full Explanation
The correct approach is to periodically summarize or trim older turns out of the conversation history sent with each request, keeping the history within the model's context window. Every model has a fixed context window measured in tokens, and sending the full, ever-growing history eventually exceeds that limit; summarizing or trimming older turns keeps the request within the window while preserving important details from earlier in the conversation, which resolves both the errors and the dropped-detail problem. The option about switching to a model with a lower content safety severity threshold is incorrect because content safety severity thresholds control which categories of harmful content get filtered; they have no relationship to how many tokens a request contains and would not prevent a context-limit error. The option about increasing the temperature is incorrect because temperature affects how varied or random the model's word choices are, not how much information it can access; raising it does not let the model recall details that were never included in the current request, and can make responses less reliable. The option about adding a vector index in Azure AI Search to permanently store the raw chat transcript is incorrect because storing the raw transcript in a vector index is useful for later retrieval or search, but the team's immediate problem is that too much text is being sent in each live request; simply archiving the transcript elsewhere does not by itself reduce what gets sent to the model unless it is paired with a retrieval and trimming strategy. Managing the active history sent per request is the direct fix.