
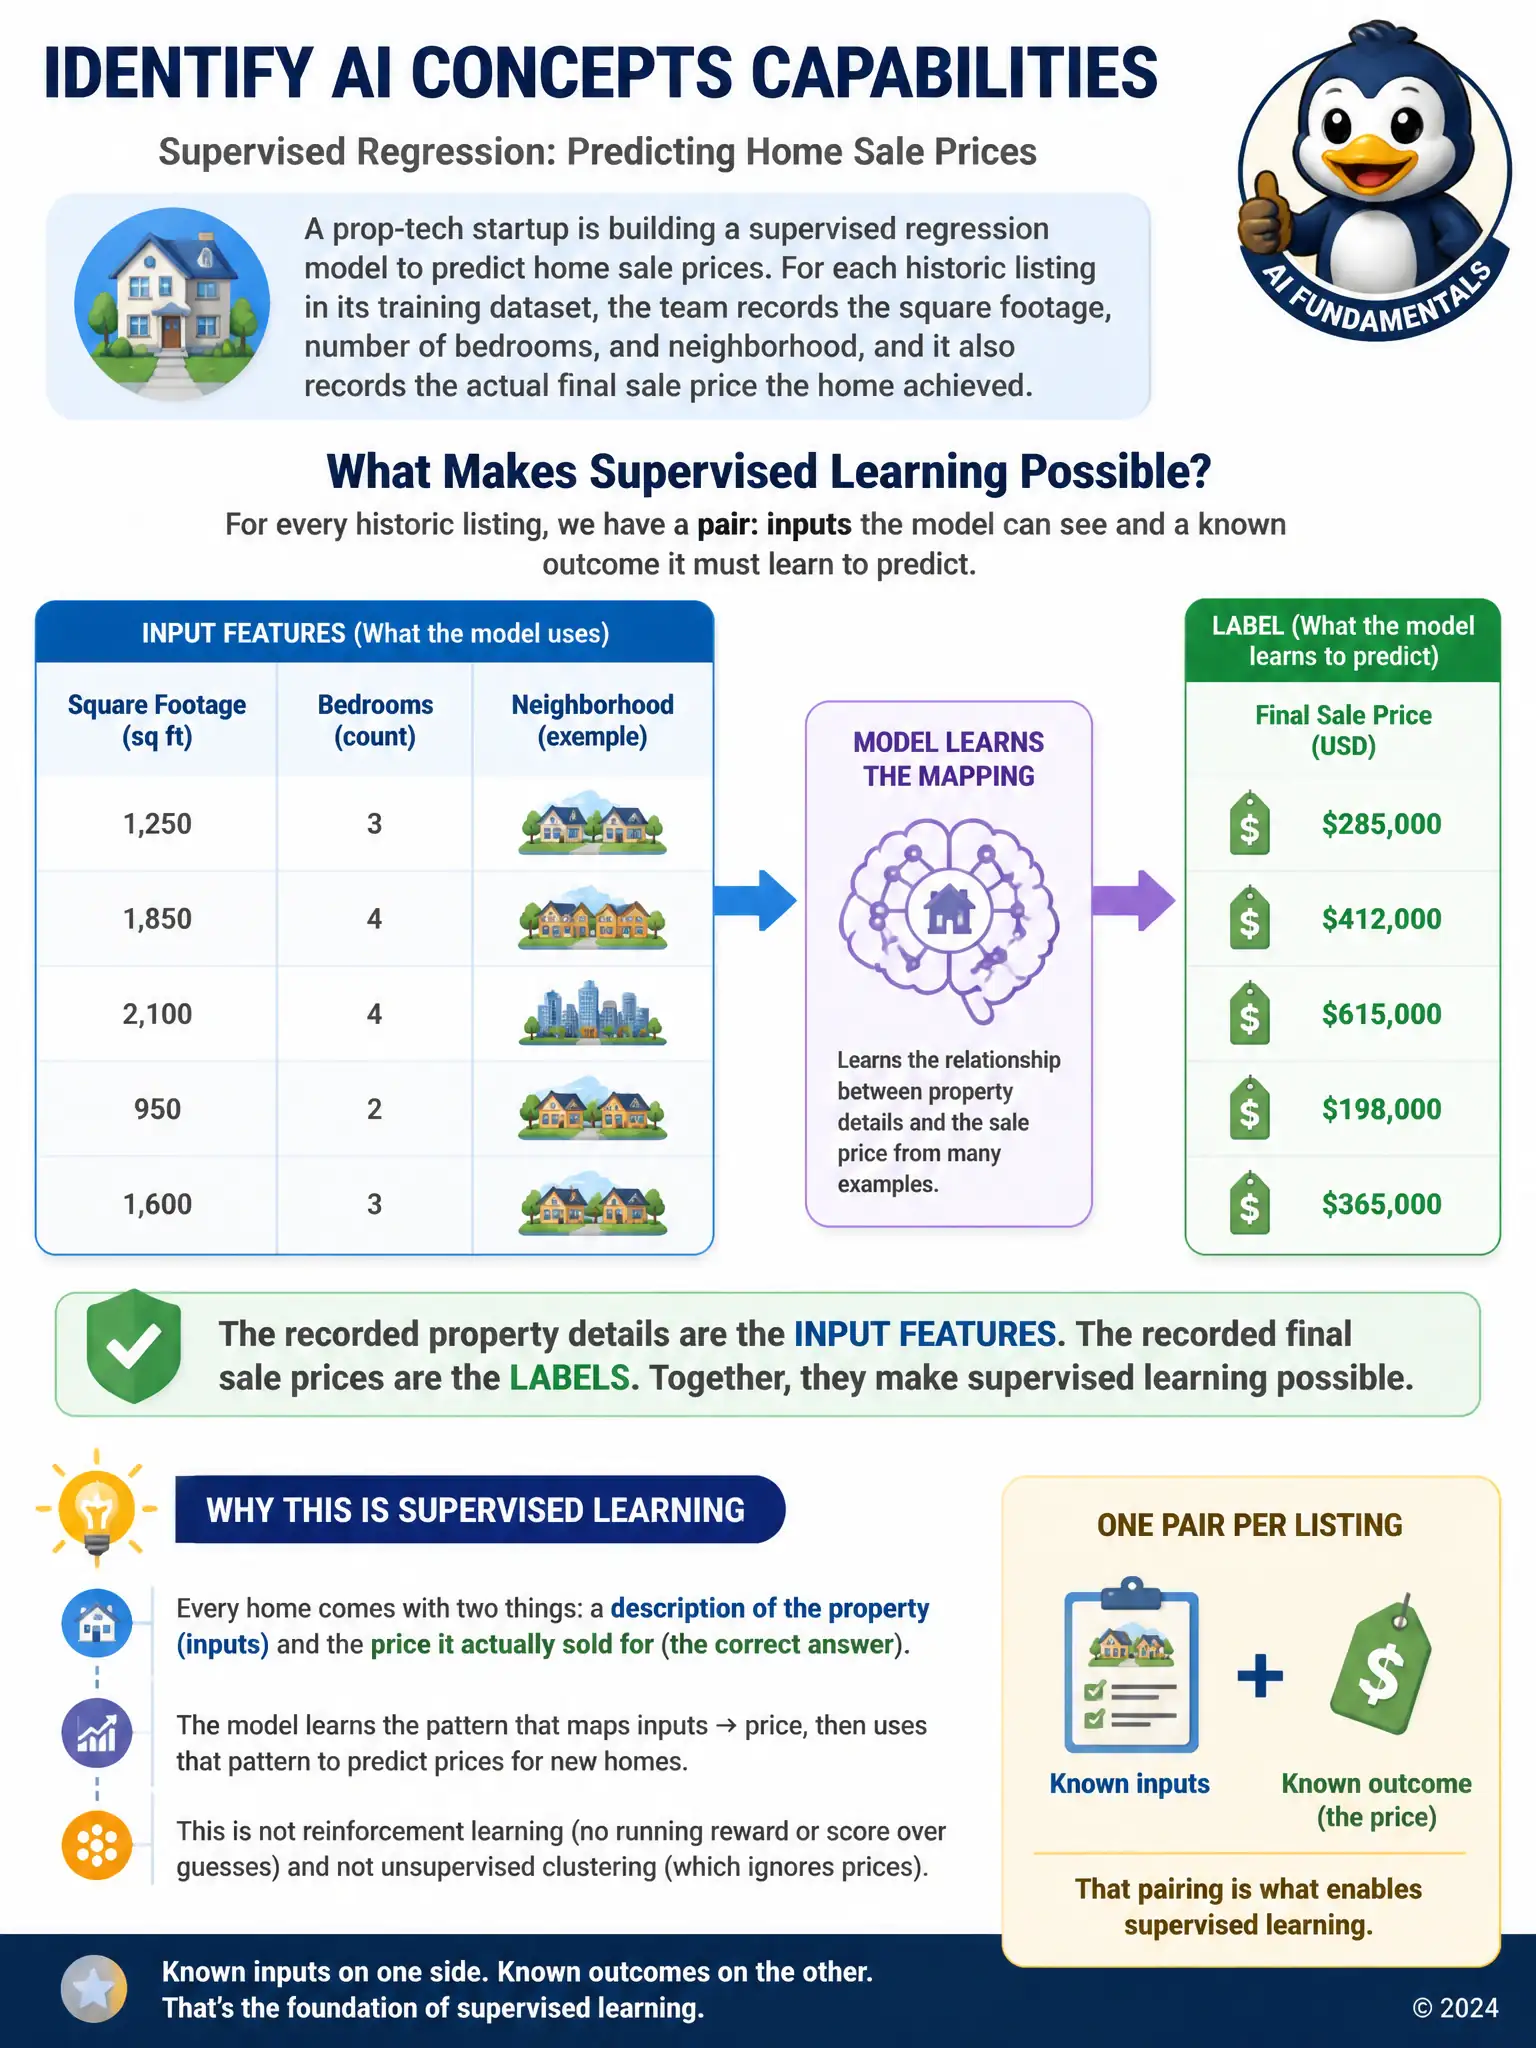
A prop-tech startup is building a supervised regression model to predict home sale prices. For each historic listing in its training dataset, the team records the square footage, number of bedrooms, and neighborhood, and it also records the actual final sale price the home achieved. (Select TWO.) Which two elements of this dataset make supervised learning possible?
Select all correct answers, then click Submit.
Short Explanation
You need both the known sale price and the property details. The price is the answer key the model learns to predict, and the square footage, bedrooms, and neighborhood are the inputs it uses. Clustering and reward signals don't make this supervised regression work.
Full Explanation
Supervised learning requires two things paired together in the training data: input features that describe each example, and a known correct output, called a label, that the model is trained to predict from those features. Here the square footage, bedroom count, and neighborhood are the input features, and the recorded final sale price is the label the model learns to map those features onto. The option describing a reward signal is incorrect because this dataset contains no reward signal at all; the model is trained by comparing its prediction directly against a known recorded price, not by accumulating a score over repeated actions the way a reinforcement learning agent would. The option describing cluster assignments is incorrect because cluster assignments belong to unsupervised learning, where groups are formed purely from similarity between examples with no reference to an outcome like price; this dataset instead pairs every example with its actual sale price, which is precisely what clustering does not require.