
A logistics company receives paper bills of lading from freight drivers. Each form has a similar layout with a shipment ID, ship and delivery dates, and a signature line in roughly the same place. The company wants software that scans a photo of each form and returns the shipment ID, dates, and signature presence as separate structured fields it can feed directly into its transportation management system, rather than just a block of extracted text. Which AI capability best fits this need?
Select an answer to reveal the explanation.
Short Explanation
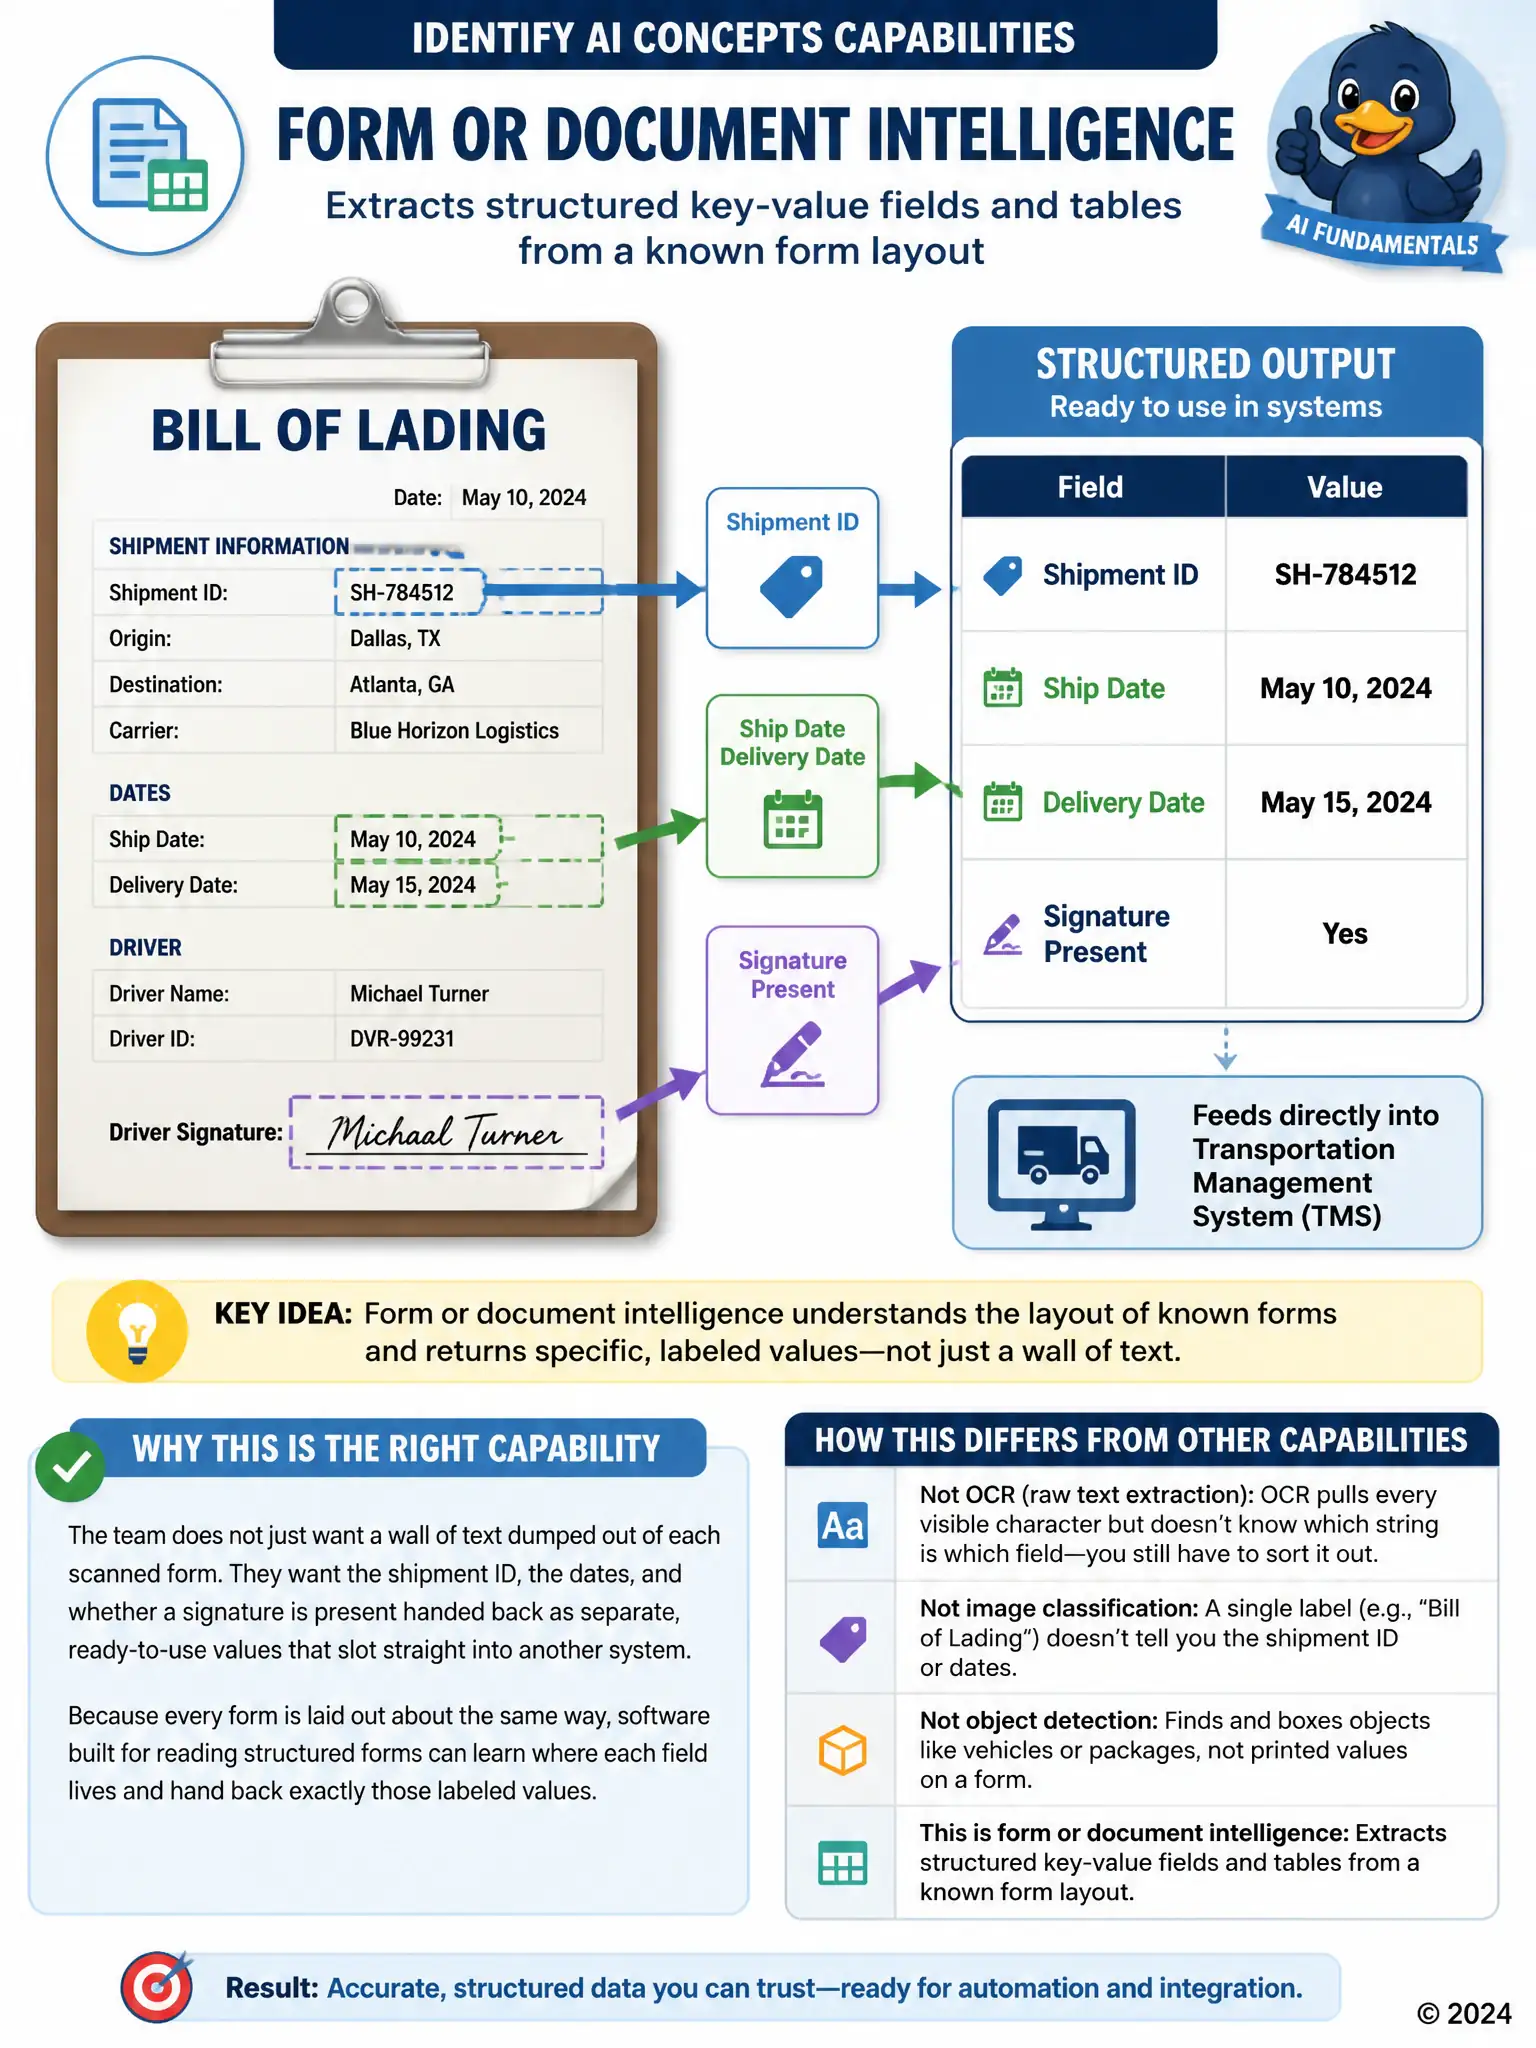
You need form or document intelligence here. It learns the consistent bill-of-lading layout and returns the shipment ID, dates, and signature presence as separate structured fields ready for your transportation management system. OCR alone, image classification, and object detection don't give you those labeled field values.
Full Explanation
The correct choice is form or document intelligence, which extracts structured key-value fields and tables from a known form layout. The company does not just want raw text pulled off the page; it wants the specific shipment ID, dates, and signature field returned as separate, structured values it can load straight into its transportation system. Because the bills of lading share a consistent layout, form or document intelligence can learn where each field sits and return key-value pairs rather than an undifferentiated block of text. The option describing optical character recognition alone is incorrect because OCR on its own only extracts all visible text from an image; it does not know that one string is the shipment ID and another is a date unless a form-understanding layer is added on top. The option describing image classification is incorrect because image classification assigns one overall label to the whole photo, such as identifying it as a bill of lading, rather than pulling out individual fields within it. The option describing object detection is incorrect because object detection locates and boxes physical objects like a truck or a pallet within an image; it is not designed to read and structure printed field values on a form.