
A conservation group deploys motion-triggered trail cameras that often capture several animals in a single photo. They need software that locates each individual animal in the frame, draws a separate box around it, and labels its species, so researchers can count how many individuals of each species appear per photo. Which computer vision capability fits this requirement?
Select an answer to reveal the explanation.
Short Explanation
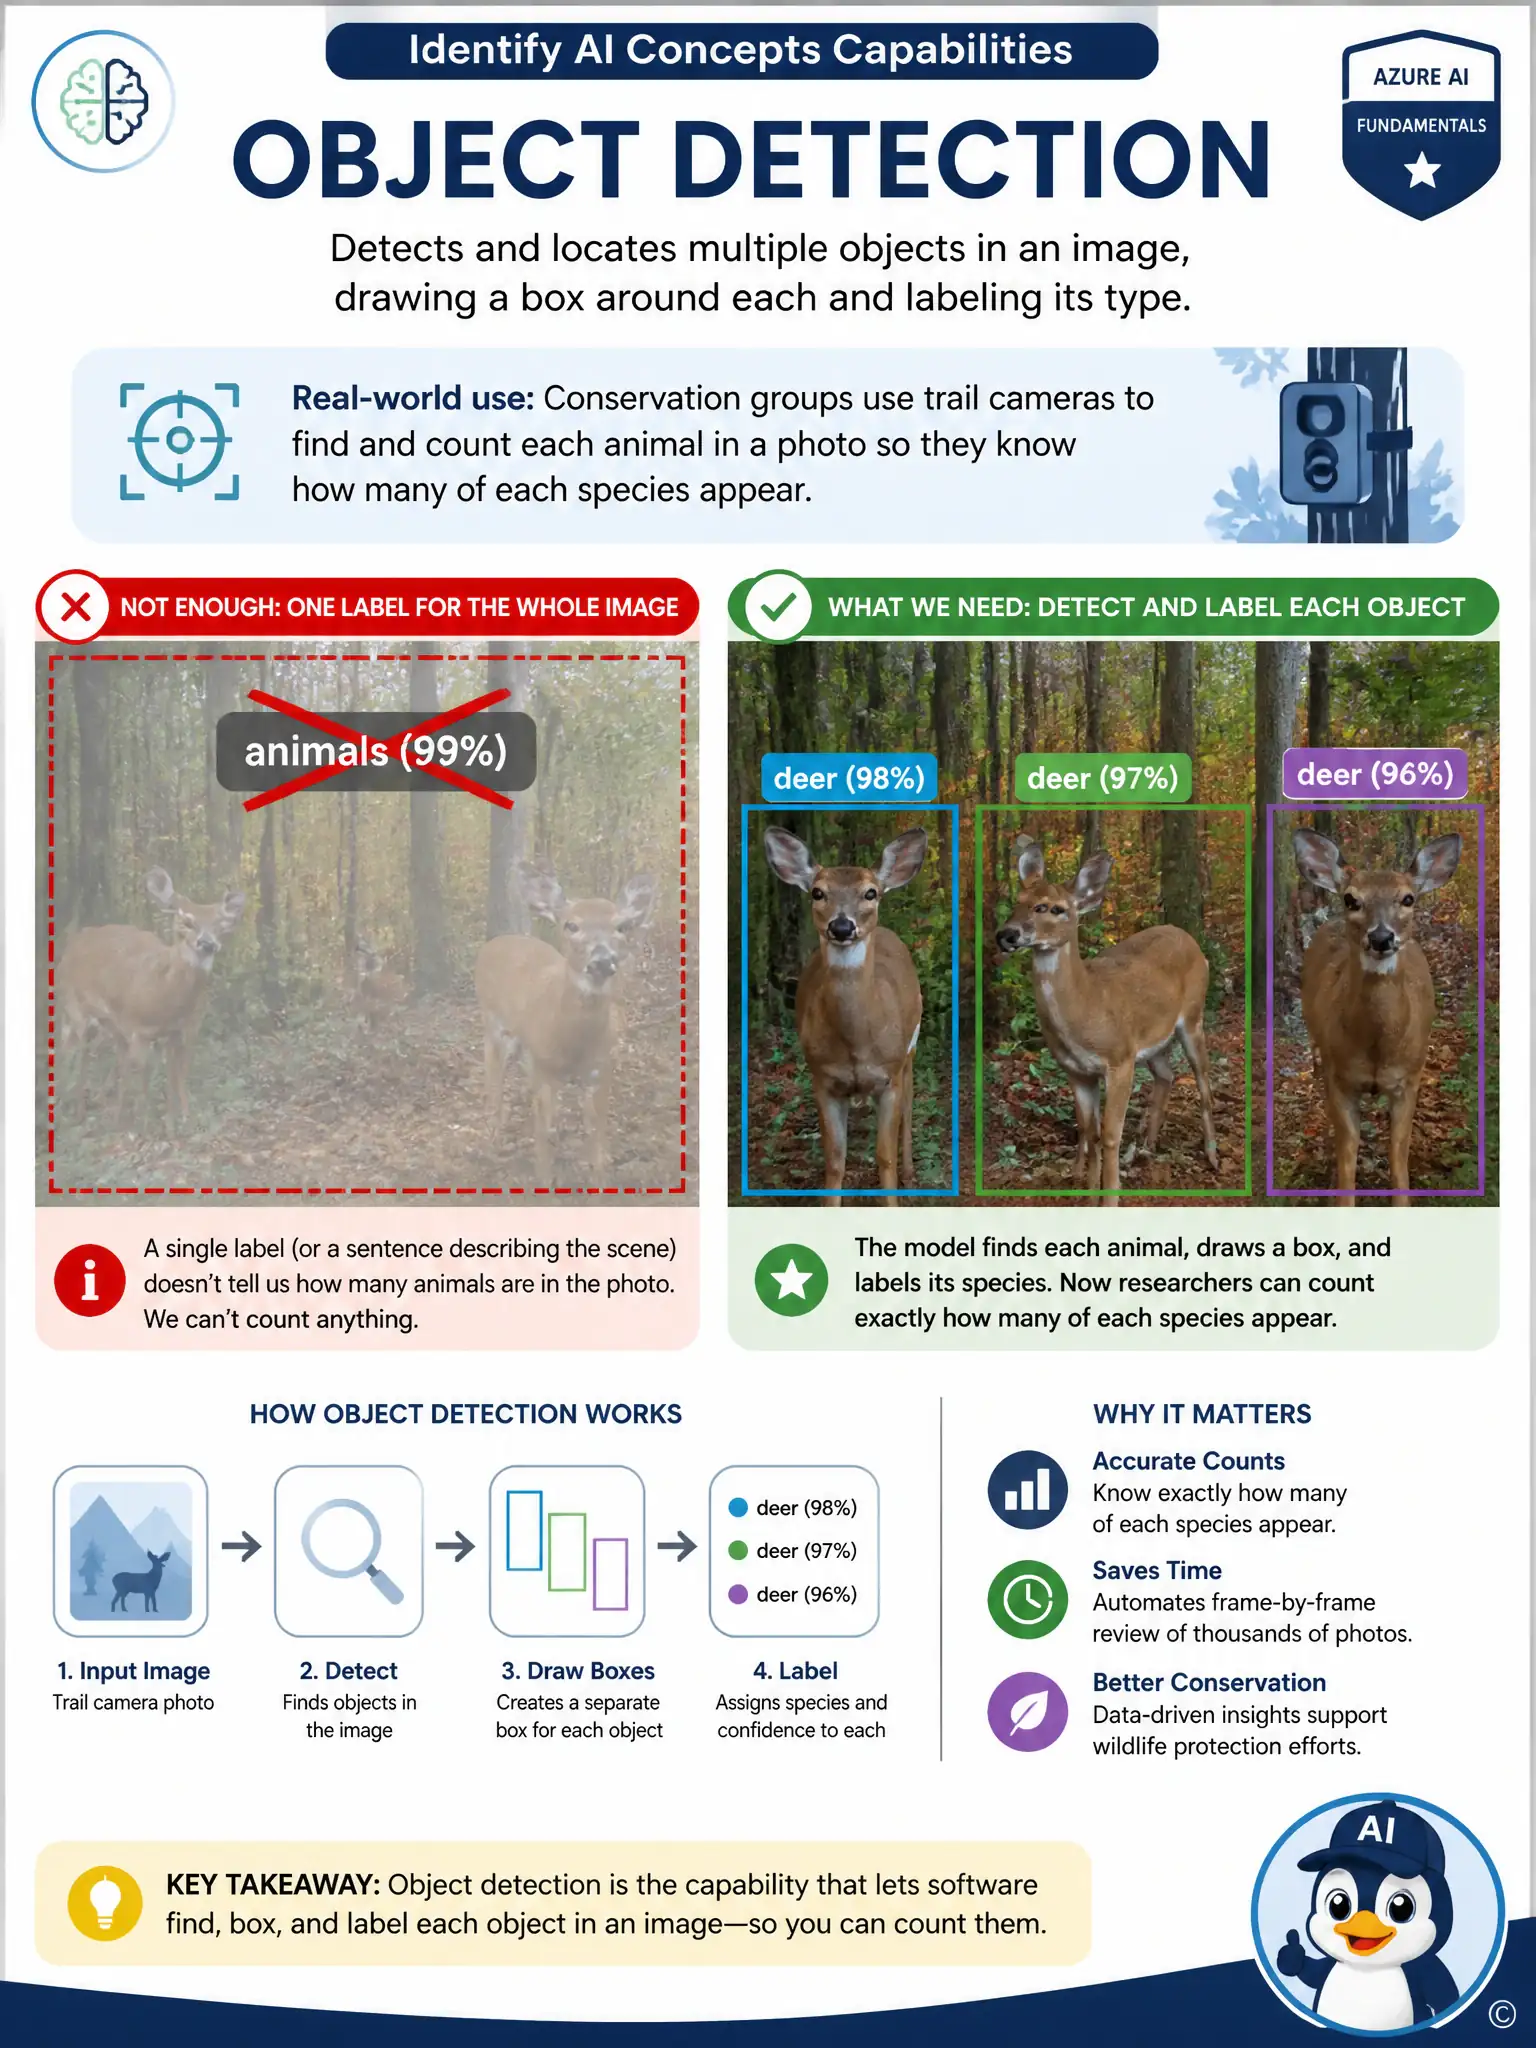
Picture a trail-cam photo with three deer bunched together. You need software that draws a separate box around each animal and labels its species, so you can count them one by one. That's object detection, not a single label or a caption.
Full Explanation
Object detection is correct because it locates each distinct object within an image, draws a bounding box around it, and assigns it a label, which is exactly what is needed to find and count multiple individual animals within a single trail-camera photo. Image captioning is incorrect because it generates one overall descriptive sentence summarizing a whole image, such as 'a group of deer near a stream,' rather than isolating and labeling each individual animal with its own box, so it cannot support per-animal counts. Image classification is incorrect because it assigns a single label to the entire photo, such as 'deer,' which breaks down as soon as a photo contains more than one animal or more than one species, and gives researchers no way to know how many individuals are present. Optical character recognition is incorrect because it reads printed or handwritten text within an image, such as a sign or timestamp, and has no role in locating or labeling animals in a wildlife photo. Because the group specifically needs a count of individuals per species per photo, only a capability that isolates each animal separately meets the requirement.