
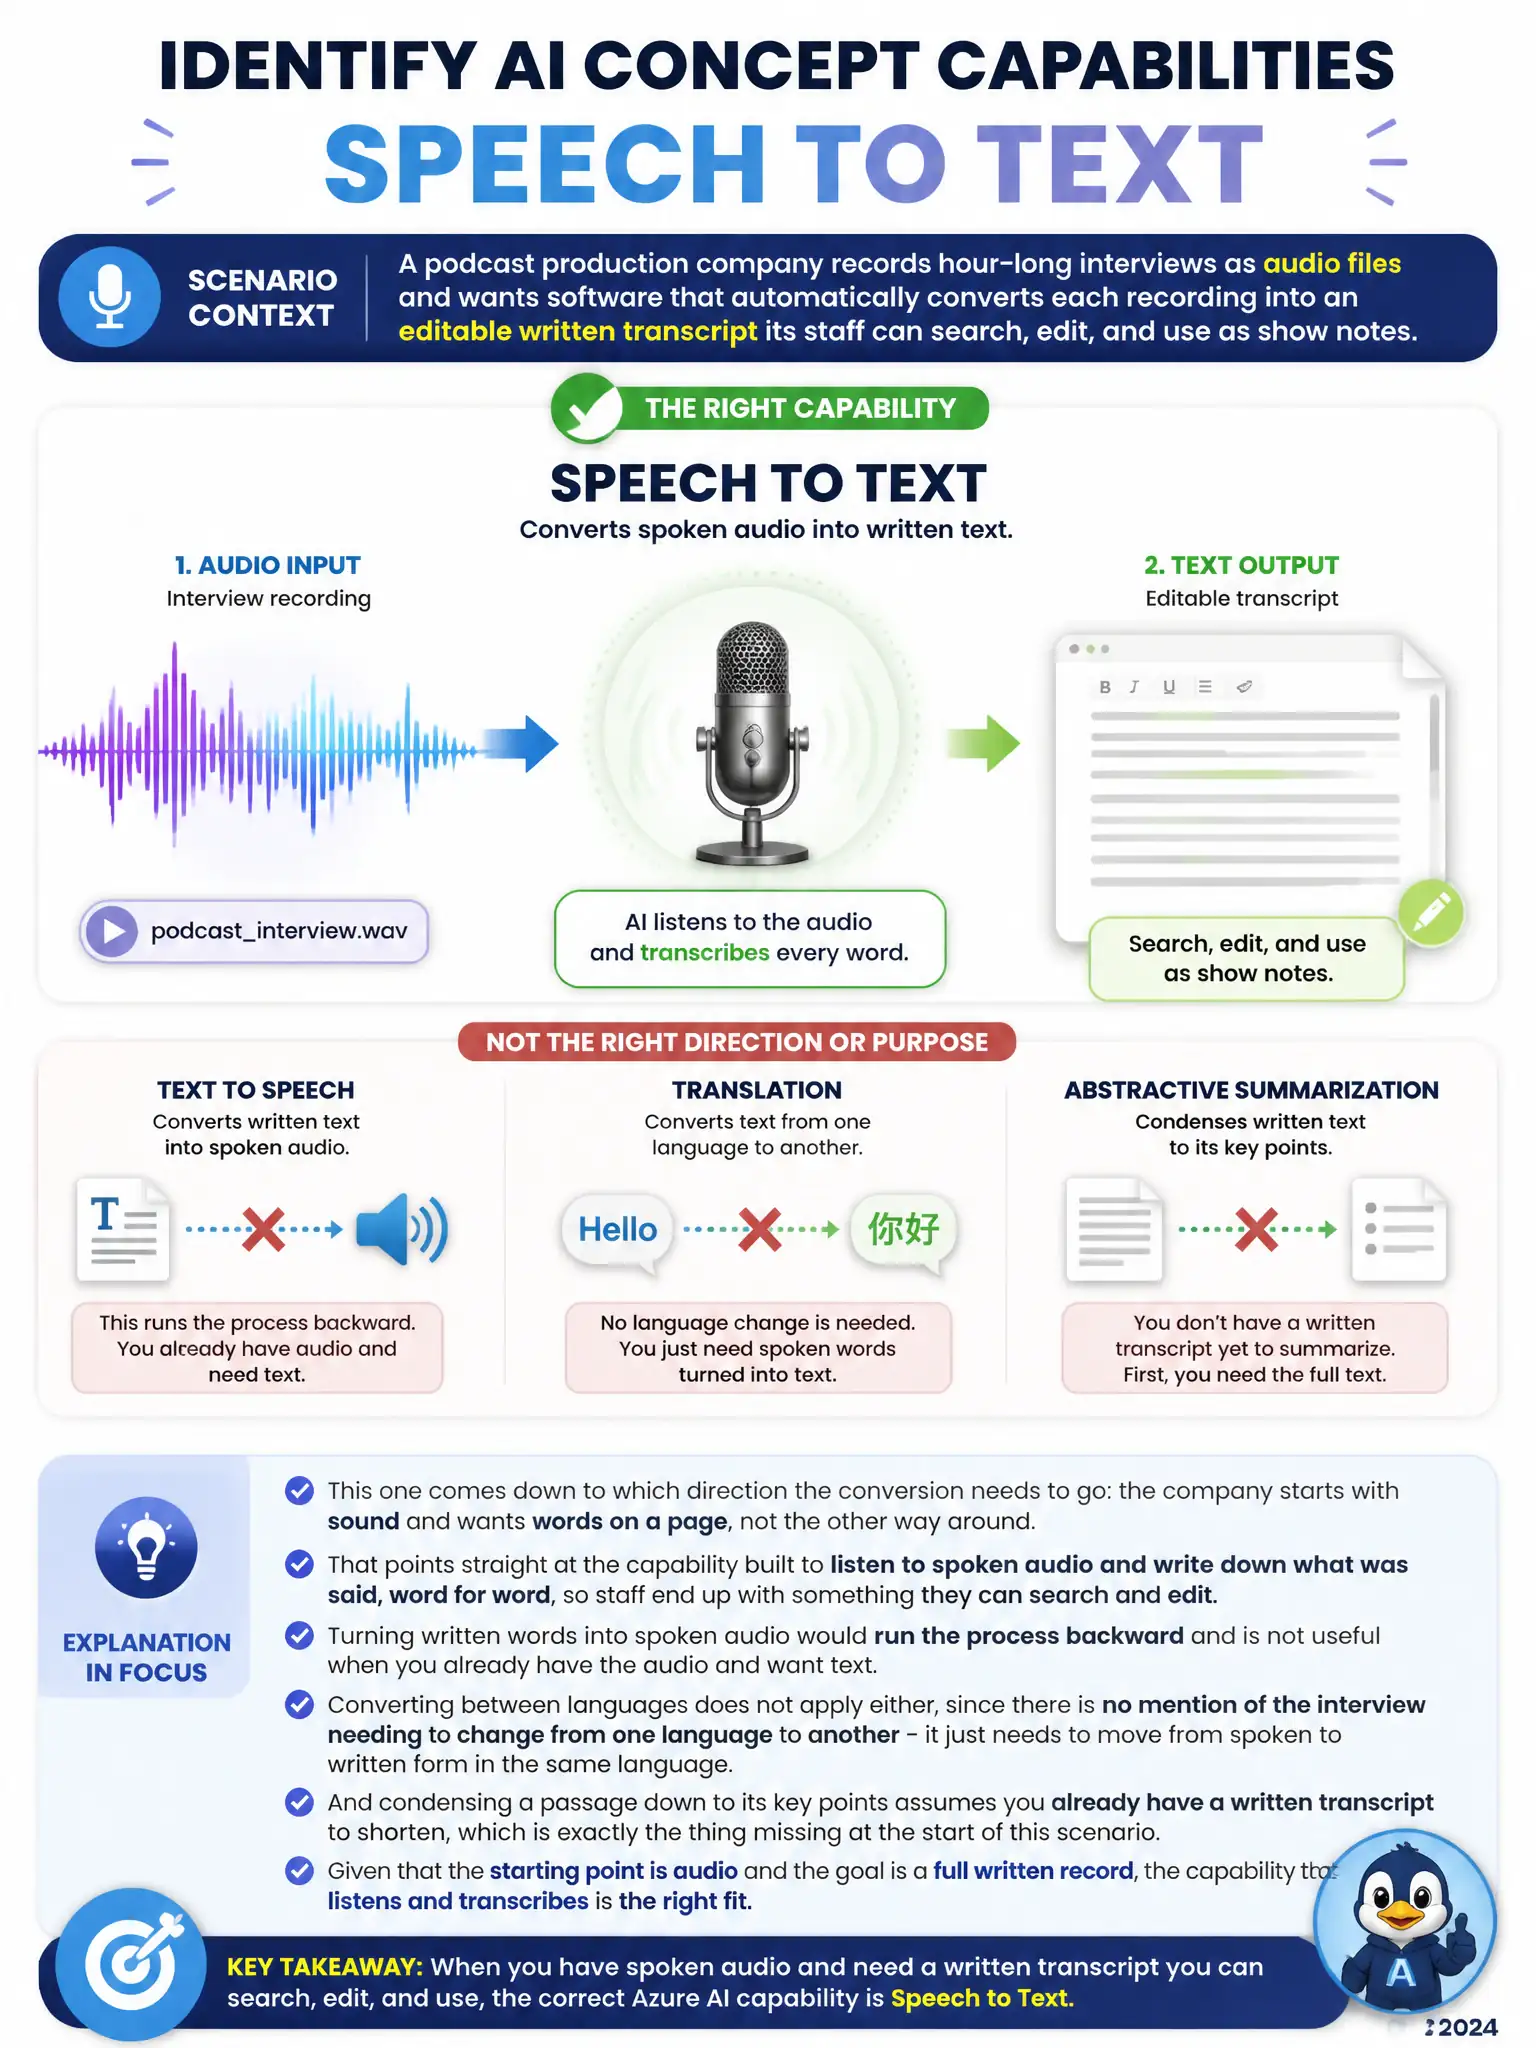
A podcast production company records hour-long interviews as audio files and wants software that automatically converts each recording into an editable written transcript its staff can search, edit, and use as show notes. Which Azure AI capability accomplishes this?
Select an answer to reveal the explanation.
Short Explanation
You need the capability that listens to spoken audio and writes it down word for word, because the company starts with recorded interviews and wants editable text. Text-to-speech goes backward, translation changes languages, and summarization needs an existing transcript.
Full Explanation
Speech to text is the Azure AI Speech capability that converts spoken audio into written text, which directly matches the production company's need to turn an hour-long recorded interview into an editable transcript that staff can search and revise. The text-to-speech capability is incorrect because it performs the opposite conversion, turning written text into synthesized spoken audio, which would not help a team that already has audio and wants text. The language translation capability is incorrect because it converts text or speech from one language into another, and nothing in the scenario indicates the interview needs to change languages, only that spoken words need to become written words in the same language. The text summarization capability is incorrect because it condenses an existing written passage into a shorter version highlighting key points, which assumes a transcript already exists and operates on text rather than producing the transcript from audio in the first place. Since the company's stated need is turning raw spoken audio into a full, editable written record rather than synthesizing audio, translating language, or condensing existing text, speech to text is the capability that fits the request.