
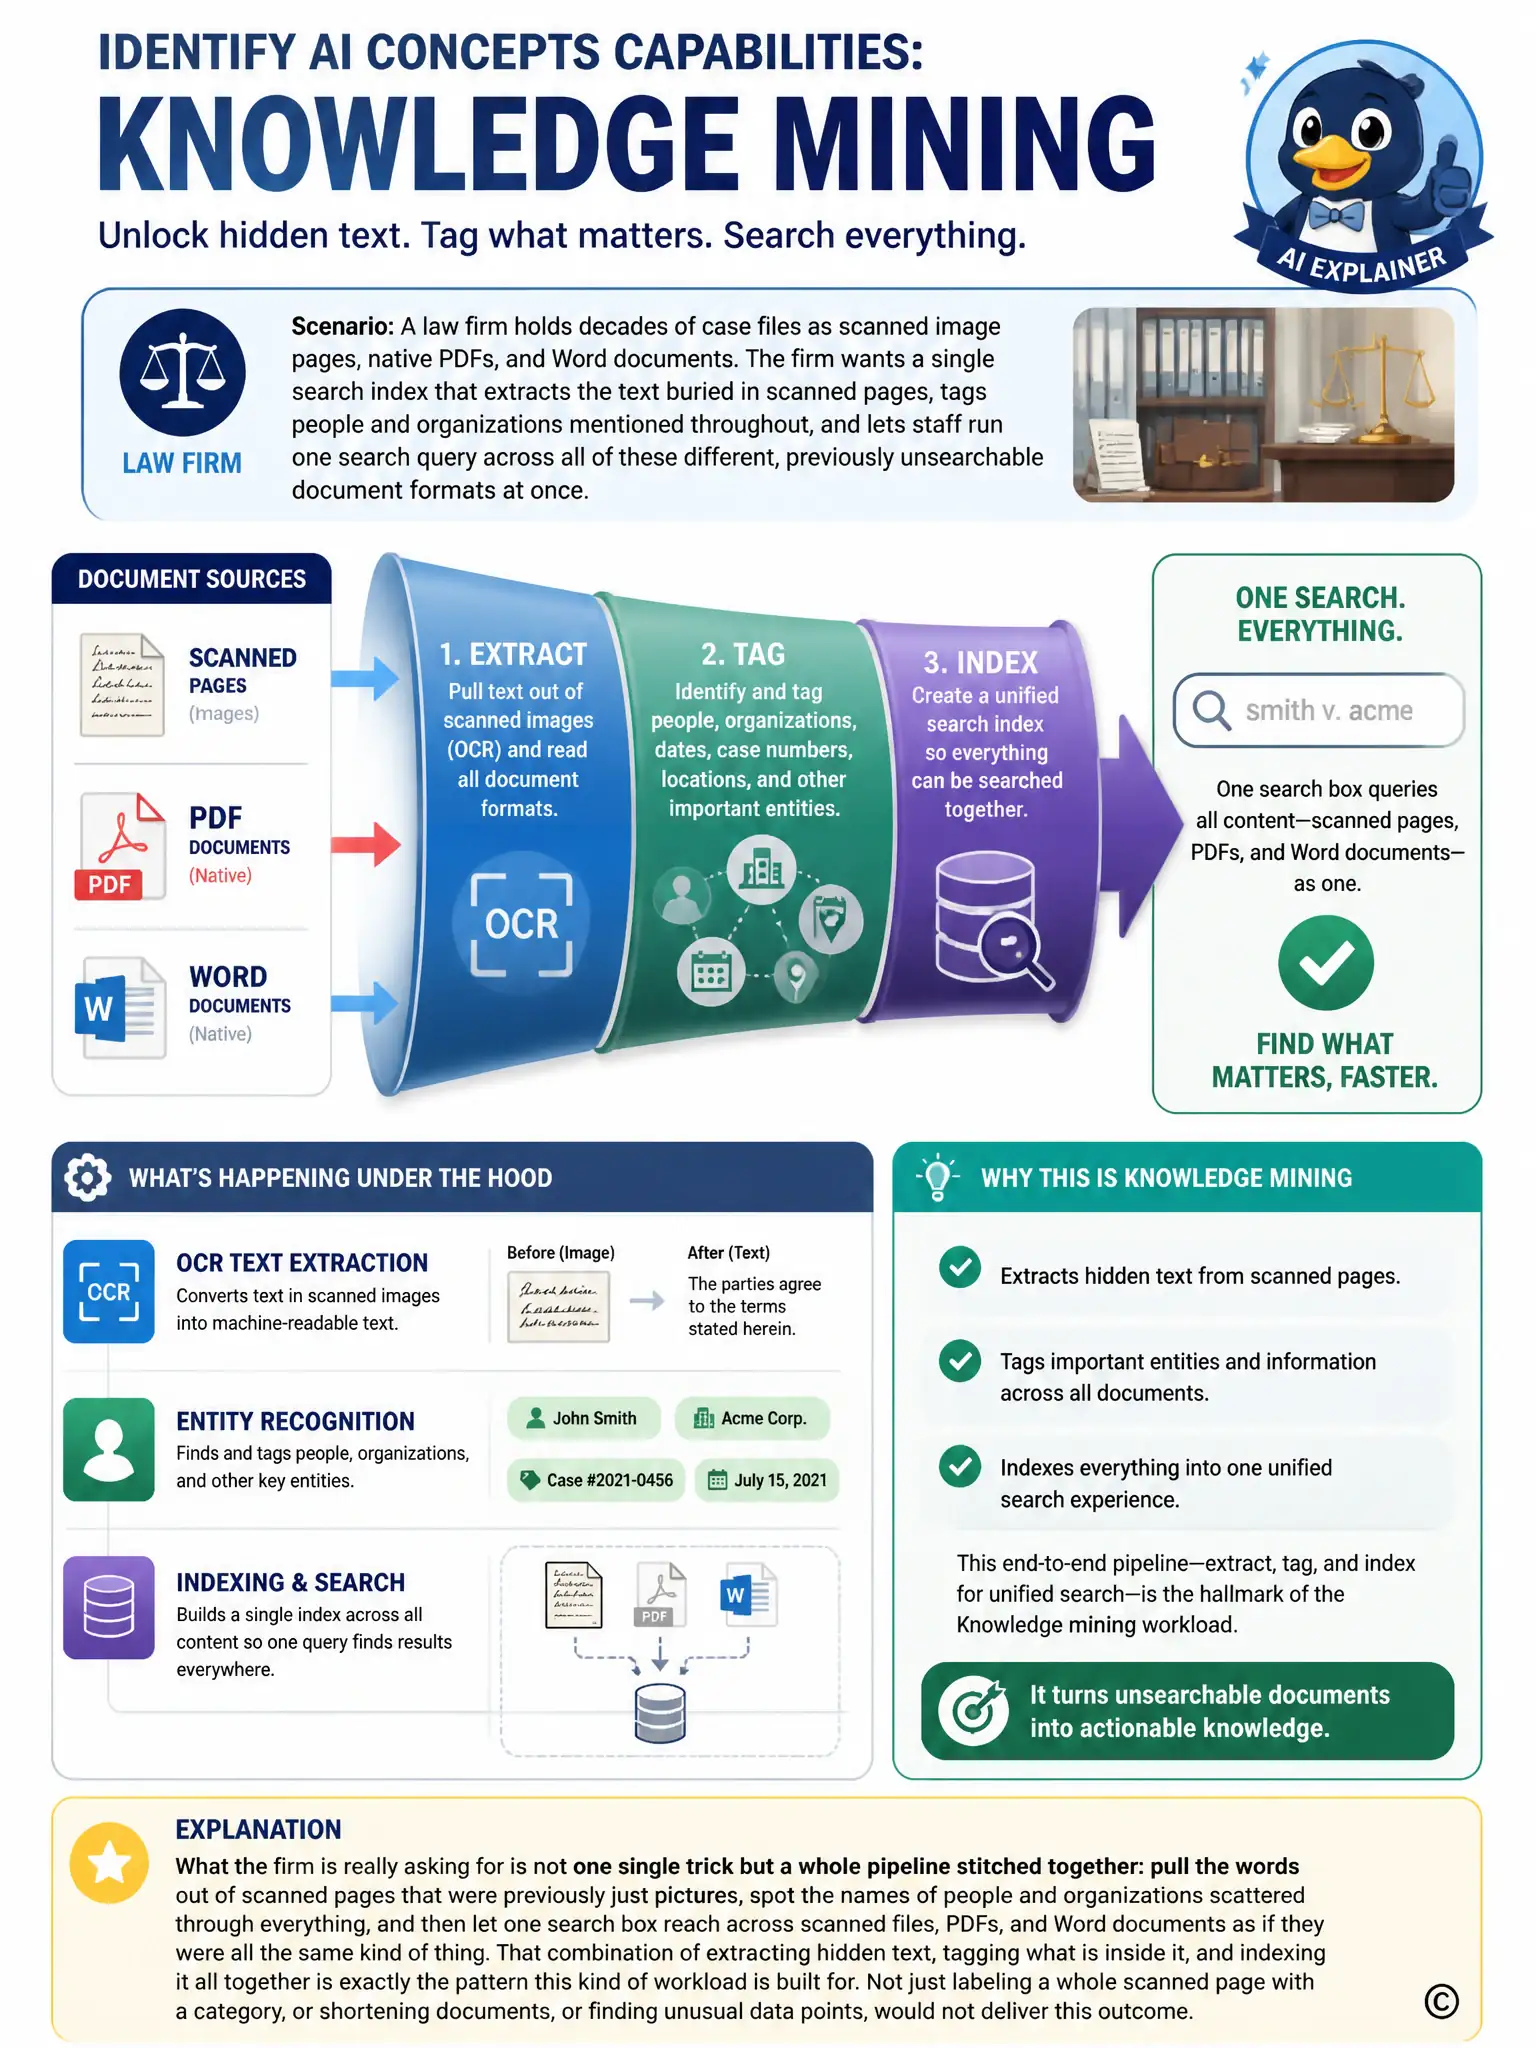
A law firm holds decades of case files as scanned image pages, native PDFs, and Word documents. The firm wants a single search index that extracts the text buried in scanned pages, tags people and organizations mentioned throughout, and lets staff run one search query across all of these different, previously unsearchable document formats at once. Which AI workload describes this combined solution?
Select an answer to reveal the explanation.
Short Explanation
What you need isn't one trick; it's a pipeline that pulls text out of scanned pages, tags people and organizations, and indexes everything so one search reaches PDFs, Word docs, and scanned files. Knowledge mining is built for that combined job. The other choices only label, summarize, or flag odd data, so they don't make the whole archive searchable.
Full Explanation
Knowledge mining is the AI workload that combines multiple capabilities, such as extracting text from scanned images, identifying entities like people and organizations, and indexing the results, into a single searchable index over large volumes of previously unsearchable content, which matches the firm's need to search across scanned pages, PDFs, and Word documents at once. Image classification is incorrect because it only assigns a category label to an entire image, such as identifying a scanned page as a contract or a letter, and does nothing to extract the text within it or build a cross-format search index. Text summarization is incorrect because it condenses existing text into a shorter version, which could be layered on top of already-extracted content but does not itself extract text from images or unify multiple document formats into one searchable index. Anomaly detection is incorrect because it identifies unusual data points that deviate from a learned normal pattern, which has no connection to making decades of scanned and typed legal documents searchable. Because the firm's goal is combining text extraction, entity tagging, and unified search across mixed document formats, that composite capability is precisely what knowledge mining describes.