
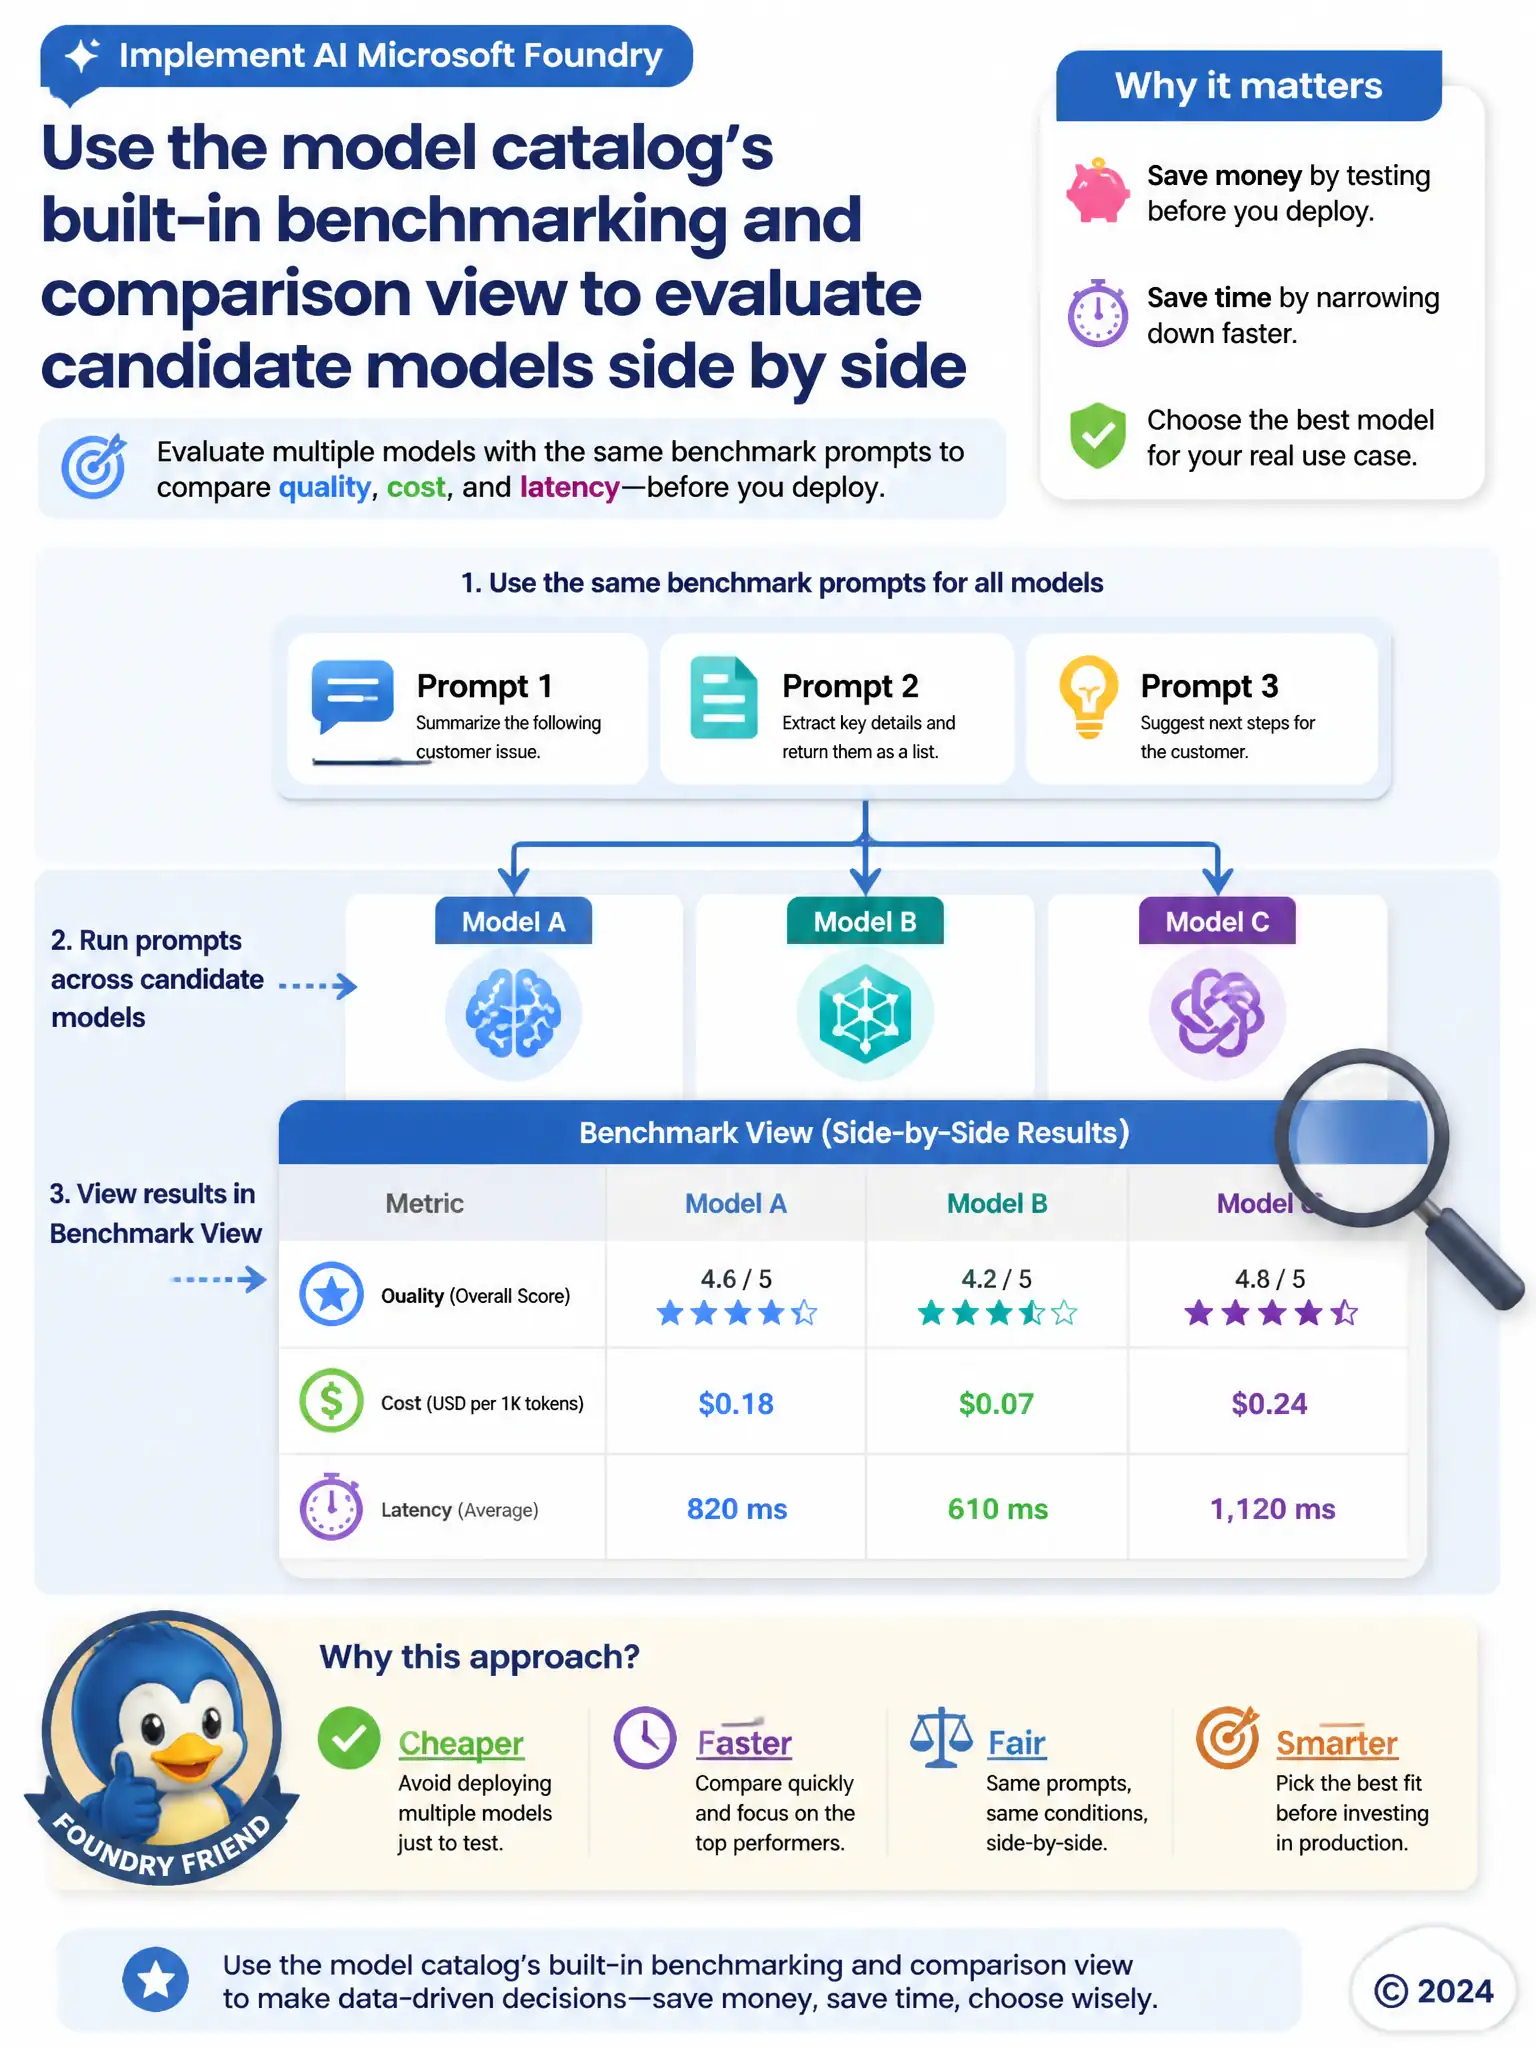
A machine learning team is choosing among several candidate language models in the Azure AI Foundry model catalog for a new customer-facing assistant. Before committing to one, they want to compare quality, cost, and latency metrics for multiple models side by side using the same benchmark prompts, without deploying every candidate to production first.
Select an answer to reveal the explanation.
Short Explanation
Before you spend money deploying five different models to see which one performs best, use the model catalog's built-in benchmarking and comparison view. It lets you run the same test prompts across candidates and see quality, cost, and speed side by side. Skipping straight to full production deployment for every option burns time and money on models that might get eliminated early.
Full Explanation
The correct answer is the model catalog's built-in benchmarking and comparison view to evaluate candidate models side by side. Azure AI Foundry's model catalog includes a benchmarking and comparison view that lets a team run the same prompts against multiple candidate models and compare quality, cost, and latency metrics before committing to a deployment, which is exactly what this team needs while still evaluating options. The approach of deploying every candidate model to production and monitoring live customer feedback for a month is incorrect because it is expensive, risky for real customers, and far slower than using the catalog's built-in comparison tools to narrow the field early. The approach of reading each model provider's marketing page to estimate which model is likely to perform best is incorrect because marketing pages reflect vendor claims rather than measured performance on the team's own benchmark prompts, and they are not a substitute for a controlled comparison. The approach of fine-tuning each candidate model on the same dataset and comparing only the fine-tuning cost is incorrect because fine-tuning cost is only one factor among several, and jumping straight to fine-tuning every candidate skips the earlier, cheaper step of comparing base model behavior first; it also conflates model selection with a separate customization decision that should come later, once a base model has already been chosen.