
A support team notices that a Foundry-hosted chatbot occasionally takes far longer than usual to respond, but the issue happens unpredictably and is hard to reproduce on demand. To investigate, an engineer connects the deployment's monitoring integration and reviews traces showing the timing of each internal step, retrieval, model inference and post-processing, for individual past requests. What is the main benefit of reviewing these per-request traces rather than only looking at an aggregate average response time metric?
Select an answer to reveal the explanation.
Short Explanation
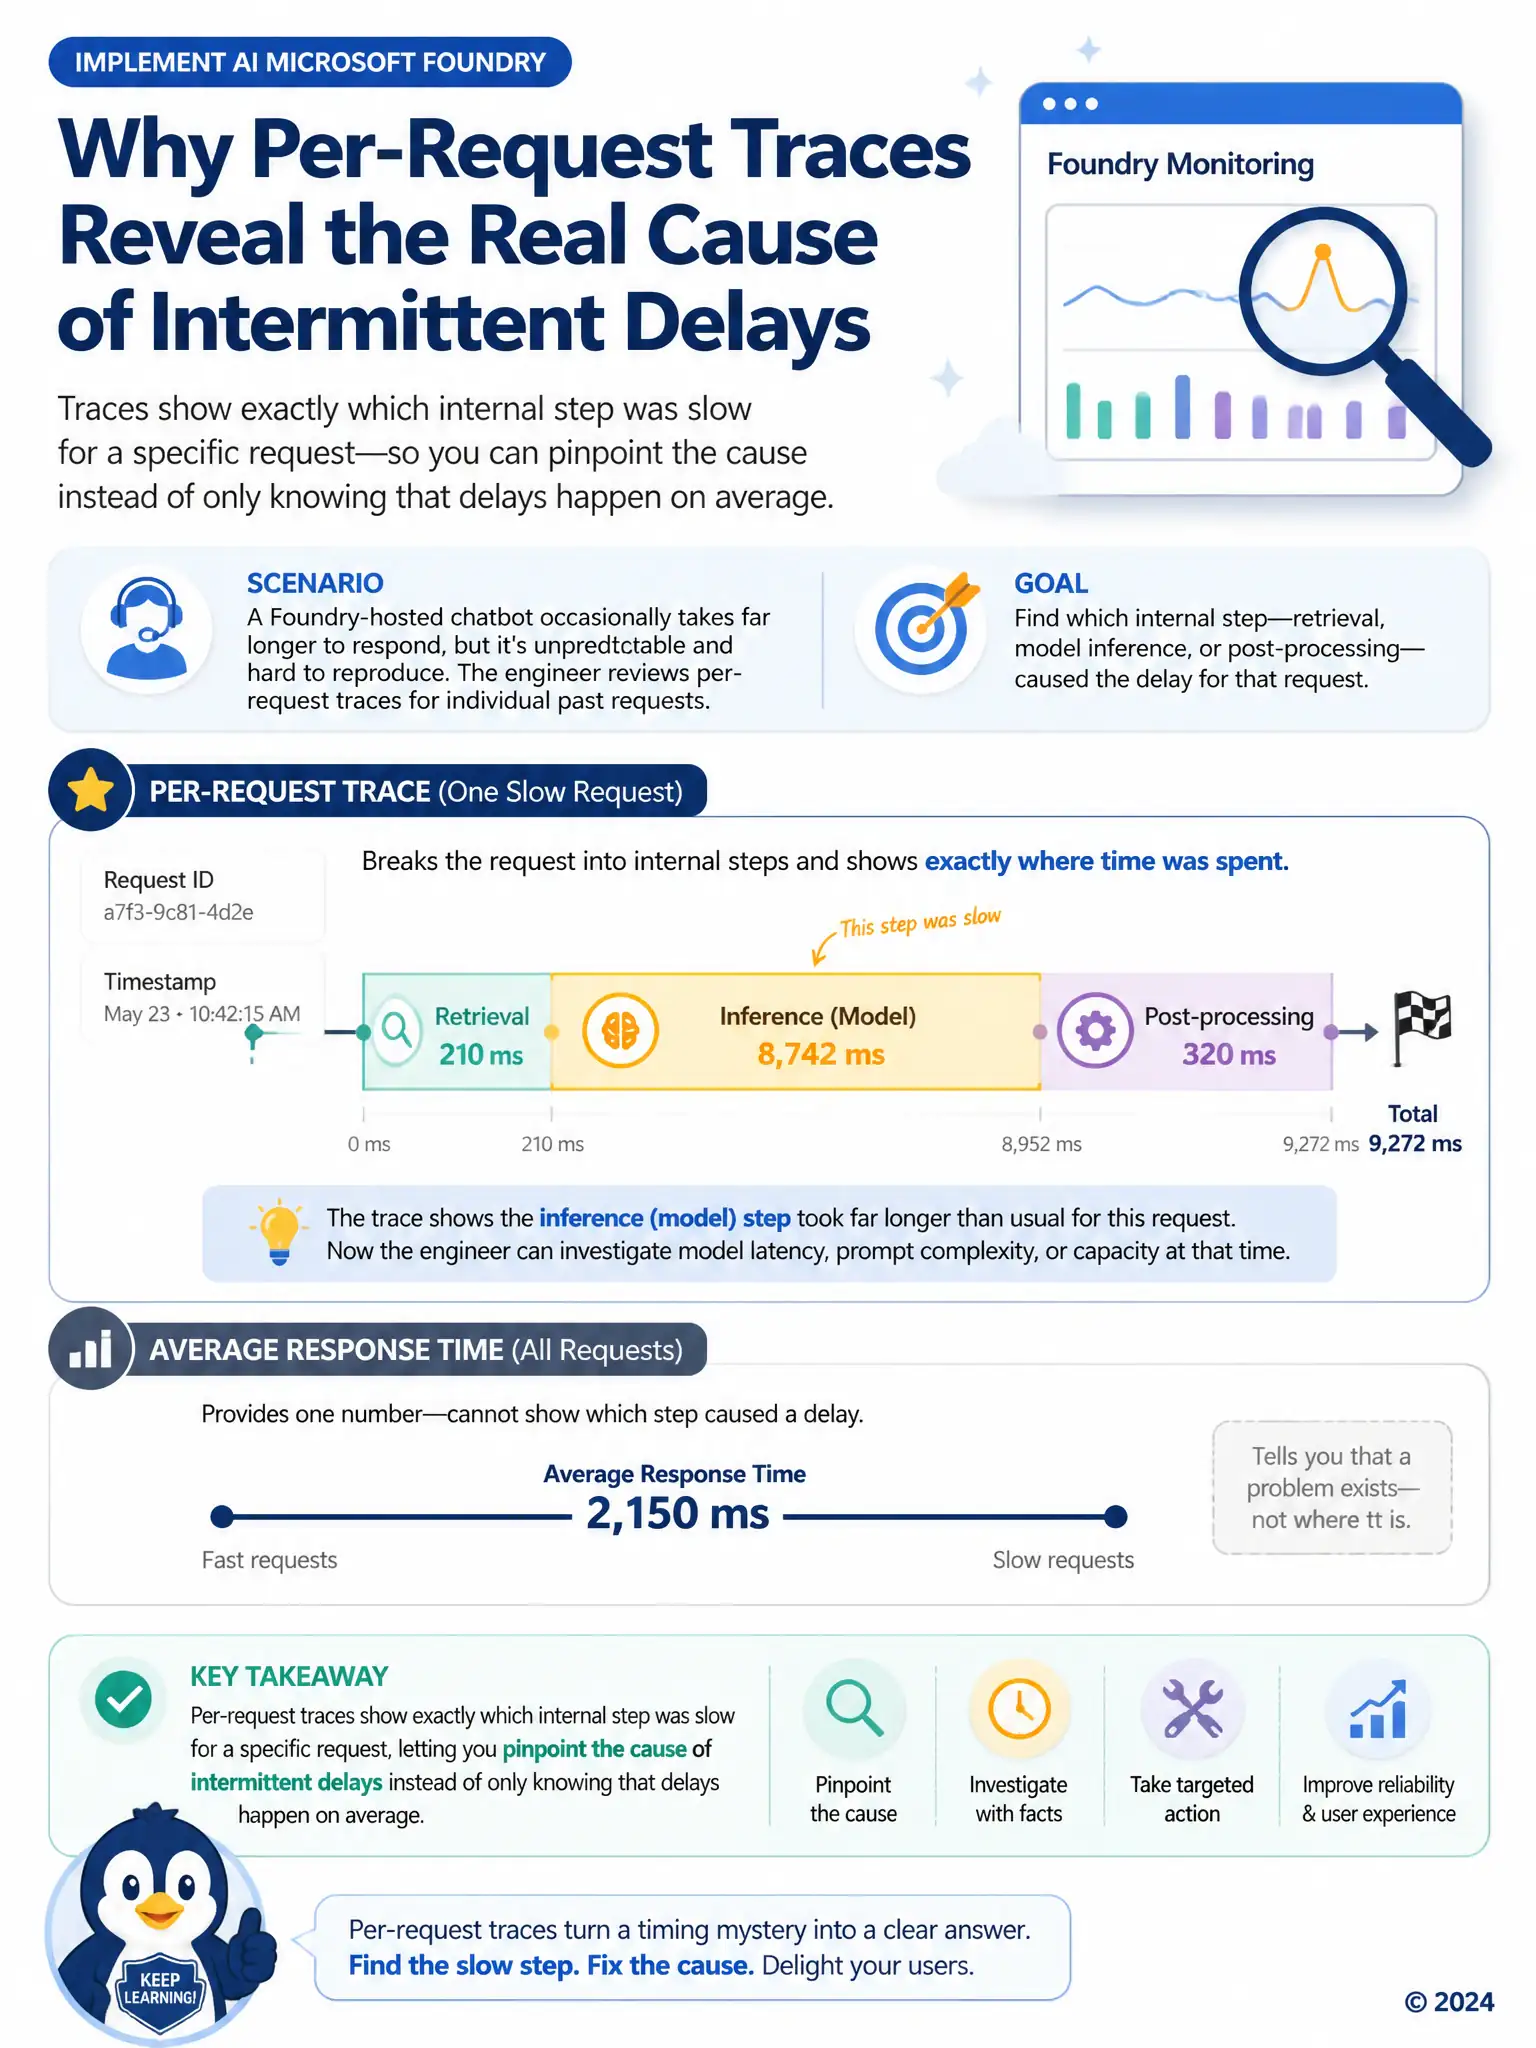
An overall average can tell you delays exist, but it won't tell you where. Per-request traces break a slow request into retrieval, inference, and post-processing, so you can see which step stalled that one request. That's how you chase intermittent problems that won't reproduce on demand.
Full Explanation
Per-request traces are valuable because an aggregate average response time only shows that delays are happening somewhere across many requests; it hides where the slowdown occurs. The traces break a single request into its internal steps, retrieval, model inference, and post-processing, so you can see, for example, that retrieval time spiked for a particular slow request while inference stayed normal. That step-level detail is exactly what you need to investigate an intermittent, hard-to-reproduce issue. The claim that traces automatically resolve slow requests by retrying them with a faster model is wrong because traces are a diagnostic and observability tool; they display what happened during a request but do not take corrective action on their own. The claim that traces replace content safety filtering is also wrong because tracing and content safety filtering are separate systems; traces record timing and execution details, while filtering evaluates whether content should be blocked. The claim that traces are the only way to see total tokens used for billing is wrong because usage and billing data may be tracked elsewhere in monitoring, and traces are not the exclusive or primary source for total token counts. In this scenario, the engineer is reviewing traces to diagnose latency, not to count tokens.