
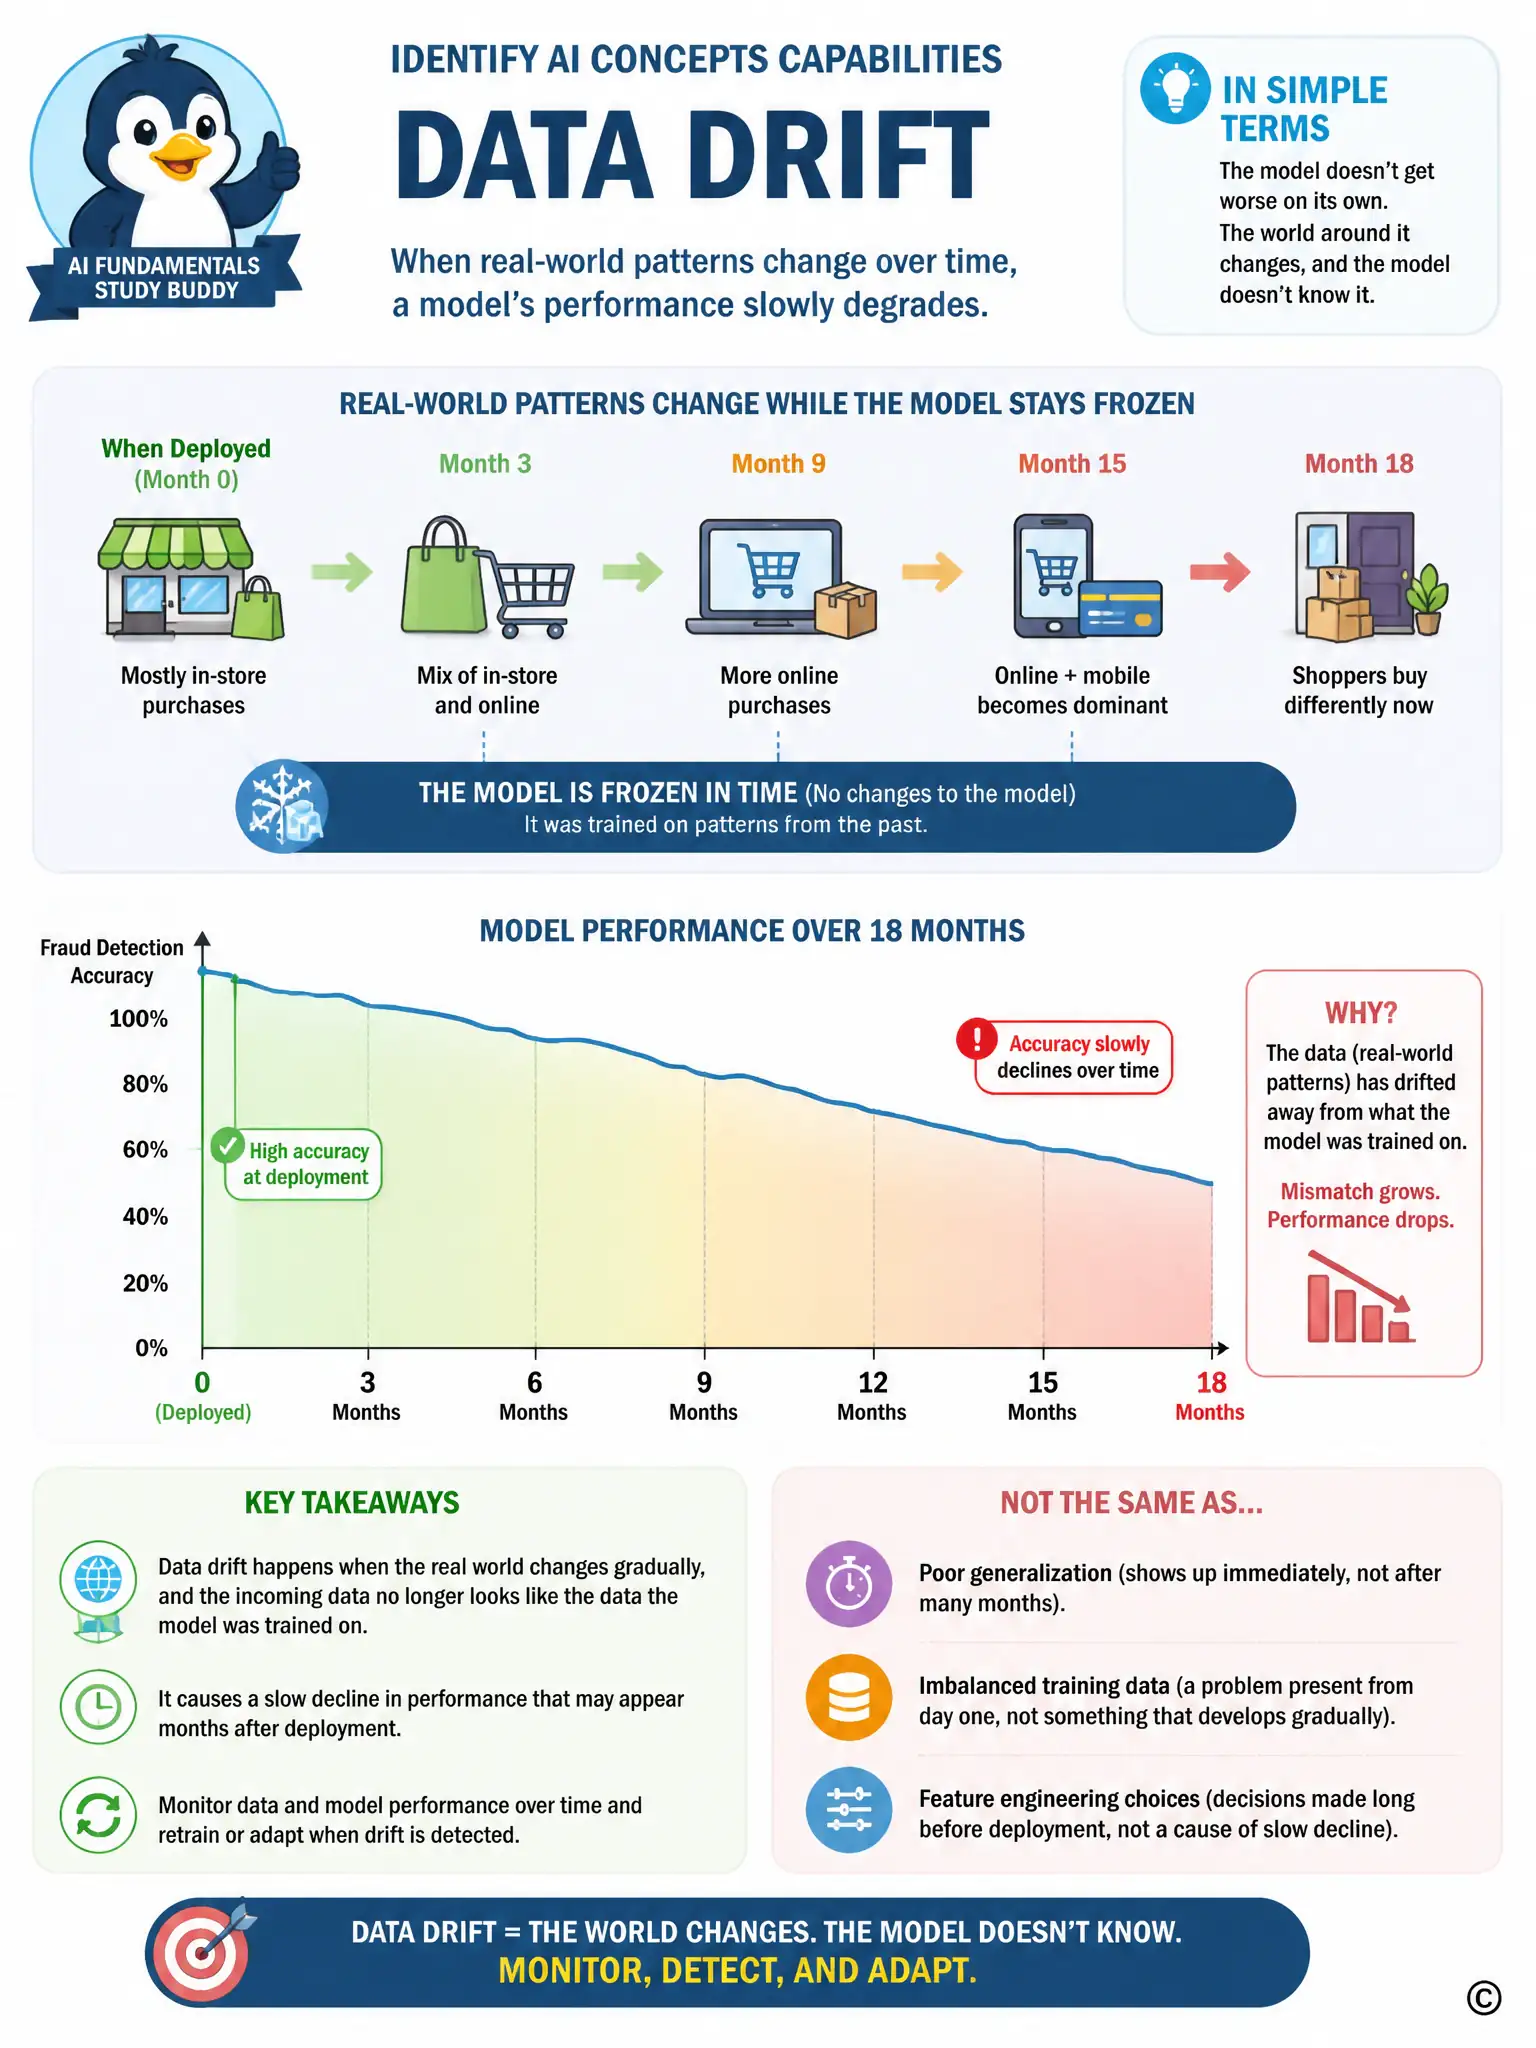
A payments company's fraud-detection model performed well when first deployed. Eighteen months later, without any change to the model itself, it starts missing fraud patterns because customers have gradually changed how and where they shop. Which concept describes why a previously accurate model degrades over time as real-world patterns change?
Select an answer to reveal the explanation.
Short Explanation
You don't need to blame the model itself; the world around it changes and the model doesn't know it. It was trained on shopping patterns from a certain point in time, and if customers gradually start buying different things in different ways, the patterns the model learned start to look less and less like reality. That mismatch between what the model was trained on and what it's now seeing in production is exactly data drift.
Full Explanation
Data drift is correct because it describes the phenomenon where the statistical properties of real-world data change over time relative to what the model was originally trained on, causing a previously accurate model to gradually perform worse even though the model itself has not changed, which matches the gradual shopping-pattern shift described here. Overfitting is incorrect because it describes a model that fit the training data too closely from the start, which would show up as poor generalization immediately after deployment rather than as a gradual decline eighteen months into otherwise stable performance. Class imbalance is incorrect because it refers to a disproportionate number of examples per category within the training data itself, a property of the original dataset, and it does not explain why an already-trained model's accuracy would decline after a long period of good performance. Feature engineering is incorrect because it refers to the process of selecting and transforming input variables during model building, not a phenomenon that explains performance changes after a model has already been deployed and left unchanged.