
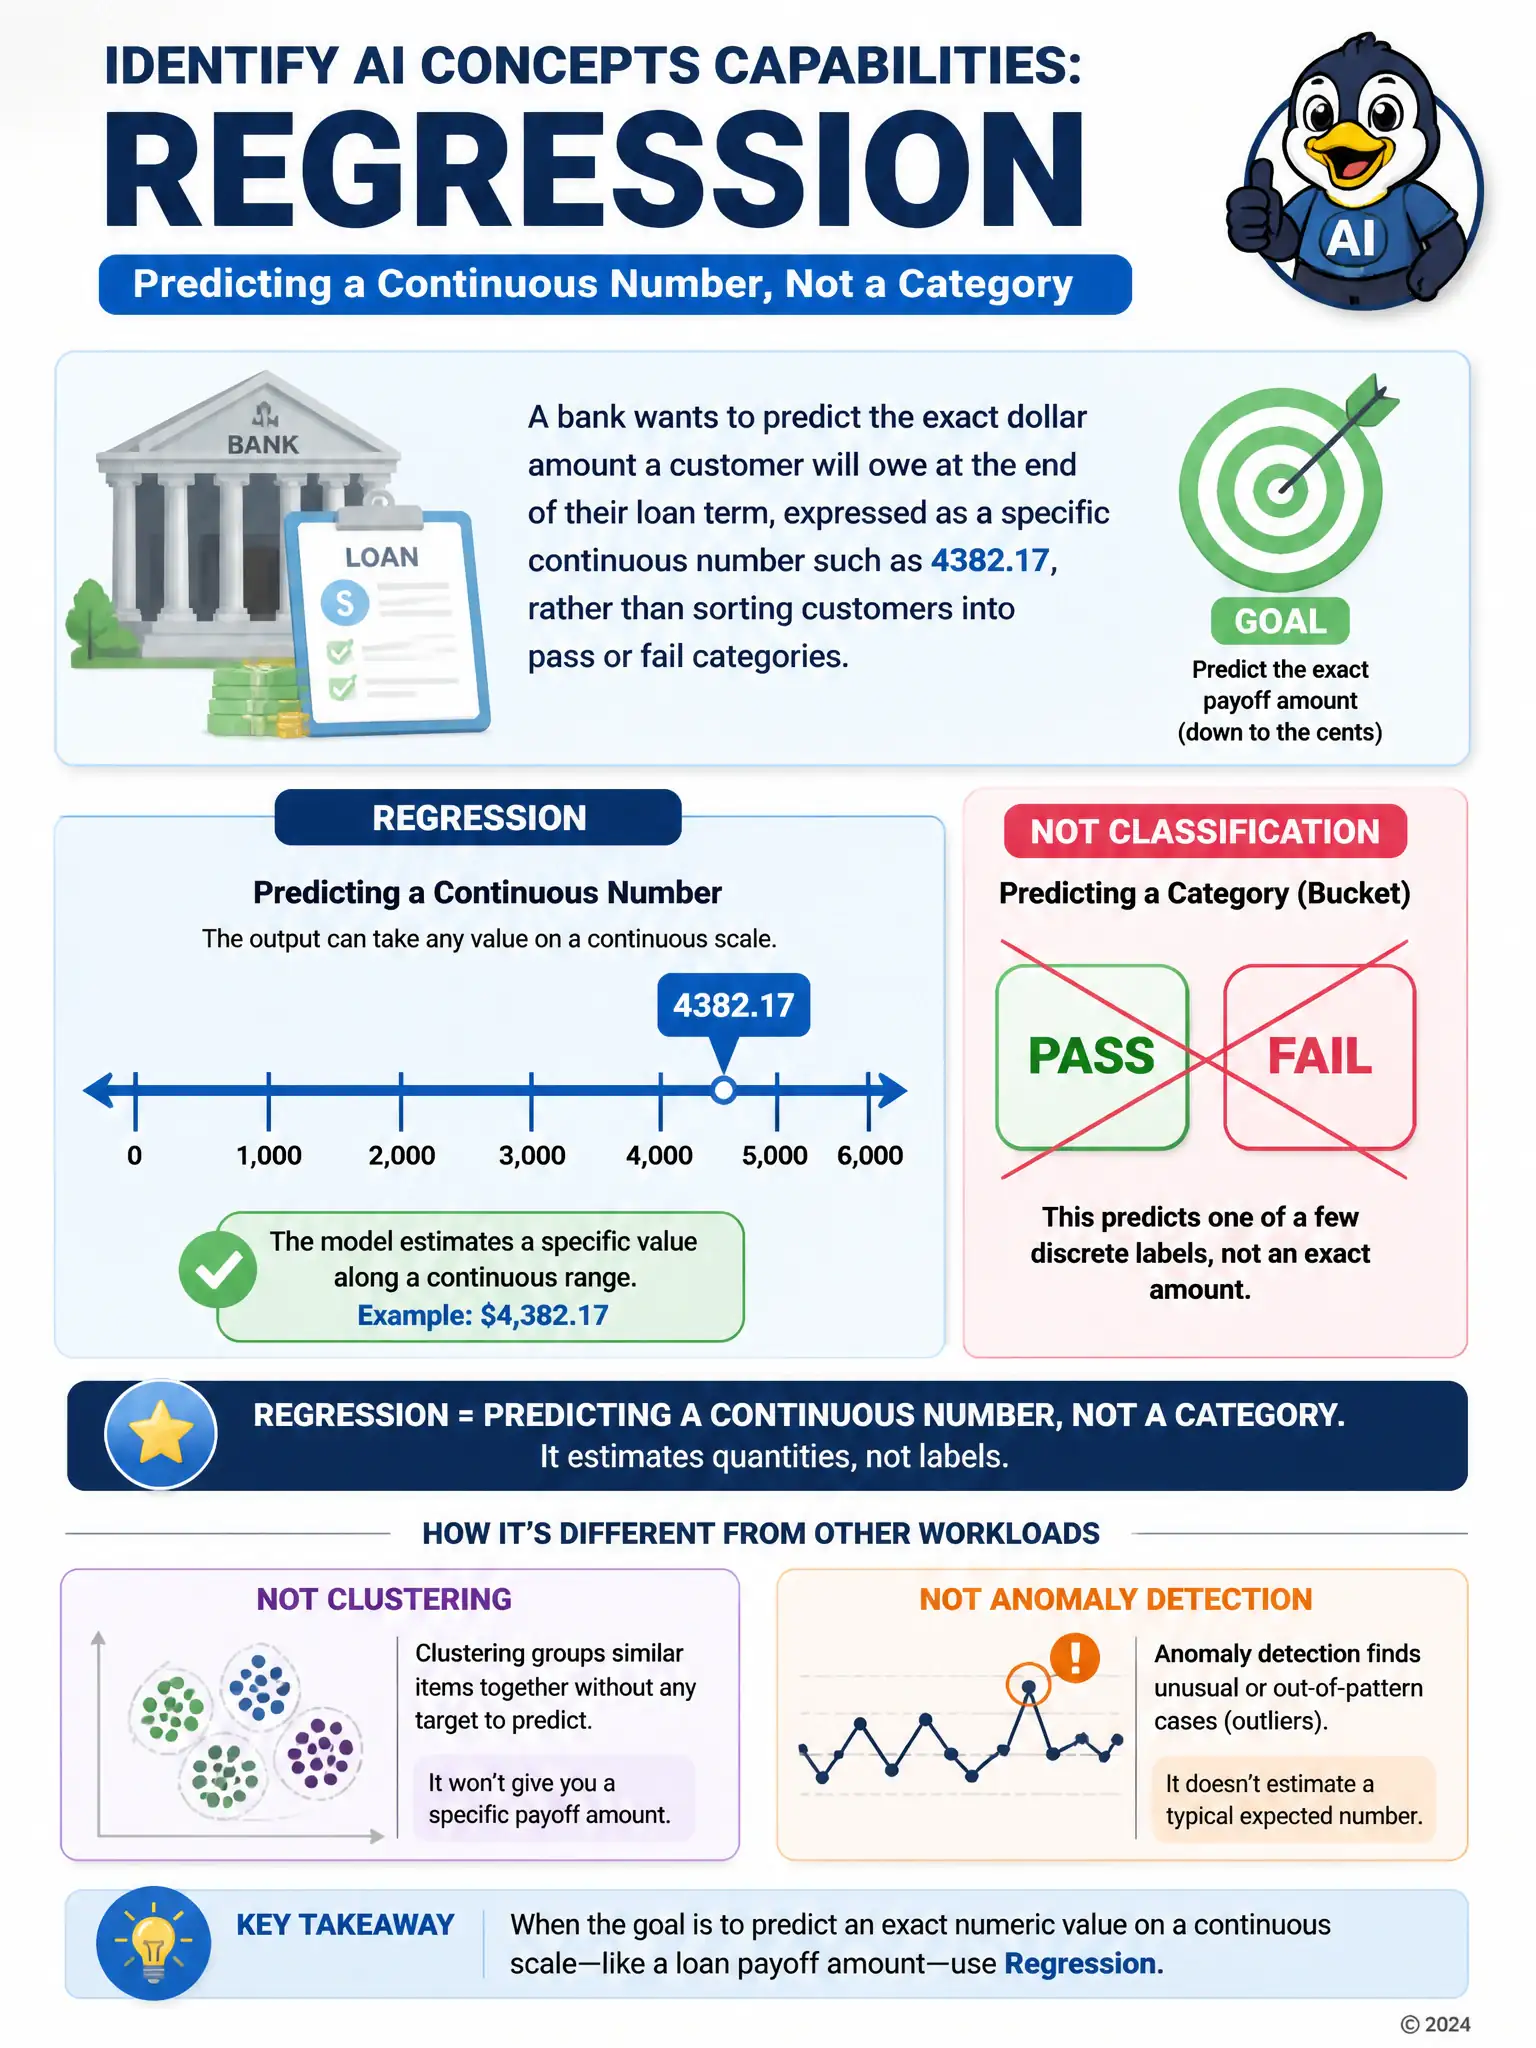
A bank wants to predict the exact dollar amount a customer will owe at the end of their loan term, expressed as a specific continuous number such as 4382.17, rather than sorting customers into pass or fail categories. Which AI workload type fits this goal?
Select an answer to reveal the explanation.
Short Explanation
The giveaway is that the bank wants an exact dollar amount, not a bucket. You're predicting a value on a continuous scale, so Regression is the right workload. Classification sorts into categories, Clustering groups without a target, and Anomaly detection flags outliers.
Full Explanation
Regression is the workload type used to predict a continuous numeric value, such as a specific dollar amount, which matches the bank's goal of estimating an exact figure rather than sorting customers into discrete groups. Classification is incorrect because it assigns records to a discrete category or label, such as pass or fail, and it is not designed to produce a specific continuous number like a precise dollar amount. Clustering is incorrect because it is an unsupervised technique that groups similar records together based on shared characteristics without any target value to predict at all, so it could not produce a specific predicted payoff amount for a customer. Anomaly detection is incorrect because it is designed to flag unusual or outlier data points, not to estimate a typical continuous outcome such as an expected payoff amount.