
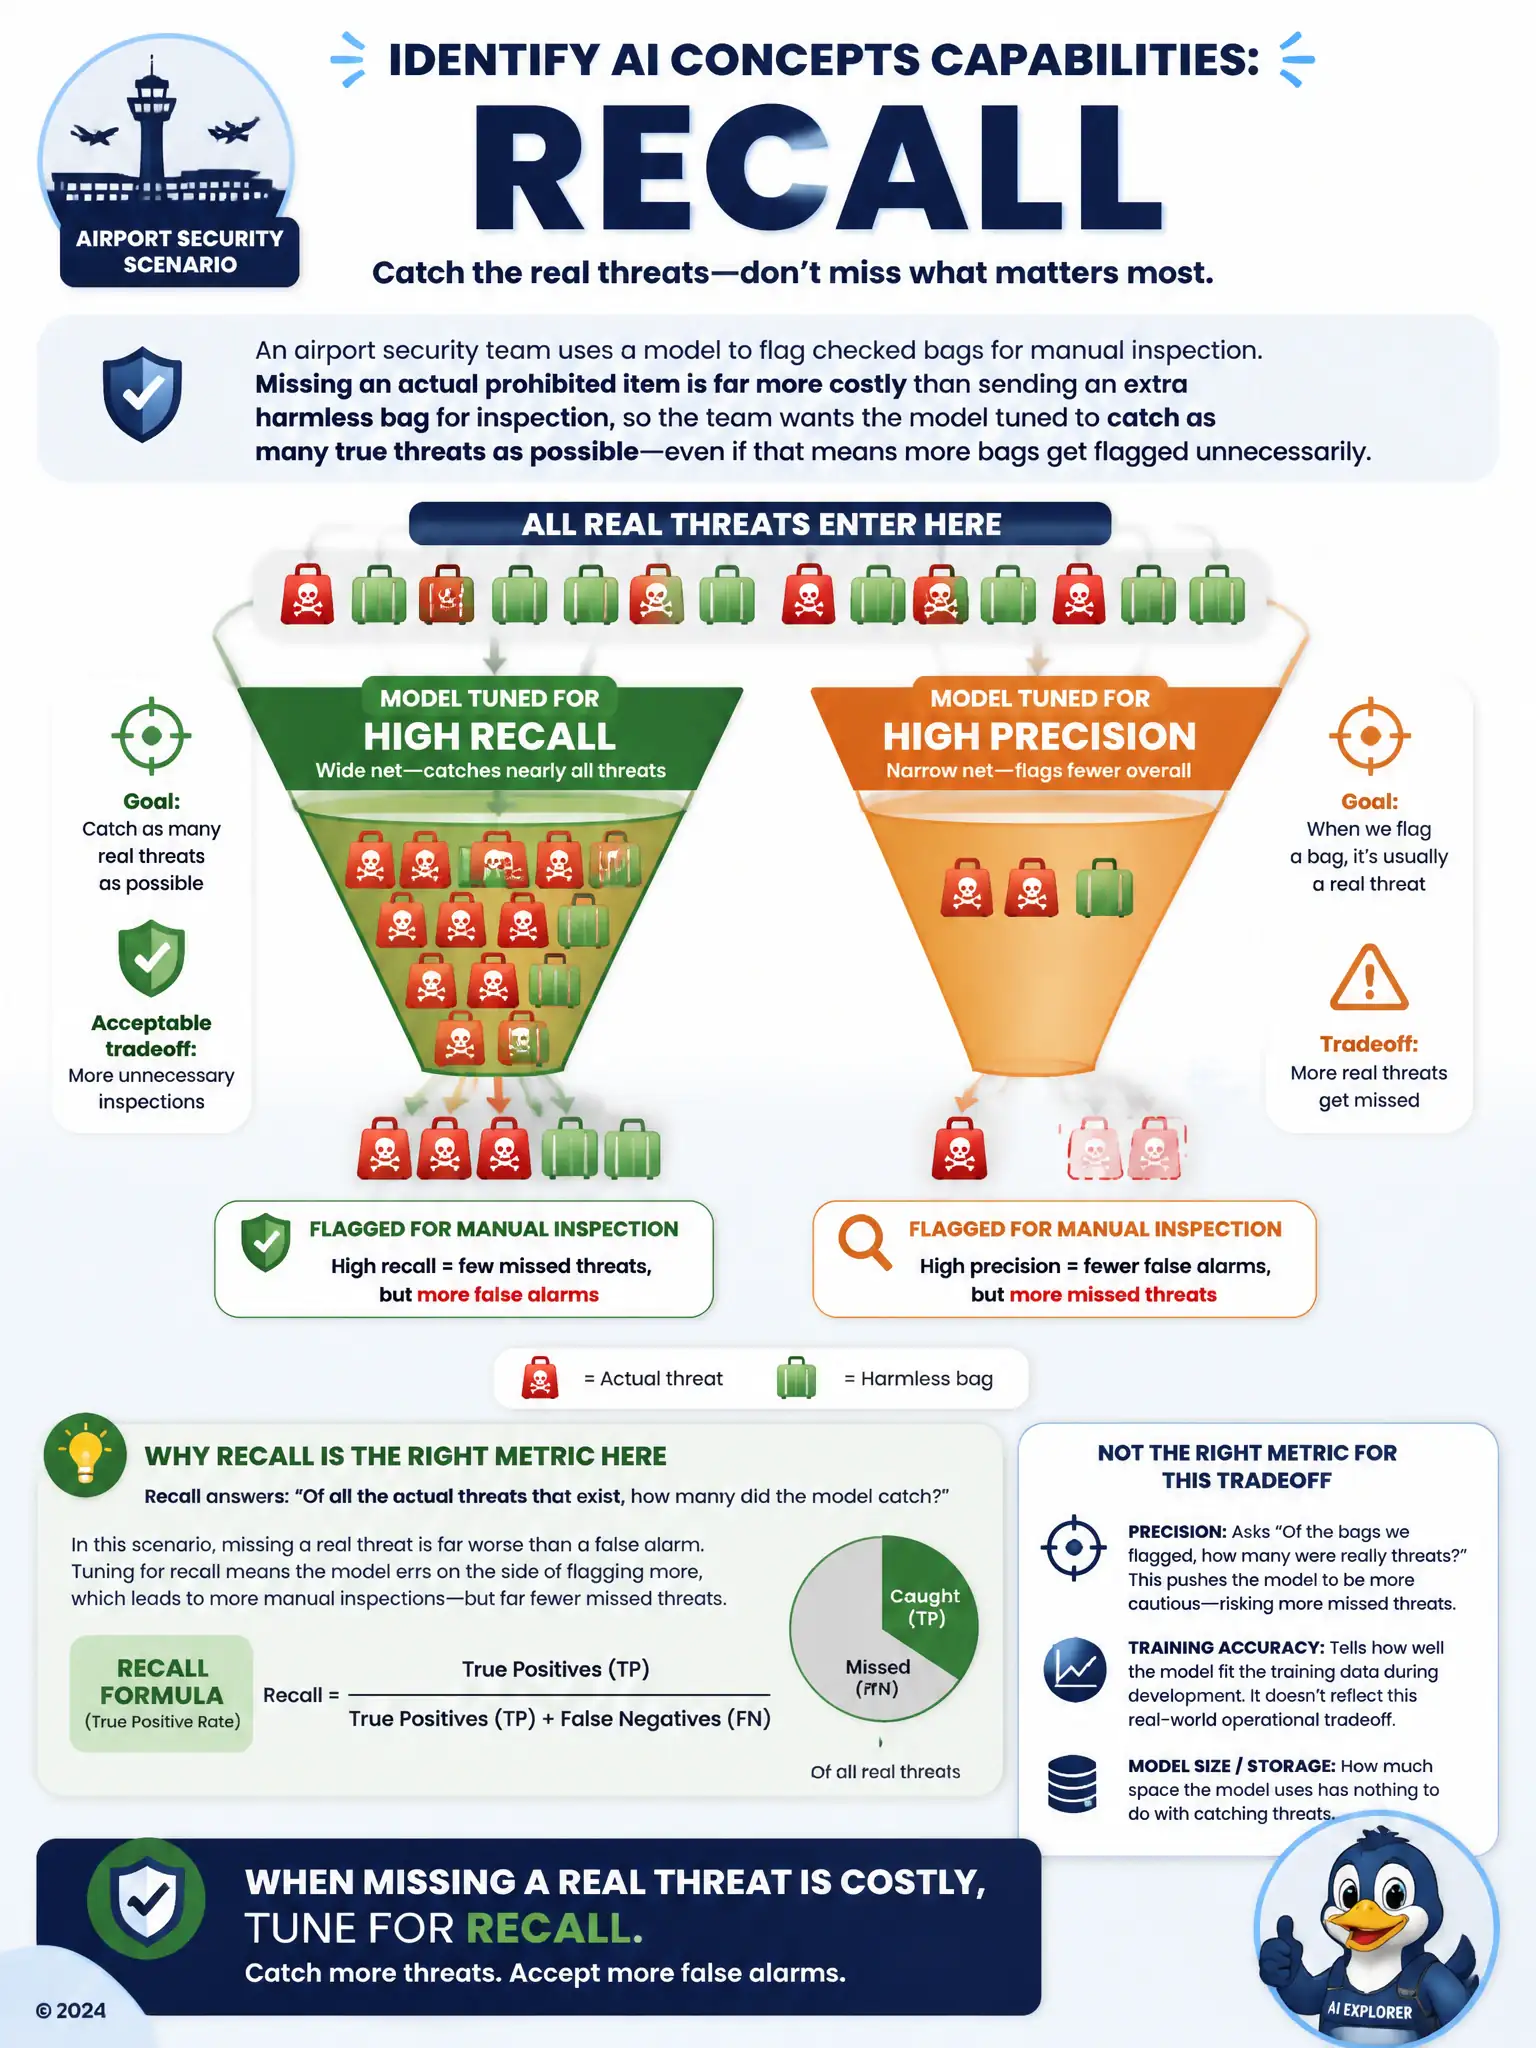
An airport security team uses a model to flag checked bags for manual inspection. Missing an actual prohibited item is far more costly than sending an extra harmless bag for inspection, so the team wants the model tuned to catch as many true threats as possible even if that means more bags get flagged unnecessarily. Which evaluation metric should the team prioritize when tuning the model?
Select an answer to reveal the explanation.
Short Explanation
When missing a real threat is far worse than a false alarm, you want the model to catch as many actual threats as possible, even if that means flagging more harmless bags. That's recall: out of all the real threats, how many did you actually catch. Tuning for it accepts more unnecessary inspections to reduce missed threats.
Full Explanation
Recall measures the proportion of actual threats the model successfully catches out of all the real threats present, so prioritizing recall directly aligns with the team's goal of missing as few genuine prohibited items as possible, accepting more false alarms as an acceptable tradeoff. Precision is incorrect because precision measures the proportion of flagged bags that turn out to actually contain a threat; optimizing for precision would push the model to be more conservative about flagging, which increases the risk of missing real threats, the opposite of what the team wants. Training loss is incorrect because training loss is an internal measure of how well the model fits the training data during the optimization process itself, and it does not directly describe how well the deployed model balances catching threats versus generating false alarms. Model file size is incorrect because model file size relates to storage and deployment considerations, and it has no bearing on detection quality or the tradeoff between missed threats and false alarms.