
A customer-experience team has 50,000 open-ended survey comments with no predefined category list and wants to discover what topics customers are naturally talking about, grouping similar comments together for review. Which Foundry-based approach fits this task?
Select an answer to reveal the explanation.
Short Explanation
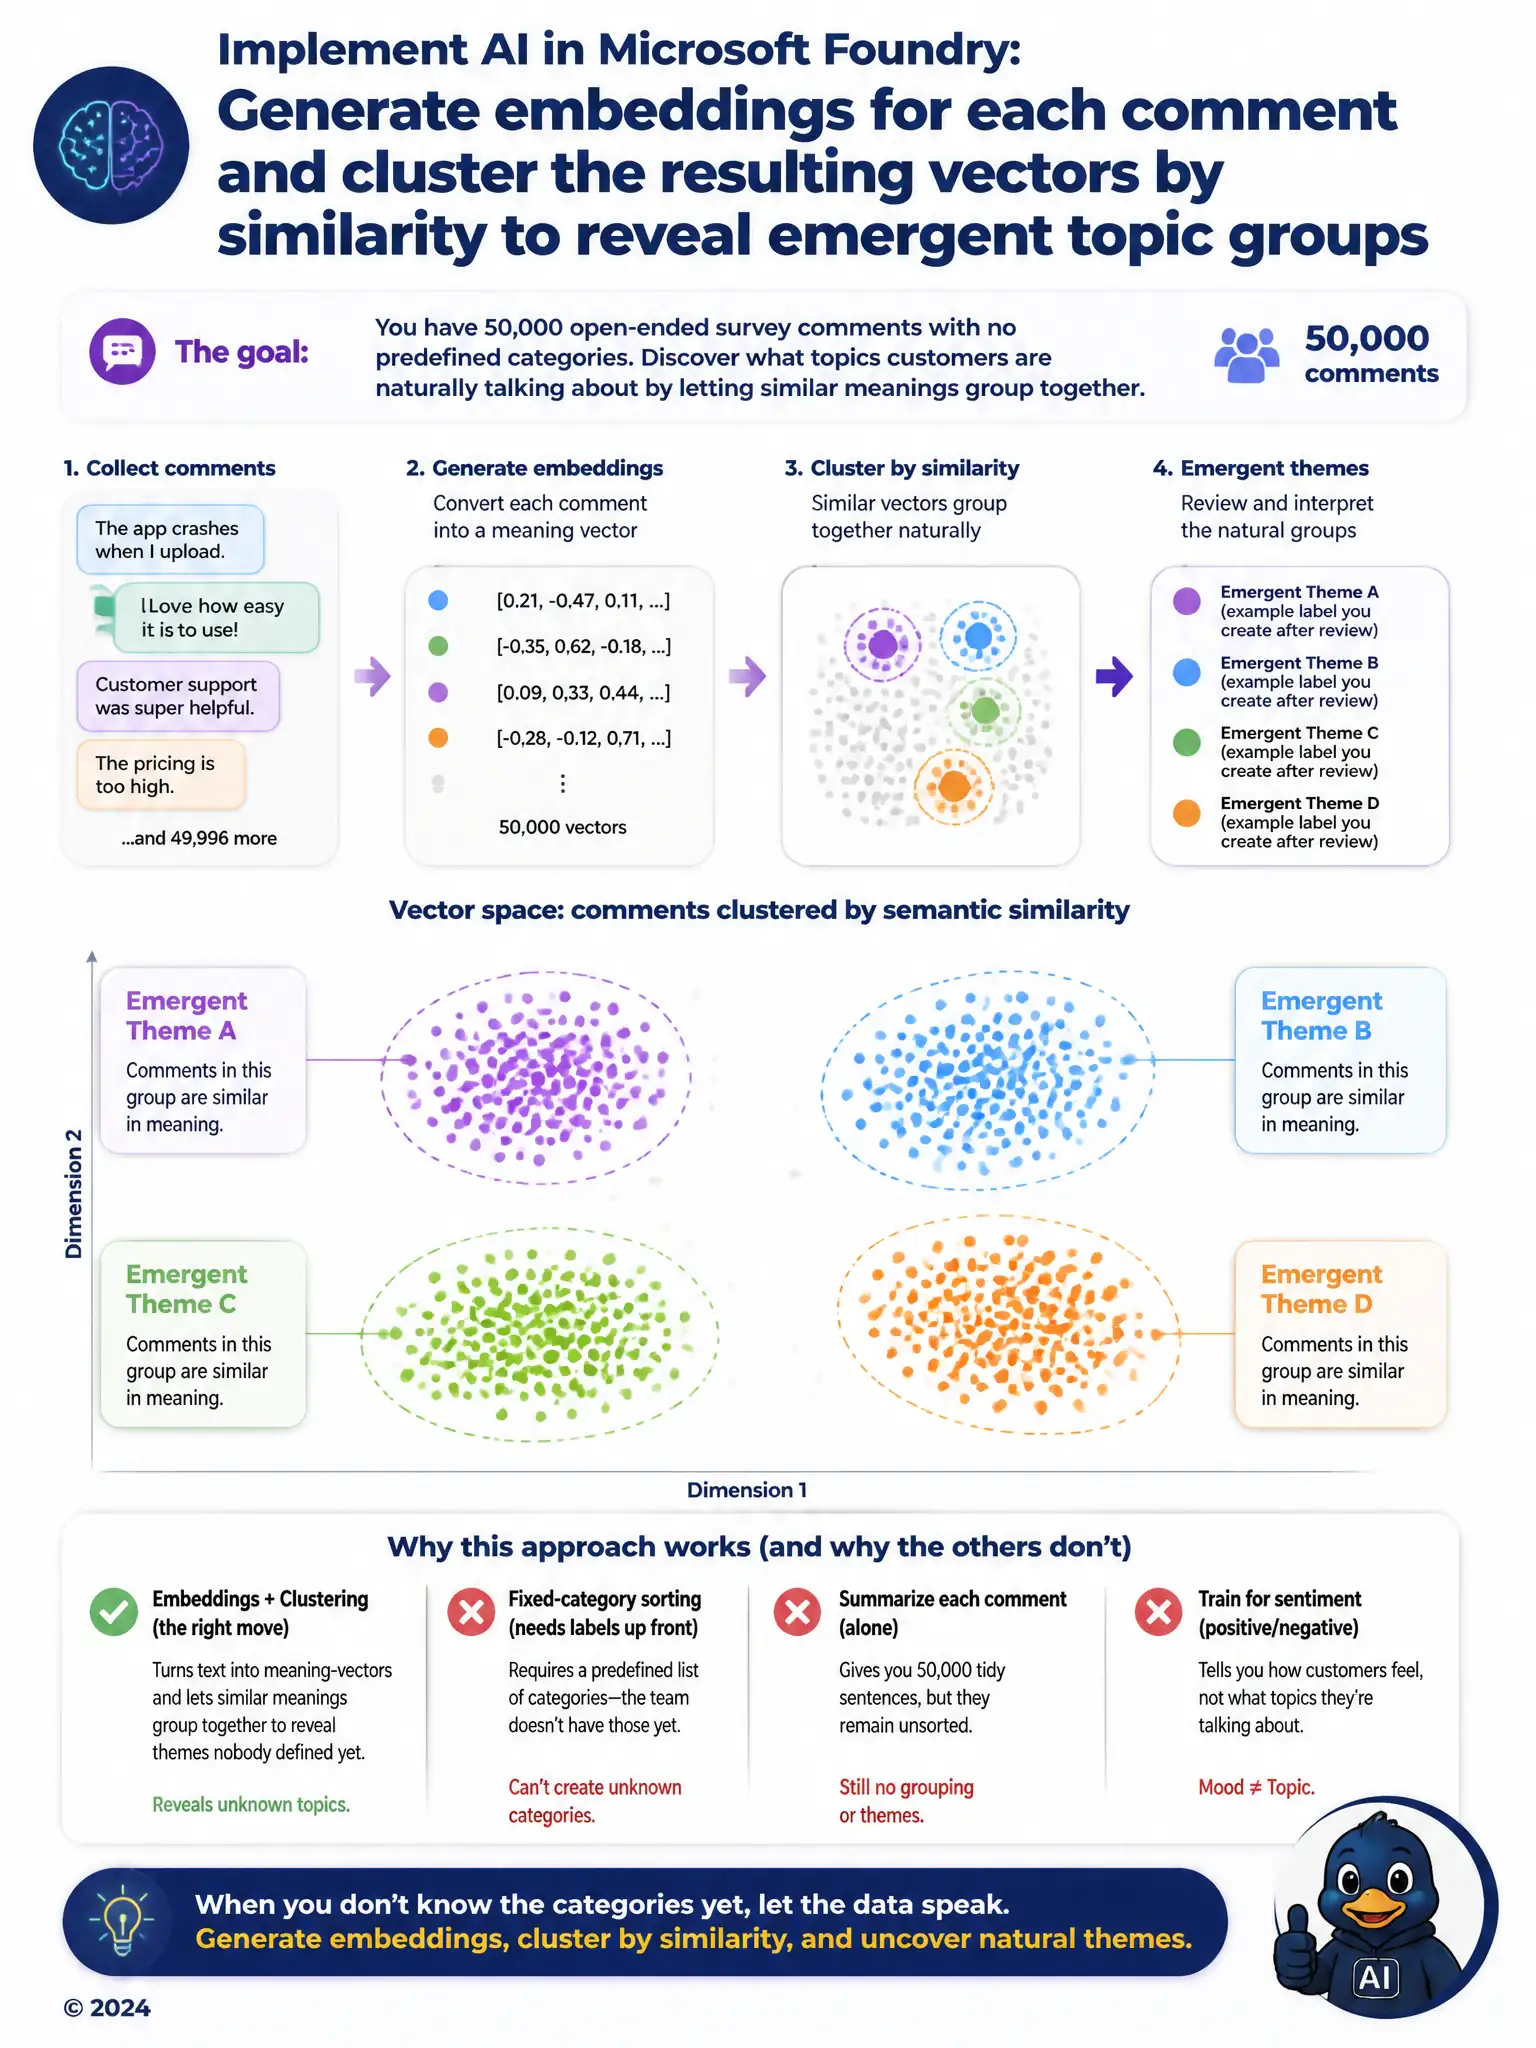
When you don't know the categories yet, you can't sort comments into a list that doesn't exist. You turn each comment into a meaning vector, then cluster similar vectors so natural topics rise to the top. A fixed-category sorter needs labels up front, and summaries or sentiment scores don't group topics.
Full Explanation
The embedding-and-clustering approach is correct because generating embeddings turns each comment into a vector that captures its meaning, and clustering those vectors by similarity groups comments that discuss related topics together, even though no one told the system in advance what those topics would be. This matches the scenario's core requirement: discovering emergent themes with no predefined category list. The fixed-category text classification model is incorrect because classification requires a fixed set of categories decided in advance, but the team explicitly has no such list yet; it fits sorting into known buckets, not discovering unknown ones. The per-comment summarization approach is incorrect because summarizing each comment individually produces 50,000 isolated summaries without grouping anything together, leaving the team with the same organizational problem they started with. The sentiment fine-tuning approach is incorrect because fine-tuning for sentiment prediction would only classify comments as positive, negative, or neutral, which says nothing about the topics customers are discussing. Embedding-based clustering is the approach purpose-built for surfacing structure in unlabeled text, making it the right fit when the goal is exploration rather than sorting into predetermined boxes.