
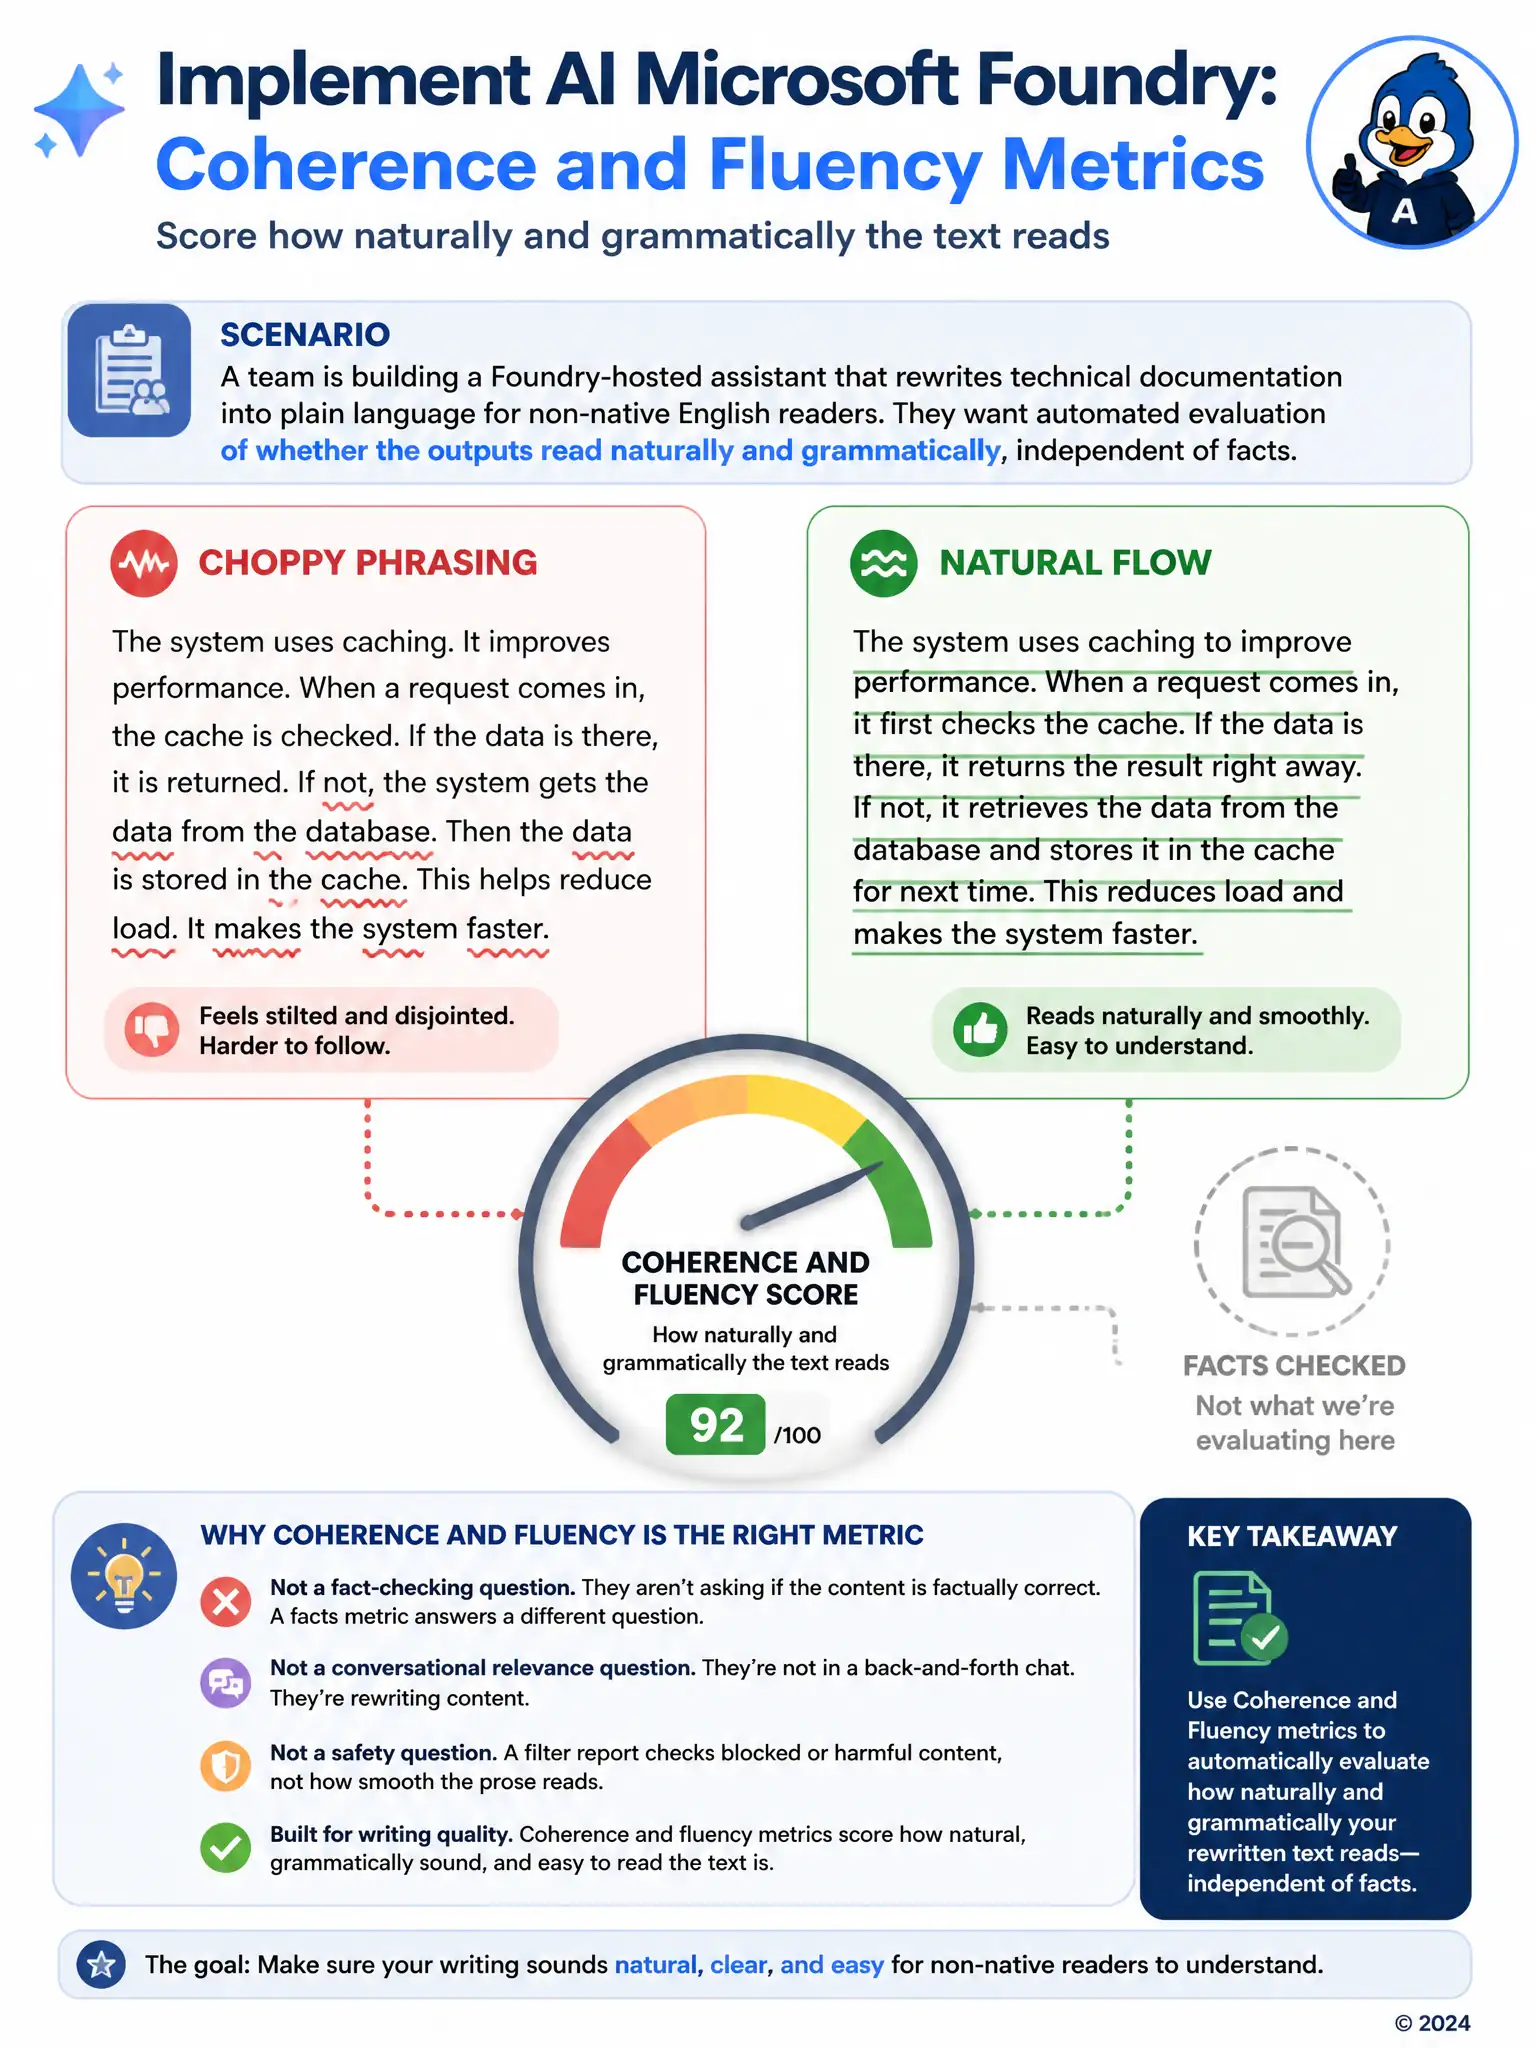
A team building a Foundry-hosted assistant that rewrites technical documentation into plain language for non-native English readers wants automated evaluation of whether the outputs read naturally and grammatically, independent of whether the underlying facts are correct. Which built-in evaluation metric should they run?
Select an answer to reveal the explanation.
Short Explanation
You're not fact-checking here—you're checking whether the rewrite sounds like real human writing. Coherence and fluency metrics score how naturally and grammatically text reads, which is exactly what you need.
Full Explanation
The correct choice is coherence and fluency metrics, which are designed to score readability and grammatical naturalness of generated text. That is precisely what the team wants to measure: whether the plain-language rewrite reads smoothly for non-native readers, separate from any question about factual accuracy. The custom content filter severity report is incorrect because it shows which harmful content categories were blocked. That concern is entirely separate from writing quality and has nothing to do with how natural the prose sounds. The relevance metric is incorrect because it measures whether the response actually addresses the question the user asked. That applies to question-and-answer scenarios rather than documentation rewriting tasks judged on style. The groundedness metric is incorrect because it checks whether the response is supported by source documents. The team explicitly wants to evaluate readability independent of factual correctness, making groundedness the wrong metric for this specific goal. Coherence and fluency metrics are purpose-built for judging how naturally and grammatically text reads, matching exactly what the scenario calls for.