
A research group has 2 million archived scientific PDFs that need a one-paragraph summary generated for each. The job will run overnight with no user waiting on results, and the team is choosing a deployment approach that minimizes cost since immediate response time does not matter. Which deployment choice fits this workload?
Select an answer to reveal the explanation.
Short Explanation
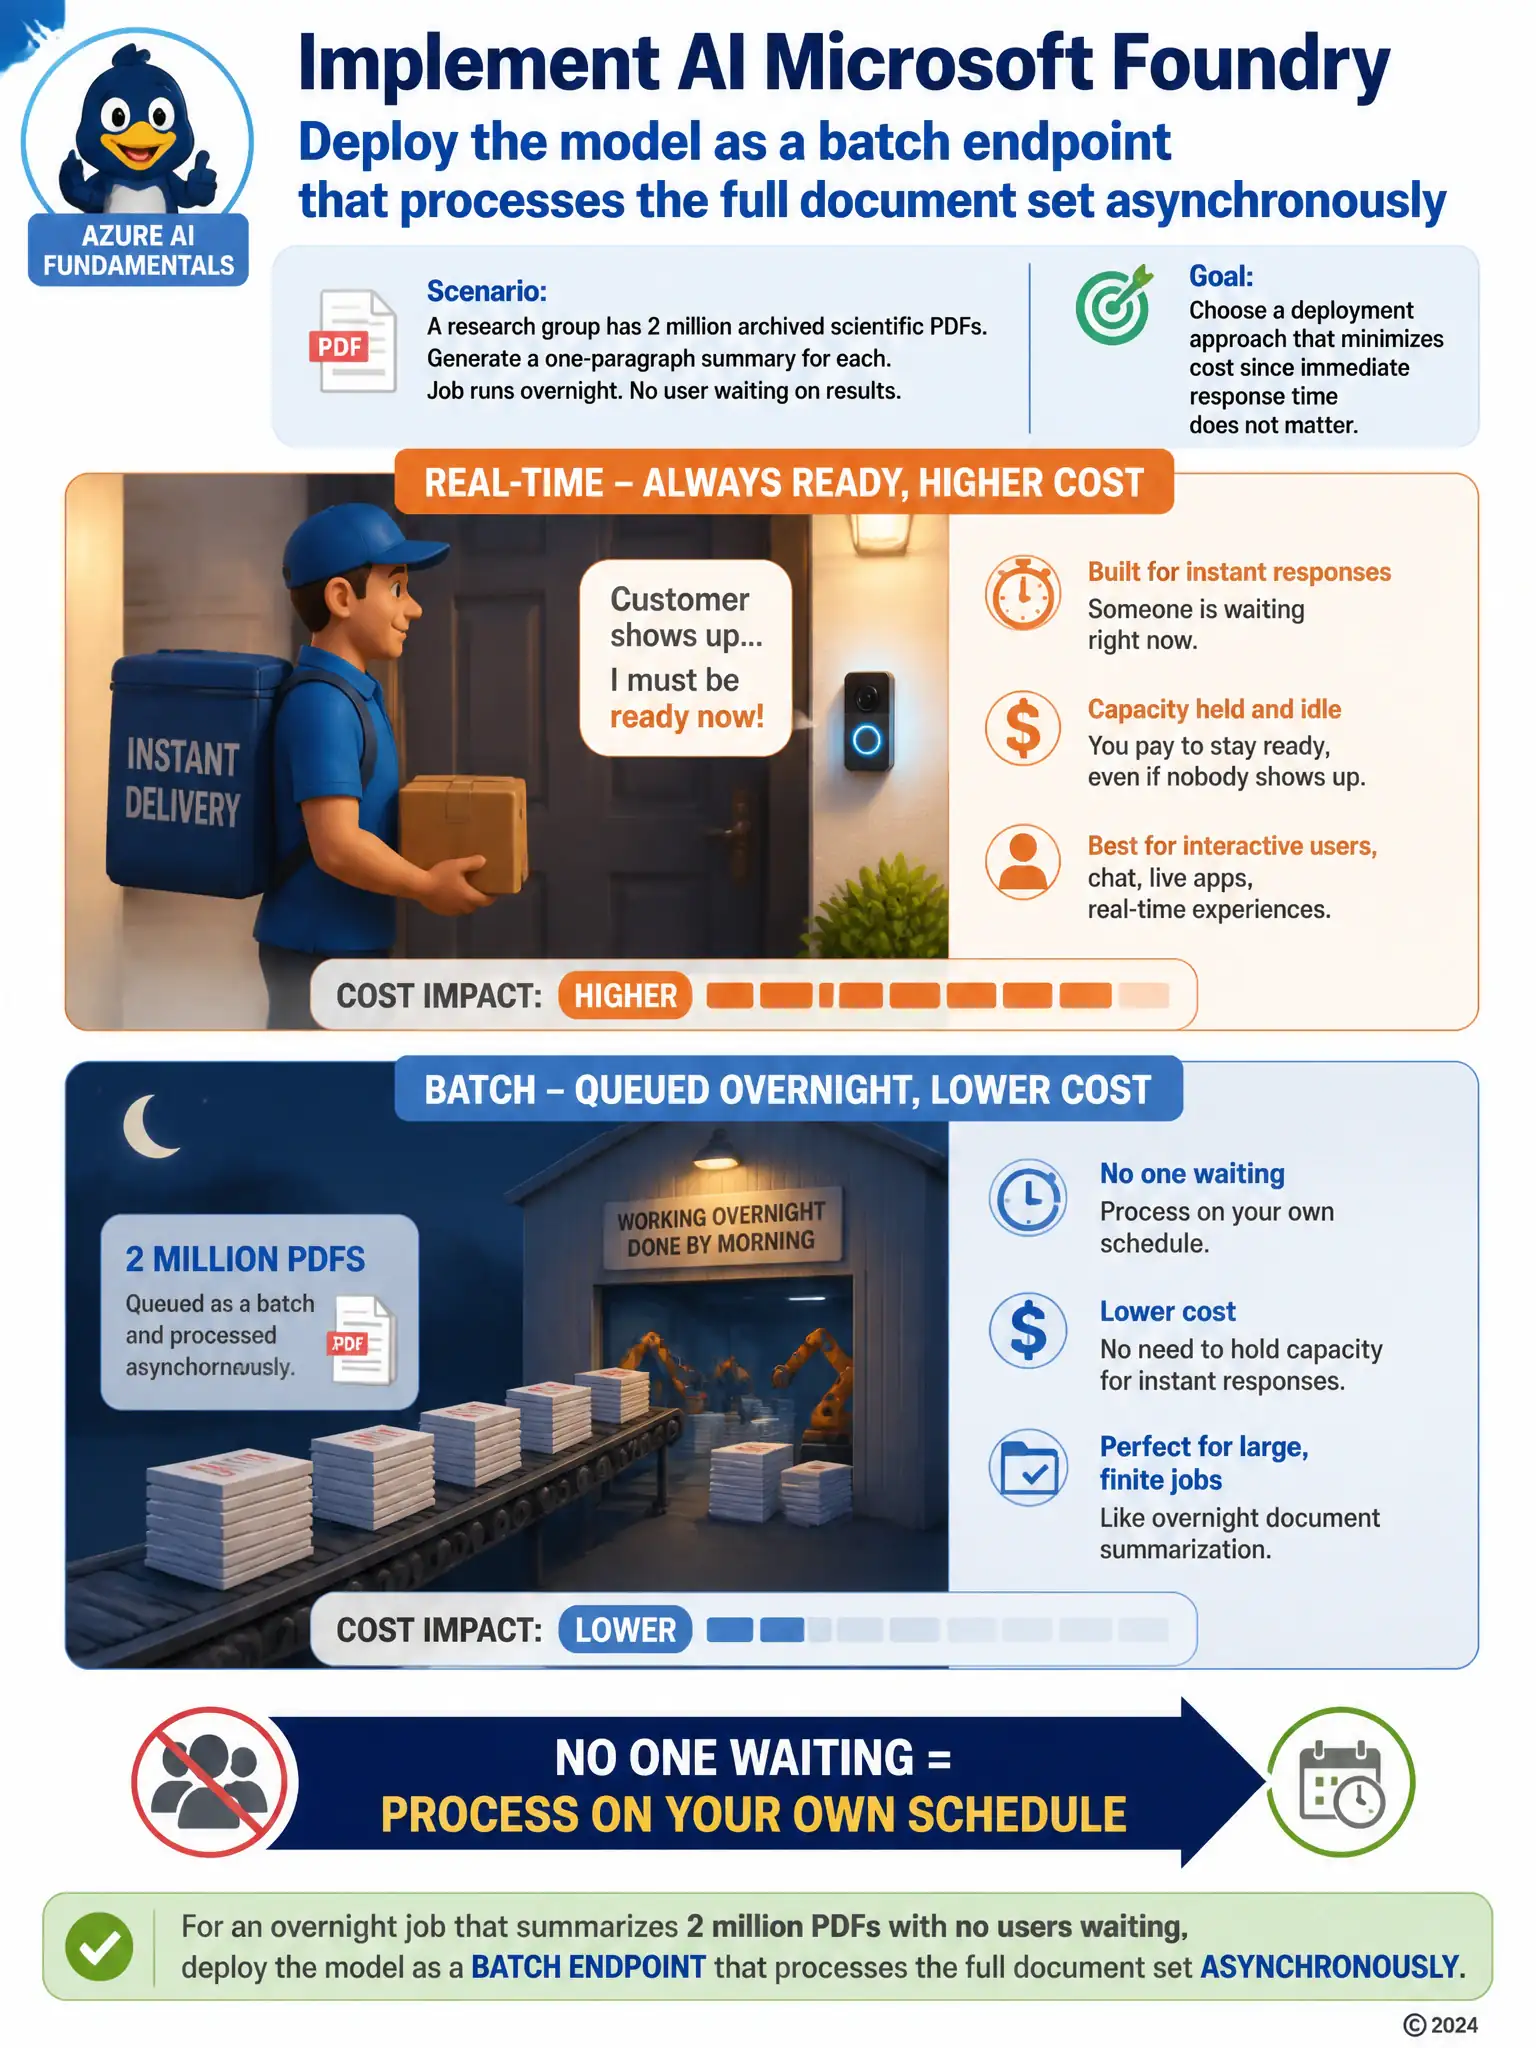
You don't need a system standing by for instant answers; you need a batch endpoint that processes the full document set asynchronously. It queues the whole pile and works through it at its own pace, which is cheaper for an overnight job with no one waiting.
Full Explanation
The deployment choice that fits is a batch endpoint that processes the full document set asynchronously. A batch endpoint is built exactly for this pattern: a large, known volume of work with no live user waiting on each response, so requests can be queued and processed at a pace that favors lower cost over speed, which matches an overnight job with 2 million documents and no latency requirement. A real-time endpoint provisioned for peak concurrent load is incorrect because it is optimized for immediate response to each request and is billed and provisioned for that responsiveness, which is unnecessary expense when nothing is waiting on the answer. A dedicated throughput unit sized for continuous low-latency traffic is incorrect because it is meant to guarantee consistent low-latency capacity for steady interactive traffic; committing to that capacity model for an overnight, non-interactive job pays for responsiveness the task does not need. Autoscaling configured to react to second-by-second request spikes is incorrect because it solves a bursty, unpredictable interactive-traffic problem, not a single large known batch of offline work, so it adds complexity without addressing the actual requirement of processing a fixed dataset cheaply.