
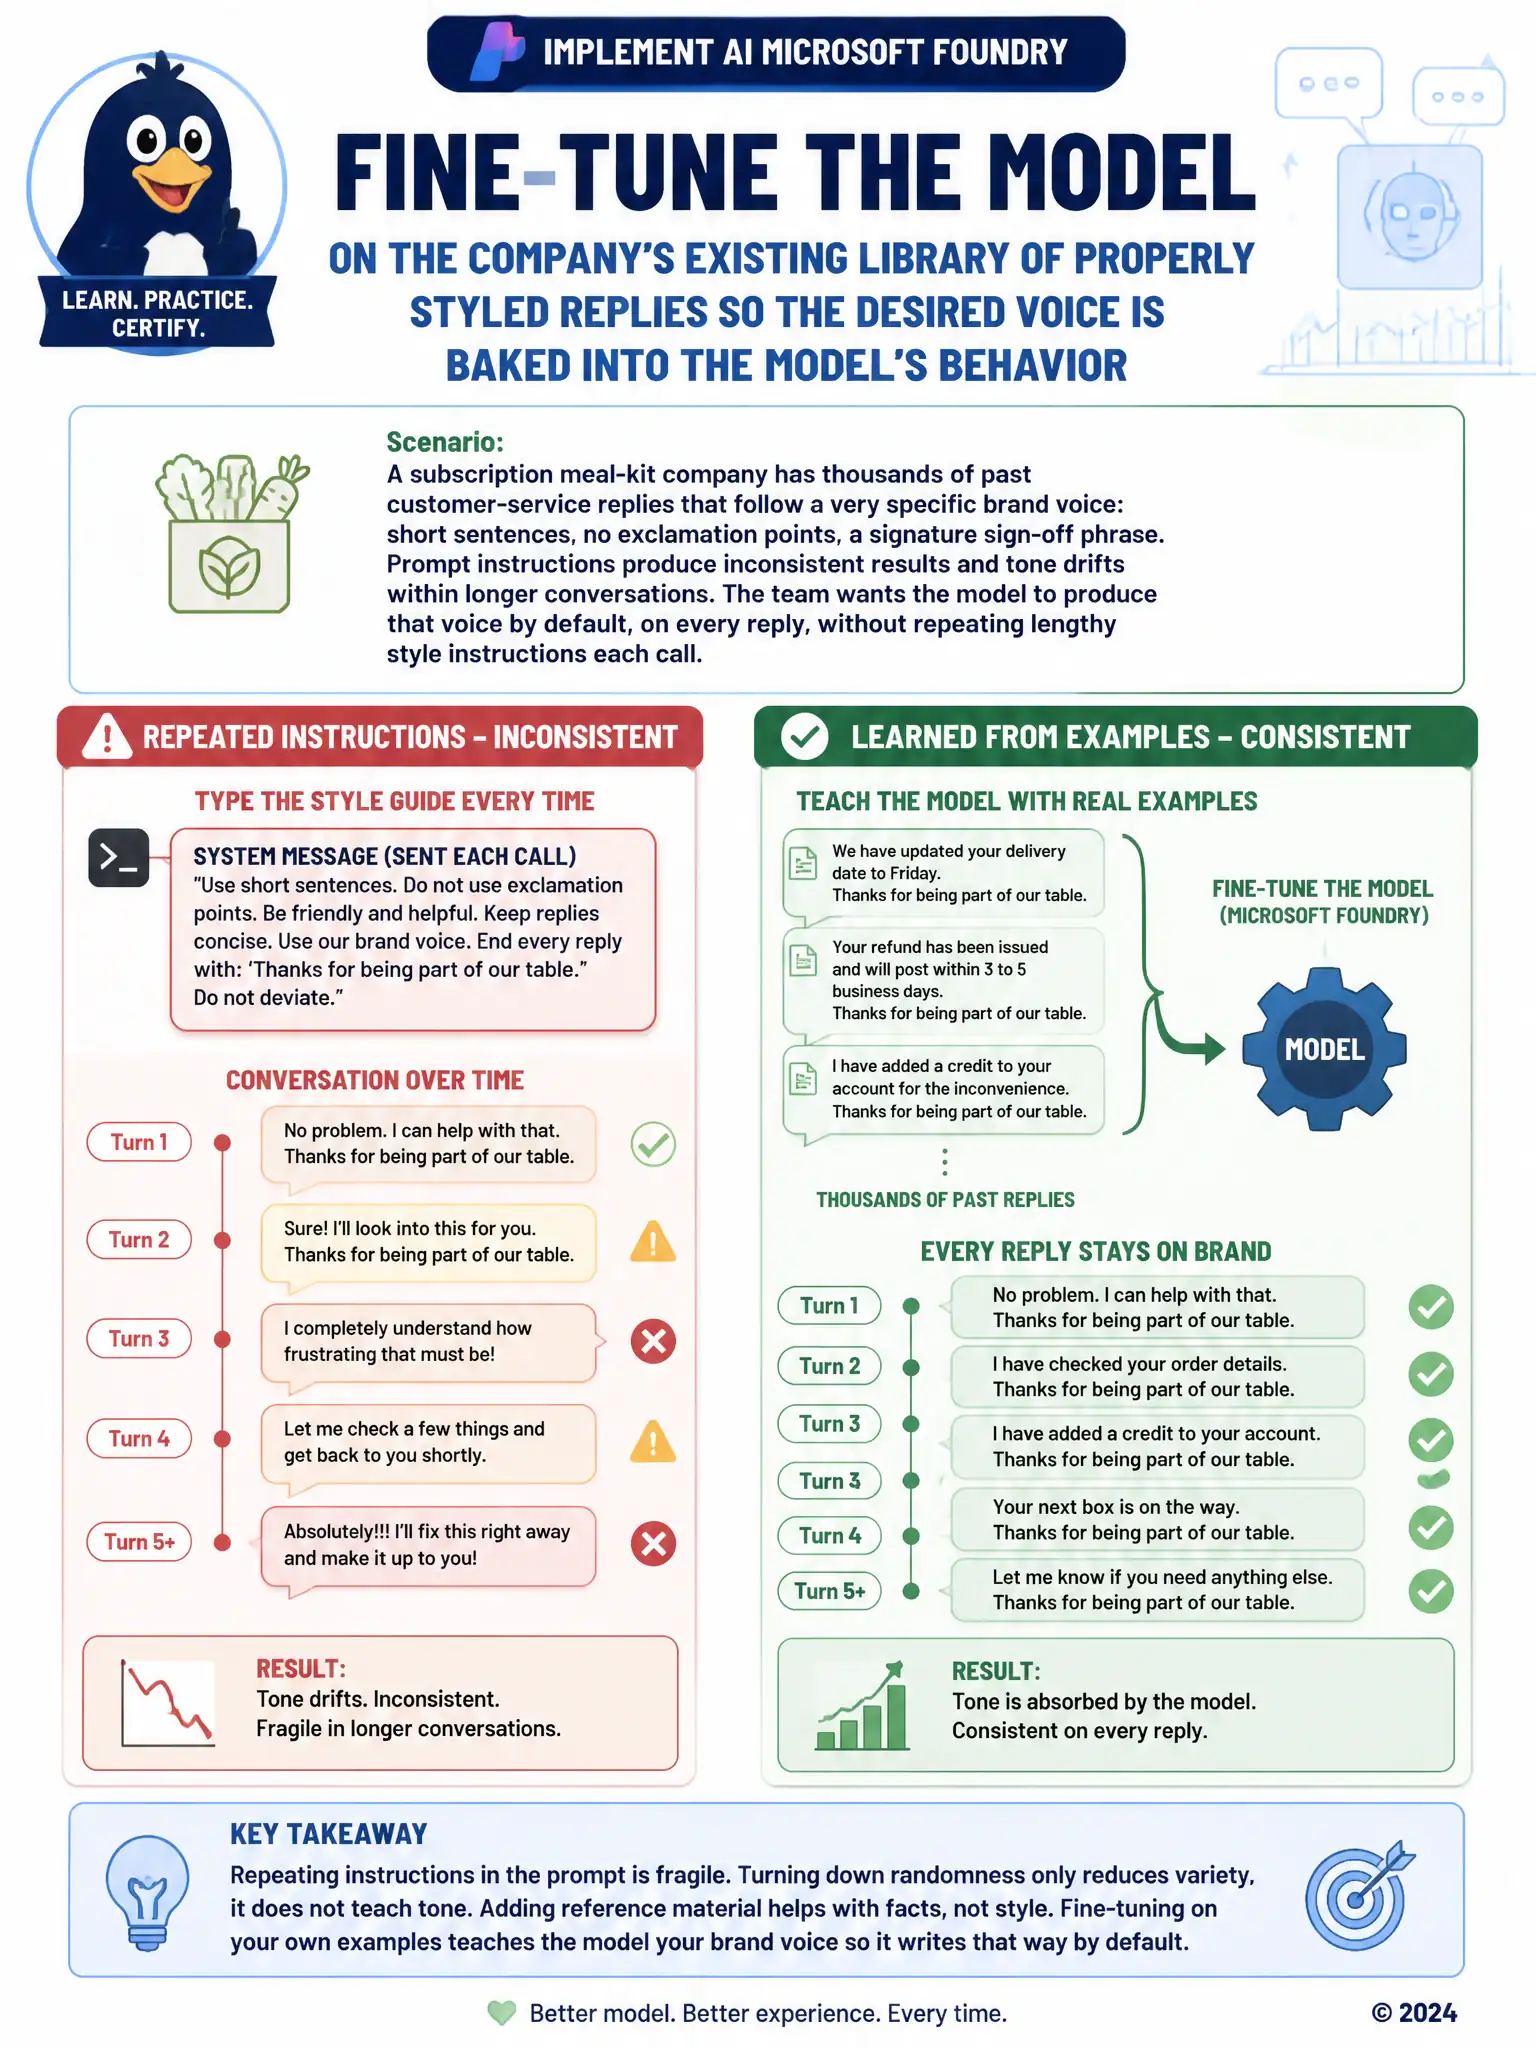
A subscription meal-kit company has thousands of past customer-service replies that all follow a very specific brand voice: short sentences, no exclamation points, a signature sign-off phrase. Prompt instructions describing this style in the system message produce inconsistent results, and the tone drifts within longer conversations. The team wants the model to produce that voice by default, on every reply, without repeating lengthy style instructions each call. Which approach best fits this need?
Select an answer to reveal the explanation.
Short Explanation
Think about the difference between handing someone a style guide every time and having someone who's absorbed the house style. You want the voice baked in, so fine-tune the model on the company's properly styled replies. Changing randomness, pulling in a style guide, or filtering mismatches won't teach the model to write that way.
Full Explanation
The correct approach is fine-tuning the model on the company's existing library of properly styled replies, because it trains the model directly on real examples so the brand voice becomes part of the model's learned behavior rather than something that has to be re-explained through prompt instructions every time, which is exactly the consistency problem described. The approach that changes the model's temperature setting to make output vary less between requests is incorrect because temperature controls the randomness of word choice at generation time; it does not teach the model a specific tone and would not fix instructions being followed inconsistently. The retrieval-augmented approach that pulls the style guide into context on every call is incorrect because retrieval-augmented generation is for supplying factual reference content the model does not know, not for instilling a writing style, and it would still rely on the model correctly interpreting style text in context each time, which is the failure mode described. The content-filter approach that flags replies not matching the brand voice is incorrect because a content filter screens for harmful categories like hate speech or violence; it has no mechanism for detecting or correcting tone and would not make replies match a brand voice.