
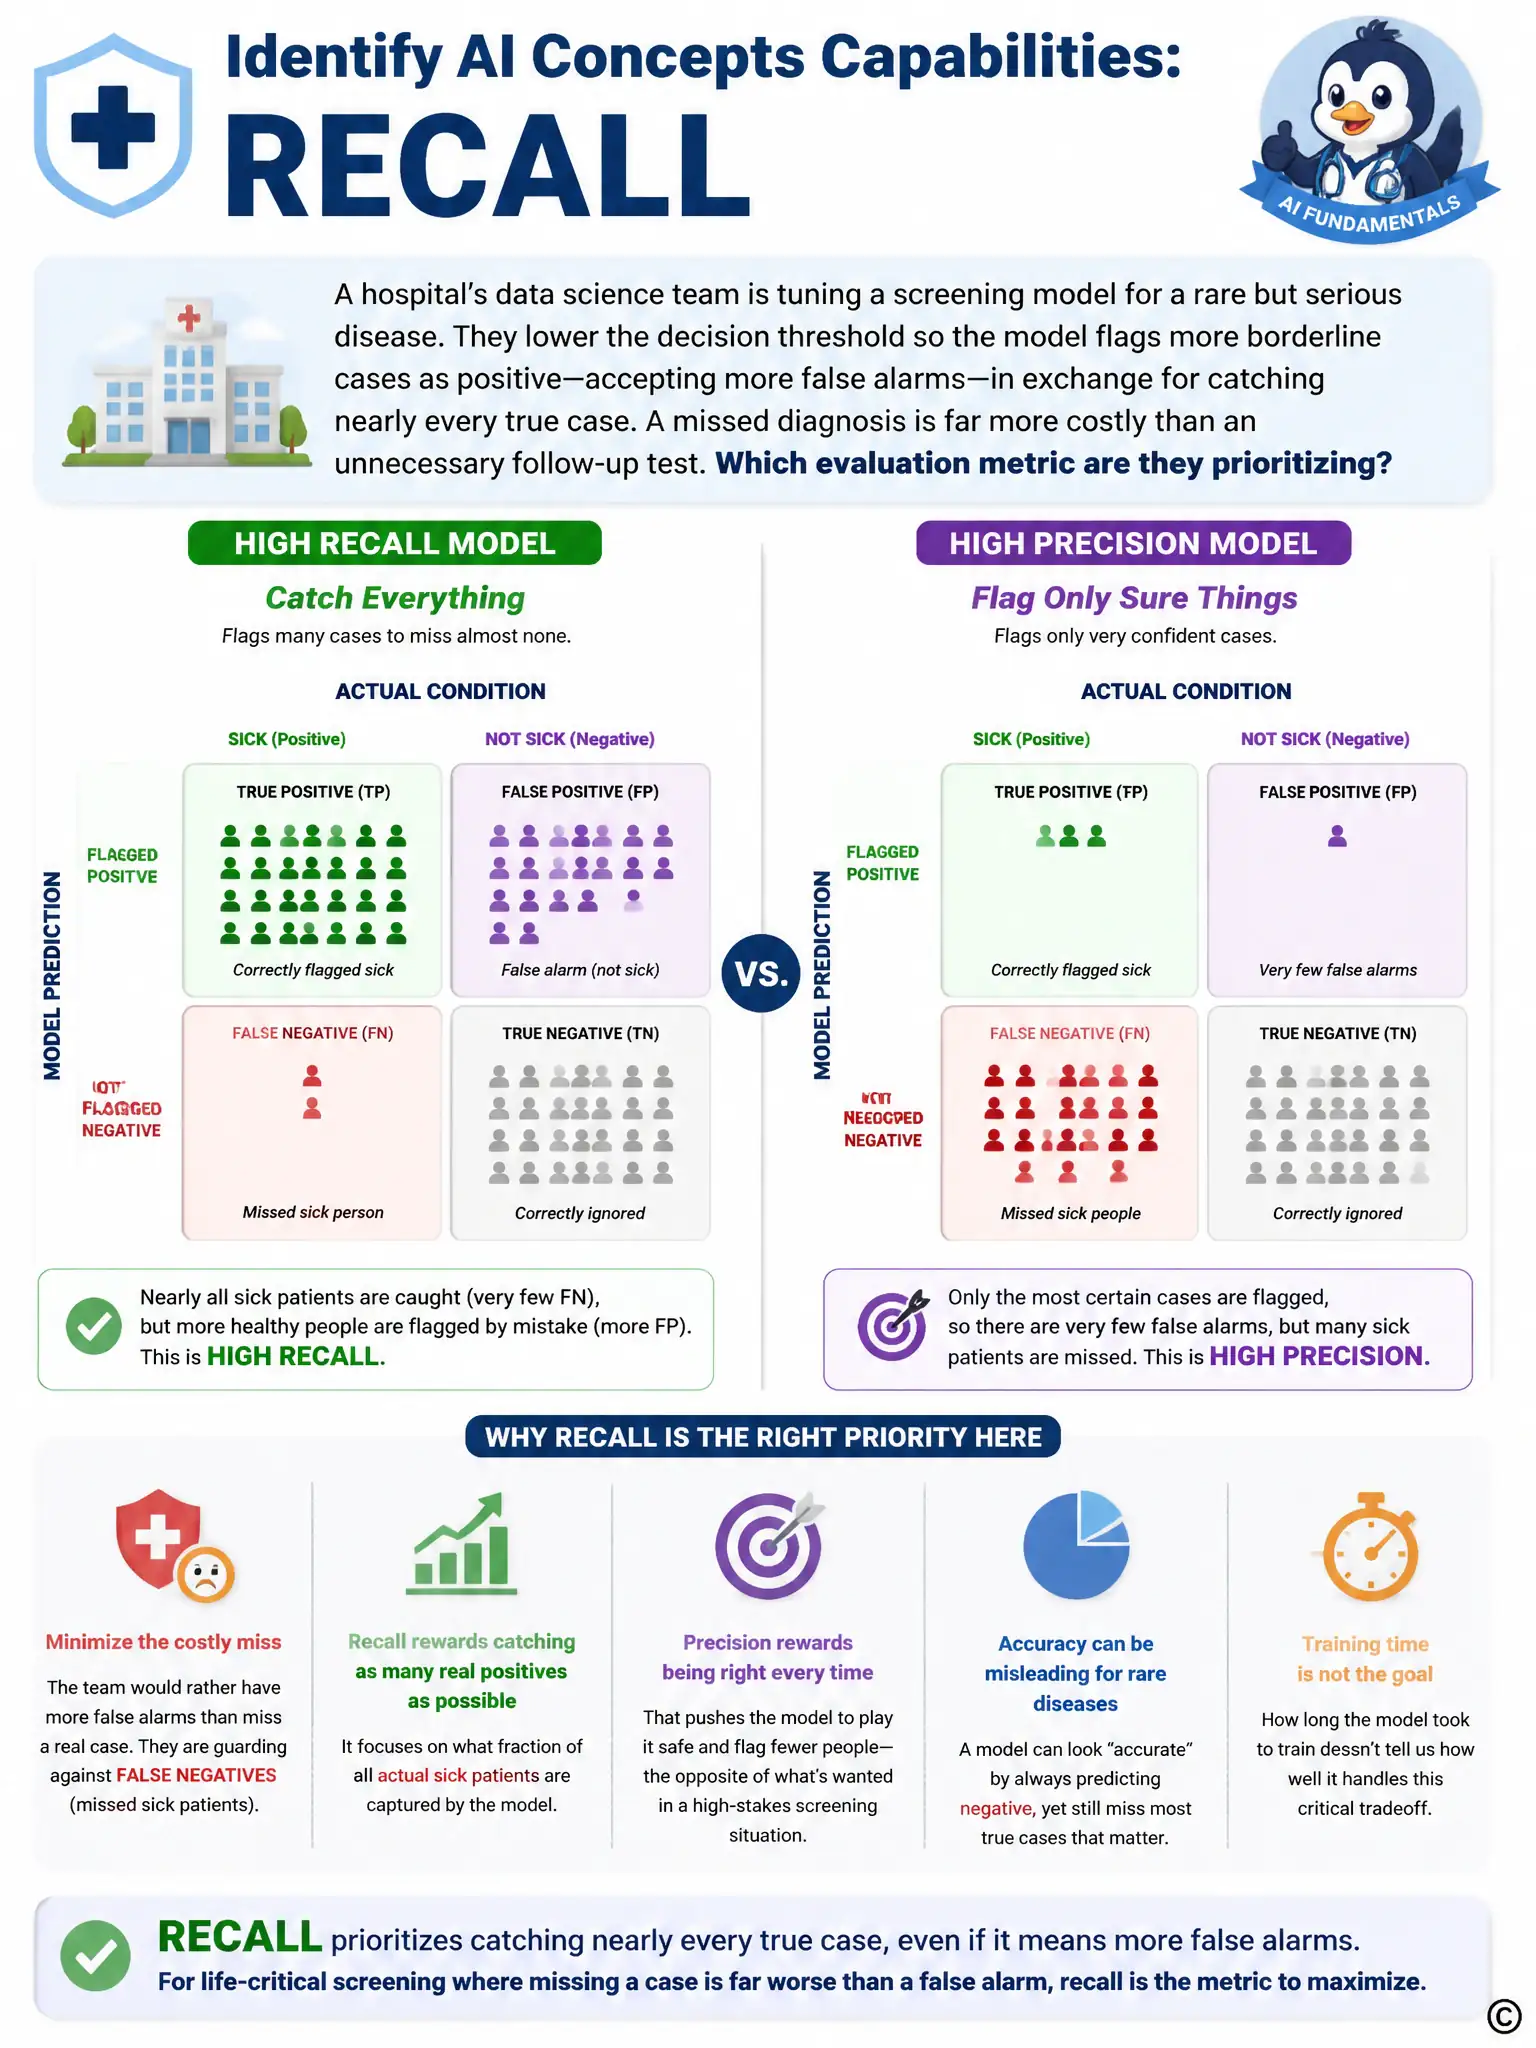
A hospital's data science team is tuning a screening model for a rare but serious disease. They deliberately adjust the decision threshold so the model flags more borderline cases as positive, accepting more false alarms in exchange for catching nearly every true case, because a missed diagnosis is far more costly than an unnecessary follow-up test. Which evaluation metric are they prioritizing?
Select an answer to reveal the explanation.
Short Explanation
You're guarding against missing real cases, so you want the metric that rewards catching as many true positives as possible even if it means more false alarms. That's recall. Precision would make the model play it safer, accuracy can hide the rare-case problem, and training time isn't part of this tradeoff.
Full Explanation
Recall measures the proportion of actual positive cases the model correctly identifies, so maximizing recall means minimizing missed true cases, which is exactly the tradeoff the team is making by accepting more false alarms. The precision option is incorrect because precision measures how many of the model's positive predictions are actually correct; optimizing for precision would push the model toward fewer, more confident positive flags, which is the opposite of what the team wants when a missed case is costly. The overall accuracy option is incorrect because overall accuracy treats all correct predictions equally and can look misleadingly high on an imbalanced dataset where the disease is rare, without reflecting how well rare positive cases are being caught. The model training time option is incorrect because training time is an engineering and cost consideration unrelated to how well the model balances catching true cases against generating false alarms. Since the scenario centers on not missing real cases even at the cost of more false alarms, recall is the metric being prioritized.