
A crisis-support hotline is deploying a Foundry-hosted chat model to have supportive conversations with people describing self-harm thoughts. Because the topic itself involves sensitive language that a generic filter might block outright, the team needs the conversation to continue while still blocking genuinely dangerous instructional content. What should they configure?
Select an answer to reveal the explanation.
Short Explanation
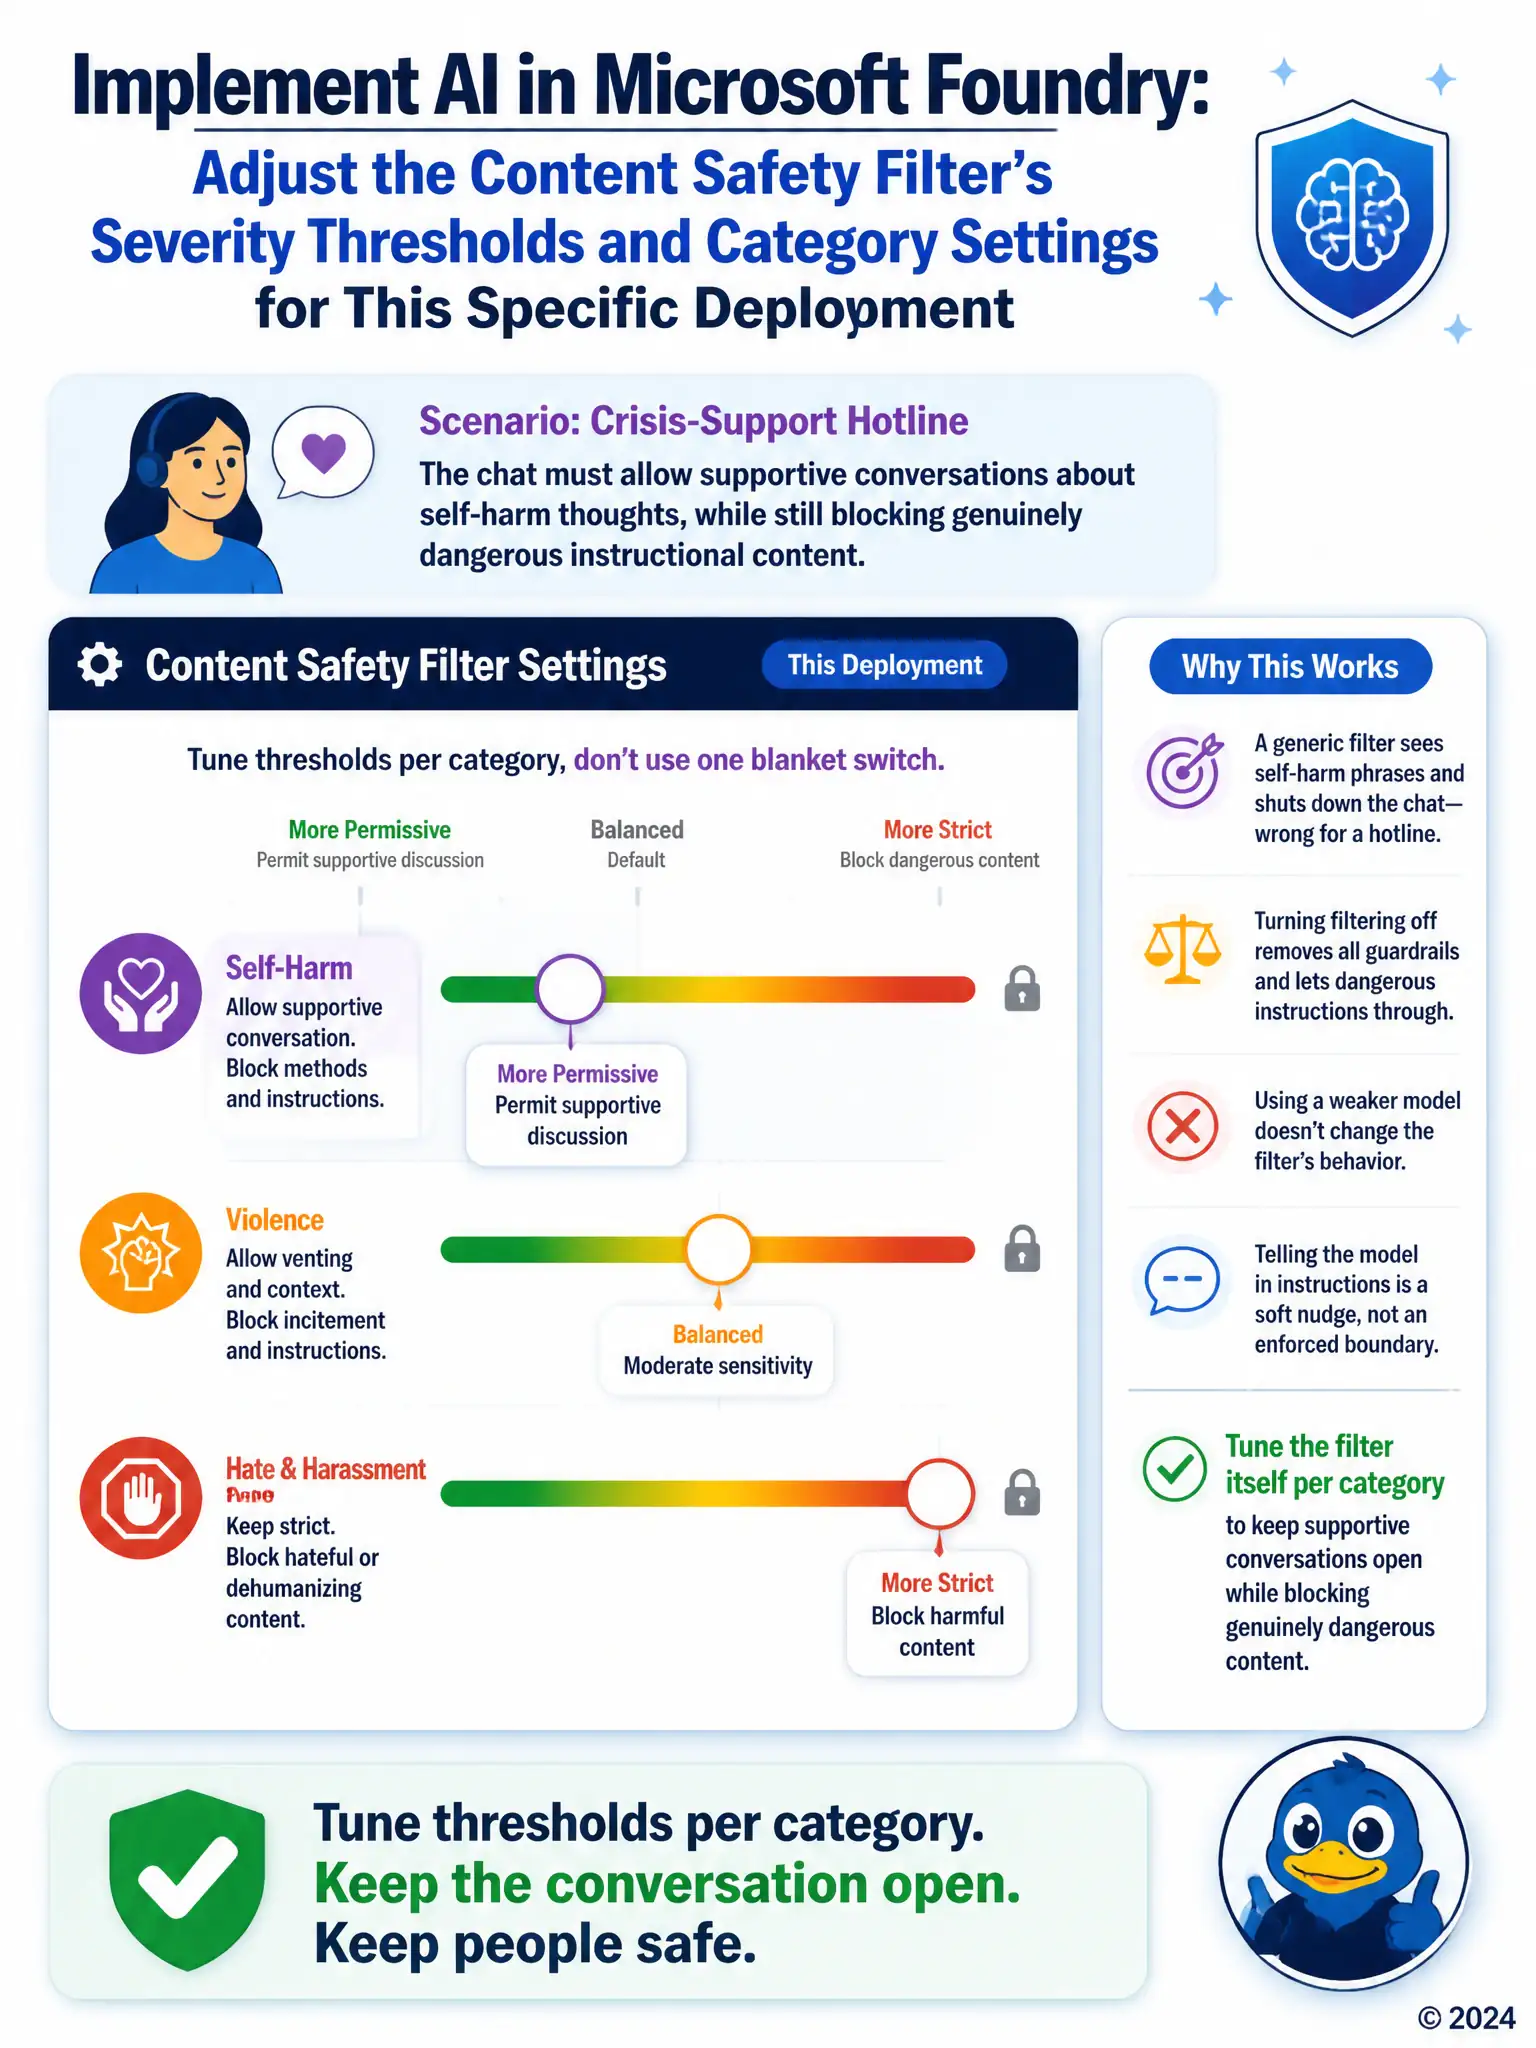
A generic filter can shut down self-harm talk too fast, but you don't want to turn filtering off and let dangerous instructions through. Tune the filter's severity thresholds and category settings for this hotline deployment so supportive conversation continues while genuinely dangerous content stays blocked.
Full Explanation
Adjusting the content safety filter's severity thresholds and category settings for this specific deployment, rather than leaving the default blanket filter in place, lets the hotline allow discussion of self-harm topics at a level appropriate to supportive counseling, while still keeping protections active against genuinely dangerous instructional content. Disabling all content safety filtering for the deployment is incorrect because turning off filtering entirely removes protection against the very content the team still wants blocked, such as detailed self-harm instructions, which is the opposite of what a hotline needs. Replacing the chat model with a smaller model that has weaker general capabilities is incorrect because swapping in a weaker model does not change how the content safety filter behaves, and it risks degrading the quality of supportive responses without solving the filtering mismatch at all. Adding a line to the system message telling the model to be careful about sensitive topics is incorrect because a note in the system message is only a soft instruction the model may or may not consistently follow; it is not an enforced gate the way the configured content safety filter is, so genuinely harmful content could still slip through or sensitive-but-appropriate content could still get blocked upstream. Tuning the filter's own configured thresholds is the mechanism designed for exactly this kind of nuanced, deployment-specific balance.