
Before committing to a model for a customer-support chatbot, a team wants to compare several candidate models in the Azure AI Foundry catalog side by side on accuracy, latency, and cost for their specific type of question, before deploying any of them. Which Foundry capability directly supports this comparison?
Select an answer to reveal the explanation.
Short Explanation
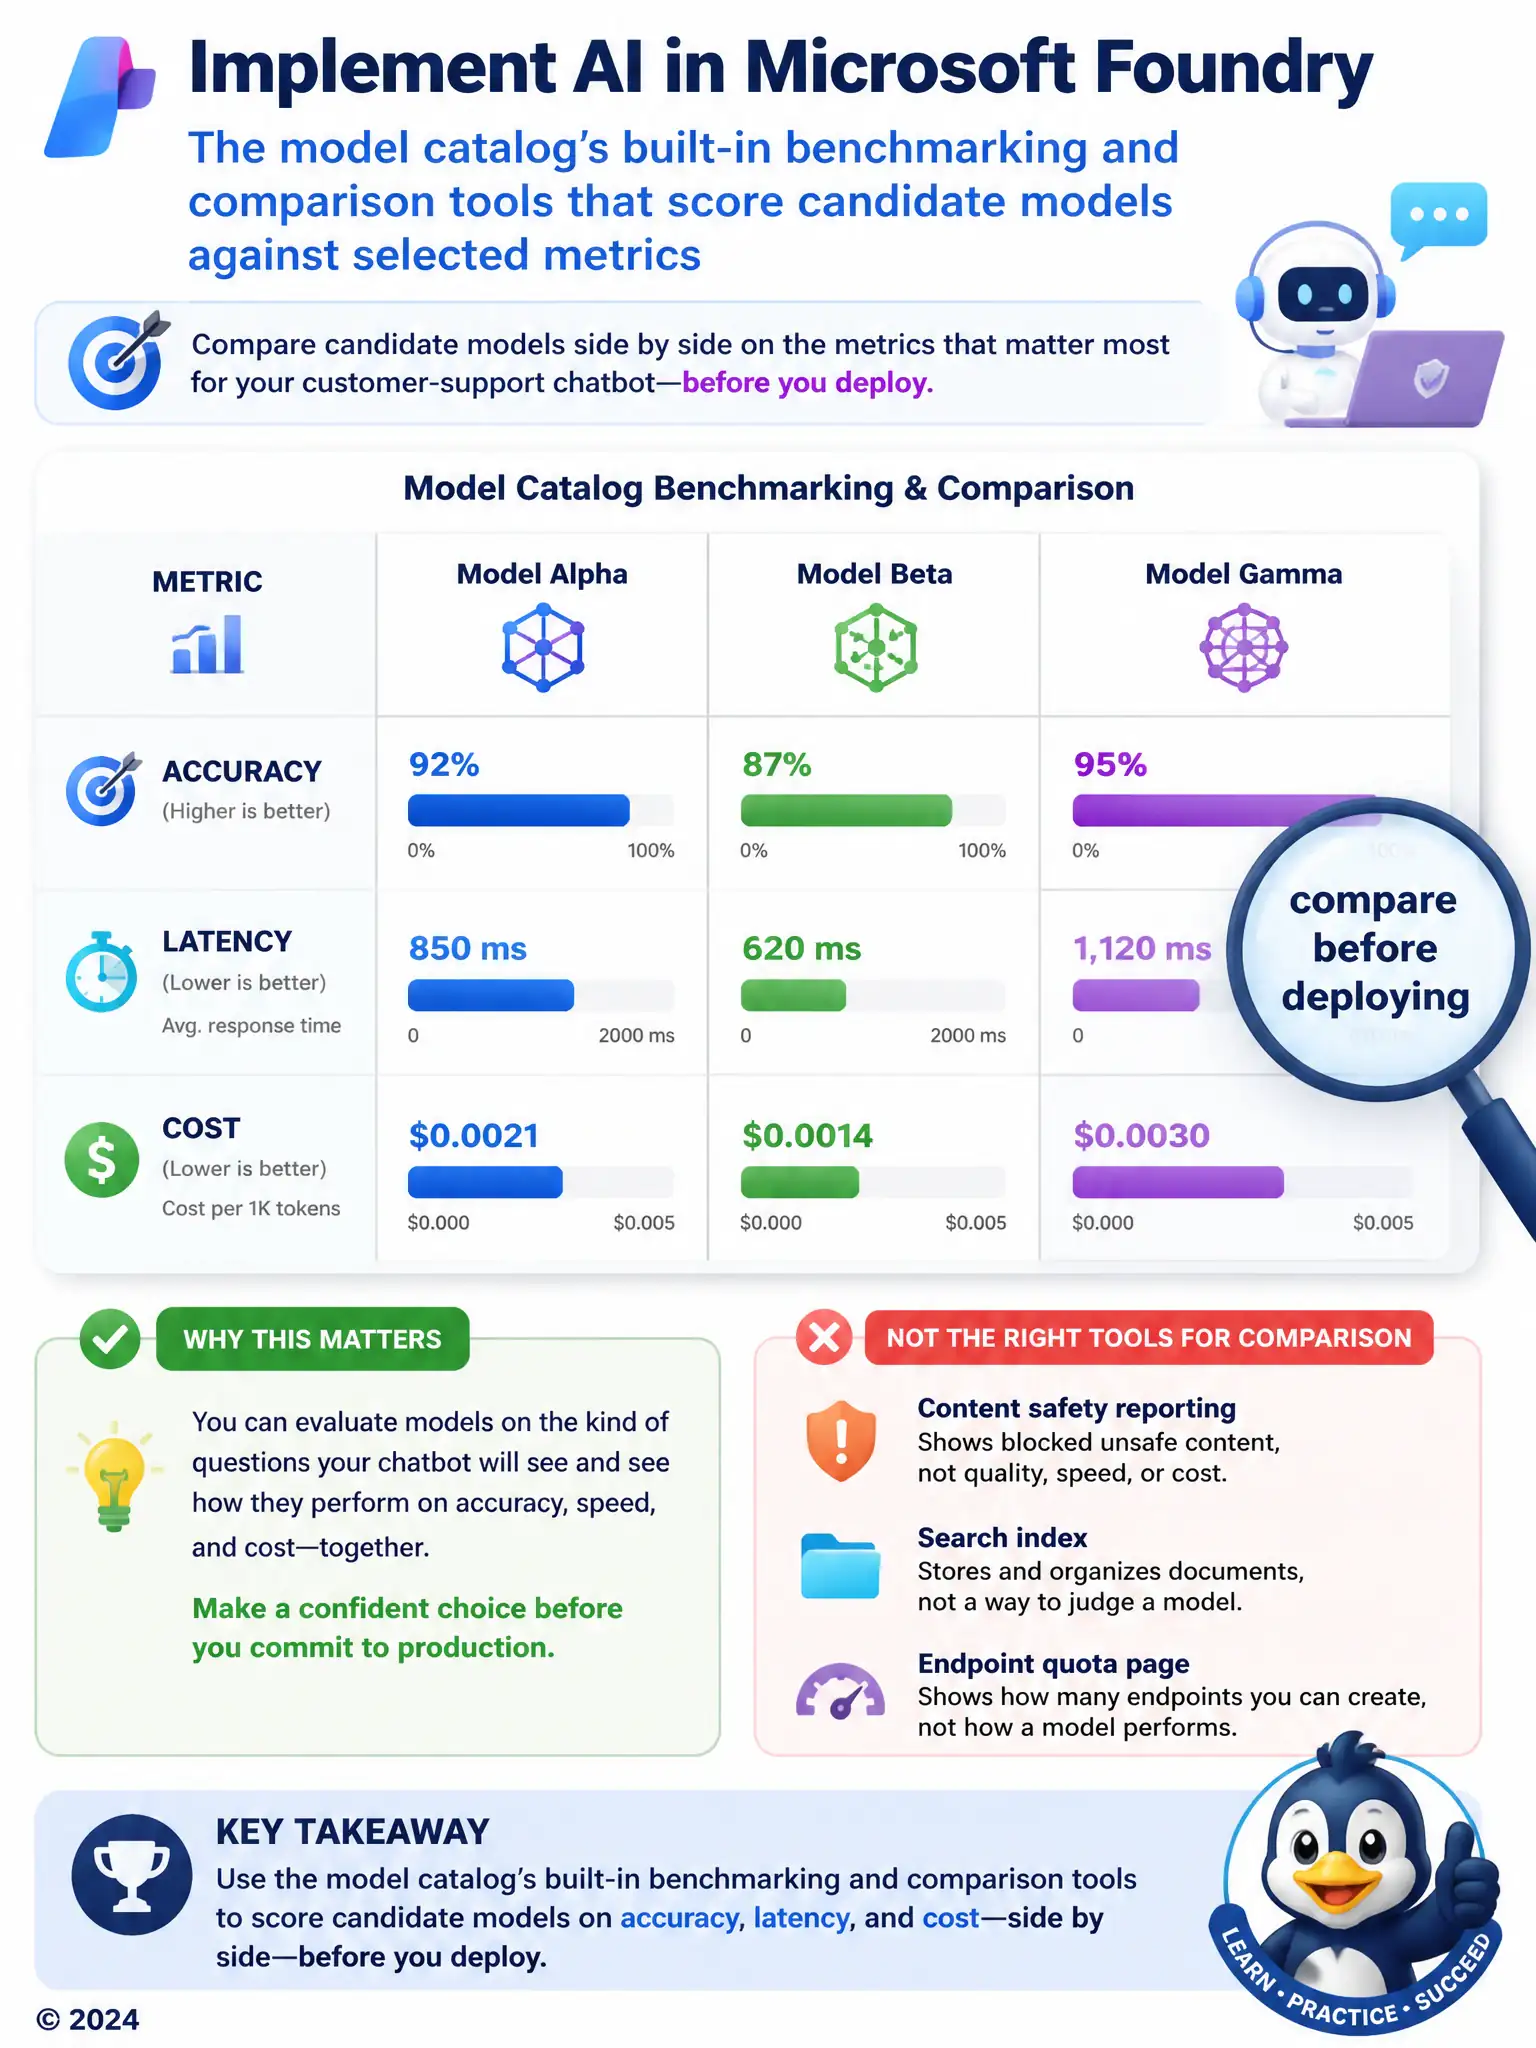
Before you commit, you want to line up candidate models and see how they score on accuracy, latency, and cost for your actual support questions. The catalog's built-in benchmarking and comparison tools do that directly, while safety-block counts, search indexes, and endpoint quotas don't measure model quality.
Full Explanation
The correct capability is the model catalog's built-in benchmarking and comparison tools that score candidate models against selected metrics. These tools let the team evaluate multiple candidate models side by side on metrics such as accuracy, latency, and cost, which is exactly the kind of pre-deployment evaluation this scenario calls for, all without committing to a full deployment first. The content safety filter configuration, which reports how often each model blocks unsafe content, is incorrect because it reports on how often content gets blocked for policy reasons, which has nothing to do with comparing model accuracy, speed, or price. The Azure AI Search index, which stores the documents the chatbot will retrieve from, is incorrect because it stores and retrieves the chatbot's knowledge documents; it plays a role in a RAG pipeline but does not benchmark or compare candidate models. The deployment quota page, which lists how many endpoints the subscription can create, is incorrect because it only shows how many endpoints a subscription is allowed to create, a capacity limit unrelated to evaluating which model performs best for the task. The benchmarking and comparison tools are purpose-built for exactly this kind of side-by-side, metric-driven model selection before deployment.