
A financial-services company has spent months refining system-message instructions and few-shot examples to get a Foundry-deployed model to consistently format outputs to the firm's compliance-mandated document template and tone, but the model still drifts back to its default style after a few conversational turns. The company has thousands of correctly formatted prior documents. What should they do next?
Select an answer to reveal the explanation.
Short Explanation
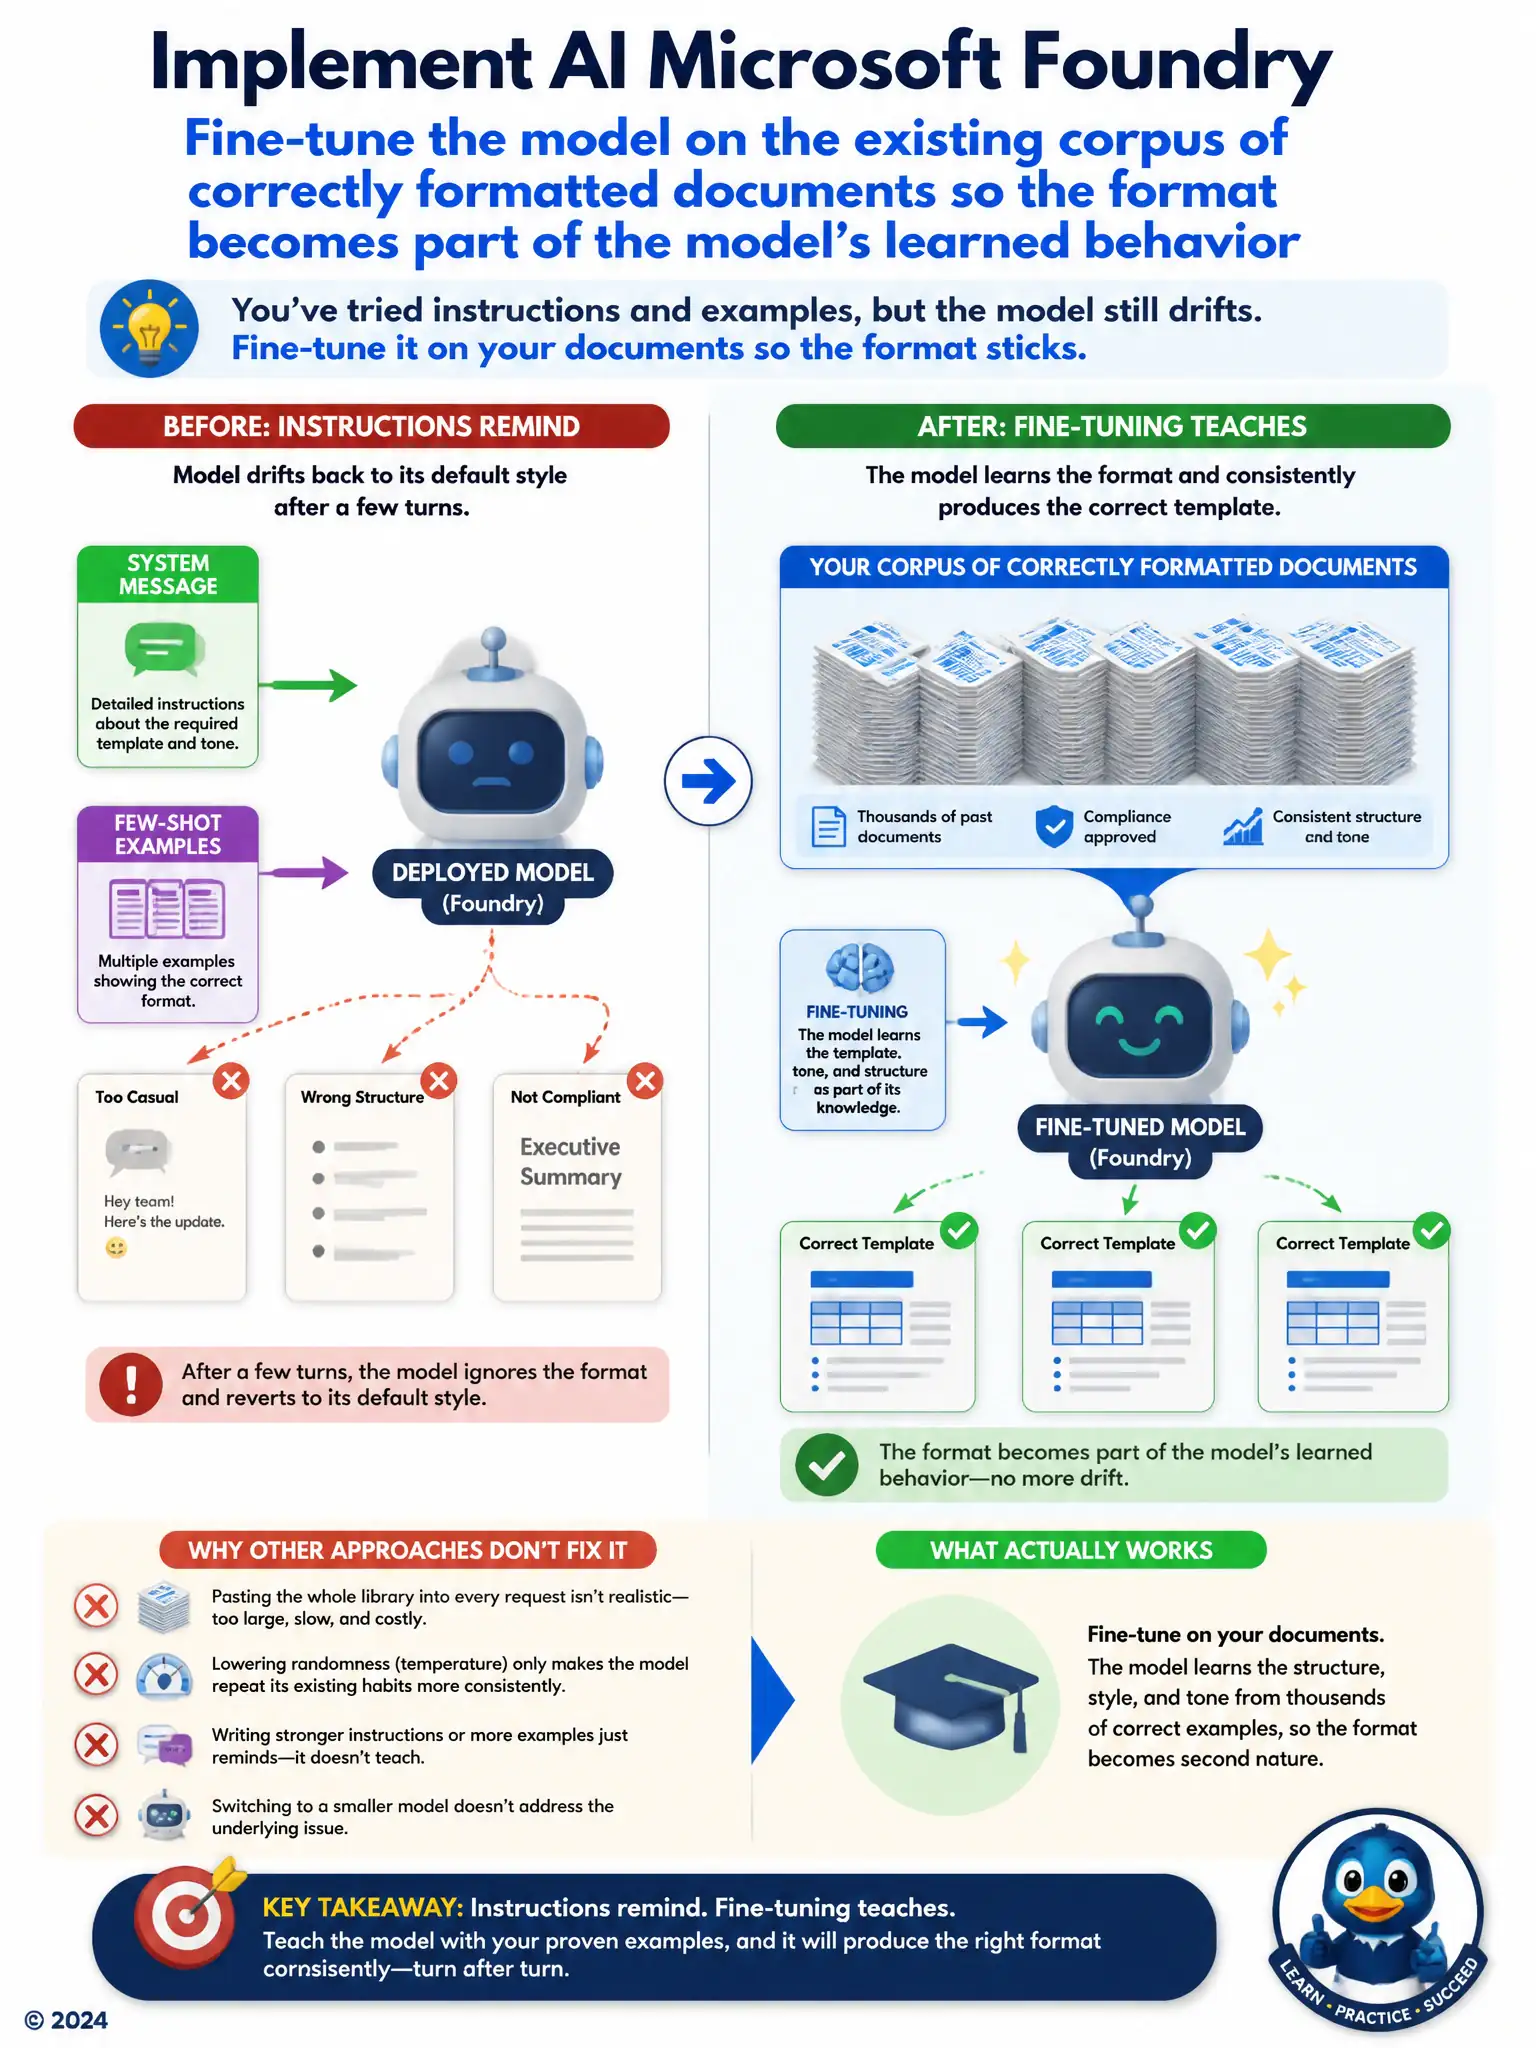
When instructions and examples keep slipping after a few turns, you need to bake the format into the model itself. Fine-tune it on your correctly formatted documents so the compliance template becomes learned behavior. Don't waste time stuffing the whole corpus into prompts, forcing deterministic output, or swapping to a smaller model.
Full Explanation
The correct approach is to fine-tune the model on the existing corpus of correctly formatted documents so the format becomes part of the model's learned behavior. Fine-tuning trains the model's weights on the company's thousands of correctly formatted documents, embedding the required tone and template as learned behavior rather than something reasserted through instructions every turn, which addresses the drift that prompt-based approaches have already failed to fix. Adding the entire document corpus directly into the system message for every request is incorrect because a corpus of thousands of documents will not fit within any model's context window, and even if a subset did fit, repeating it in every request would be prohibitively slow and expensive at scale. Lowering the model's temperature setting to zero for all requests is incorrect because it makes outputs more deterministic and repetitive but does not teach the model the specific compliance format; it can still confidently drift toward its default style, just more consistently. Switching to a smaller, cheaper model from the catalog to reduce drift is incorrect because it does not address the root cause, which is that the model was never trained to prefer this template, and a smaller model is if anything more likely to drift, not less. Fine-tuning is the approach that changes what the model has actually learned, rather than relying on instructions it must be reminded of every time.