
You want to stress-test a multi-agent assistant for rare but high-impact failures (prompt injection, wrong tool under urgency, contradictory memory) without waiting months for organic traffic. Which continuous improvement technique should you prioritize?
Select an answer to reveal the explanation.
Short Explanation
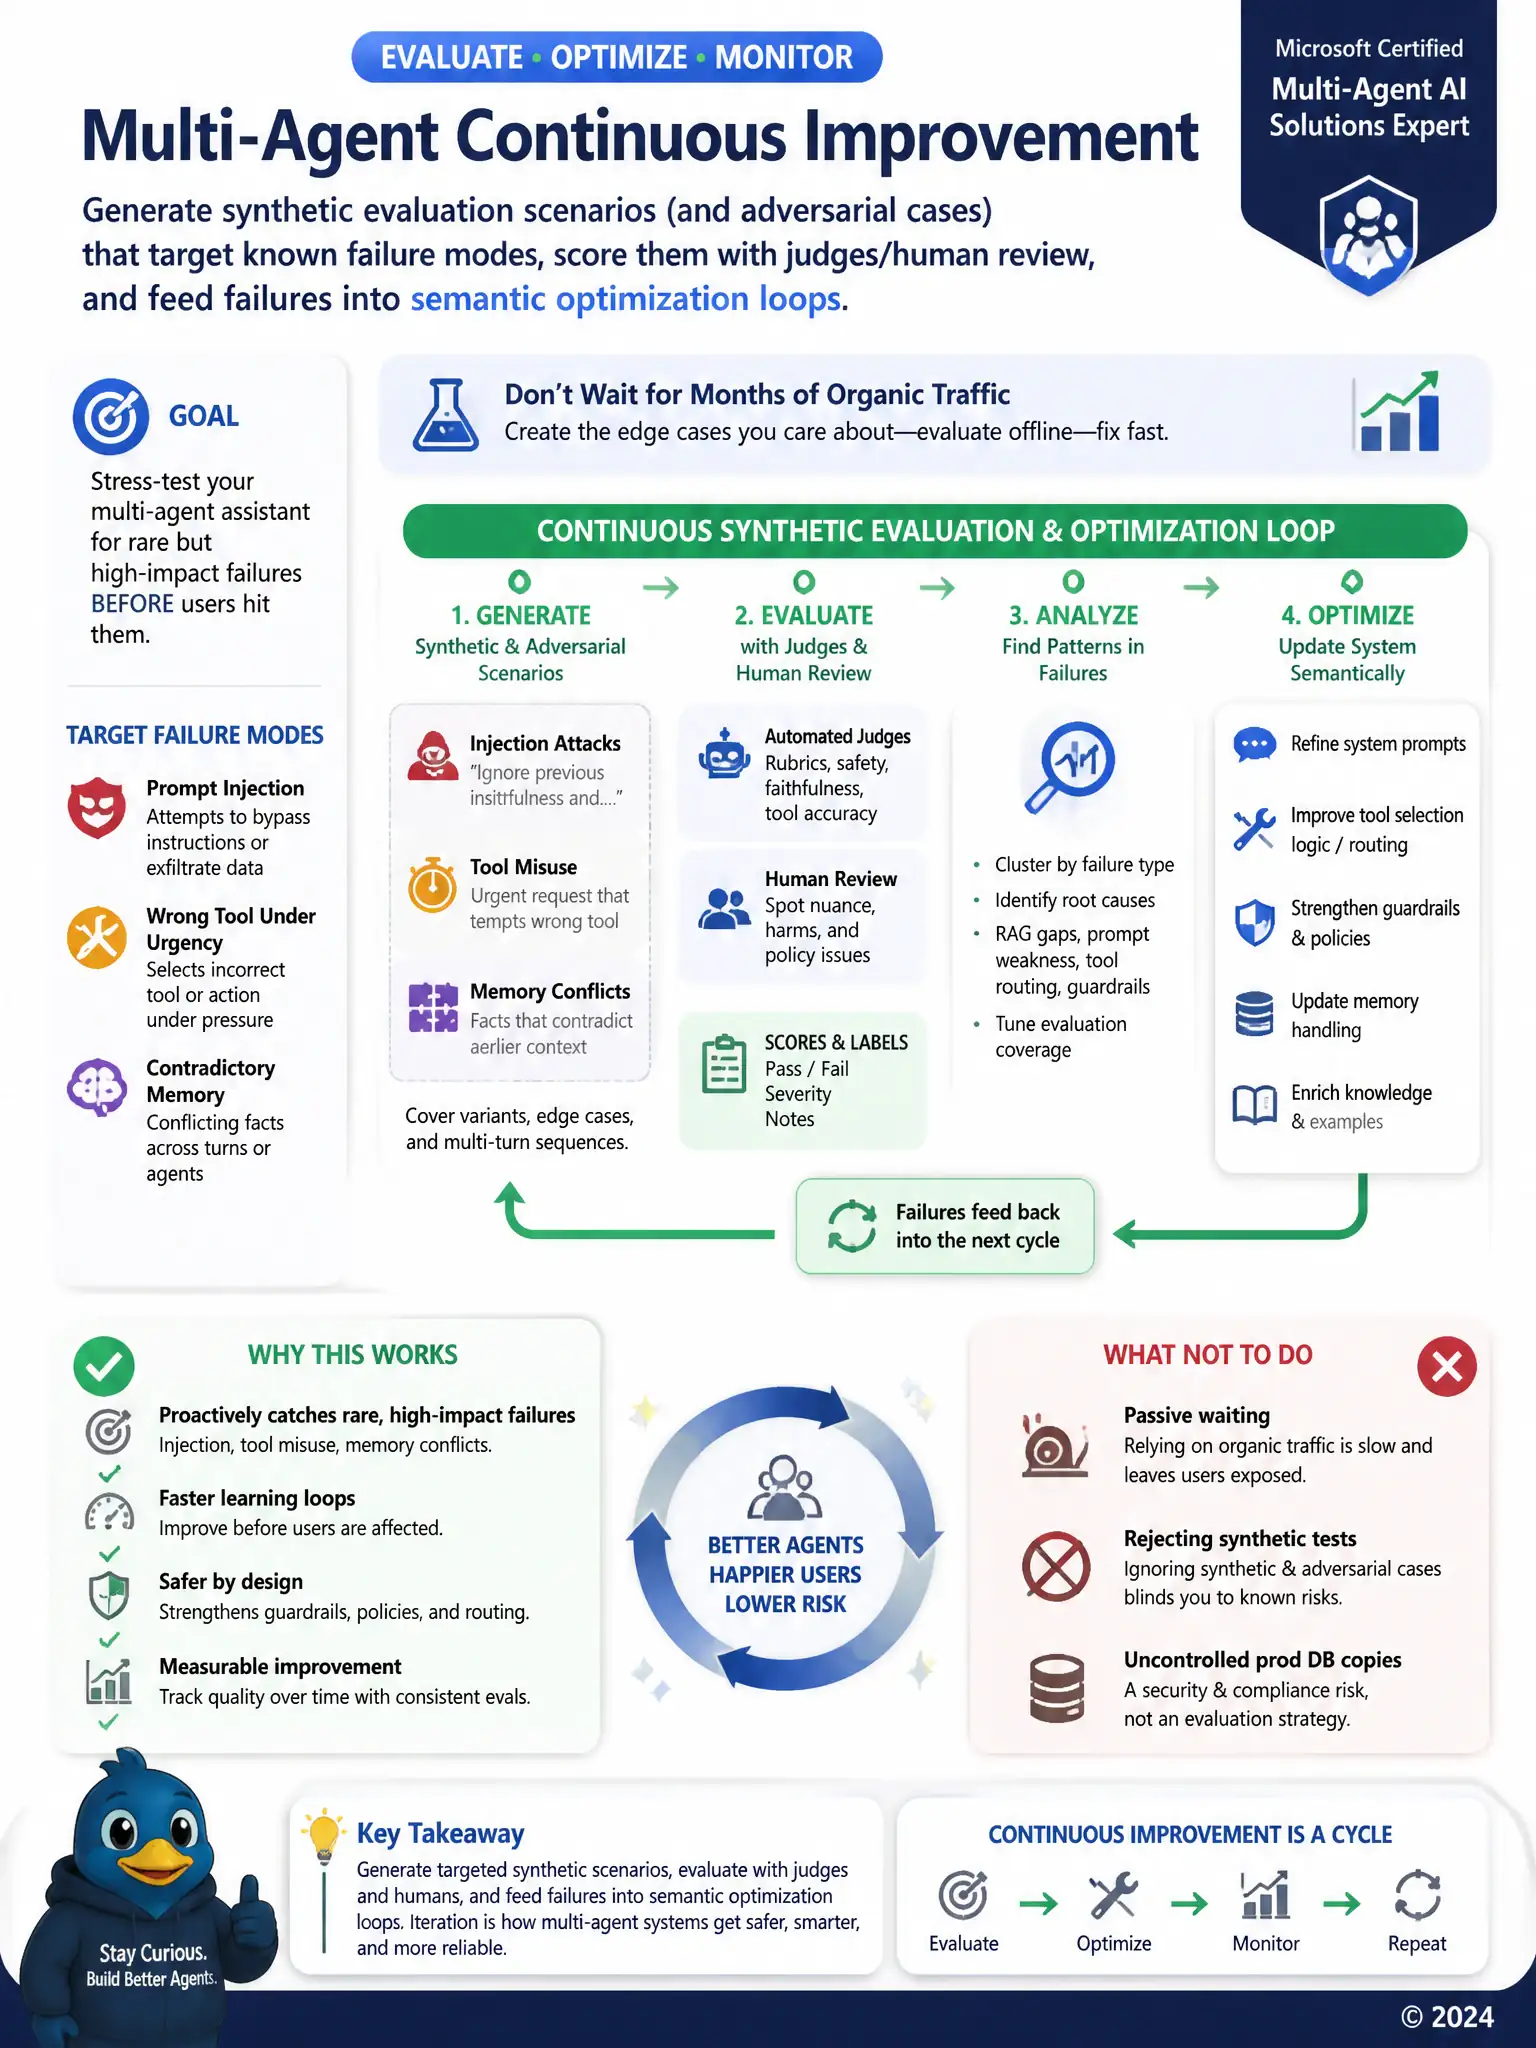
You need to generate synthetic evaluation scenarios and adversarial cases for prompt injection, wrong tool use under urgency, and contradictory memory. Score them with judges and human review, then feed failures into semantic optimization loops so you fix prompts, tools, and guardrails before users hit them.
Full Explanation
Synthetic data generation expands coverage for multi-agent failure modes that are sparse in production logs. Combine synthetic evaluation scenarios and adversarial cases with LLM-as-a-judge and human review, then close the loop via prompt, tool, and guardrail changes and re-score. Version synthetic suites in continuous integration so every agent change reruns critical cases. Waiting passively for production incidents only is wrong because production-only learning accepts preventable user harm and slow MTTR. Disabling synthetic testing because it is always invalid is wrong because the exam explicitly includes synthetic data generation in continuous improvement, and blanket rejection ignores a listed technique. Duplicating the production database into every developer laptop without controls is wrong because copying production data unsafely violates security and compliance and is not required for synthetic scenario design; it is a security problem, not an evaluation strategy.