
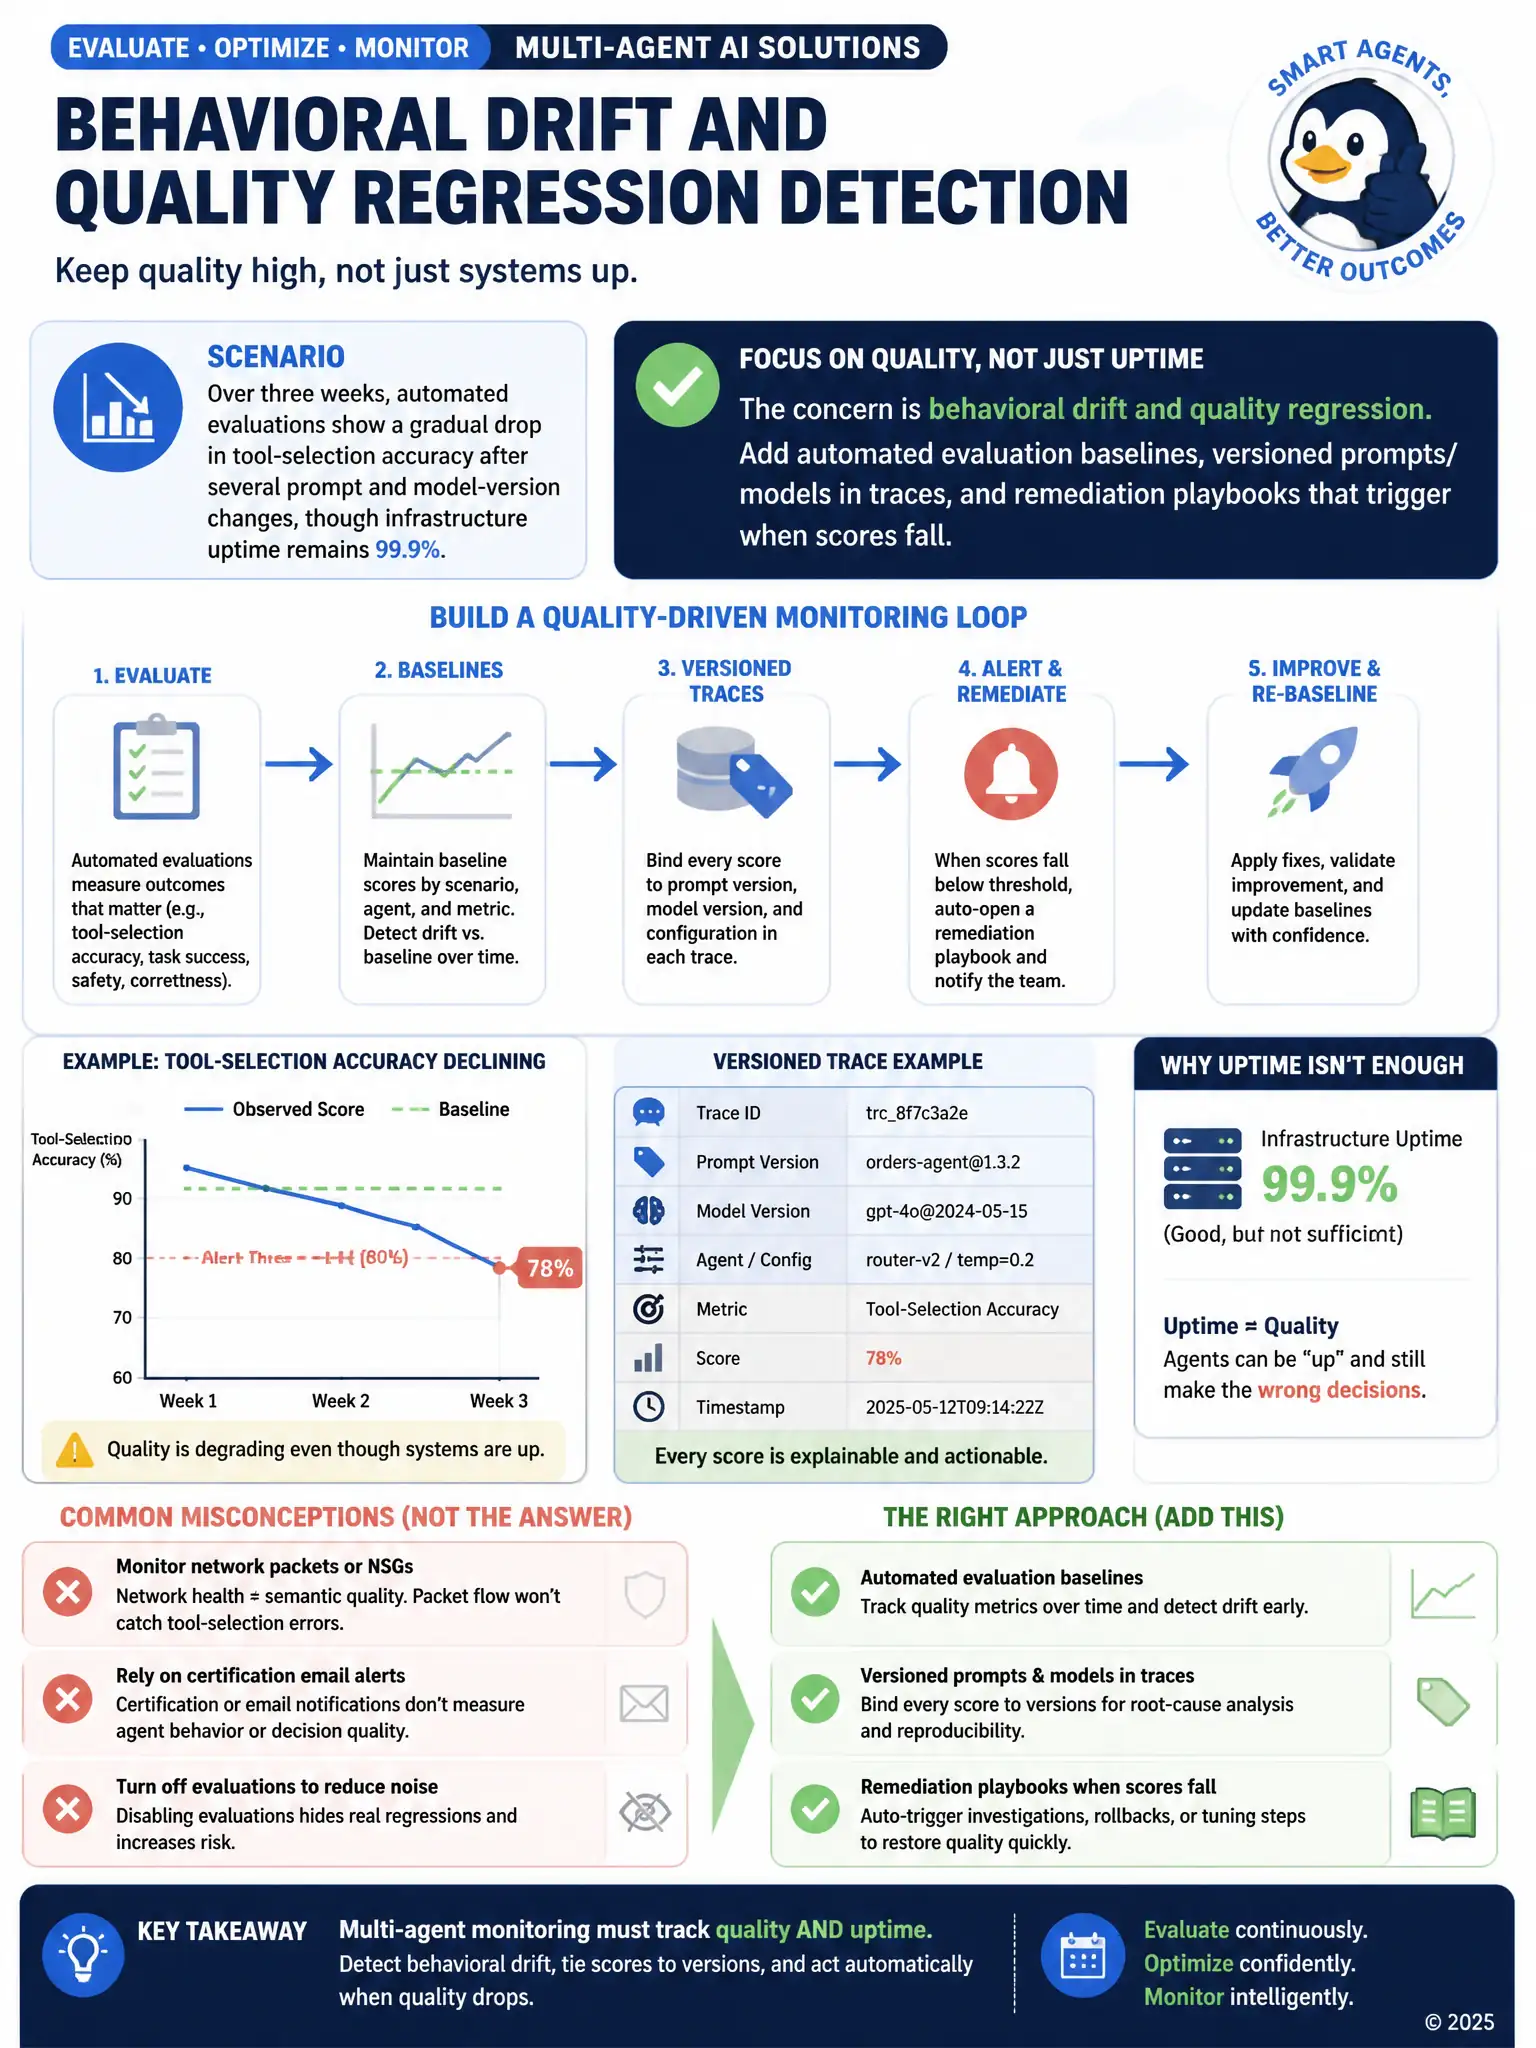
Over three weeks, automated evaluations show a gradual drop in tool-selection accuracy after several prompt and model-version changes, though infrastructure uptime remains 99.9%. Which monitoring concern is this, and what should you add?
Select an answer to reveal the explanation.
Short Explanation
When tool-selection accuracy drops after prompt and model changes, you're dealing with behavioral drift and quality regression, not an infrastructure outage. Keep automated evaluation baselines, tie scores to versioned prompts and models in traces, and trigger remediation playbooks when scores fall.
Full Explanation
The monitoring concern is behavioral drift and quality regression detection, and you should add automated evaluation baselines, versioned prompts and models in traces, and remediation playbooks when scores fall. Skills include monitoring components for cross-agent coordination, behavioral drift, quality regression detection, and automated remediation for failure patterns. Uptime SLAs can be green while agent behavior silently degrades after prompt or model churn. Network packet loss monitors on NSGs are wrong because network monitors do not measure tool-choice quality. Certificate expiry emails are wrong because certificate operations are necessary but orthogonal to agent behavioral drift. Disabling evaluations to stabilize scores is wrong because evaluations are how you detect drift; disabling them removes the signal. Implement continuous eval jobs, compare against golden sets, and gate or roll back model or prompt versions on regression.