
Incidents in production show incomplete explanations: Azure Monitor has some dependency logs, but engineers cannot reconstruct which orchestrator decision led which subagent to call which tool for a single user session. What observability design is required?
Select an answer to reveal the explanation.
Short Explanation
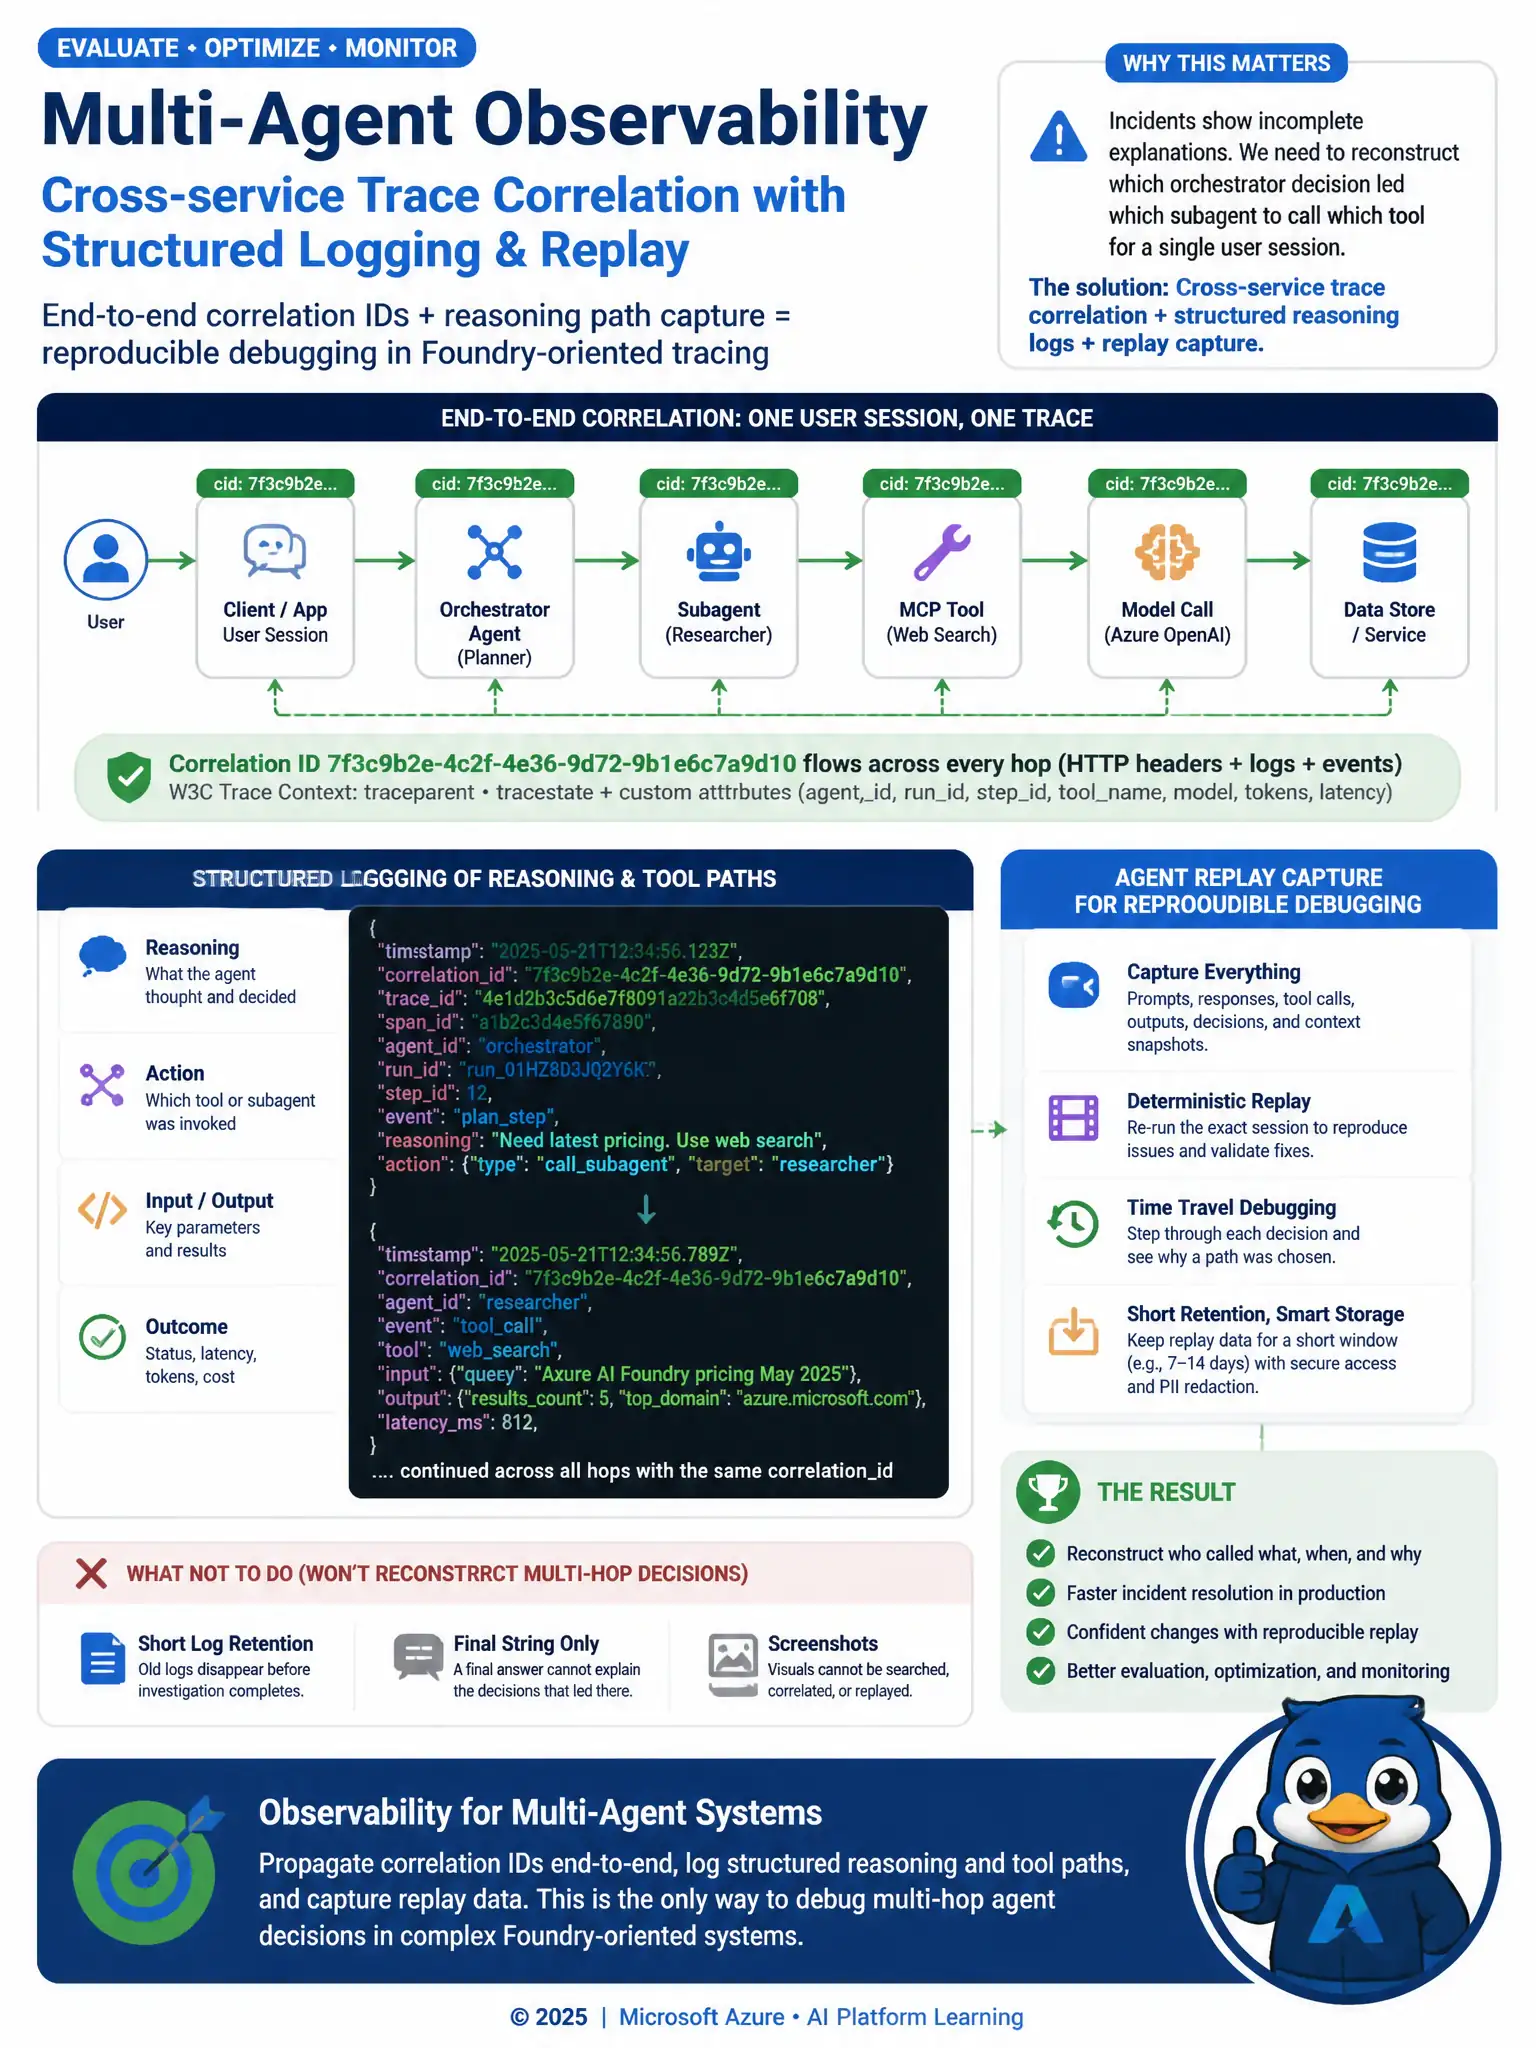
You need cross-service trace correlation with structured logging of agent reasoning paths, end-to-end correlation IDs, and agent replay capture. That lets you reconstruct which orchestrator decision led which subagent to call which tool for a single user session. Deleting logs, logging only final strings, or relying on screenshots won't give you that trace.
Full Explanation
The cross-service trace correlation option with structured logging of agent reasoning paths, end-to-end correlation IDs, and agent replay capture for reproducible debugging in Foundry-oriented tracing is correct because observability for multi-agent systems must be designed for reliability: agent health, workflow failures, trace correlation, and remediation. Foundry tracing should cover tokens, prompts, correlation IDs, alerting, and execution tracking. Without distributed correlation, multi-agent graphs are undebuggable. Also emit metrics for workflow failure rates and quality regression detectors tied to the same correlation model. The five-minute log deletion option is wrong because it destroys forensic and quality analysis value. The final-user-visible-strings-only logging option is wrong because user-visible text lacks tool inputs/outputs, model versions, and routing decisions. The manual chat UI screenshot option is wrong because screenshots do not scale and miss backend tool chains.