
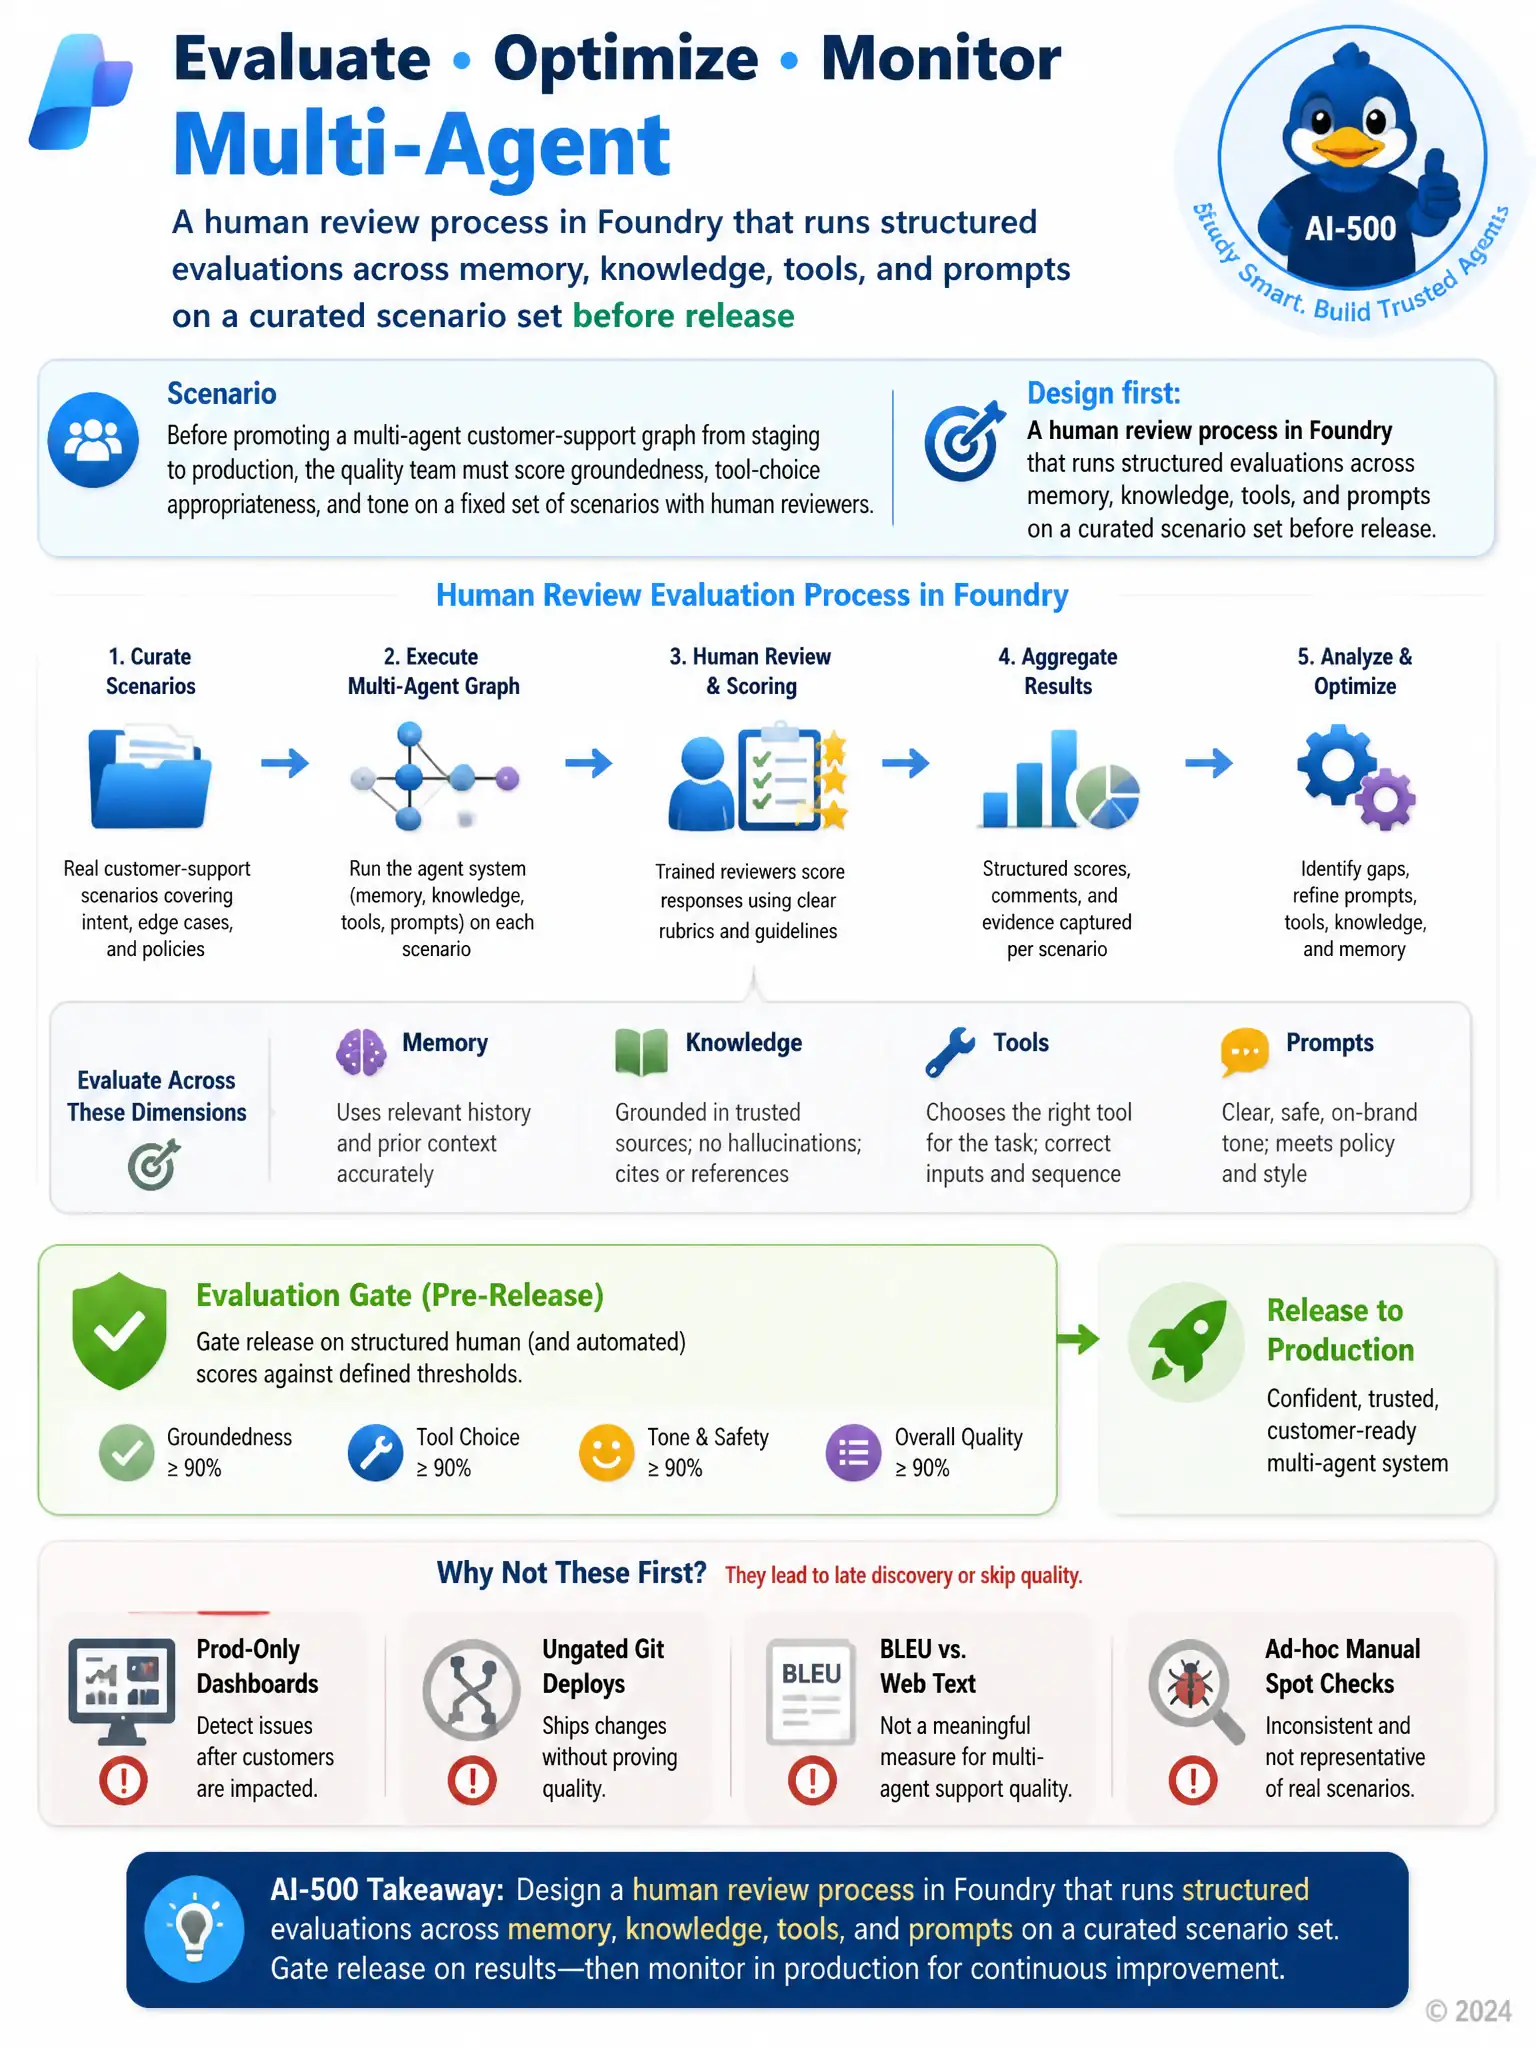
Before promoting a multi-agent customer-support graph from staging to production in Microsoft Foundry, the quality team must score groundedness, tool-choice appropriateness, and tone on a fixed set of scenarios with human reviewers. What should you design first?
Select an answer to reveal the explanation.
Short Explanation
You need human review in Foundry that runs structured evaluations across memory, knowledge, tools, and prompts on curated scenarios before release. That lets you score groundedness, tool-choice appropriateness, and tone on real support scenarios before production. Monitoring-only dashboards, ungated git promotions, and BLEU scores against random web text don't provide needed pre-release quality gates.
Full Explanation
Design and implement evaluation and validation strategies: human review in Foundry plus targeted evaluations of memory, knowledge, tools, and prompts. Curate scenarios that exercise retrieval quality, correct tool selection, safe refusals, and multi-agent handoffs; capture reviewer scores and block promotion on thresholds. Combine human review with LLM-as-judge and regression suites for scale.
The production-only monitoring dashboard with no pre-release review is insufficient alone: monitoring is necessary after release but does not replace pre-production evaluation gates.
Automatic promotion on every git commit with zero evaluation gates is incorrect: continuous delivery still needs automated and human evaluation gates for agent quality and safety.
Sole reliance on BLEU scores against random web text is incorrect: classical n-gram metrics on unrelated corpora do not measure groundedness or tool appropriateness for support agents.