
A travel multi-agent flow depends on a primary fares API tool. When that API returns 503 or times out, the booking agent currently crashes the whole workflow. The business wants degraded service: try a secondary fares provider, then offer human handoff if both fail, while logging failures for ops. Which design best implements this?
Select an answer to reveal the explanation.
Short Explanation
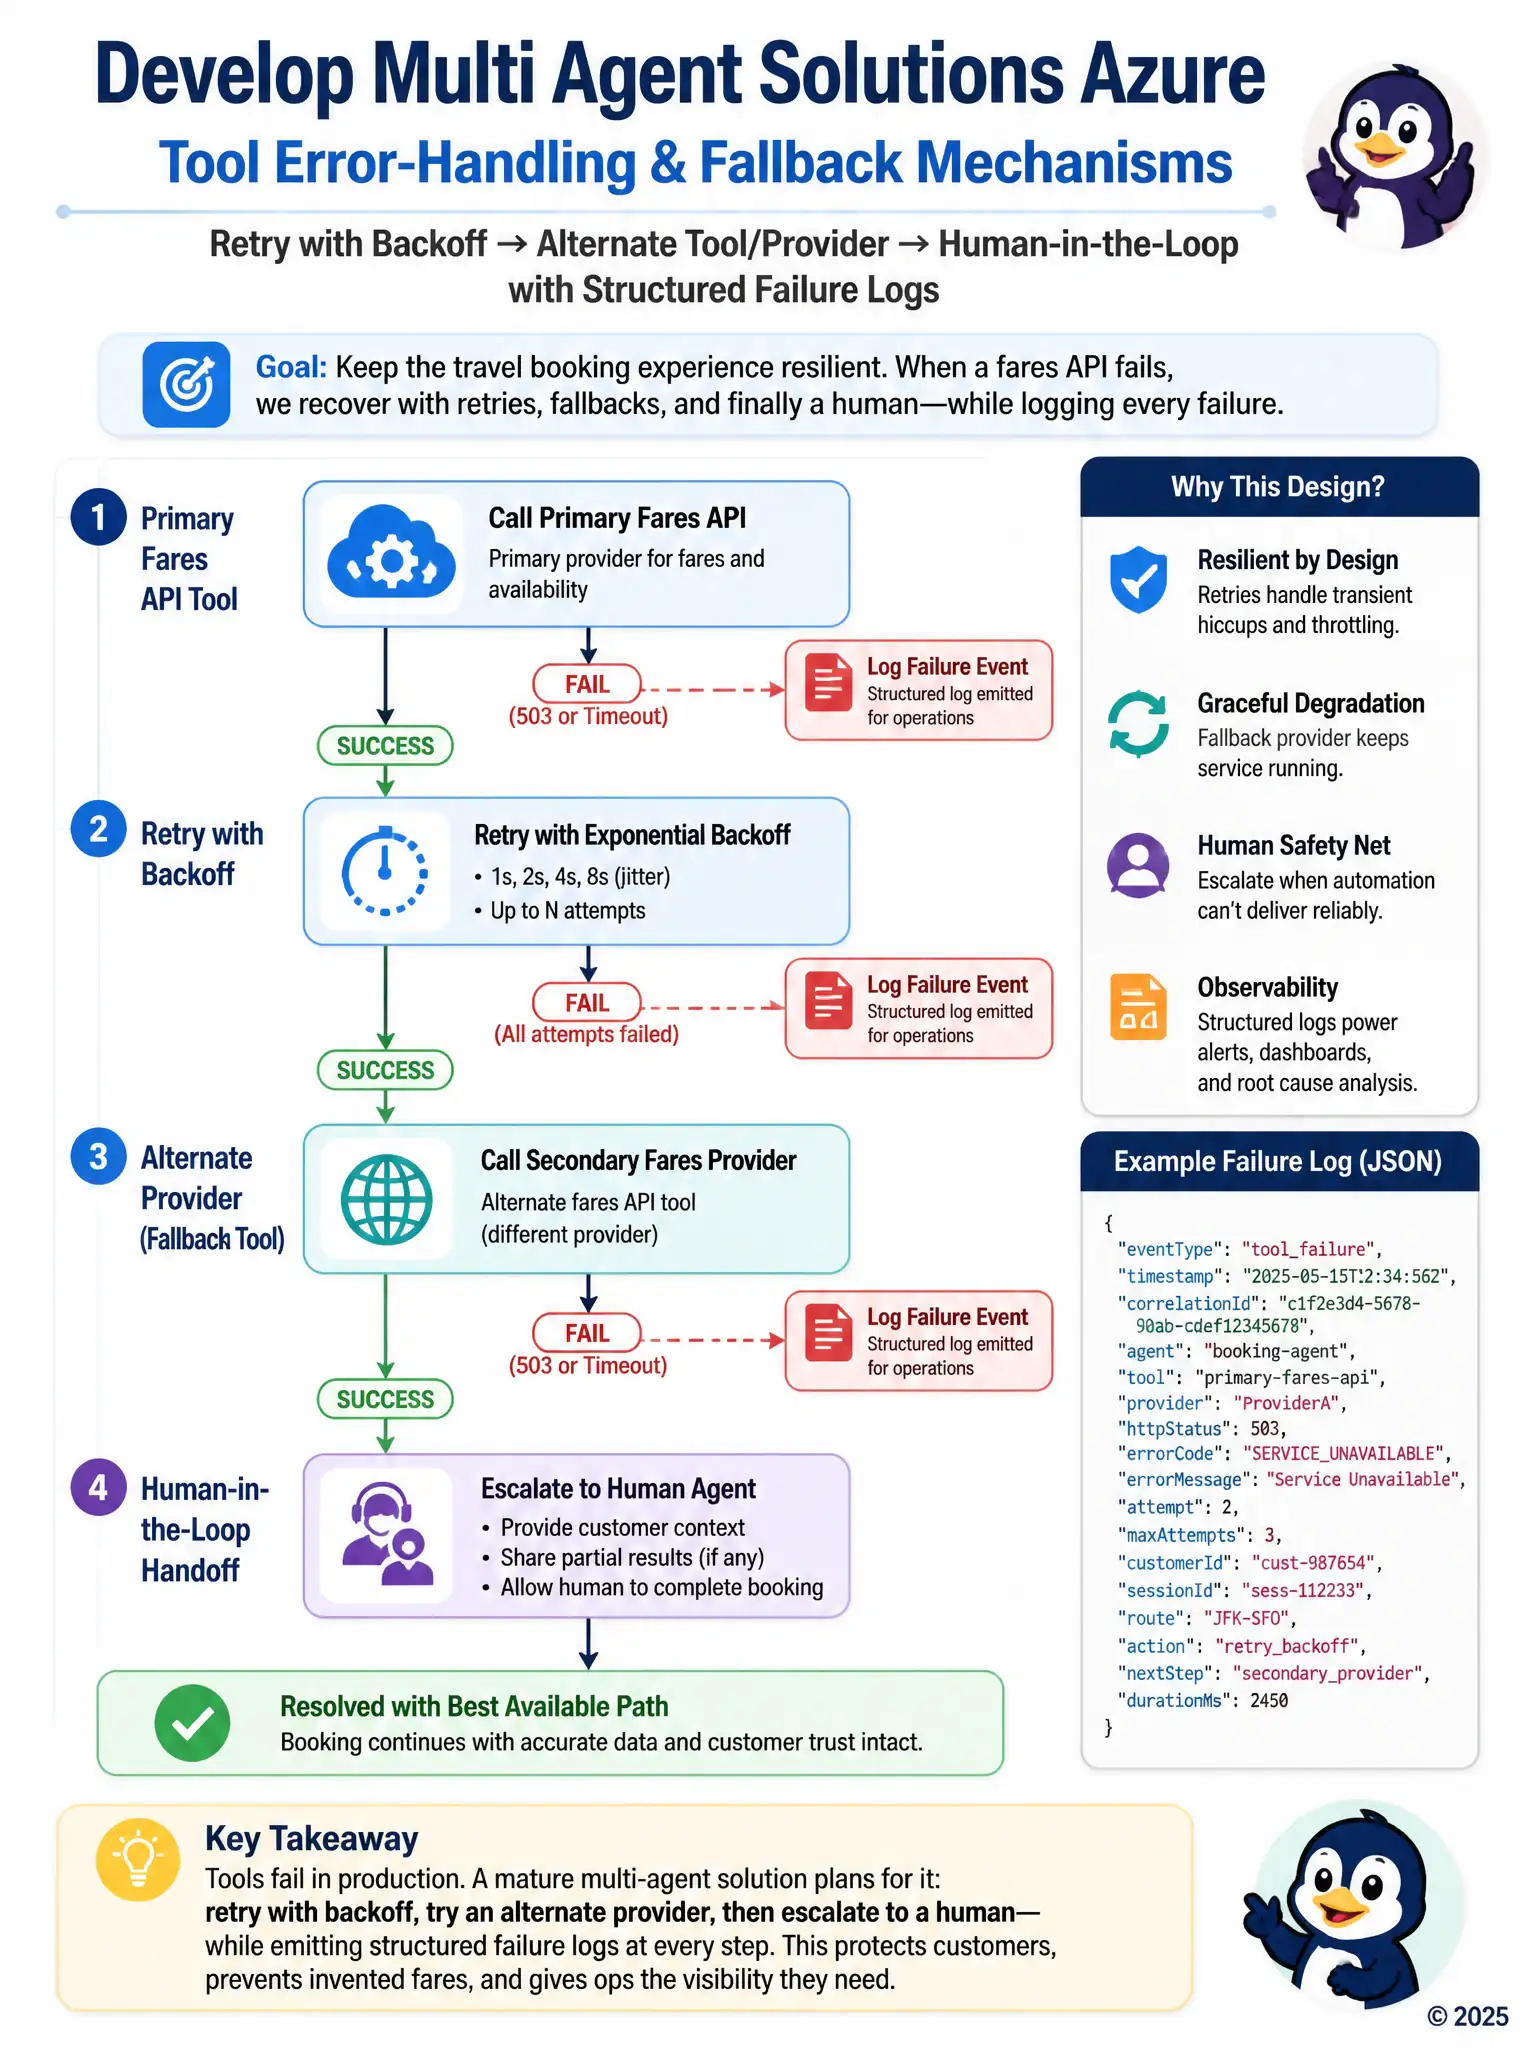
Tools fail in production, so you need a real fallback plan. You should retry with backoff, try an alternate fares provider, then hand off to a human with structured failure logs. Fabricating fares or nuking the agent isn't resilience.
Full Explanation
The correct design is tool error-handling and fallback mechanisms: retry with backoff, use an alternate fares provider, then escalate to human-in-the-loop with structured failure logs. Mature tool ecosystems plan for production failures with timed retries, alternate providers, graceful degradation, and observability. Fabricating fares is wrong because it creates incorrect bookings and compliance risk. Deleting the booking agent on any tool failure is wrong because it is not a controlled fallback strategy. Increasing only UI animation speed is wrong because it does not change backend resilience. Exam focus: tool failures need explicit multi-step fallback, not silent invention or hard crashes.