
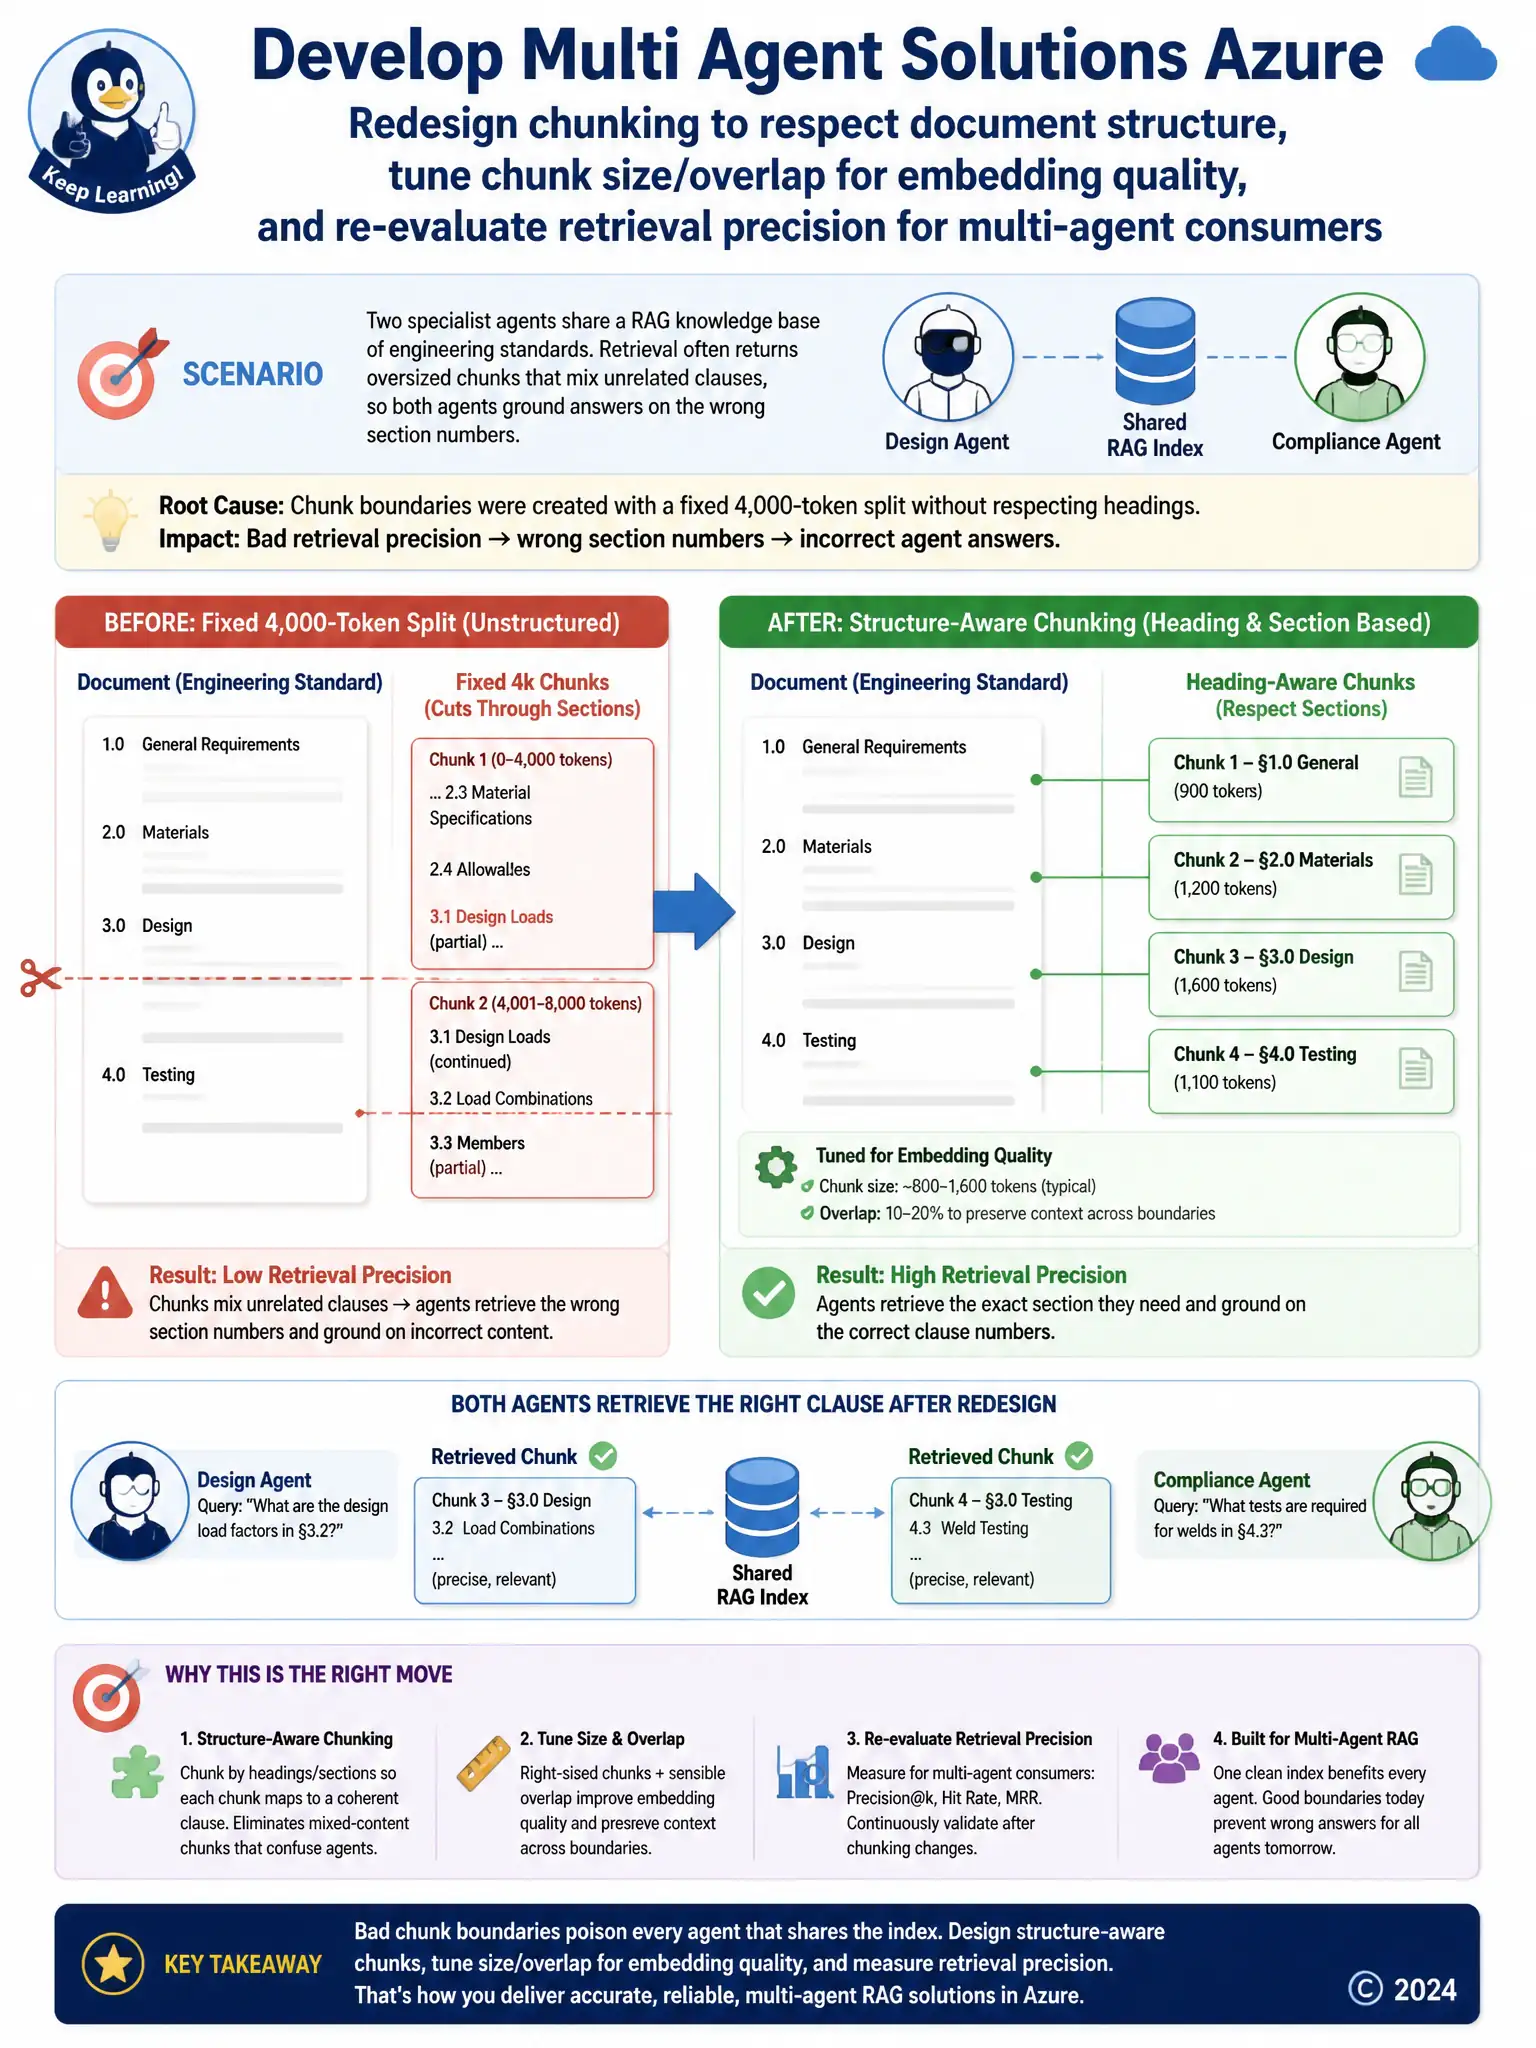
Two specialist agents share a RAG knowledge base of engineering standards. Retrieval often returns oversized chunks that mix unrelated clauses, so both agents ground answers on the wrong section numbers. Embedding quality is acceptable on short texts, but chunk boundaries were created with a fixed 4,000-token split without respecting headings. What should the team prioritize to improve multi-agent RAG precision?
Select an answer to reveal the explanation.
Short Explanation
Bad chunk boundaries poison every agent that shares the index. You need structure-aware chunking, sensible size and overlap, and retrieval precision checks for multi-agent consumers. Full-corpus fine-tuning, whole-document chunks, and random shuffling won't fix the grounding problem.
Full Explanation
Redesign chunking to respect document structure, tune chunk size and overlap for embedding quality, and re-evaluate retrieval precision for multi-agent consumers. Multi-agent RAG architecture design includes chunking, embedding quality, and retrieval precision. Structure-aware segmentation improves the signal specialists receive when multiple agents consume the same knowledge base.
Disabling retrieval and fine-tuning both agents solely on the entire standards corpus is not a first-line fix because exclusive fine-tuning is costly, slow to update, and does not replace retrieval architecture for evolving document sets.
Increasing chunk size to the full document so each retrieval returns an entire manual is incorrect because whole-document retrieval reduces precision and overwhelms context windows.
Randomly shuffling chunk order in the index to increase answer diversity is incorrect because shuffling chunks harms consistent retrieval of the correct clause.
Exam focus: shared multi-agent knowledge quality starts with chunking and retrieval precision, not randomness.