
A multi-agent claims team needs continuous quality scoring on thousands of nightly agent runs. Human review can cover only a small sample. They want automated semantic scoring of final answers against policies, with periodic human calibration, feeding a semantic optimization loop. Which approach best fits Foundry-oriented continuous improvement?
Select an answer to reveal the explanation.
Short Explanation
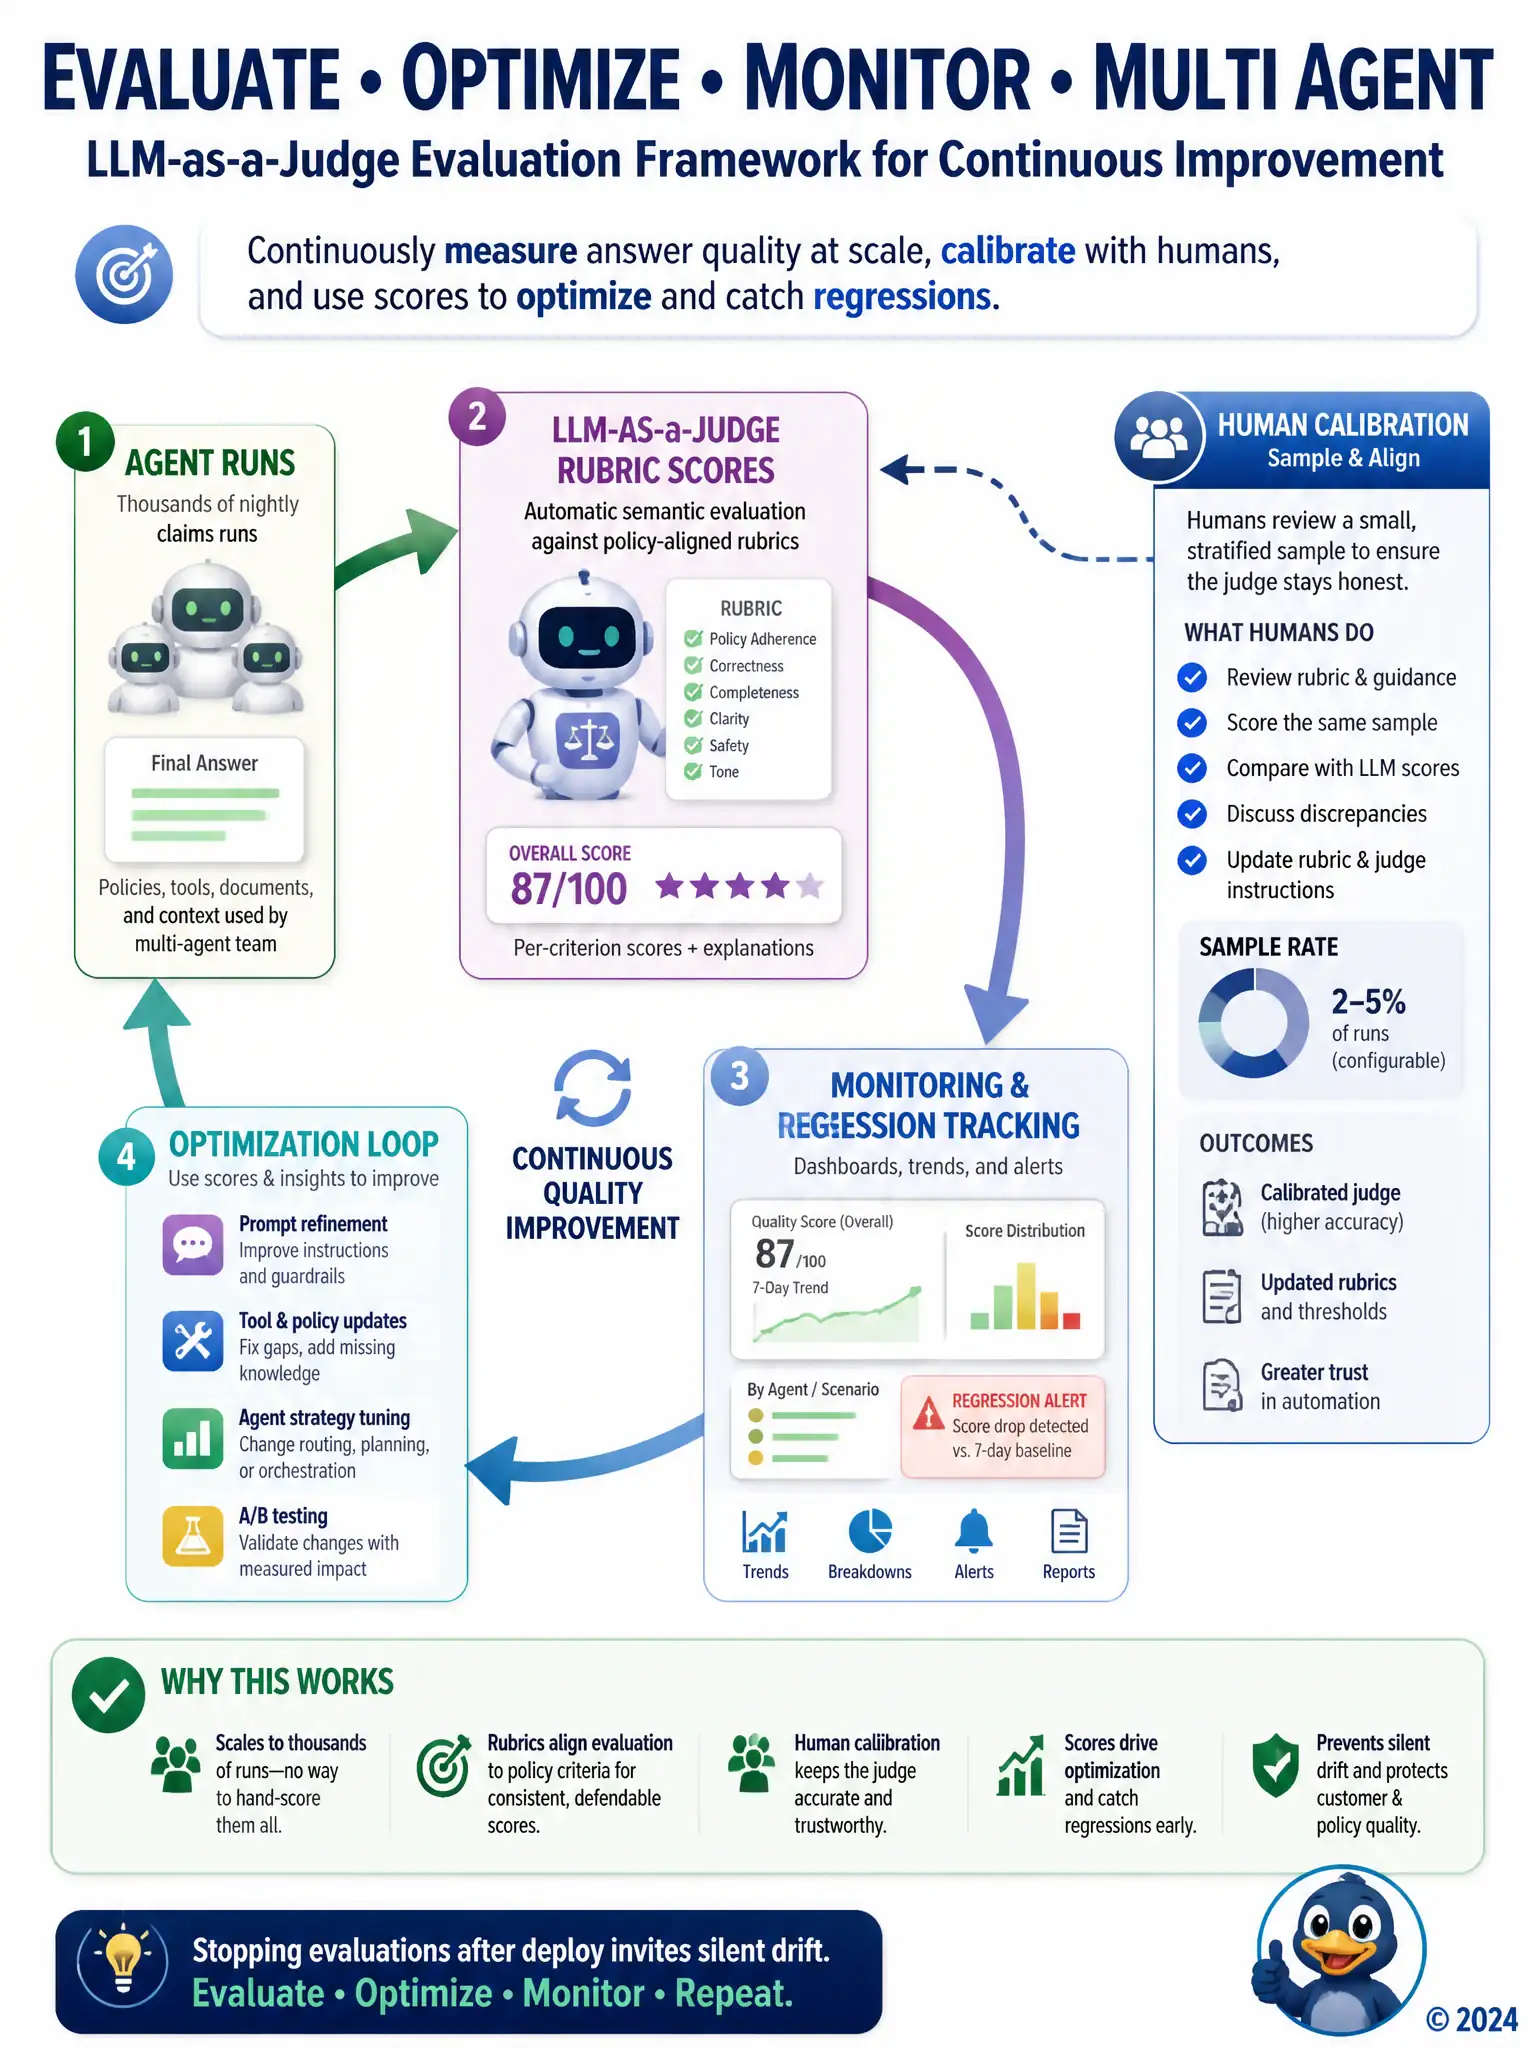
You cannot hand-score thousands of runs nightly. Use an LLM-as-a-judge evaluation framework with policy-aligned rubrics, sample human calibration, and scores feeding optimization and regression tracking. Character counting, stopping evaluations, and CPU heat miss semantic answer quality.
Full Explanation
The correct approach is an LLM-as-a-judge evaluation framework with policy-aligned rubrics, sample human calibration, and scores fed into optimization and regression tracking. Foundry-oriented continuous improvement includes LLM-as-a-judge frameworks, synthetic data generation, semantic optimization loops, and user feedback loops. Automated judges enable scale; human calibration maintains alignment; scores drive prompt, tool, and model optimization and quality regression monitoring. Exam focus: LLM-as-judge is a core continuous evaluation technique when human review cannot cover full volume. The character-count approach that rewards longer responses is incorrect because length is a poor proxy for policy-correct claims answers. The approach that disables all evaluations after the first production deploy is incorrect because production multi-agent systems require ongoing evaluation for drift and regression. The approach that uses only CPU temperature of the host VM as a proxy for answer quality is incorrect because infrastructure telemetry is not a semantic quality metric for agent answers.