
An orchestrator dynamically spawns specialist subagents for each line item in large orders. During a peak sale, a single request spawned hundreds of concurrent agents, exhausted rate limits on the model deployment, and caused cascading timeouts for other customers. Which control should the team implement?
Select an answer to reveal the explanation.
Short Explanation
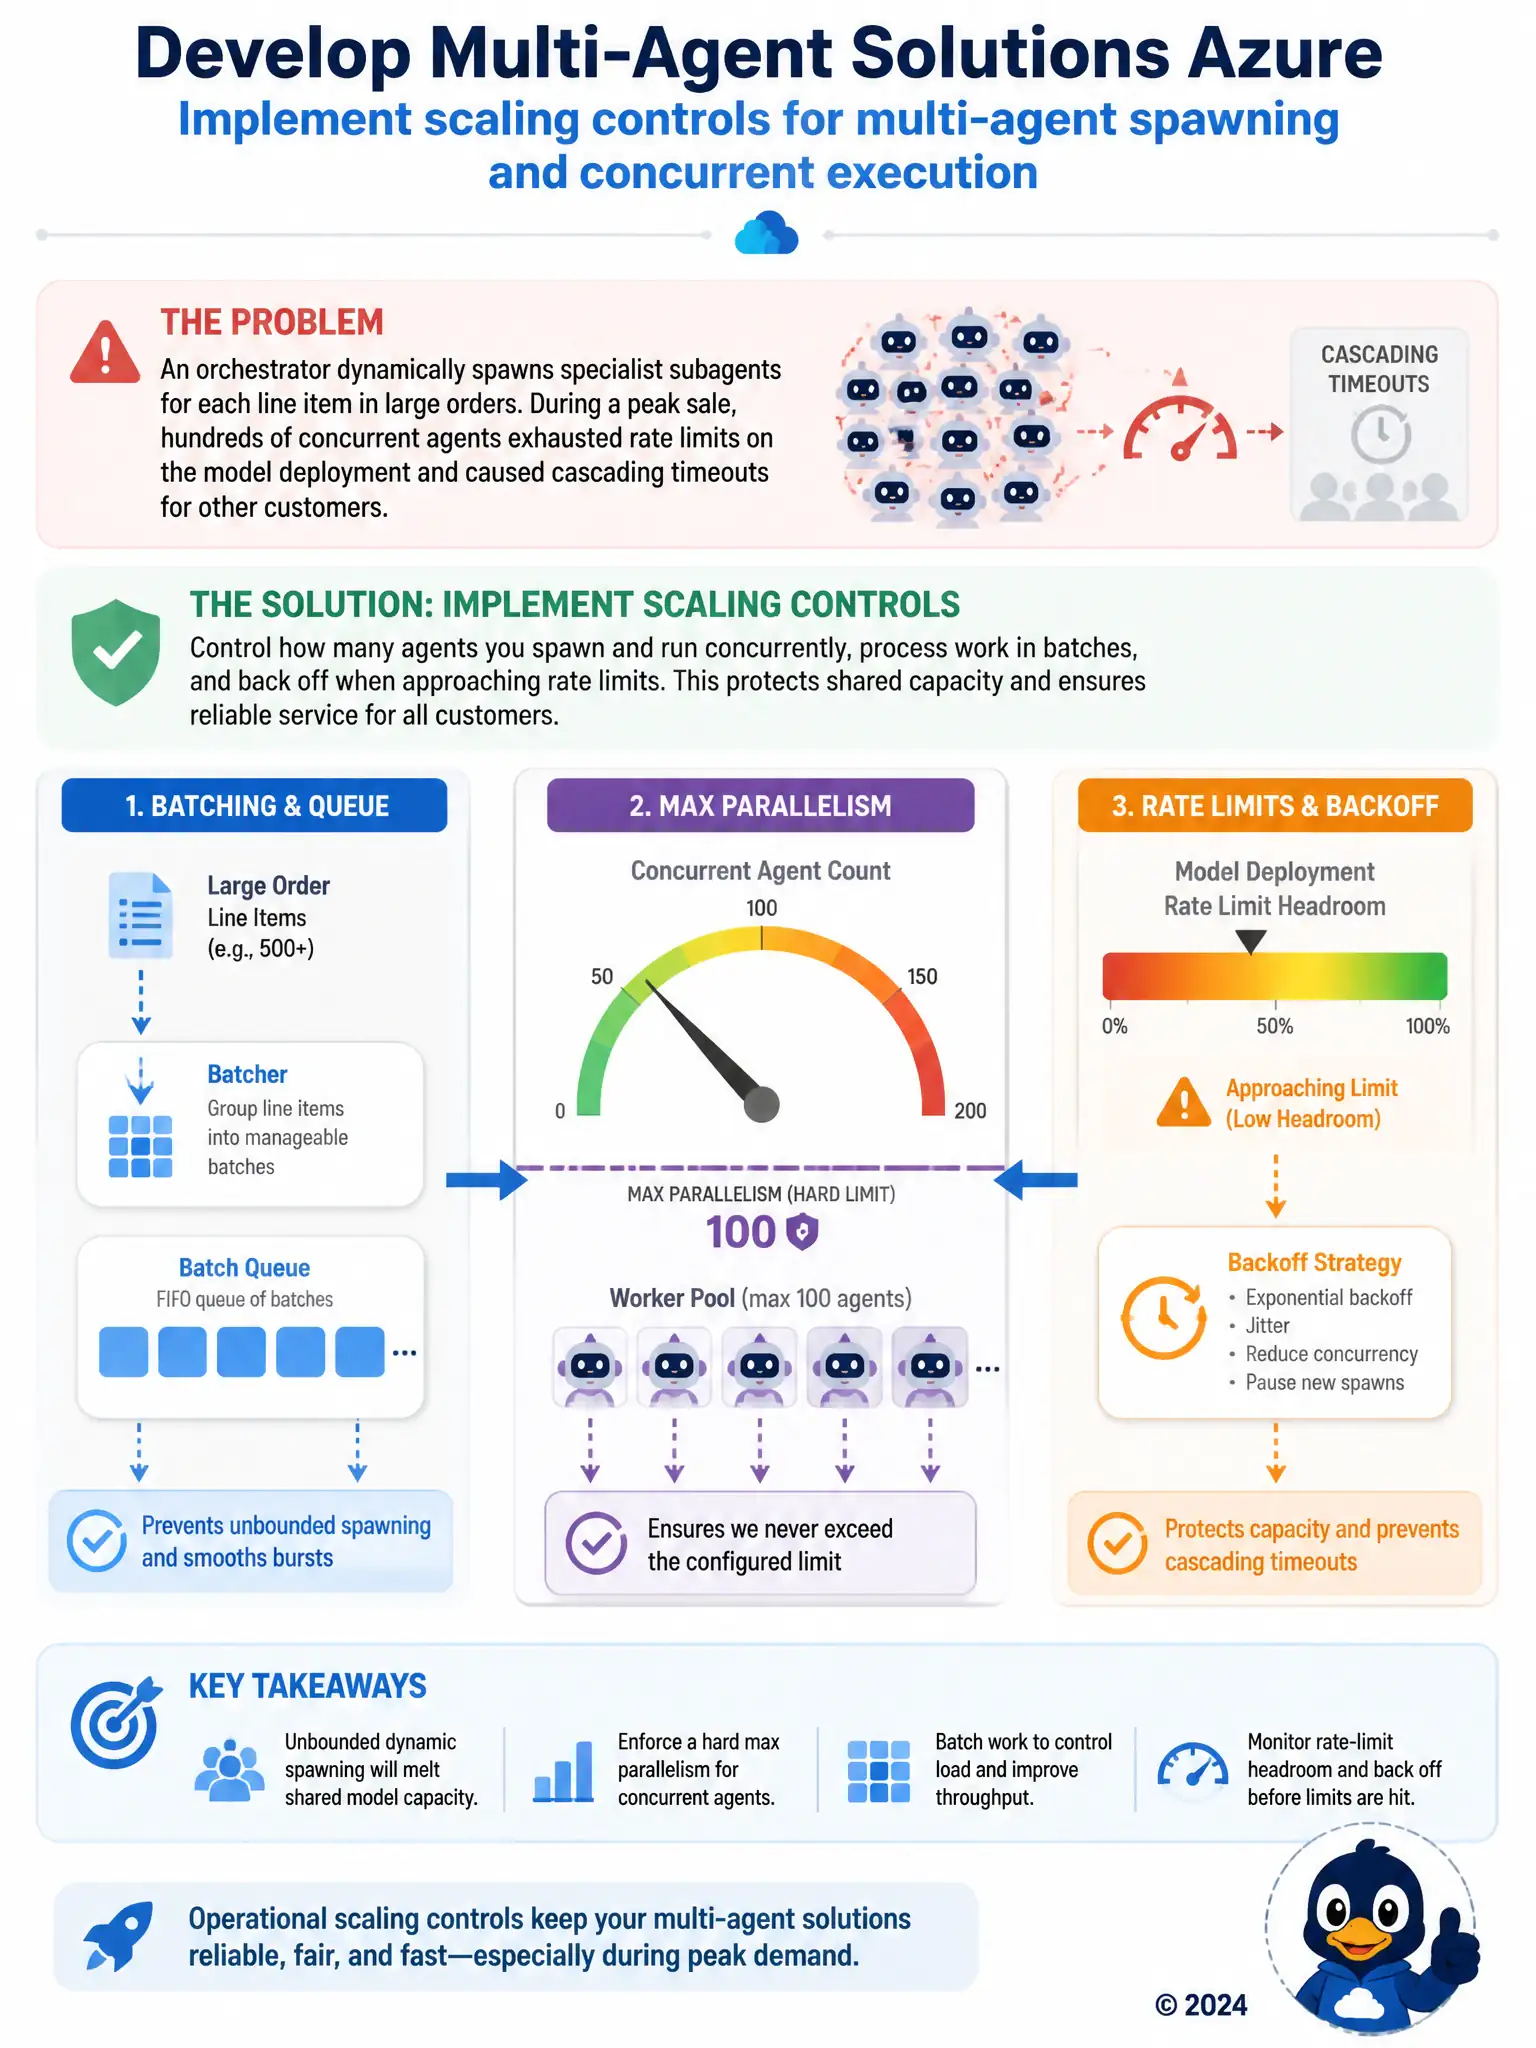
Dynamic spawning without caps will melt shared model capacity. You need explicit concurrency controls: max parallel agents, batching line items, and backoff when rate limits approach. Unbounded spawn recreates the outage, laptop execution isn't a production multi-tenant fix, and a non-completing loop isn't control.
Full Explanation
The correct control is implementing scaling controls for multi-agent spawning and concurrent execution, including batching, max parallelism, and backoff when approaching rate limits. Multi-agent orchestration needs scaling and control of spawning, batching, and concurrent execution so peak demand does not exhaust model rate limits or starve other workloads. Removing all concurrency limits and spawning unbounded agents is wrong because unbounded parallelism caused the failure. Spawning agents only on developer laptops outside Azure is wrong because local machines are not a scalable, governed production control plane. Replacing the orchestrator with a single-threaded infinite loop that never completes batches is wrong because it provides no controlled concurrency or reliable throughput. Exam focus: pair agent spawning with batching, caps, and rate-limit-aware backoff.