
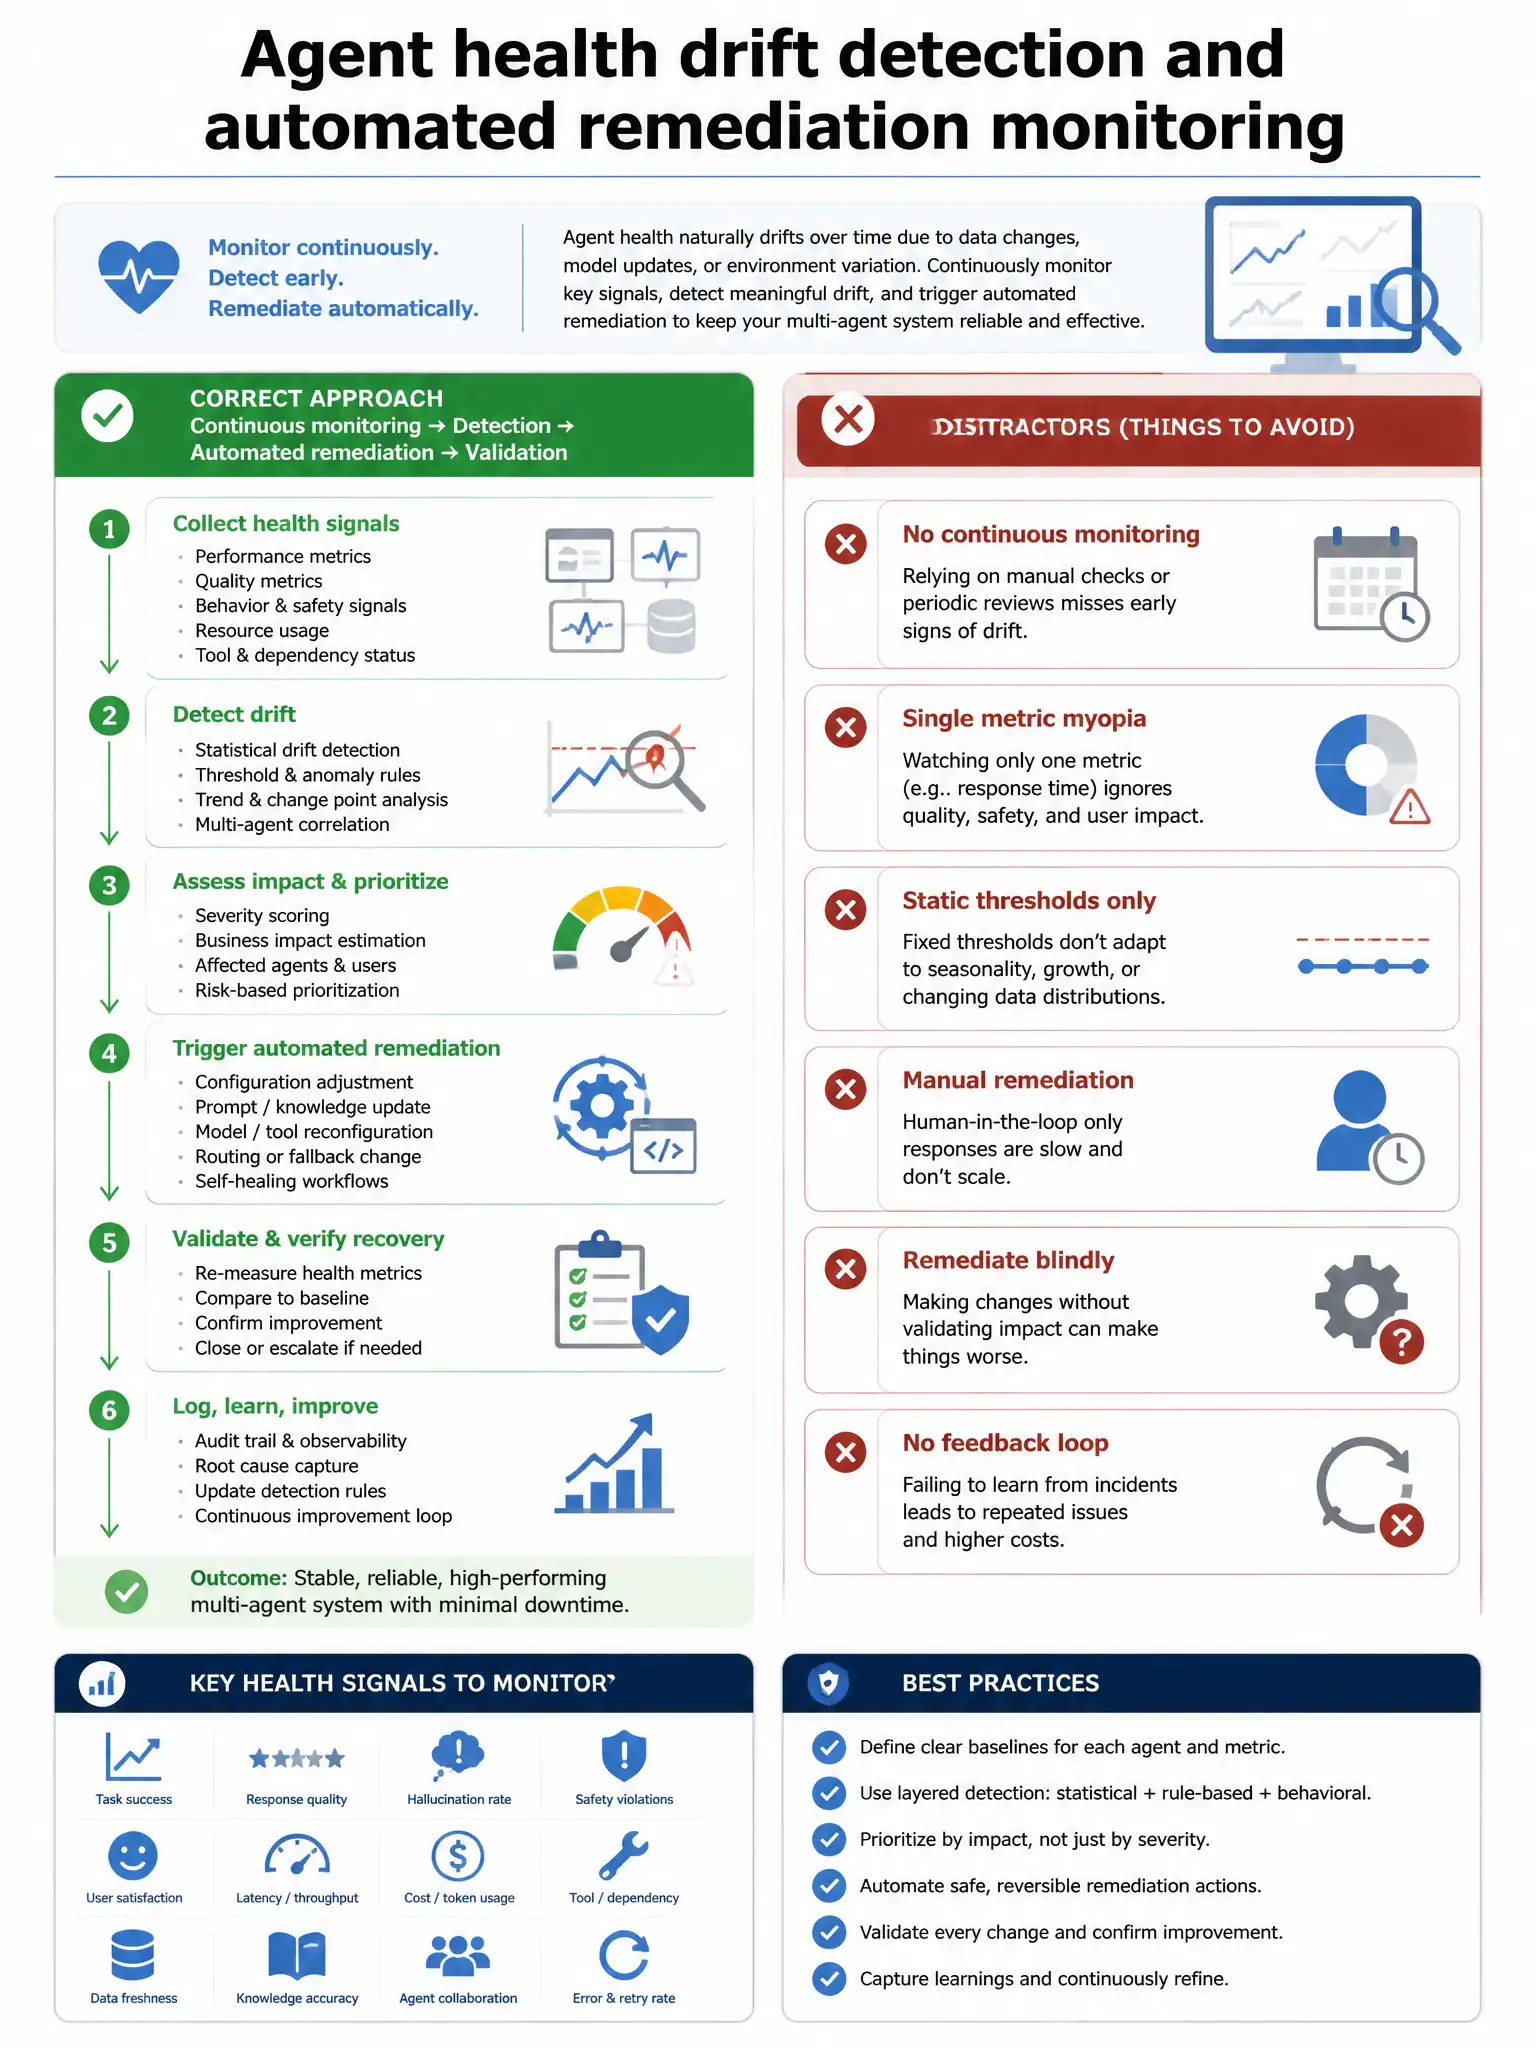
Operations needs a reliability strategy for multi-agent production: detect unhealthy agents, workflow failures, quality regressions, and behavioral drift, then trigger remediation. What should you design?
Select an answer to reveal the explanation.
Short Explanation
The right design is straight from the monitoring skills: agent health, workflow failures, trace correlation, drift detection, quality regression, and remediation. Don't stop at disk space—build metrics and traces that catch coordination failures and quality drops, then automate safe remediation where patterns are known.
Full Explanation
Correct answer — the comprehensive monitoring and remediation design
Reliability monitoring for multi-agent solutions covers agent health, workflow failures, trace correlation, behavioral drift, quality regression, and automated remediation for known failure patterns.
Why the disk-space-only design is wrong: Infrastructure disk metrics alone miss agent cognitive and workflow failures.
Why the log-nothing design is wrong: Absence of logs prevents detection and forensics.
Why the page-after-customer-cancel design is wrong: Customer churn is a lagging, unacceptable primary signal.
Exam tip: Drift + regression + remediation is the reliability triad on AI-500.