
You need continuous improvement for a multi-agent support solution: scalable scoring of free-text answers, periodic synthetic hard cases, and incorporation of user thumbs-down. Which approach best fits?
Select an answer to reveal the explanation.
Short Explanation
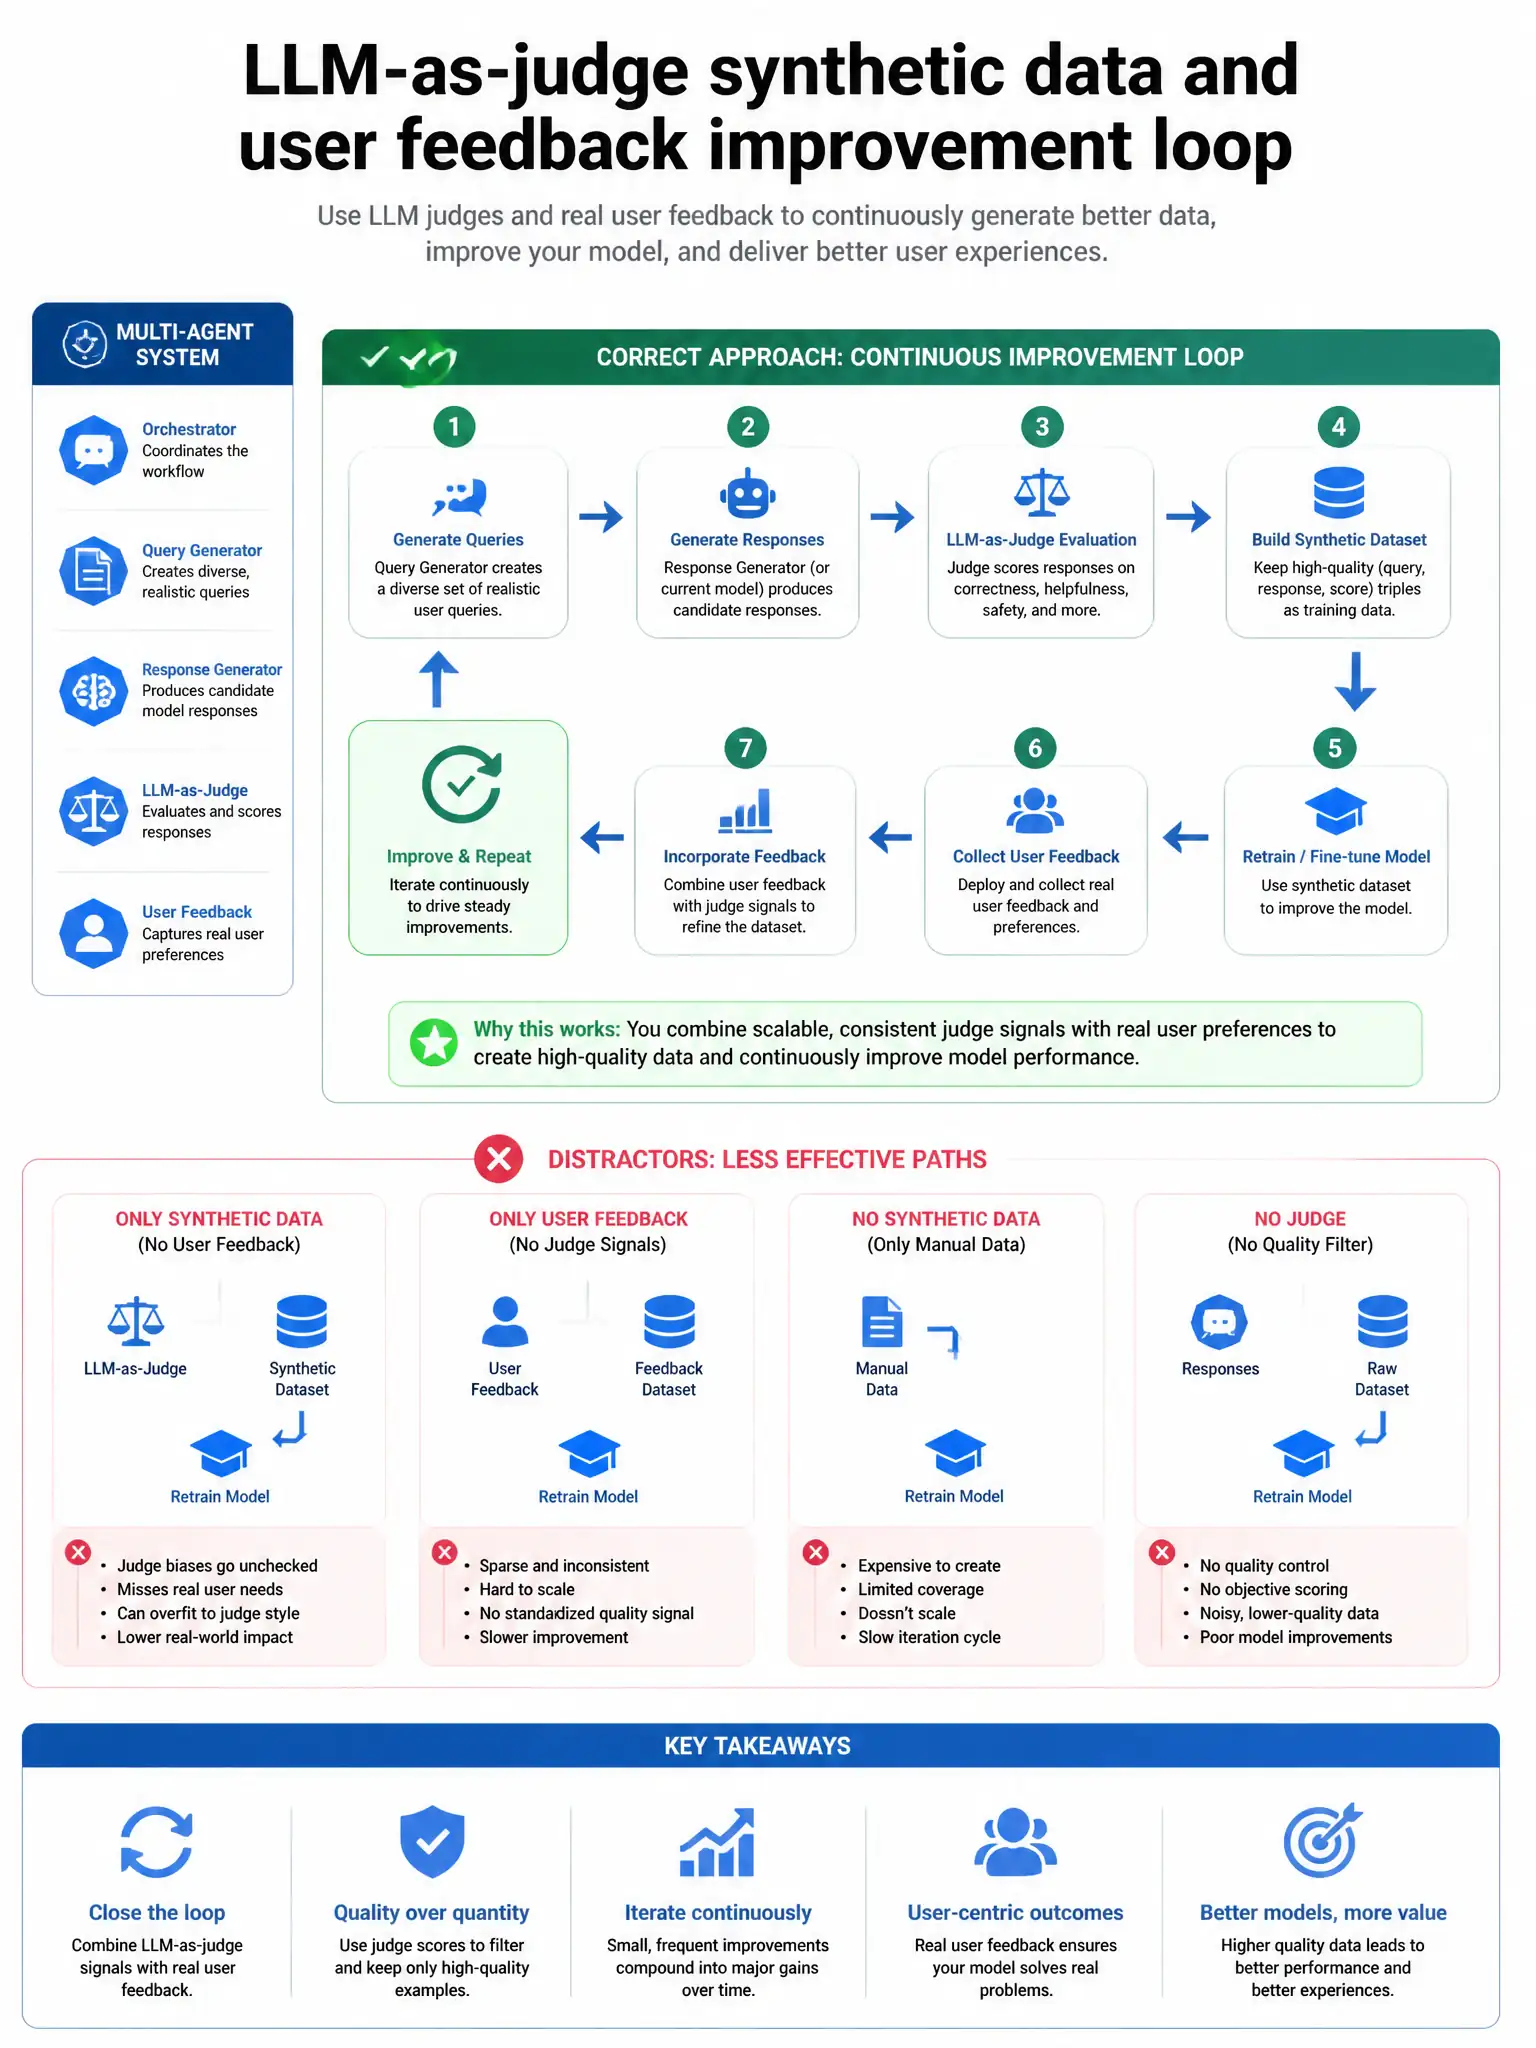
You need continuous-improvement loops that scale: use LLM-as-judge scoring, synthetic hard cases, semantic optimization on weak prompts, and user thumbs-down feedback. That combo gives you measurable quality work instead of rare manual checks.
Full Explanation
Continuous improvement for multi-agent solutions includes LLM-as-judge frameworks, synthetic data generation, semantic optimization loops, and user feedback loops—enabling scalable quality measurement and iterative prompt/model improvements. The annual manual-only review approach cannot keep pace with drift. The unmeasured random prompt edits approach risks regressions. The uptime-pings approach does not evaluate answer quality. Exam tip: LLM-as-judge + feedback + synthetics = continuous optimization story. Wire judges to dashboards and promotion gates for real optimization loops.