
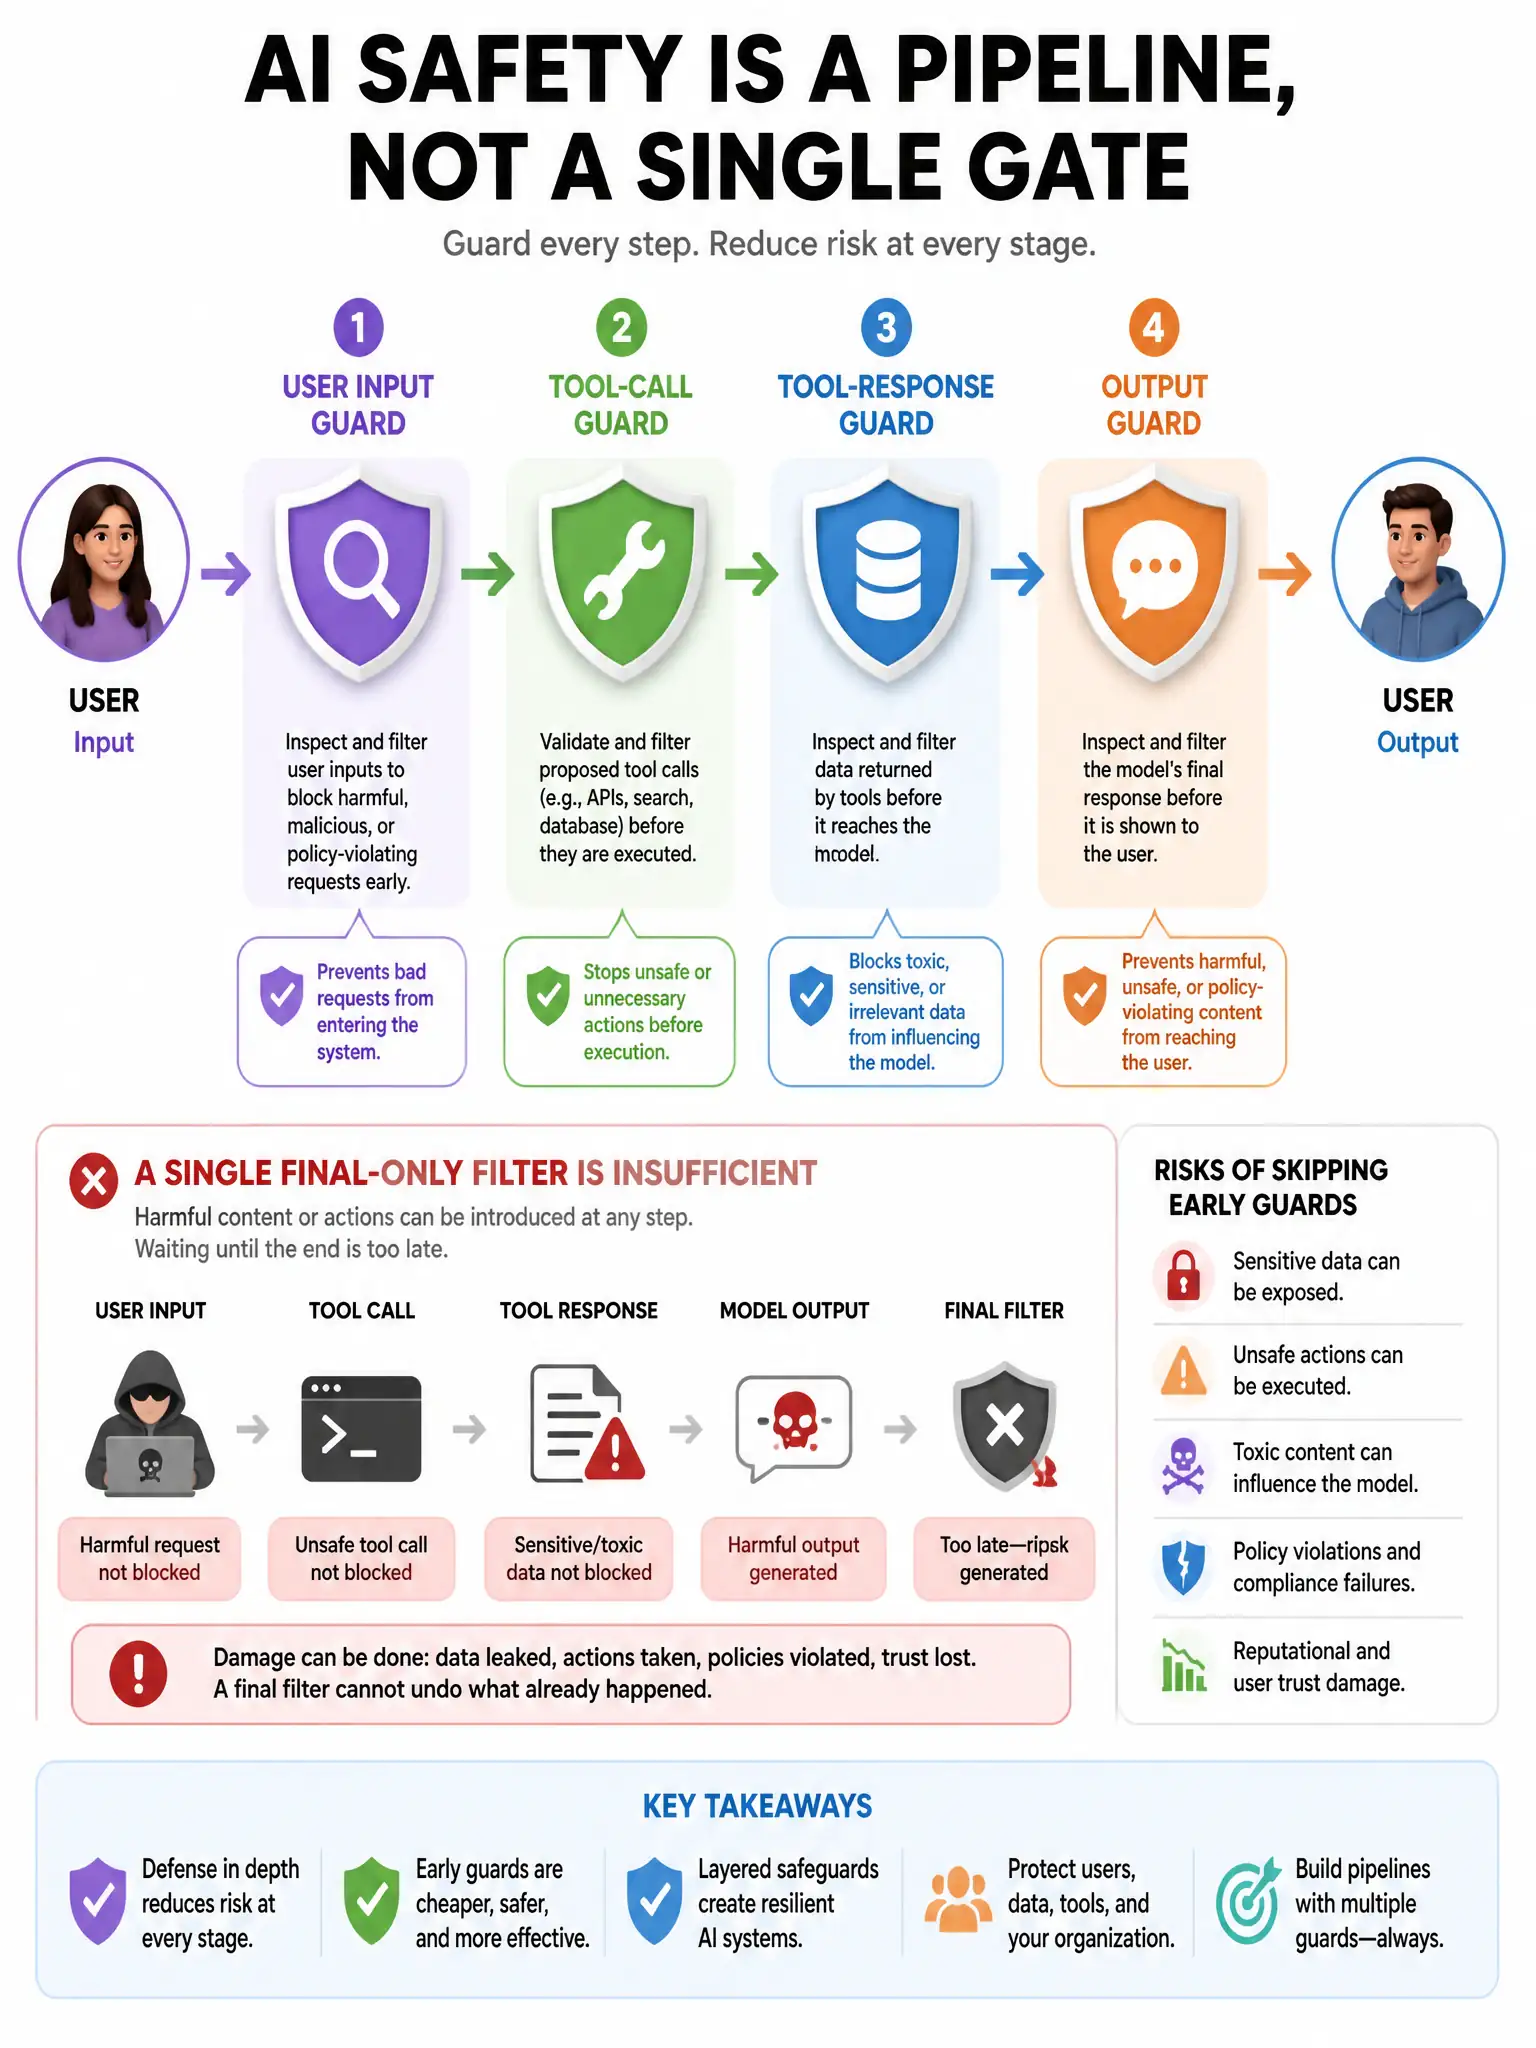
An enterprise multi-agent system must block toxic user inputs, prevent disallowed tool calls, validate tool responses before they re-enter the model, and filter unsafe final answers. Security rejects a single check only on the final response. What guardrail strategy should you design?
Select an answer to reveal the explanation.
Short Explanation
One final-output filter isn't enough. You need multi-intervention guardrails that inspect user inputs, gate tool calls, validate tool responses before they re-enter context, and filter model outputs, with independent enforcement and logging.
Full Explanation
Multi-intervention guardrails across user inputs, tool calls, tool responses, and outputs is an explicit secure/govern skill. The correct strategy implements independent enforcement at each stage with observability of blocks. Guardrails solely on the marketing website contact form leave the agent path unprotected. Trusting training alone ignores runtime threats such as injection and tool misuse. Logging violations only after customers see them is detective-only and too late for many harms. Add domain-specific custom guardrails where regulations demand, and test layers with synthetic adversarial data.