
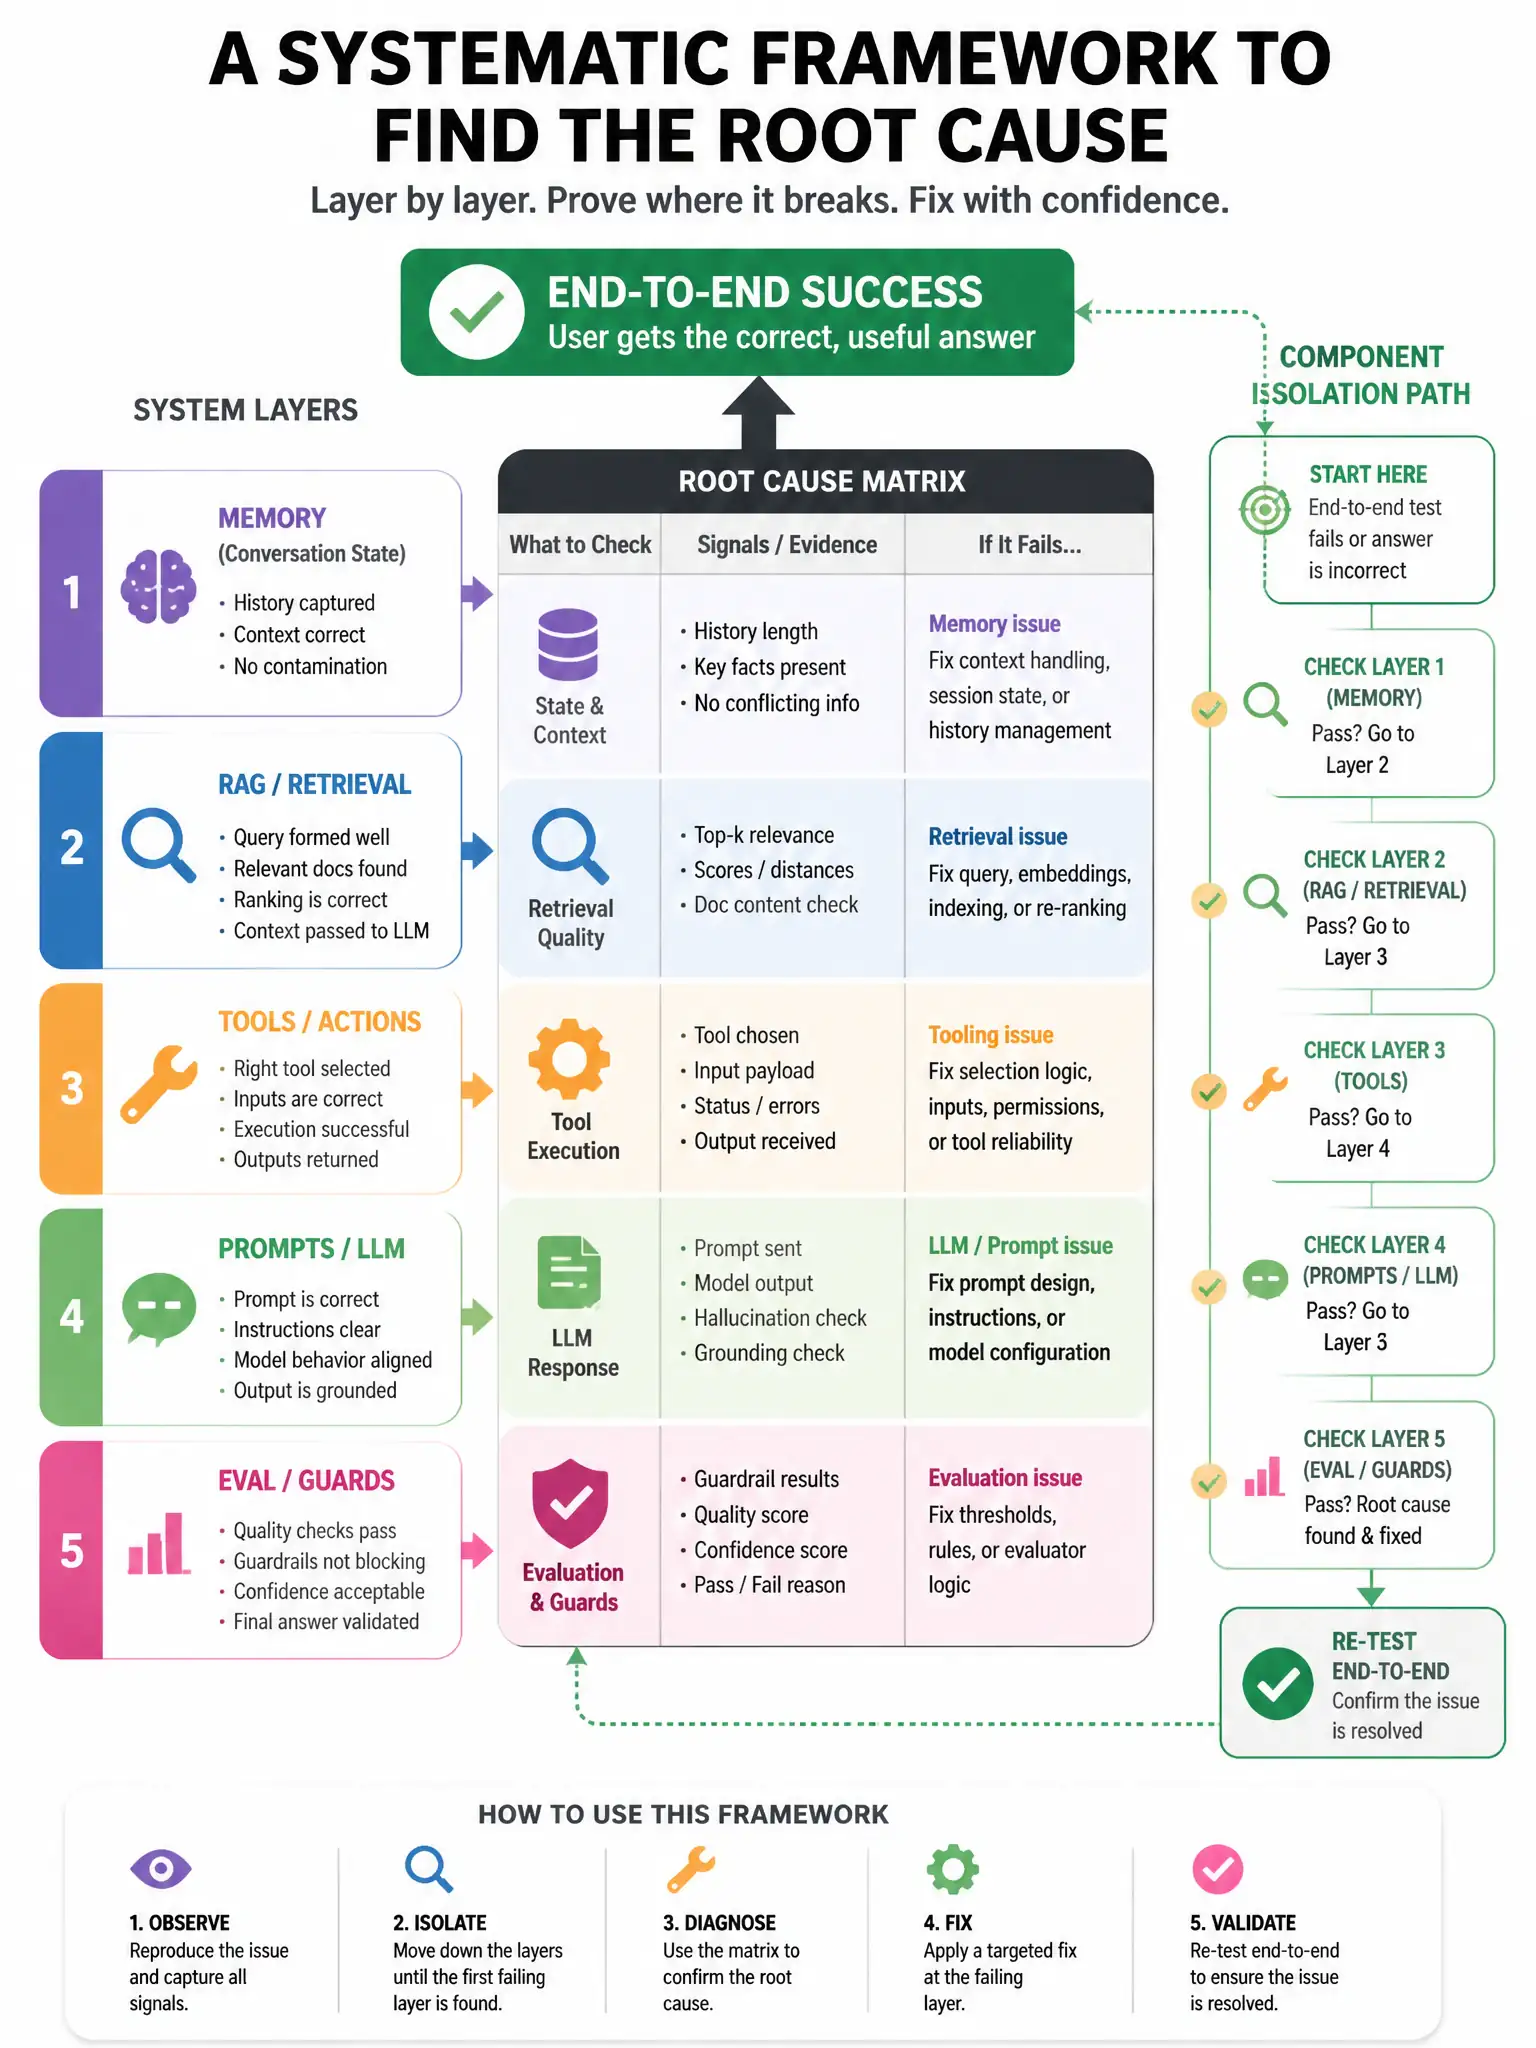
A platform squad wants evaluations that isolate failures across memory, knowledge retrieval, tools, and prompts rather than only scoring final answers. Which evaluation design best supports root-cause localization?
Select an answer to reveal the explanation.
Short Explanation
You need component-level evaluations—memory retention, retrieval precision/recall, tool contract and error-path tests, and prompt regression suites—plus end-to-end task success. That tells you whether memory, retrieval, tools, or prompts caused the failure. Timing, front-end status, or one developer thumbs-up won't localize the problem.
Full Explanation
Evaluations for multi-agent solutions should cover memory, knowledge, tools, and prompts—not only overall outcomes. The component-level evaluation design decomposes the system into testable components while retaining end-to-end metrics, enabling root-cause localization. Measuring only total wall-clock time of the orchestrator process and scoring solely whether the front-end returns status 200 are infrastructure or availability signals. Running a single subjective thumbs-up from one developer after demos is informal and non-repeatable. A robust Foundry-aligned strategy versions each evaluation suite, runs them in continuous integration on changes to prompts, tools, and indexes, and attaches failures to the responsible component owner.