
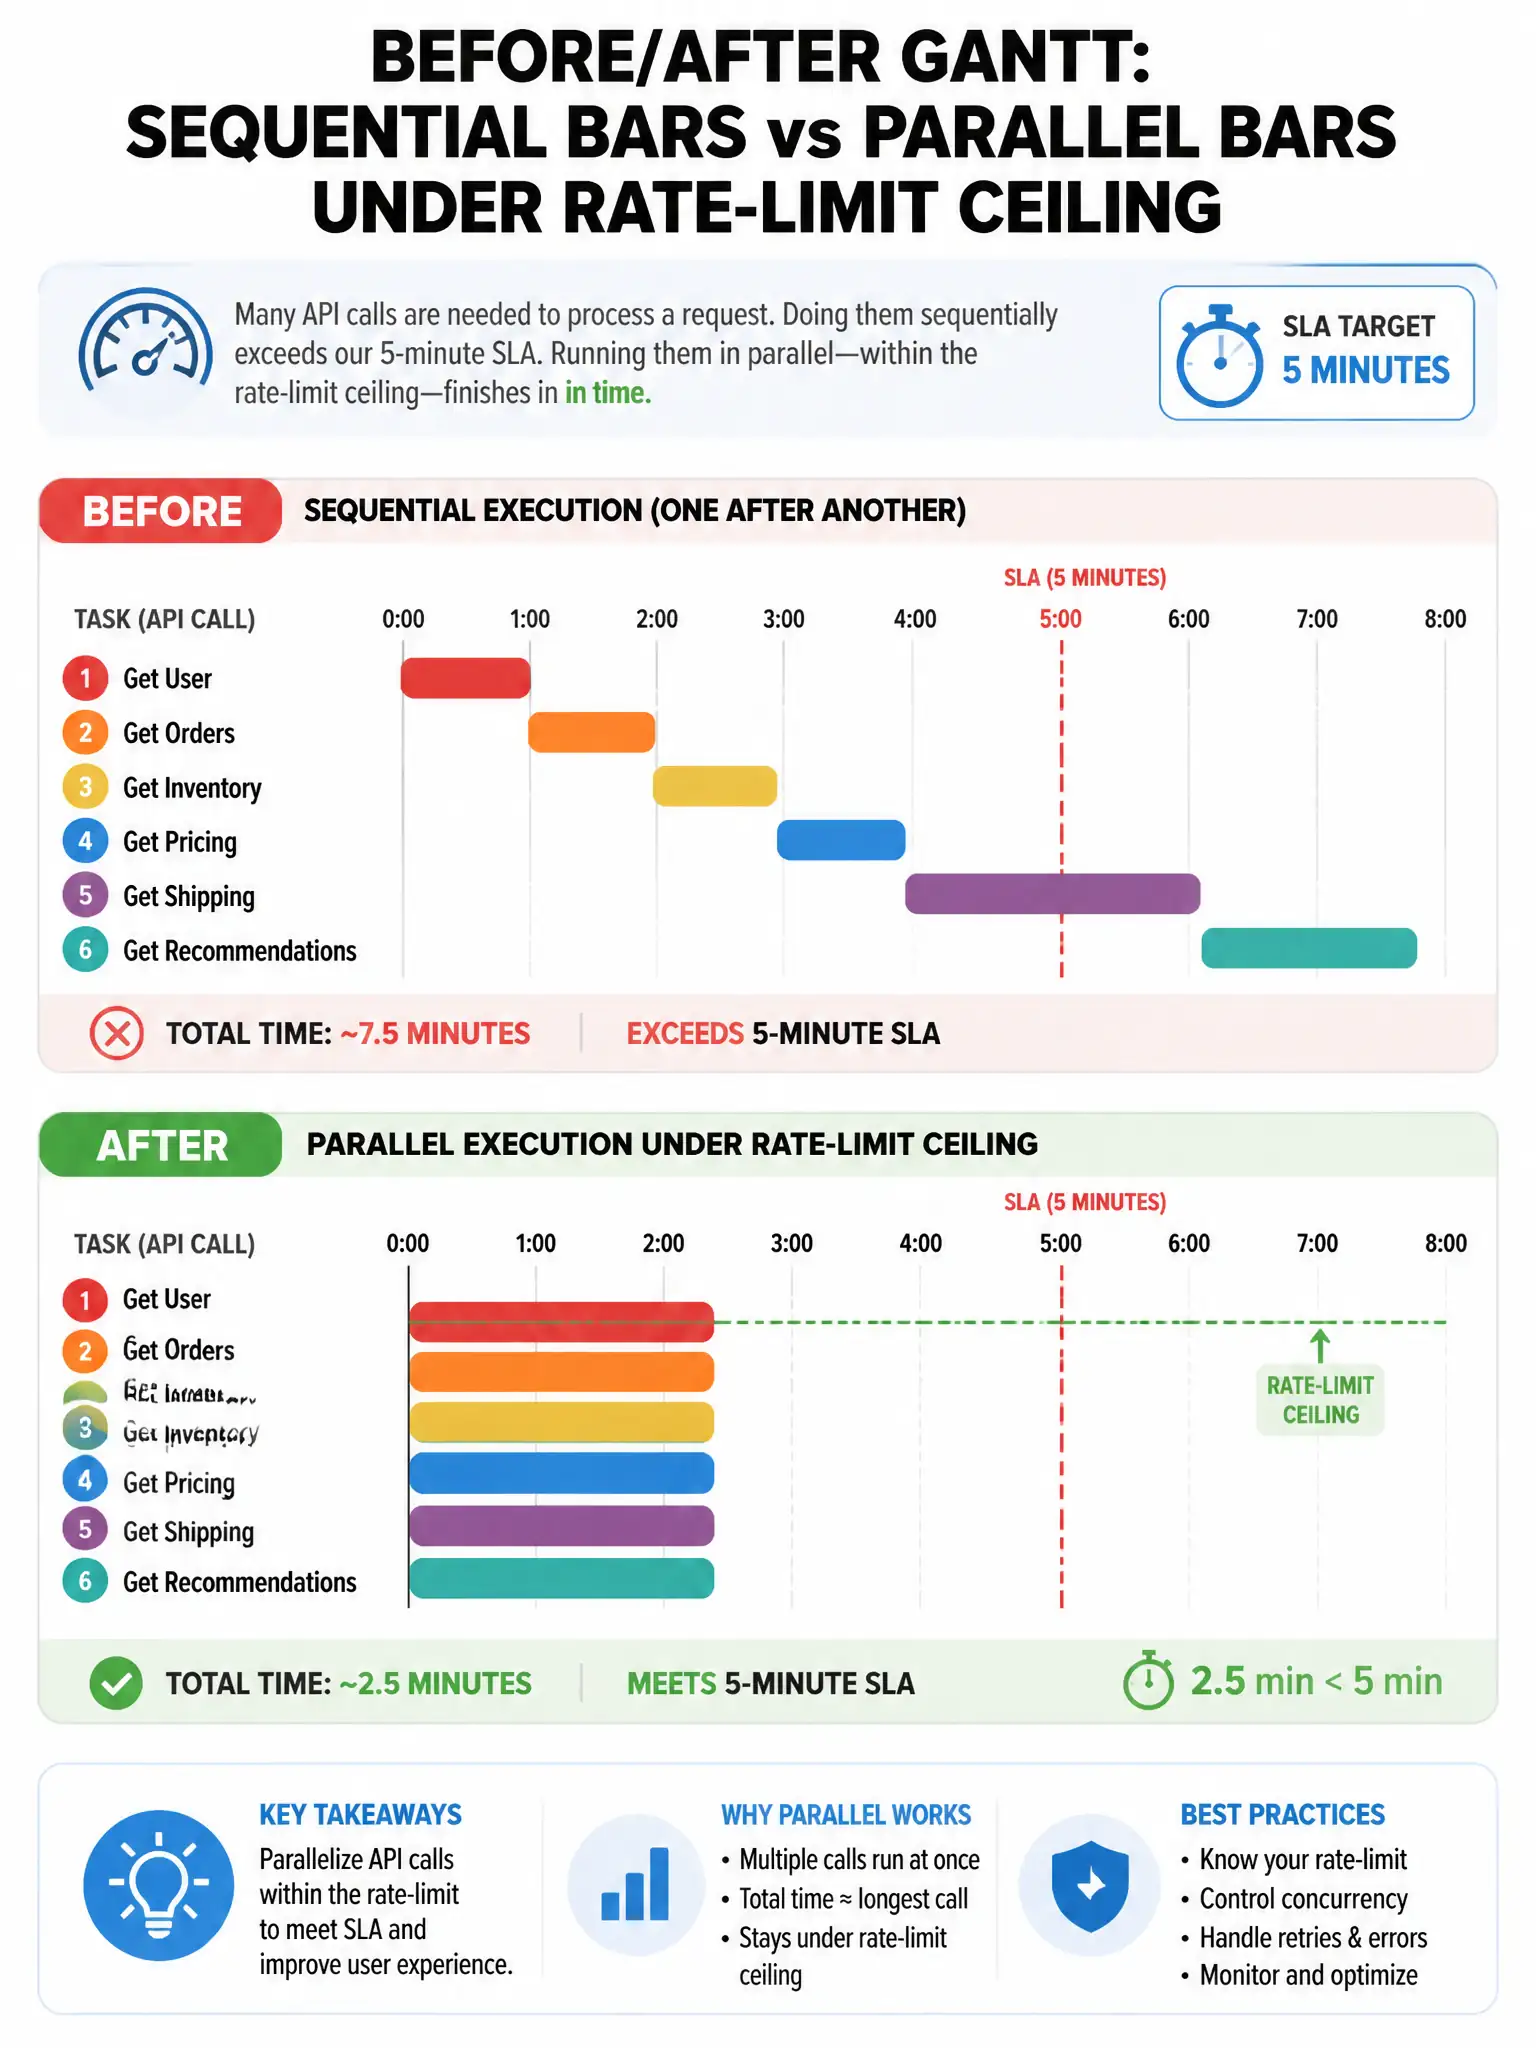
An orchestrator fans out ten research subagents sequentially even though their tasks are independent. End-to-end duration exceeds the five-minute SLA, while the model deployment still has headroom before rate limits. What should you do to optimize task duration?
Select an answer to reveal the explanation.
Short Explanation
You should run the independent research subagents in parallel, stay inside rate-limit budgets, batch when it helps, and serialize only true dependencies. Adding sleeps just makes the SLA worse. A no-tools mega-prompt drops research quality, and removing cache adds latency and cost.
Full Explanation
Optimizing task duration for multi-agent solutions includes parallelism and respect for rate limits. The scenario states independence among research tasks and remaining deployment headroom, so sequential fan-out is the bottleneck. Running independent subagents in parallel within model rate-limit budgets, batching where helpful, and serializing only steps with true data dependencies addresses the bottleneck. Adding a one-minute sleep between each subagent start increases duration. Collapsing all ten research tasks into a single mega-prompt that never uses tools sacrifices tool-based research quality and does not address orchestration structure. Removing caching so every subagent always hits the live model removes performance optimizations and increases latency and cost. Implement concurrency controls, exponential backoff on throttling, watch concurrency versus 429 responses, tune max parallel agents, and track p95 end-to-end duration versus SLA.