
A permits RAG bot returns irrelevant code sections for resident questions. What optimization should engineers try first for retrieval quality?
Select an answer to reveal the explanation.
Short Explanation
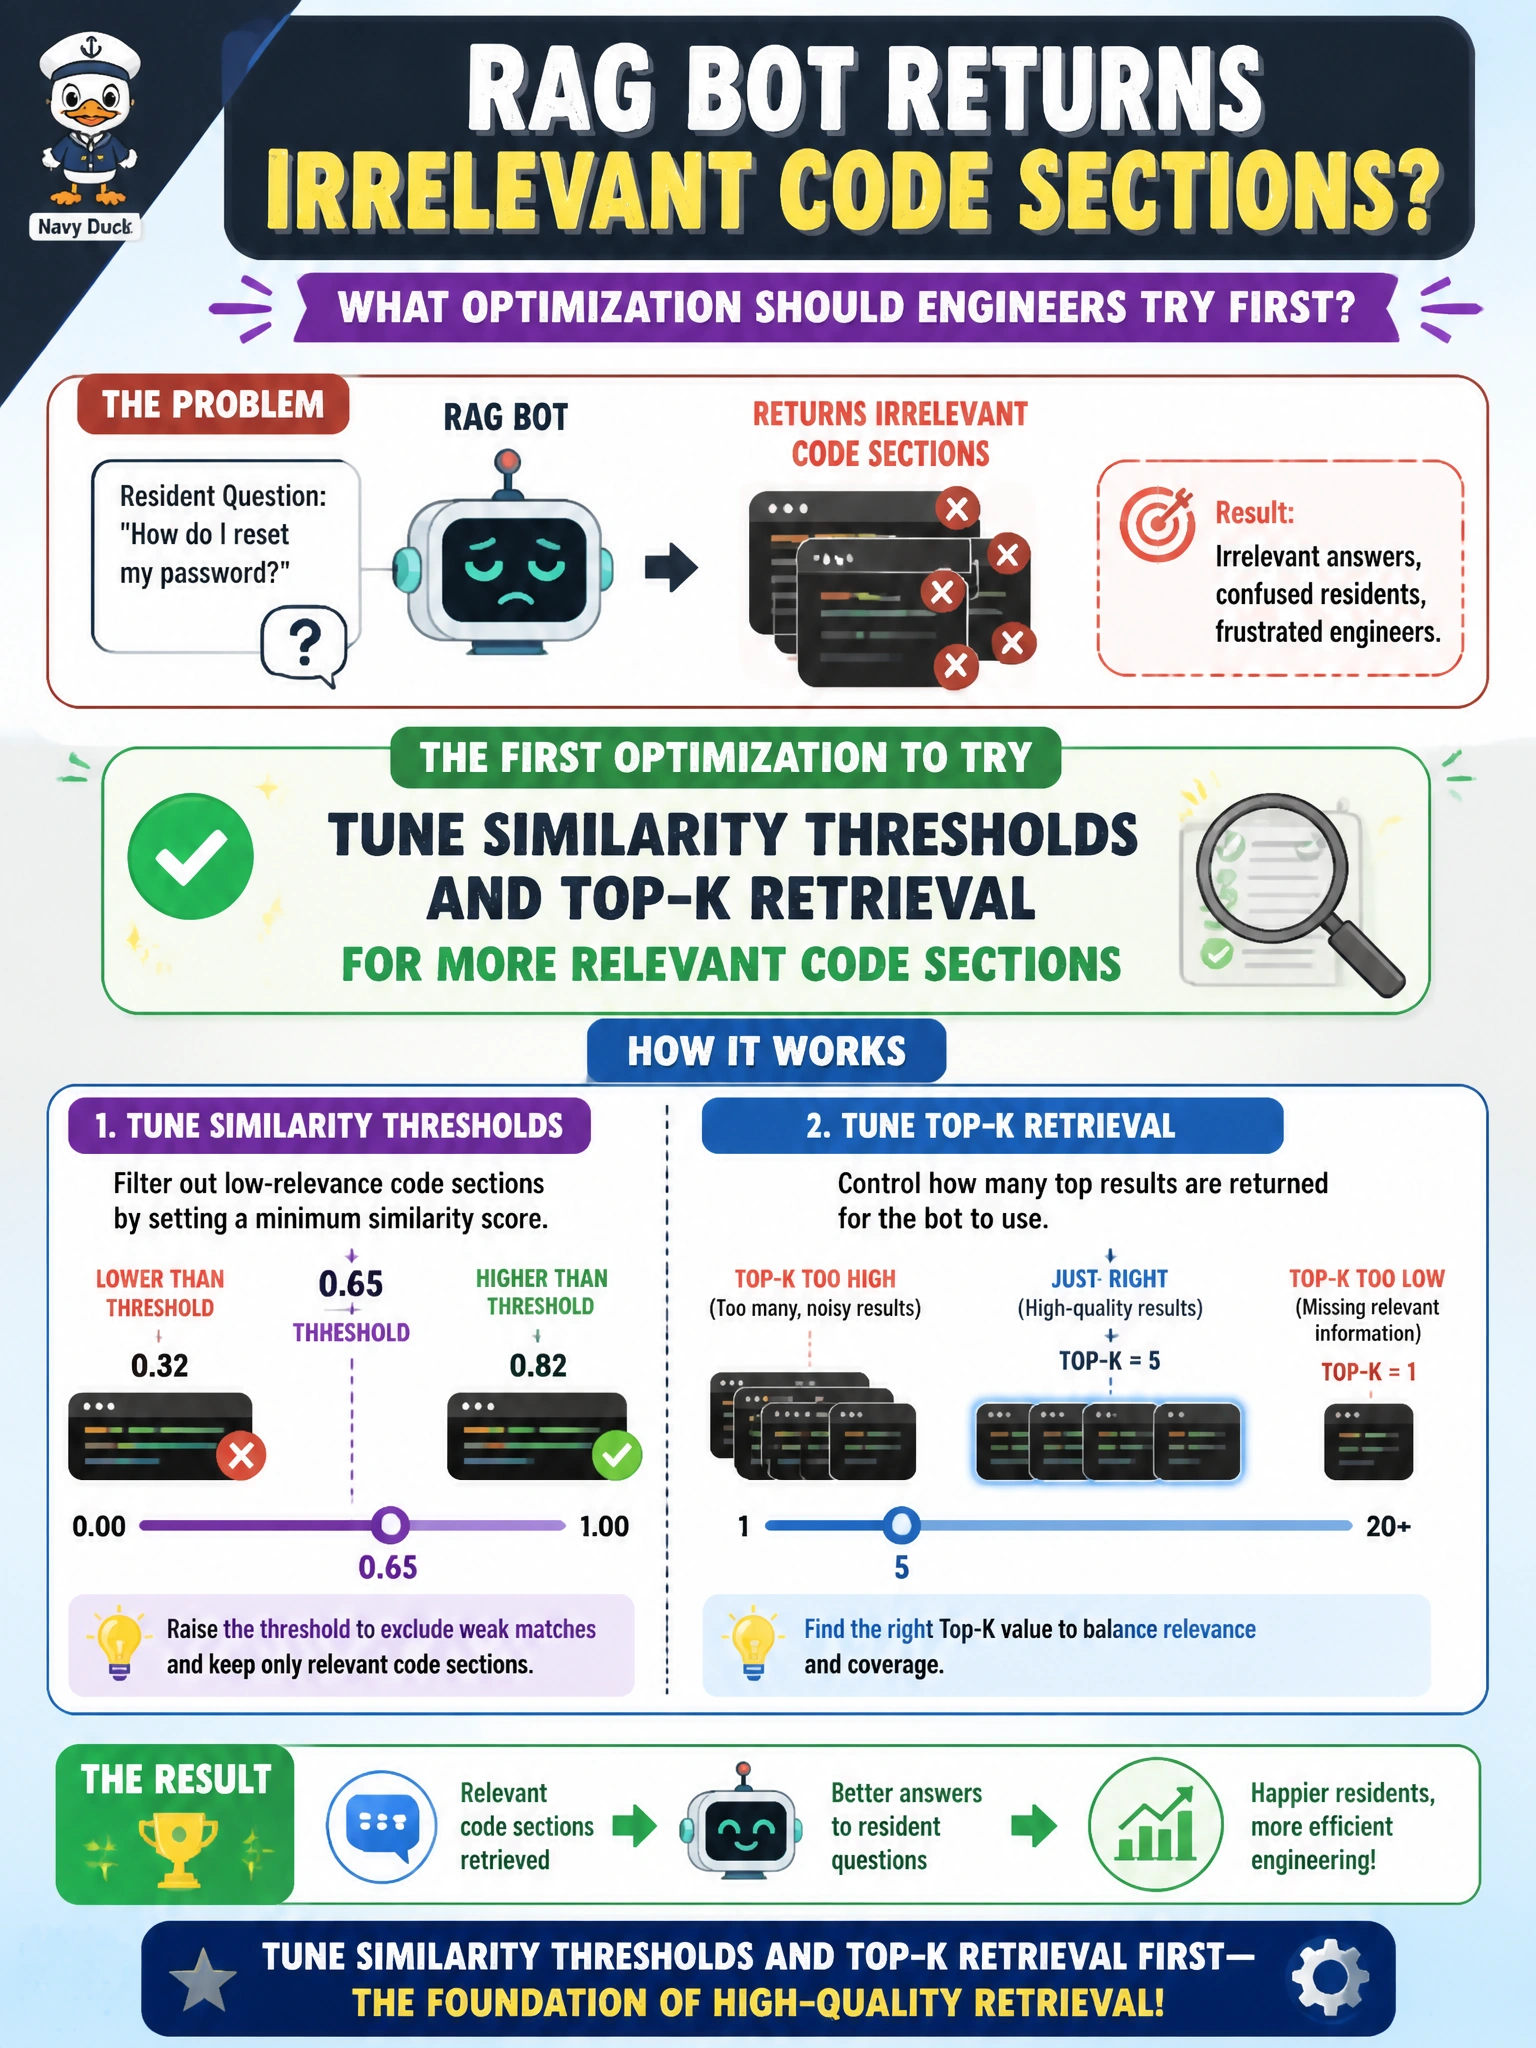
Wrong code sections usually mean the retriever is too loose or grabbing too many neighbors. Tighten similarity thresholds and top-k before rewriting city law.
Full Explanation
Tuning similarity thresholds and top-k retrieval for more relevant code sections is correct because RAG answer quality depends heavily on what the retriever returns before generation. When a permits RAG bot surfaces irrelevant building-code sections, engineers should first adjust how aggressively and how many neighbors are retrieved—raising similarity thresholds to reject weak matches and tuning top-k to avoid noisy extra chunks—then re-evaluate relevance. That is the least-invasive, highest-leverage retrieval-quality optimization for municipal code Q&A.
Upgrading to a larger embedding model for the permits corpus vectors leaves the retriever fetching the same irrelevant code sections; a better embedding model alone cannot fix retrieval if the similarity thresholds and top-k are still misconfigured. Refining the system prompt with detailed permit code citation instructions alters the generator’s output style, not which code sections were retrieved; irrelevant sections remain irrelevant regardless of prompt phrasing. Introducing a cross-encoder reranker to reorder retrieved permit sections per query adds complexity without addressing the root cause; if the initial retrieval step already fetches irrelevant sections, reranking will only reshuffle noise.
Exam caveat: irrelevant RAG results → tune retrieval controls (similarity threshold, top-k, and related rankers) first. Do not disable RAG, do not expect prompt refinement alone to fix retrieval, and do not "fix" retrieval by rewriting municipal law.
Operational check: build a permits eval set of resident questions with expected code sections, sweep similarity threshold and top-k, score retrieval hit-rate and answer relevance, pick settings that maximize relevant sections without starving recall, and promote only after the eval set improves versus baseline.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.