
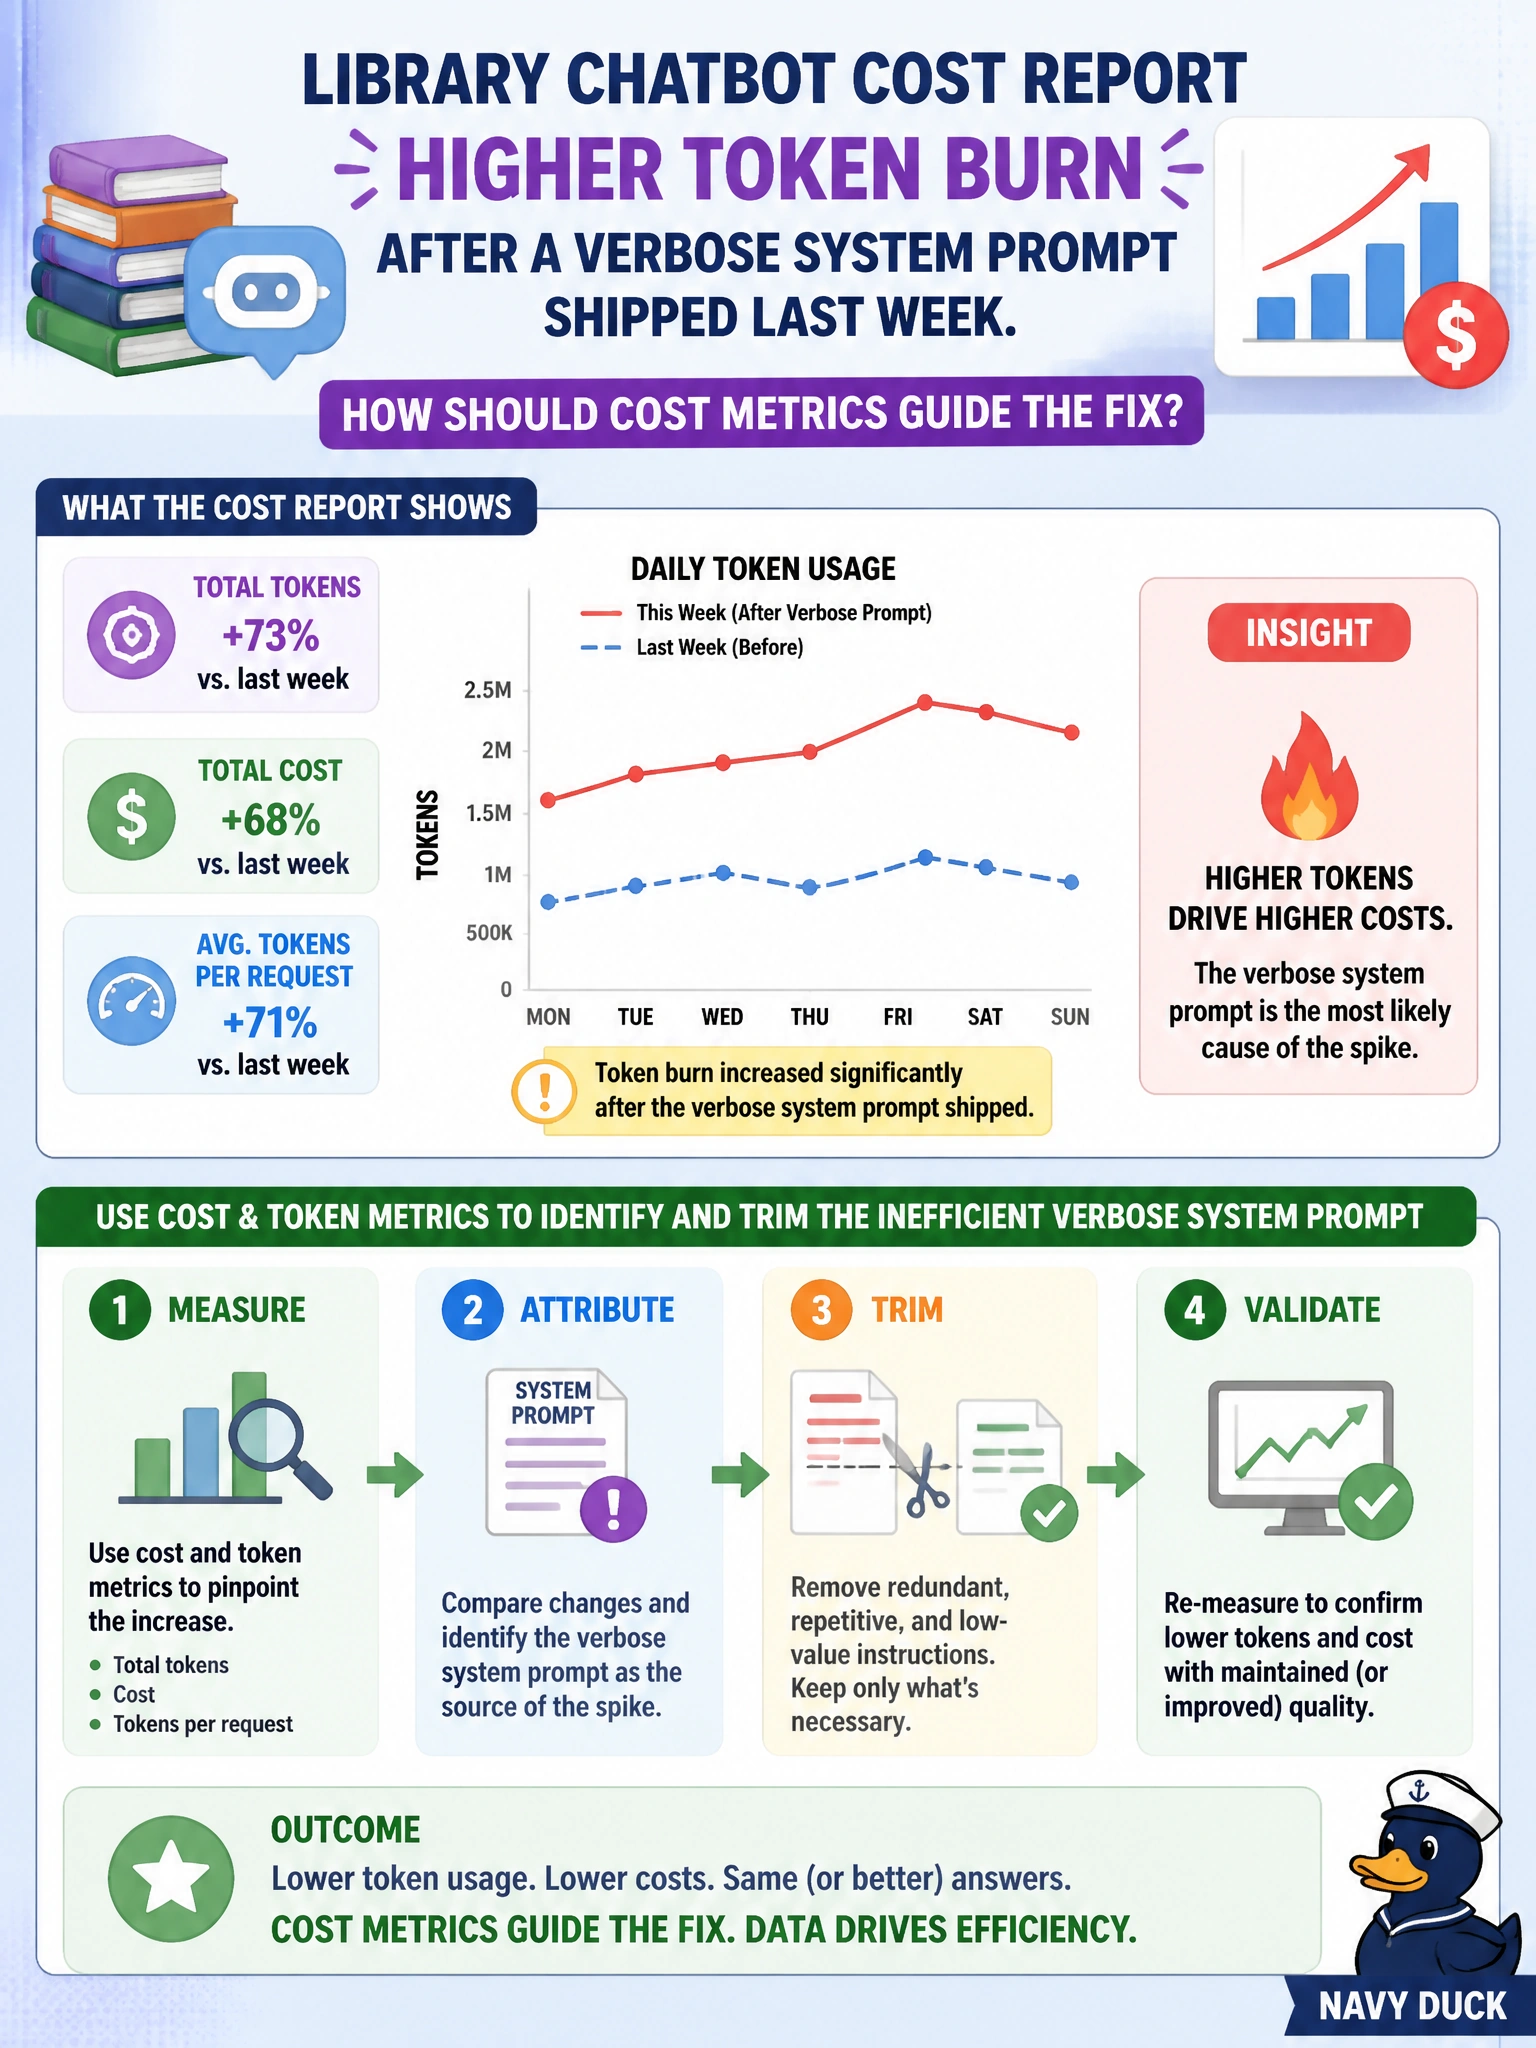
A library chatbot cost report shows higher token burn after a verbose system prompt shipped last week. How should cost metrics guide the fix?
Select an answer to reveal the explanation.
Short Explanation
If tokens spiked right after a wordy system prompt landed, the cost report just pointed at the culprit. Trim the prompt.
Full Explanation
Using cost and token metrics to identify and trim the inefficient verbose system prompt is correct because token burn is a direct lever on generative spend. When a library chatbot cost report shows higher token consumption after a verbose system prompt shipped, the metrics themselves point to prompt bloat as the likely cause: every turn carries extra instructions into the context window. Cost and token dashboards should drive a prompt review and trim so municipal library budgets return to baseline without sacrificing required safety or grounding instructions.
Using cost and token metrics to tune sampling temperature for the verbose system prompt changes sampling behavior, not the fixed per-turn instruction overhead that drives the observed burn. Using cost and token metrics to shift the verbose system prompt to a larger context model can plausibly feel like a quality improvement, but moving to a bigger model does not reduce the per-turn instruction overhead that caused the cost report to spike in the first place. Using cost and token metrics to resize the vector index for the verbose system prompt misassigns cause to infrastructure sizing instead of usage-driven token costs that prompt design controls.
Exam caveat: cost/token spikes correlated with a prompt change → optimize the prompt (and related context size). Do not confuse tuning sampling temperature for the verbose system prompt, shifting to a larger-context model, or resizing the vector index with token-efficiency remediation.
Operational check: compare token-per-conversation before and after the prompt change, A/B a shortened system prompt that retains mandatory library policies, verify quality metrics (relevance/groundedness) stay within threshold, and promote the trimmed prompt once cost and quality both pass the library’s GenAIOps gates.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.