
A transit multimodal assistant must run a vision-capable foundation model on station camera stills with controlled compute. What deployment option fits better than pure bursty serverless chat?
Select an answer to reveal the explanation.
Short Explanation
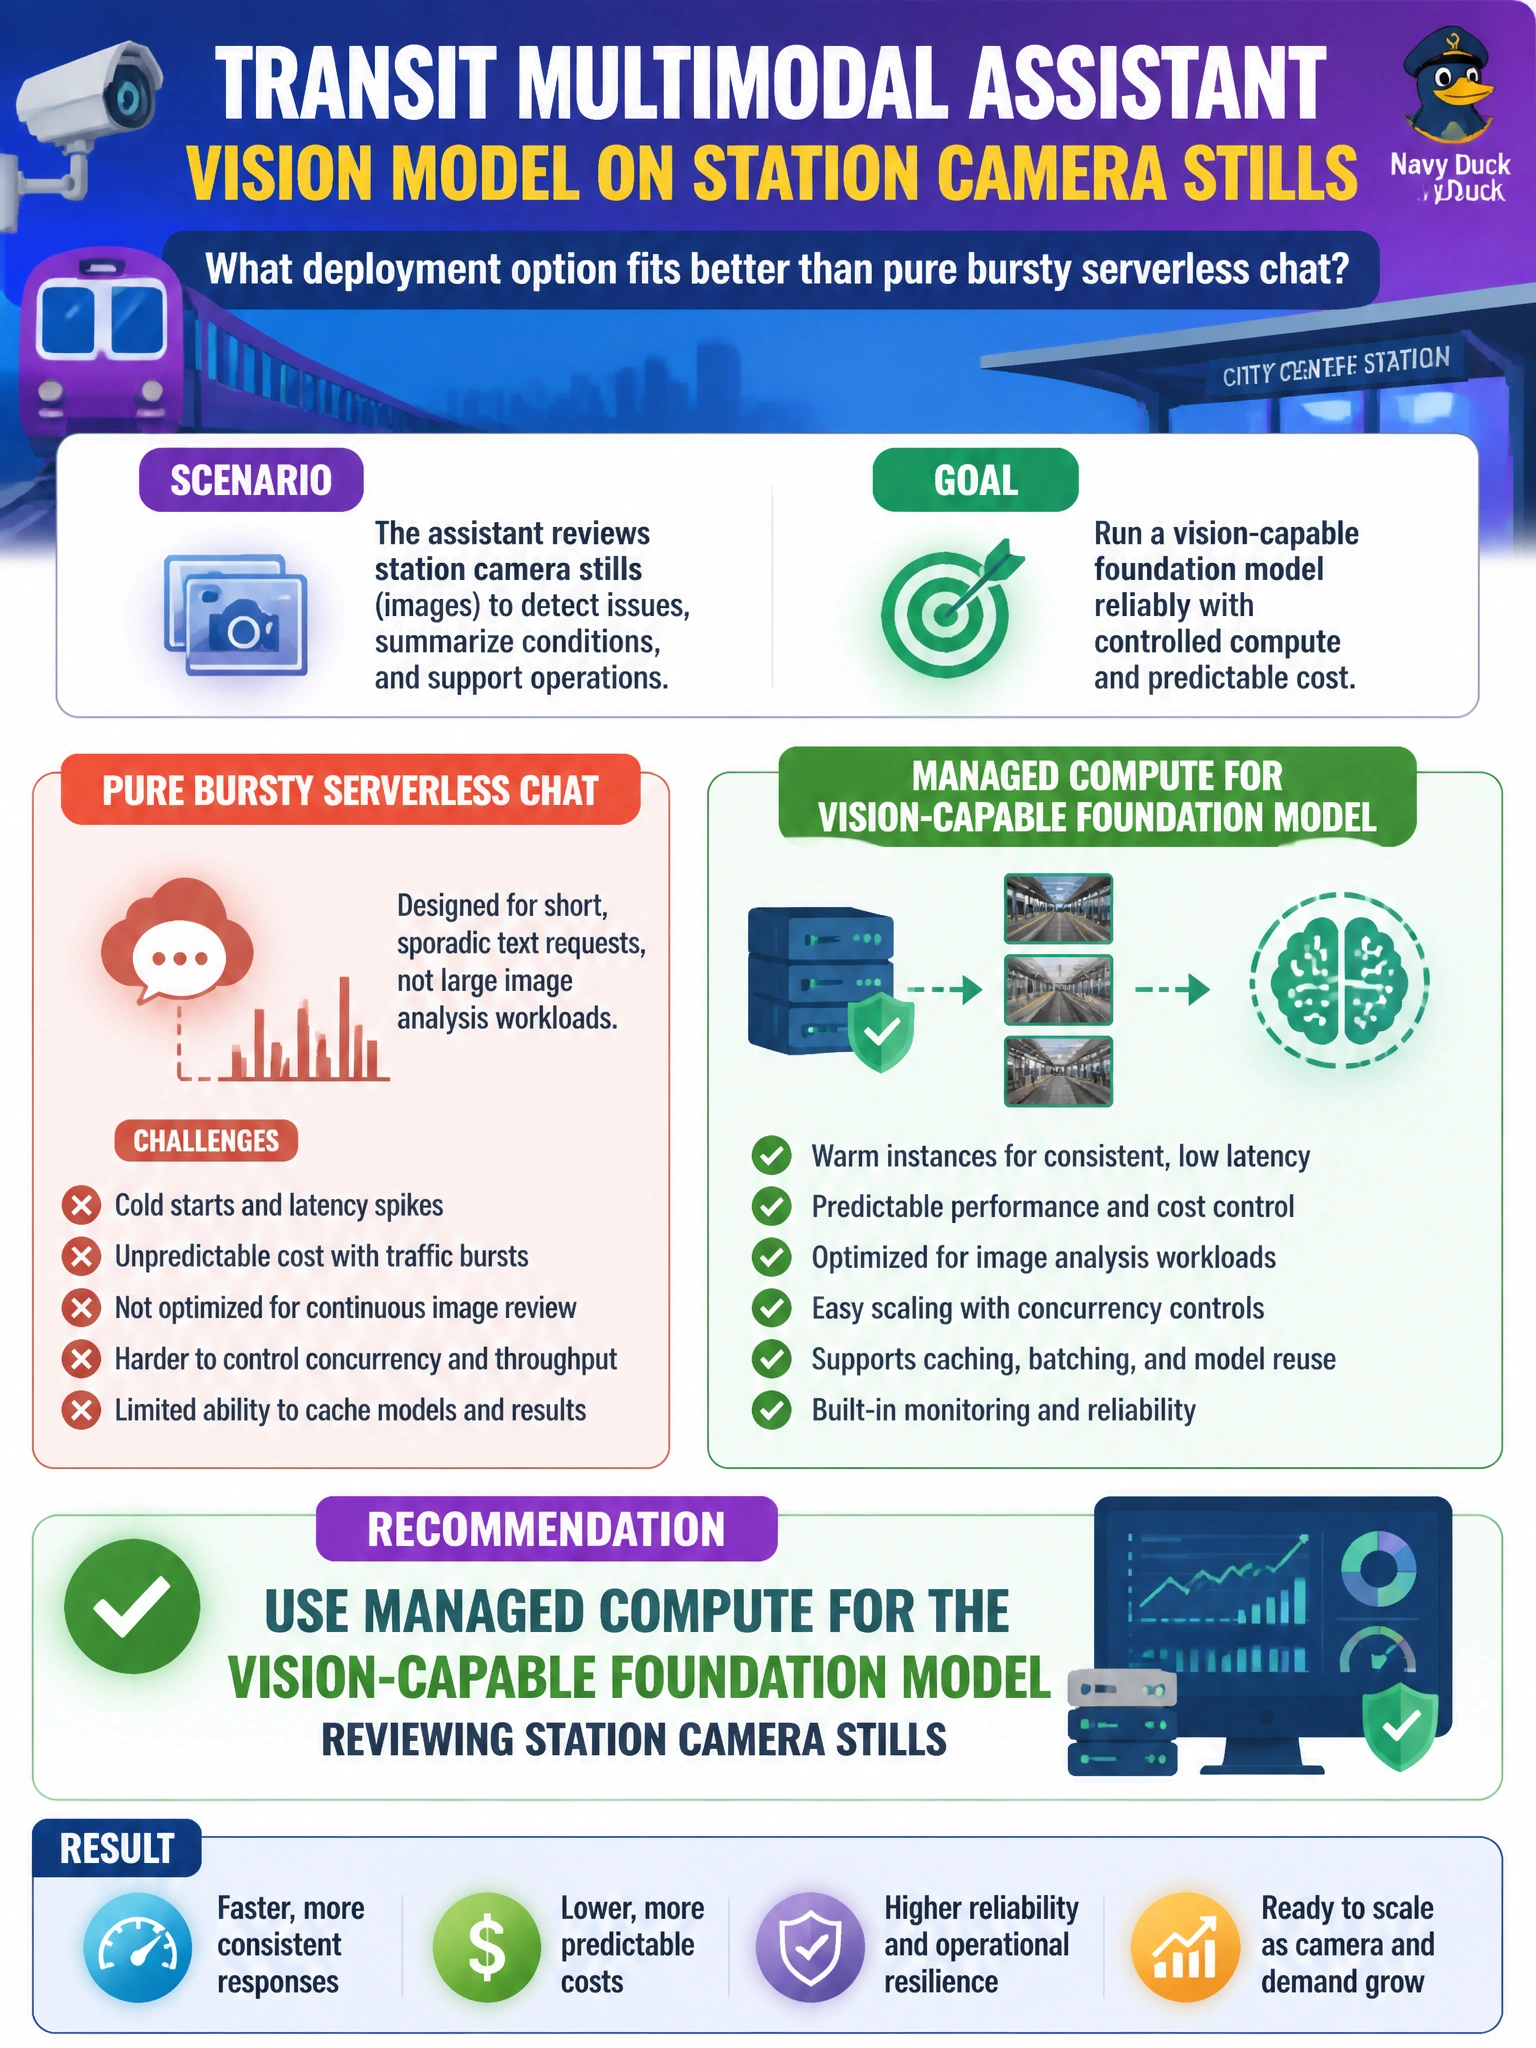
Vision on station stills is heavier than quick text FAQ, so you won't get controlled compute from serverless chat for reviewing them. Park that foundation model on managed compute so you get predictable capacity, not a guessy burst tier.
Full Explanation
Using managed compute for the vision-capable foundation model reviewing station camera stills is the better fit than pure bursty serverless chat for a transit multimodal assistant that needs controlled compute. Vision workloads on camera stills are typically heavier and more sustained than short text FAQ turns; managed compute gives transit GenAIOps predictable capacity, clearer performance envelopes, and operational control for multimodal inference that may not behave well on a chat-oriented burst tier alone. The platform can still remain governed under municipal identity and networking while serving station imagery review.
Using serverless chat for the vision-capable foundation model reviewing station camera stills fails because sustained multimodal inference on camera stills is heavier than short bursty text turns, and a chat-oriented serverless tier lacks the controlled, predictable capacity the stem asks for. Using a batch endpoint for the vision-capable foundation model scoring station camera stills fails because batch inference is asynchronous offline bulk scoring with queued latency, not the controlled online inference the assistant needs for responsive review of station imagery. Using managed compute for the vision-capable foundation model training on station camera stills fails because training provisions compute to create or tune the model, not to serve inference reviews, so it does not deliver the reviewing capability the stem asks for despite using managed compute.
Exam caveat: serverless APIs suit variable text chat; managed compute is the distractor-beating answer when the stem pairs vision/multimodal load with “controlled compute” versus bursty serverless chat. Do not pick serverless solely because it appeared in adjacent questions.
Operational check: host the vision-capable FM on managed compute sized for station-still throughput, confirm private data paths for imagery, and measure latency/throughput under representative transit camera batches before production cutover.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.