
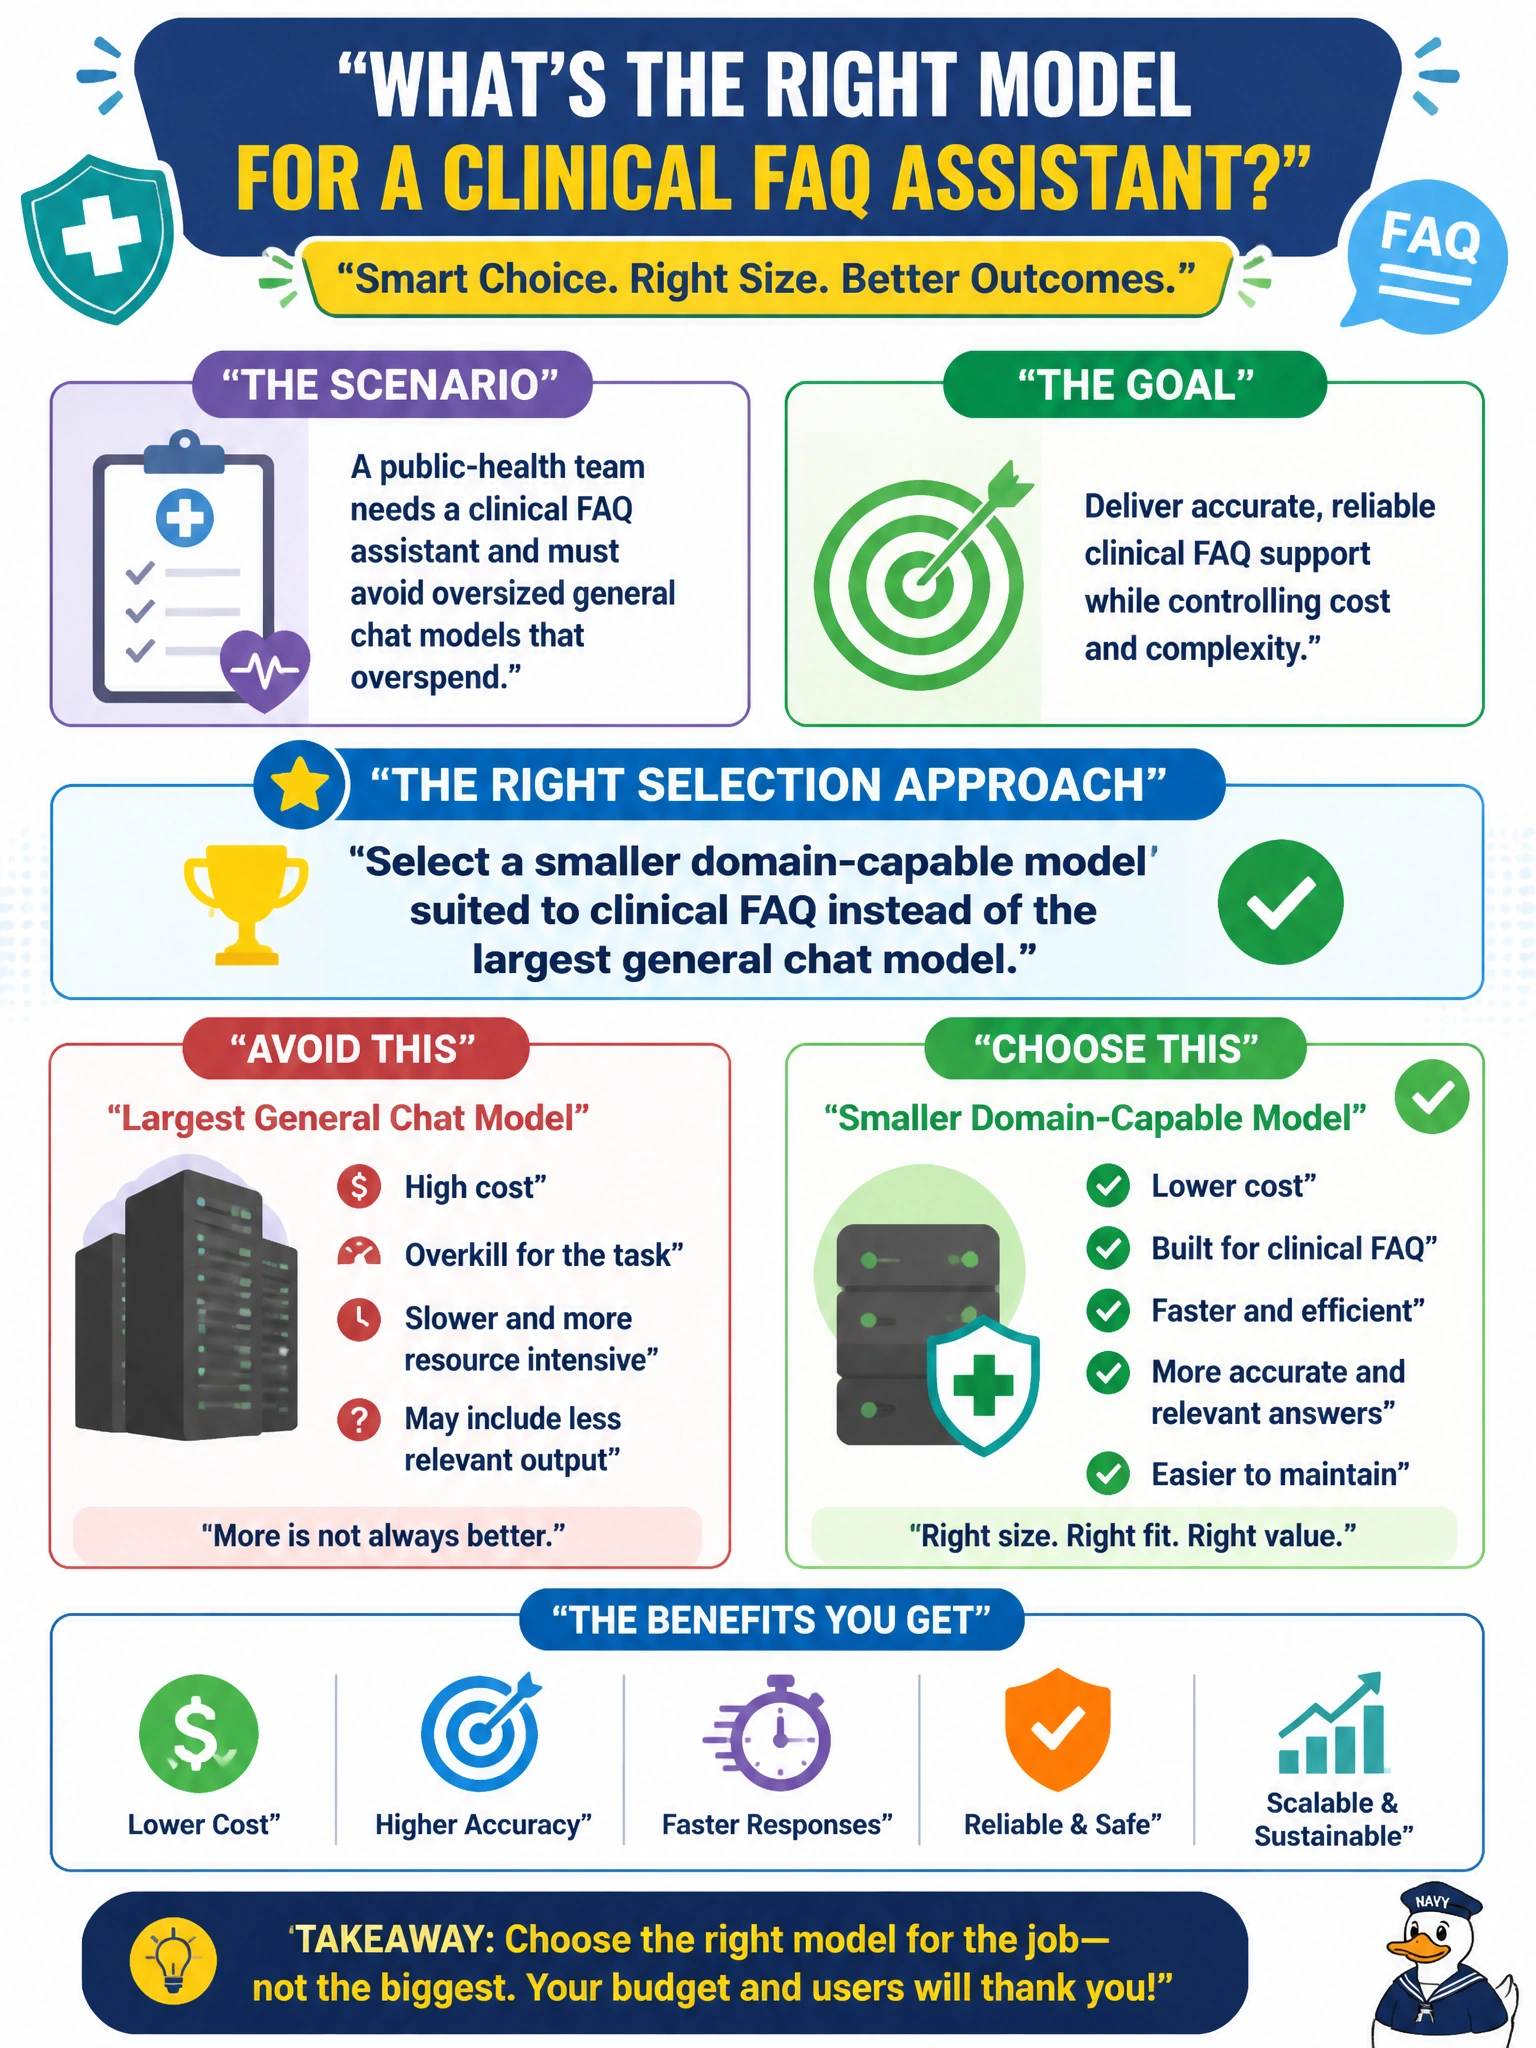
A public-health team needs a clinical FAQ assistant and must avoid oversized general chat models that overspend. What selection approach fits?
Select an answer to reveal the explanation.
Short Explanation
Clinical FAQ isn't a creativity contest. Pick a smaller domain-capable model — you'll get clinical accuracy, not just casual chat or one built for a different job. Casual conversation skills or a leaderboard rank won't fix that for you.
Full Explanation
Selecting a smaller domain-capable model suited to clinical FAQ instead of the largest general chat model is the correct selection approach for a public-health team that must avoid oversized general chat spend. Foundation-model choice should match task scope, domain language, and cost: clinical FAQ assistants need accurate health-guidance retrieval and grounded answers more than maximum creative breadth. A smaller domain-capable model typically reduces per-token cost and operational overhead while remaining adequate for constrained FAQ dialogs under municipal budget and policy.
Selecting a smaller open-domain dialogue model optimized for casual conversation for clinical FAQ coverage fails because it is optimized for casual open-domain chat, not clinical guidance — it lacks the domain language and grounded health-answer accuracy required for clinical FAQ, so small size alone does not make it a suitable fit. Selecting a clinical summarization model optimized for discharge notes to support FAQ interaction needs fails because that model is tuned for a different task — summarizing clinical notes, not holding a conversational FAQ exchange — so it is a task mismatch rather than a right-sized fit. Benchmarking candidate models on general-purpose chat leaderboards to select the clinical FAQ assistant fails because leaderboard rank reflects broad conversational ability, not clinical-FAQ accuracy, so it says nothing about whether a model handles health-guidance questions correctly.
Exam caveat: “right-size the model to the use case” beats “biggest model wins.” When stems mention FAQ scope and overspend on general chat models, prefer smaller domain-capable selections; reserve larger general models for broader generative tasks with justified budgets.
Operational check: define clinical FAQ evaluation sets, compare a smaller domain-capable candidate against a large general chat baseline on quality and token cost, and document the selection against the public-health budget before production.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.