
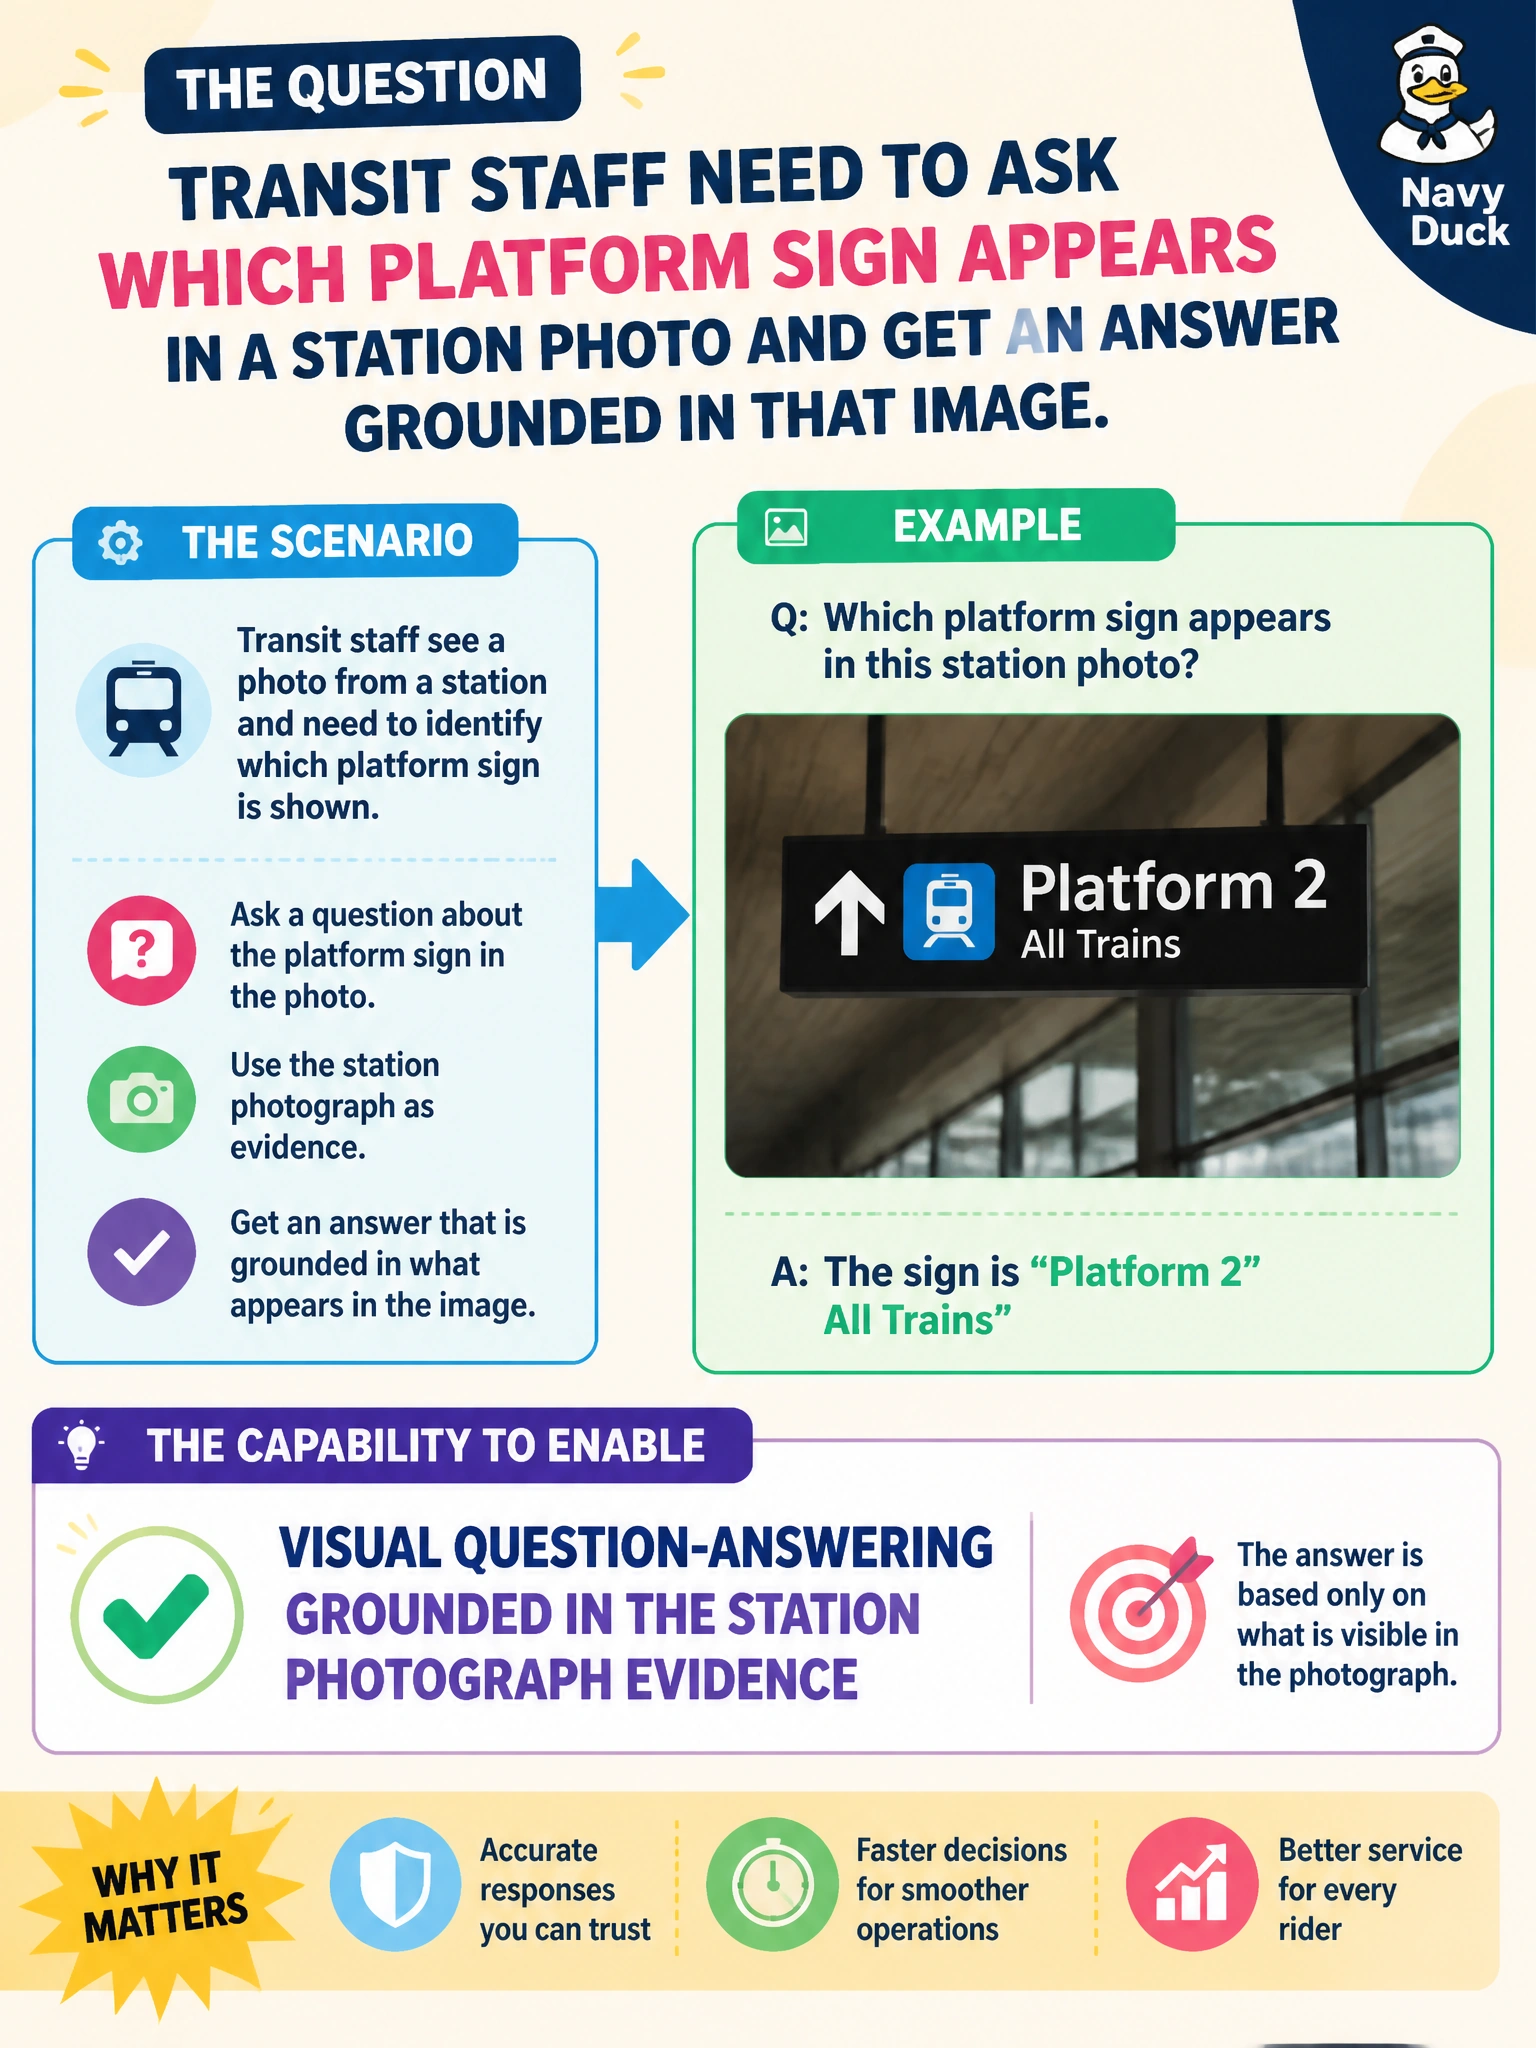
Transit staff need to ask which platform sign appears in a station photo and get an answer grounded in that image. Which capability should they enable?
Select an answer to reveal the explanation.
Short Explanation
Visual Q&A is like pointing at the photo and asking, “Which sign is that?” The model answers your specific question from what’s actually in the frame. A general caption of the scene, raw text pulled off every sign, or a box drawn around a sign’s location all stop short of actually answering which one it is.
Full Explanation
Visual question-answering (VQA) lets operators ask natural-language questions about an image and receive answers grounded in that image’s content. Transit staff who need to know which platform sign appears in a station photograph should enable VQA so the model inspects the uploaded frame and answers from visible signage rather than from generic knowledge. Grounding is the distinguishing concept: the response must be tied to evidence in the photo, and it must answer the specific question asked.
Dense image captioning describing the overall station scene content produces a general description of what’s in the frame—platform, crowd, signage in passing—but a caption is not an answer to a specific question like “which sign is this,” so staff would still have to guess which part of it addresses their query. Optical character recognition extracting text regions from the photo pulls raw text off every sign and label in the frame without knowing which text belongs to the sign staff asked about, so a person still has to sort the extracted strings. Object detection locating platform signs within the station image can draw a box around a sign, but locating where a sign is is not the same as reporting which sign it is. Each capability touches the image but stops short of the grounded, question-specific answer VQA provides.
Exam caveat: VQA quality depends on image clarity, occlusion, and sign language; low-light or angled shots may yield low-confidence answers that staff must verify on-site or against CAD drawings. Choose VQA over captioning, OCR, or detection whenever the task is answering a specific question about the image, not just describing, extracting text from, or locating objects within it. Operational check: submit a known station photo with a test question about the visible platform sign, confirm the answer matches the frame, require human confirmation before operational decisions, and retain the photo with the Q&A log for audit.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.