
Hakim is preparing an Azure AI Search index at Starbridge Logistics so their Copilot Studio agent can query shipment documentation. He has uploaded 3,000 PDF-derived documents to an Azure Blob container and created an indexer. Before the agent can query the index successfully, which TWO configuration elements must Hakim ensure are in place? (Choose the best single answer that correctly identifies both.)
Select an answer to reveal the explanation.
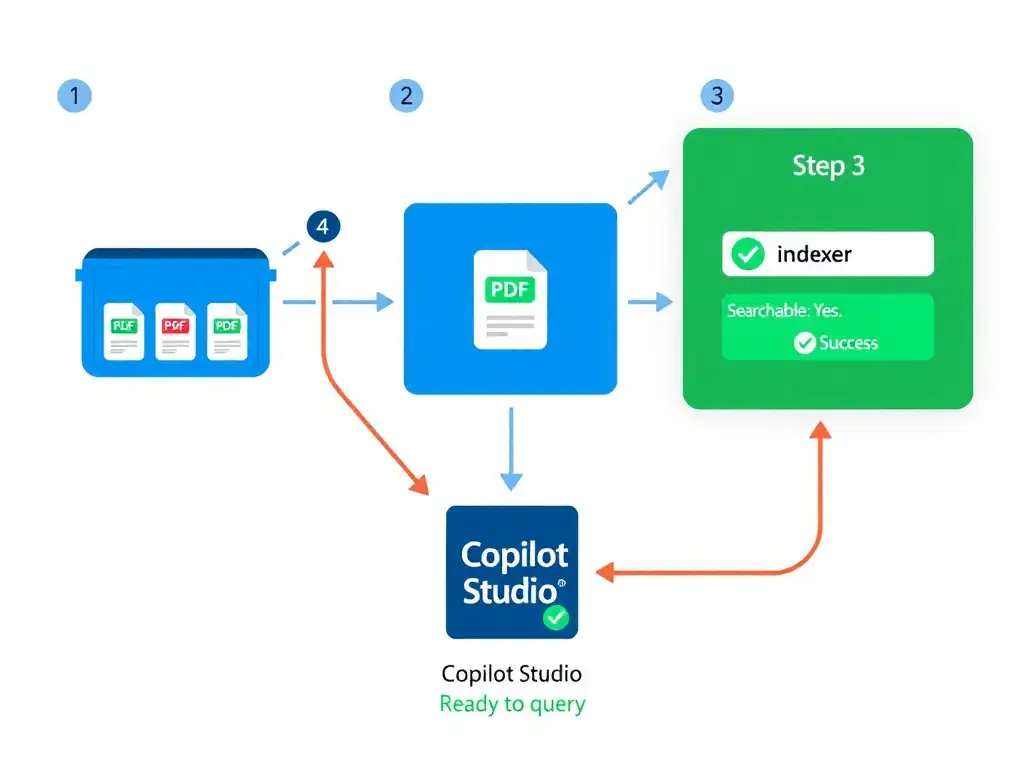
Short Explanation
You need a searchable field that actually holds the document content, plus a successful indexer run that loads the PDF text into the index. Without those, queries return zero results no matter how the connector is configured.
Full Explanation
Before a Copilot Studio agent can successfully retrieve documents from Azure AI Search, two foundational prerequisites must be satisfied at the index level: schema correctness and data availability.
The correct configuration is the one requiring an index schema that defines at least one searchable field holding document content, plus a successful indexer run so documents are present in the index. The schema requirement is that the index contain at least one field with the 'Searchable' attribute set to true, and that field must hold the document text that the search engine evaluates against queries. Without a searchable content field, no query can match the shipment documentation. The data requirement is that the indexer must have completed at least one successful run. The indexer is the pipeline that reads documents from the blob container, extracts text, and loads it into the index. Until the indexer runs, the index is empty and every query returns zero results.
The option saying the index must have at least one field marked as 'Searchable' and the indexer must have completed at least one successful run so that documents are populated into the index is not the best answer because it stops short of the required schema detail: it does not state that the searchable field must hold document content. Metadata-only searchable fields alone would not let the agent retrieve the PDF-derived text, and a completed indexer run only matters if it loads content into a searchable content field. Therefore, the more precise requirement is a searchable content field plus a successful indexer run.
The option requiring a semantic configuration naming title, keyword, and content fields, and an AI enrichment skillset to extract text from PDF blobs, is incorrect because a semantic configuration is required only when semantic search ranking is enabled. It is not a prerequisite for basic keyword search queries from the agent. An AI enrichment skillset is valuable for cracking open PDF binary content, but a basic indexer with native blob parsing can extract plain text from PDFs without a full cognitive skillset.
The option requiring a scoring profile that boosts the 'date' field and public anonymous read access on the blob storage container is incorrect because a scoring profile is an optional relevance tuning feature, not a prerequisite for basic search functionality. Additionally, blob storage does not need public anonymous access — the indexer authenticates using either a storage account key or managed identity, which is the recommended secure approach.
Exam tip: Azure AI Search prerequisites often appear in exam questions. Remember the baseline: schema (searchable fields), data (indexer has run), and — only when semantic features are used — a semantic configuration. DLP, scoring profiles, and vector configurations are optional enhancements.