
A utility wants inspection PDFs to ground an agent. The files are raw scan dumps that mix inspection pages, stamps, and blank sheets. What should happen before grounding?
Select an answer to reveal the explanation.
Short Explanation
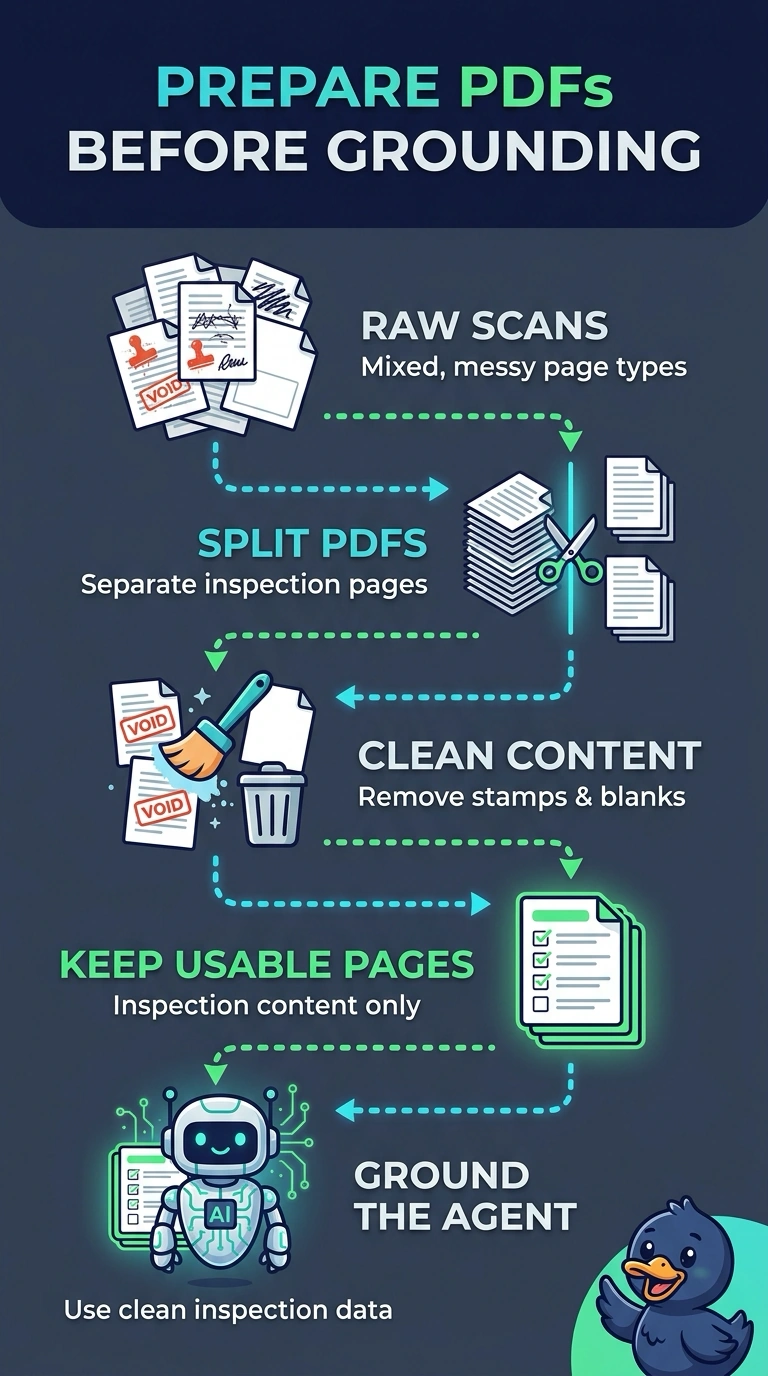
Wash and sort the pages before they go into the binder the model reads. You split and clean the inspection PDFs so the grounding is the inspection content, not the raw scan dump. Indexing the dump as it stands teaches the agent the stamps and the blank sheets.
Full Explanation
Source data is cleaned and split into usable pieces before it grounds a model. These inspection PDFs are raw scan dumps that mix inspection pages with stamps and blank sheets, so indexing them as they stand would let the agent retrieve noise. Stamps and blank sheets are not inspection findings, and a retrieval that returns them will quote noise as if it were a result. The prep step is to split and clean the files so only the usable inspection content grounds the model. Pasting the unsplit dump into the system prompt on every call skips that prep and also treats a living document as prompt text. Fine-tuning a custom model on the raw dump, and skipping the split and cleaning, teaches the noise into the model and is not justified when the defect is the file, not a missing behavior. Exam caveat: cleaning is not a one-time heroics pass; the next batch of inspection scans has to take the same path or the library fills with raw dumps again. Operational check: ask a question whose answer sits on one inspection page and confirm the grounded passage is that page's content, not a stamp or a blank sheet from the dump.