
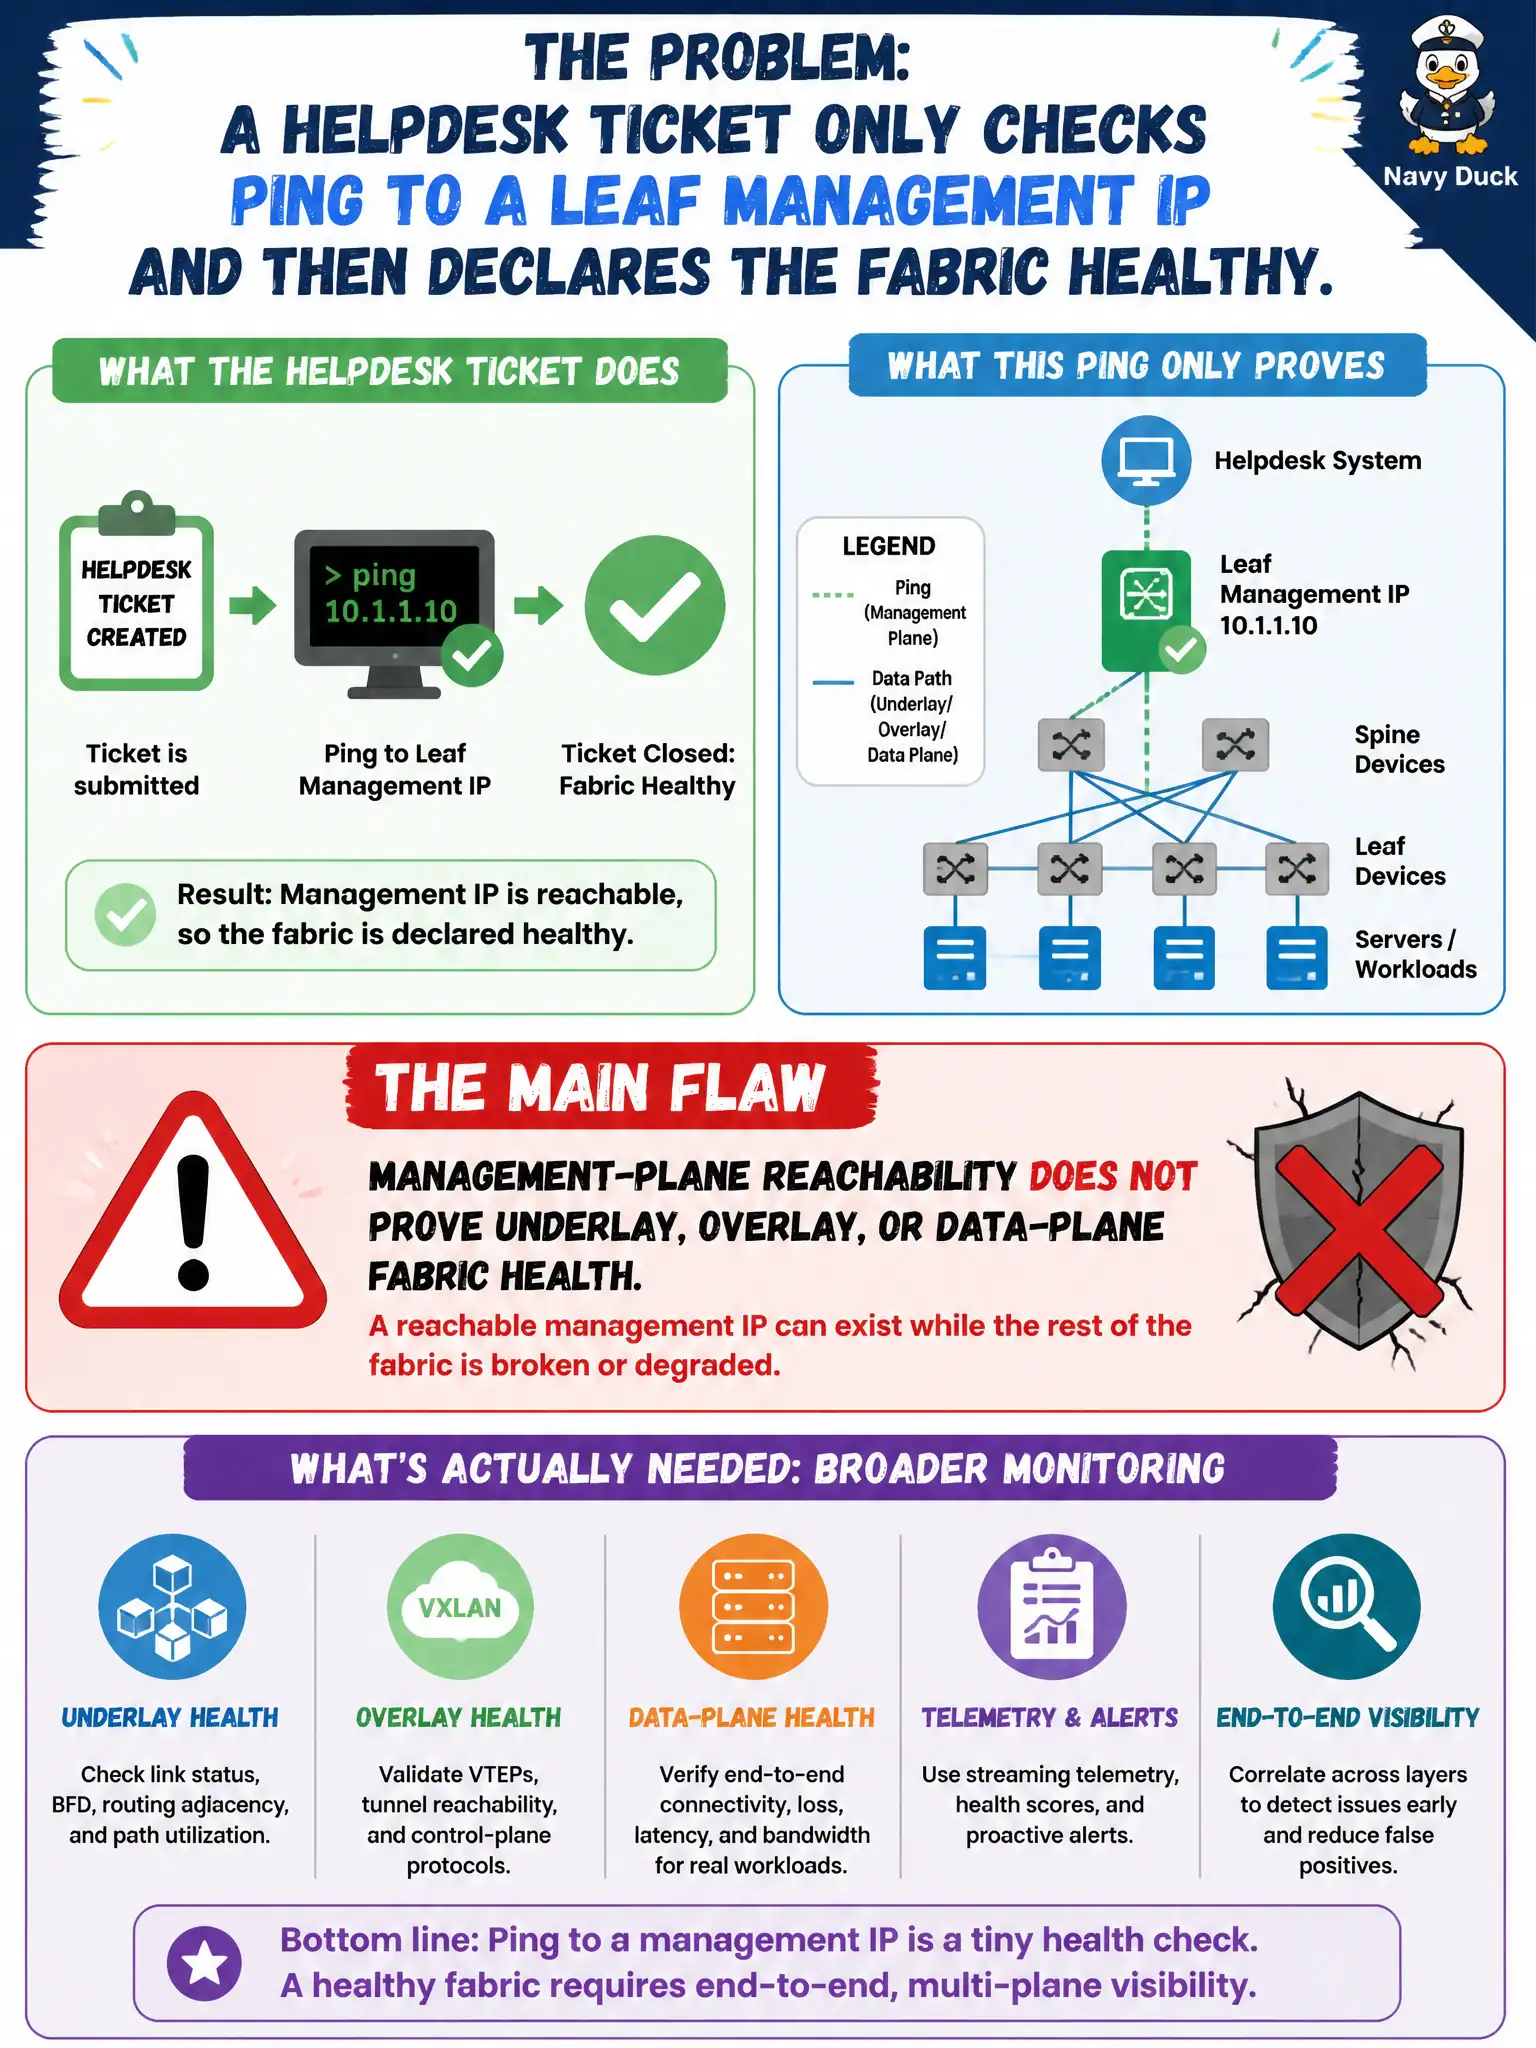
A helpdesk ticket only checks ping to a leaf management IP and then declares the fabric healthy. What is the main flaw in that approach?
Select an answer to reveal the explanation.
Short Explanation
Pinging the management address is like calling the building's front desk and assuming every elevator and hallway works because someone answered the phone. The phone line can be fine while the data-plane floors are dark. Real fabric health needs underlay, overlay, and forwarding checks too.
Full Explanation
Management-plane ping to a leaf proves only management reachability; it does not prove underlay, overlay, or data-plane fabric health, so broader monitoring is still required. Management ping does not prove every EVPN route and VXLAN tunnel is perfect. Management IPs are normal on Junos DC switches; the test is possible but insufficient. Ticket closure time is not a technical definition of fabric health. Exam caveat: Helpdesk scripts should escalate to fabric health checks rather than closing on management ping alone. Operational check: Break an overlay session while management ping still works and show both results in the ticket notes. In civic data-center operations, record the expected CLI or collector evidence for this concept so the next on-call engineer can validate fabric behavior without re-deriving the design under incident pressure. In civic data-center operations, record the expected CLI or collector evidence for this concept so the next on-call engineer can validate fabric behavior without re-deriving the design under incident pressure. In civic data-center operations, record the expected CLI or collector evidence for this concept so the next on-call engineer can validate fabric behavior without re-deriving the design under incident pressure.