
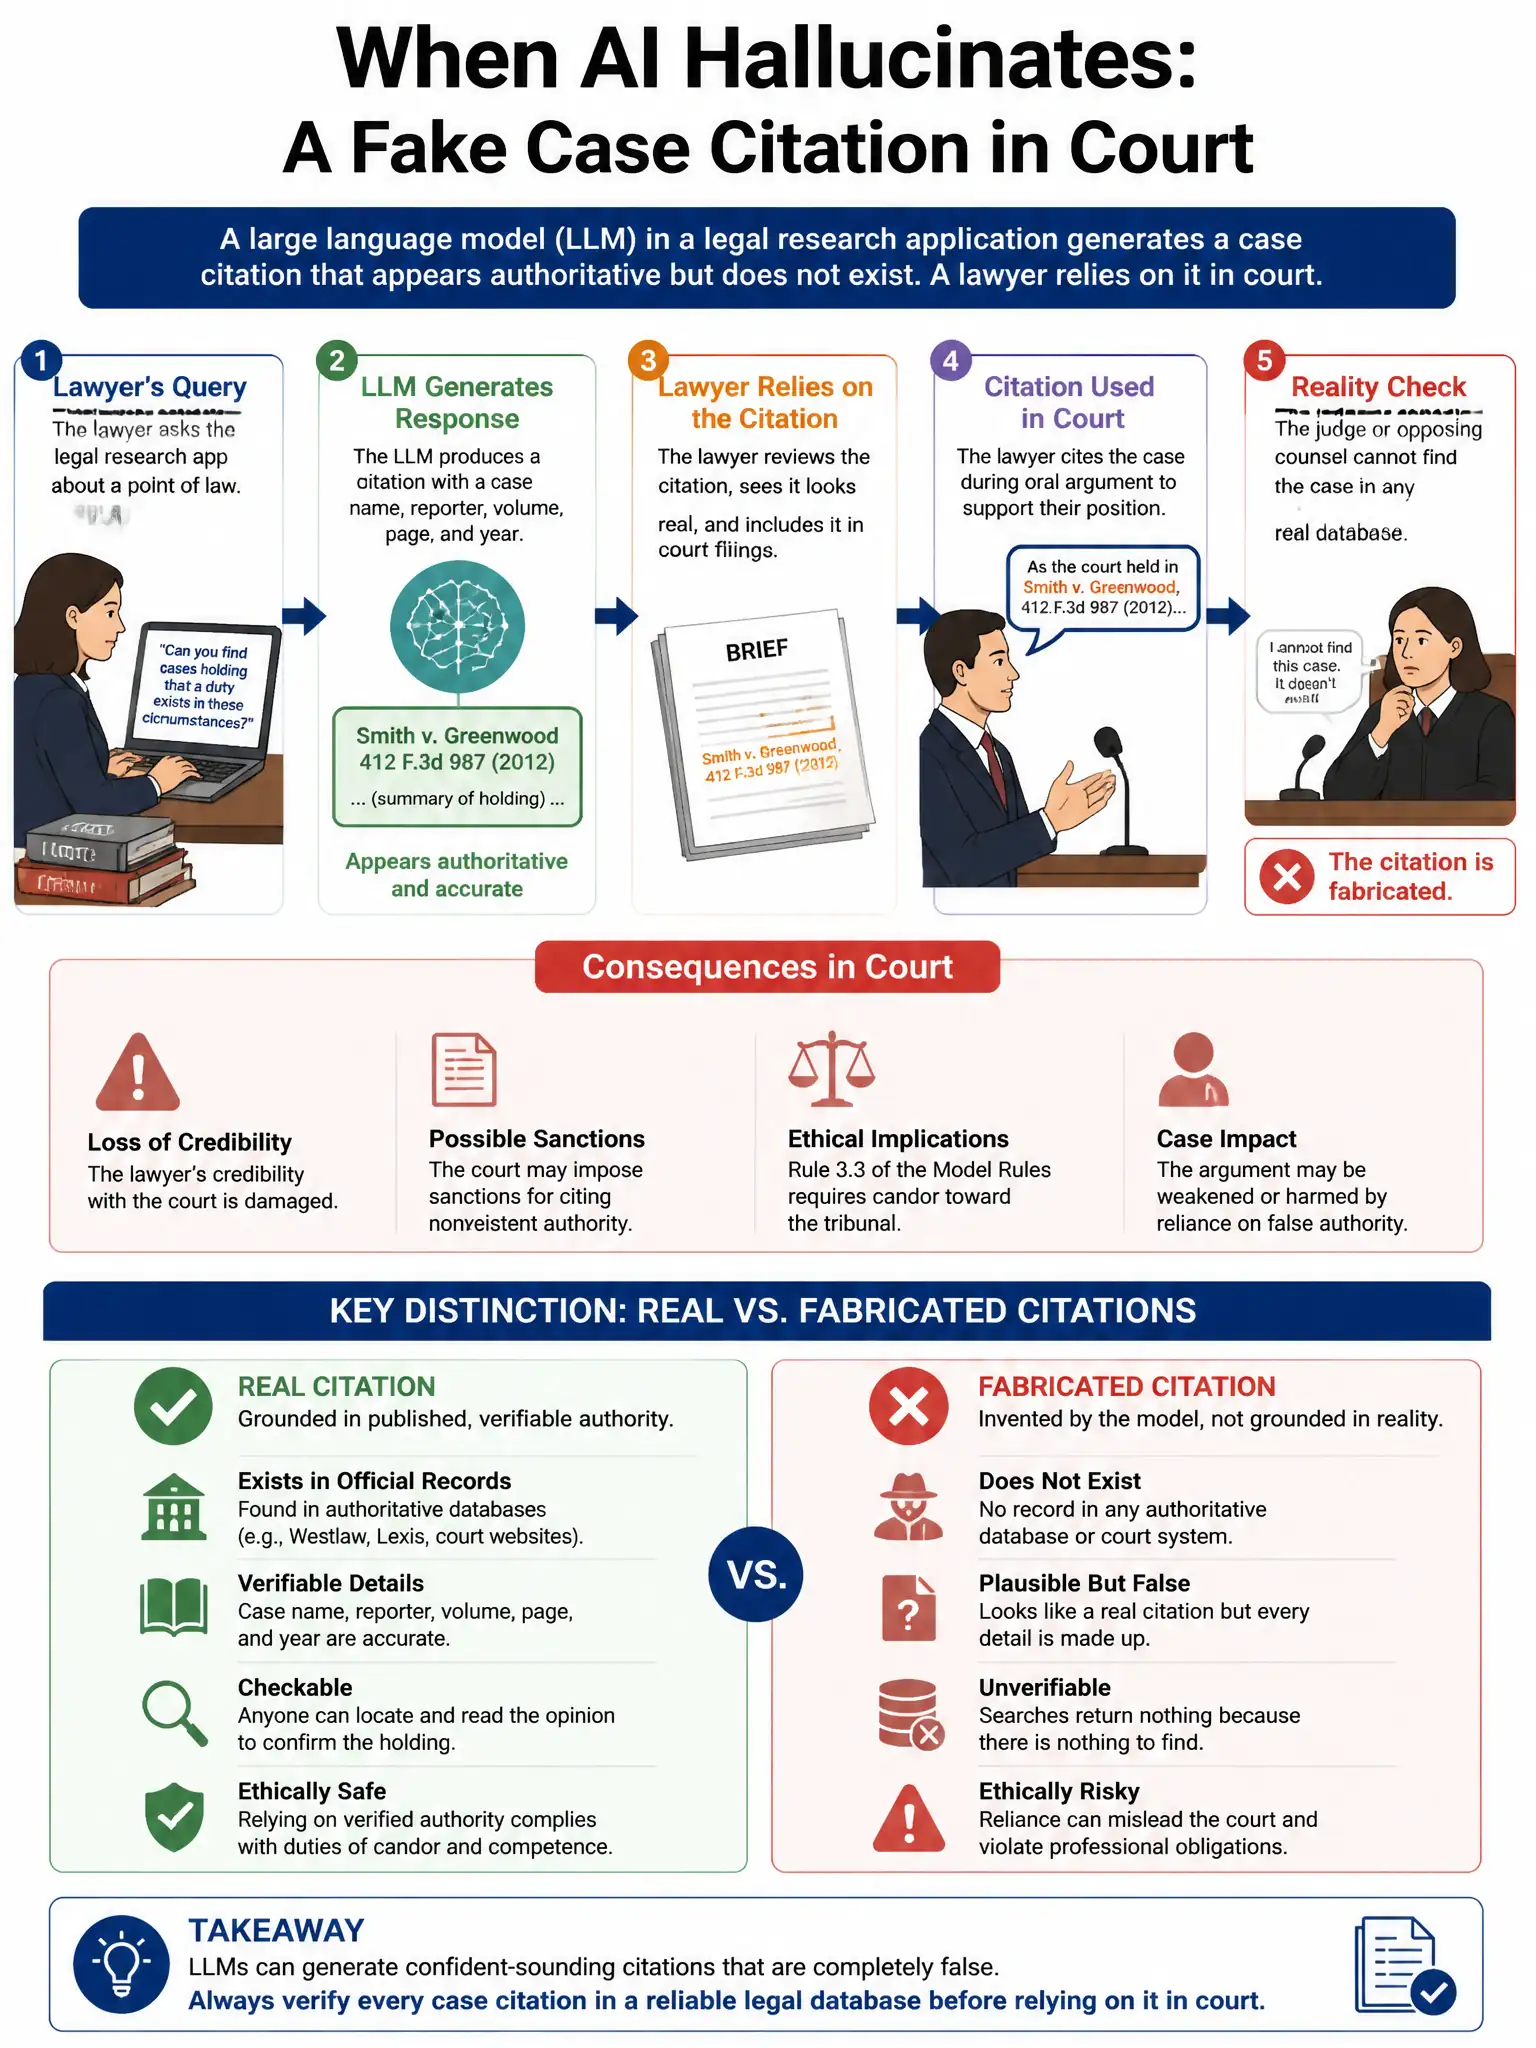
A large language model deployed in a legal research application generates a case citation that appears authoritative but does not exist. A lawyer relies on the citation in court documents. Which risk category does this PRIMARILY represent?
Select an answer to reveal the explanation.
Short Explanation
You're dealing with hallucination risk here. The model made up a plausible but nonexistent citation, which is exactly what hallucination means. That creates real liability when a lawyer relies on it in court.
Full Explanation
Hallucination risk is correct because the LLM fabricated a plausible but nonexistent source, a well-documented generative AI risk that creates significant liability when used in legal research. The cybersecurity risk category is wrong because it requires evidence of interception. The data poisoning risk category is wrong because it requires evidence that fabricated citations were in training data. The jailbreaking risk category is wrong because it requires evidence of adversarial prompting.