
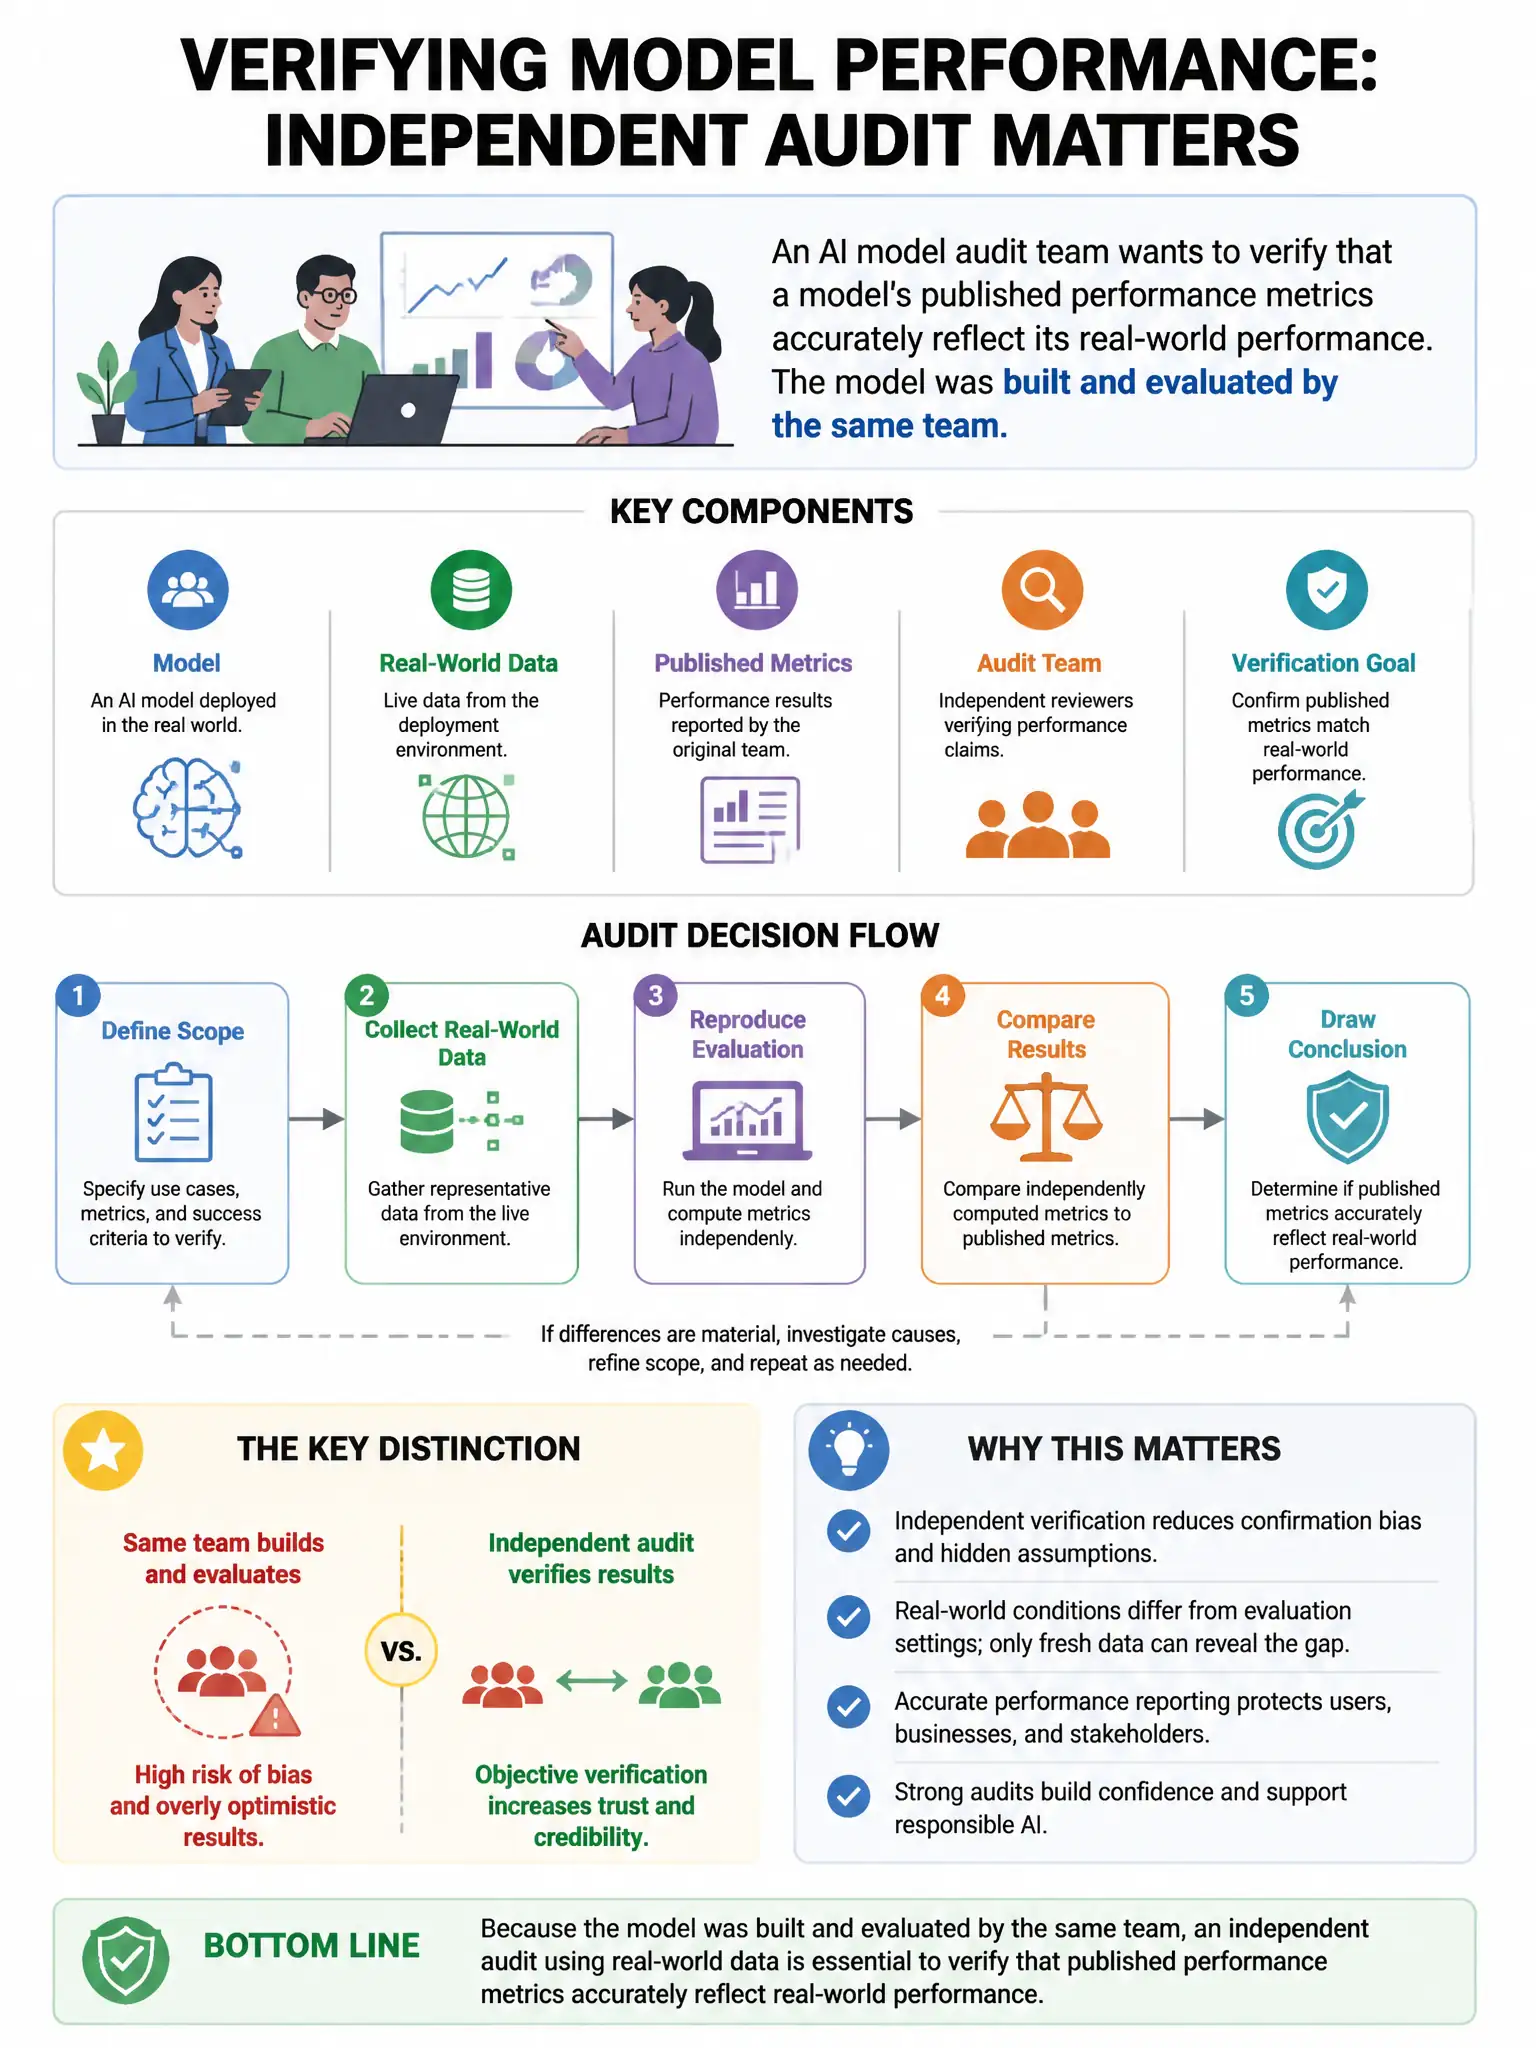
An AI model audit team wants to verify that a model's published performance metrics accurately reflect its real-world performance. The model was built and evaluated by the same team. Which validation approach provides the STRONGEST evidence of real-world performance?
Select an answer to reveal the explanation.
Short Explanation
You need real-world proof, so run the model in controlled shadow mode and compare its decisions to actual outcomes over a representative period using independent data. Published metrics can look good under cherry-picked test conditions, but live deployment exposes distribution shifts, edge cases, and real performance.
Full Explanation
Shadow mode deployment is strongest because it compares model decisions to actual outcomes over a representative period using independent evaluation data. Published metrics may reflect cherry-picked test conditions; live deployment reveals distribution shifts, edge cases, and performance on the live population. Independent outcome data, not labeled by the same team, eliminates self-serving evaluation bias. Reviewing the published validation report and confirming statistical methods are sound does not add independent evidence. Interviewing the development team about testing robustness is management representation. Benchmarking against academic papers on similar models assesses the model type generally, not this model on this population.